kdnuggets.com /1 week ago

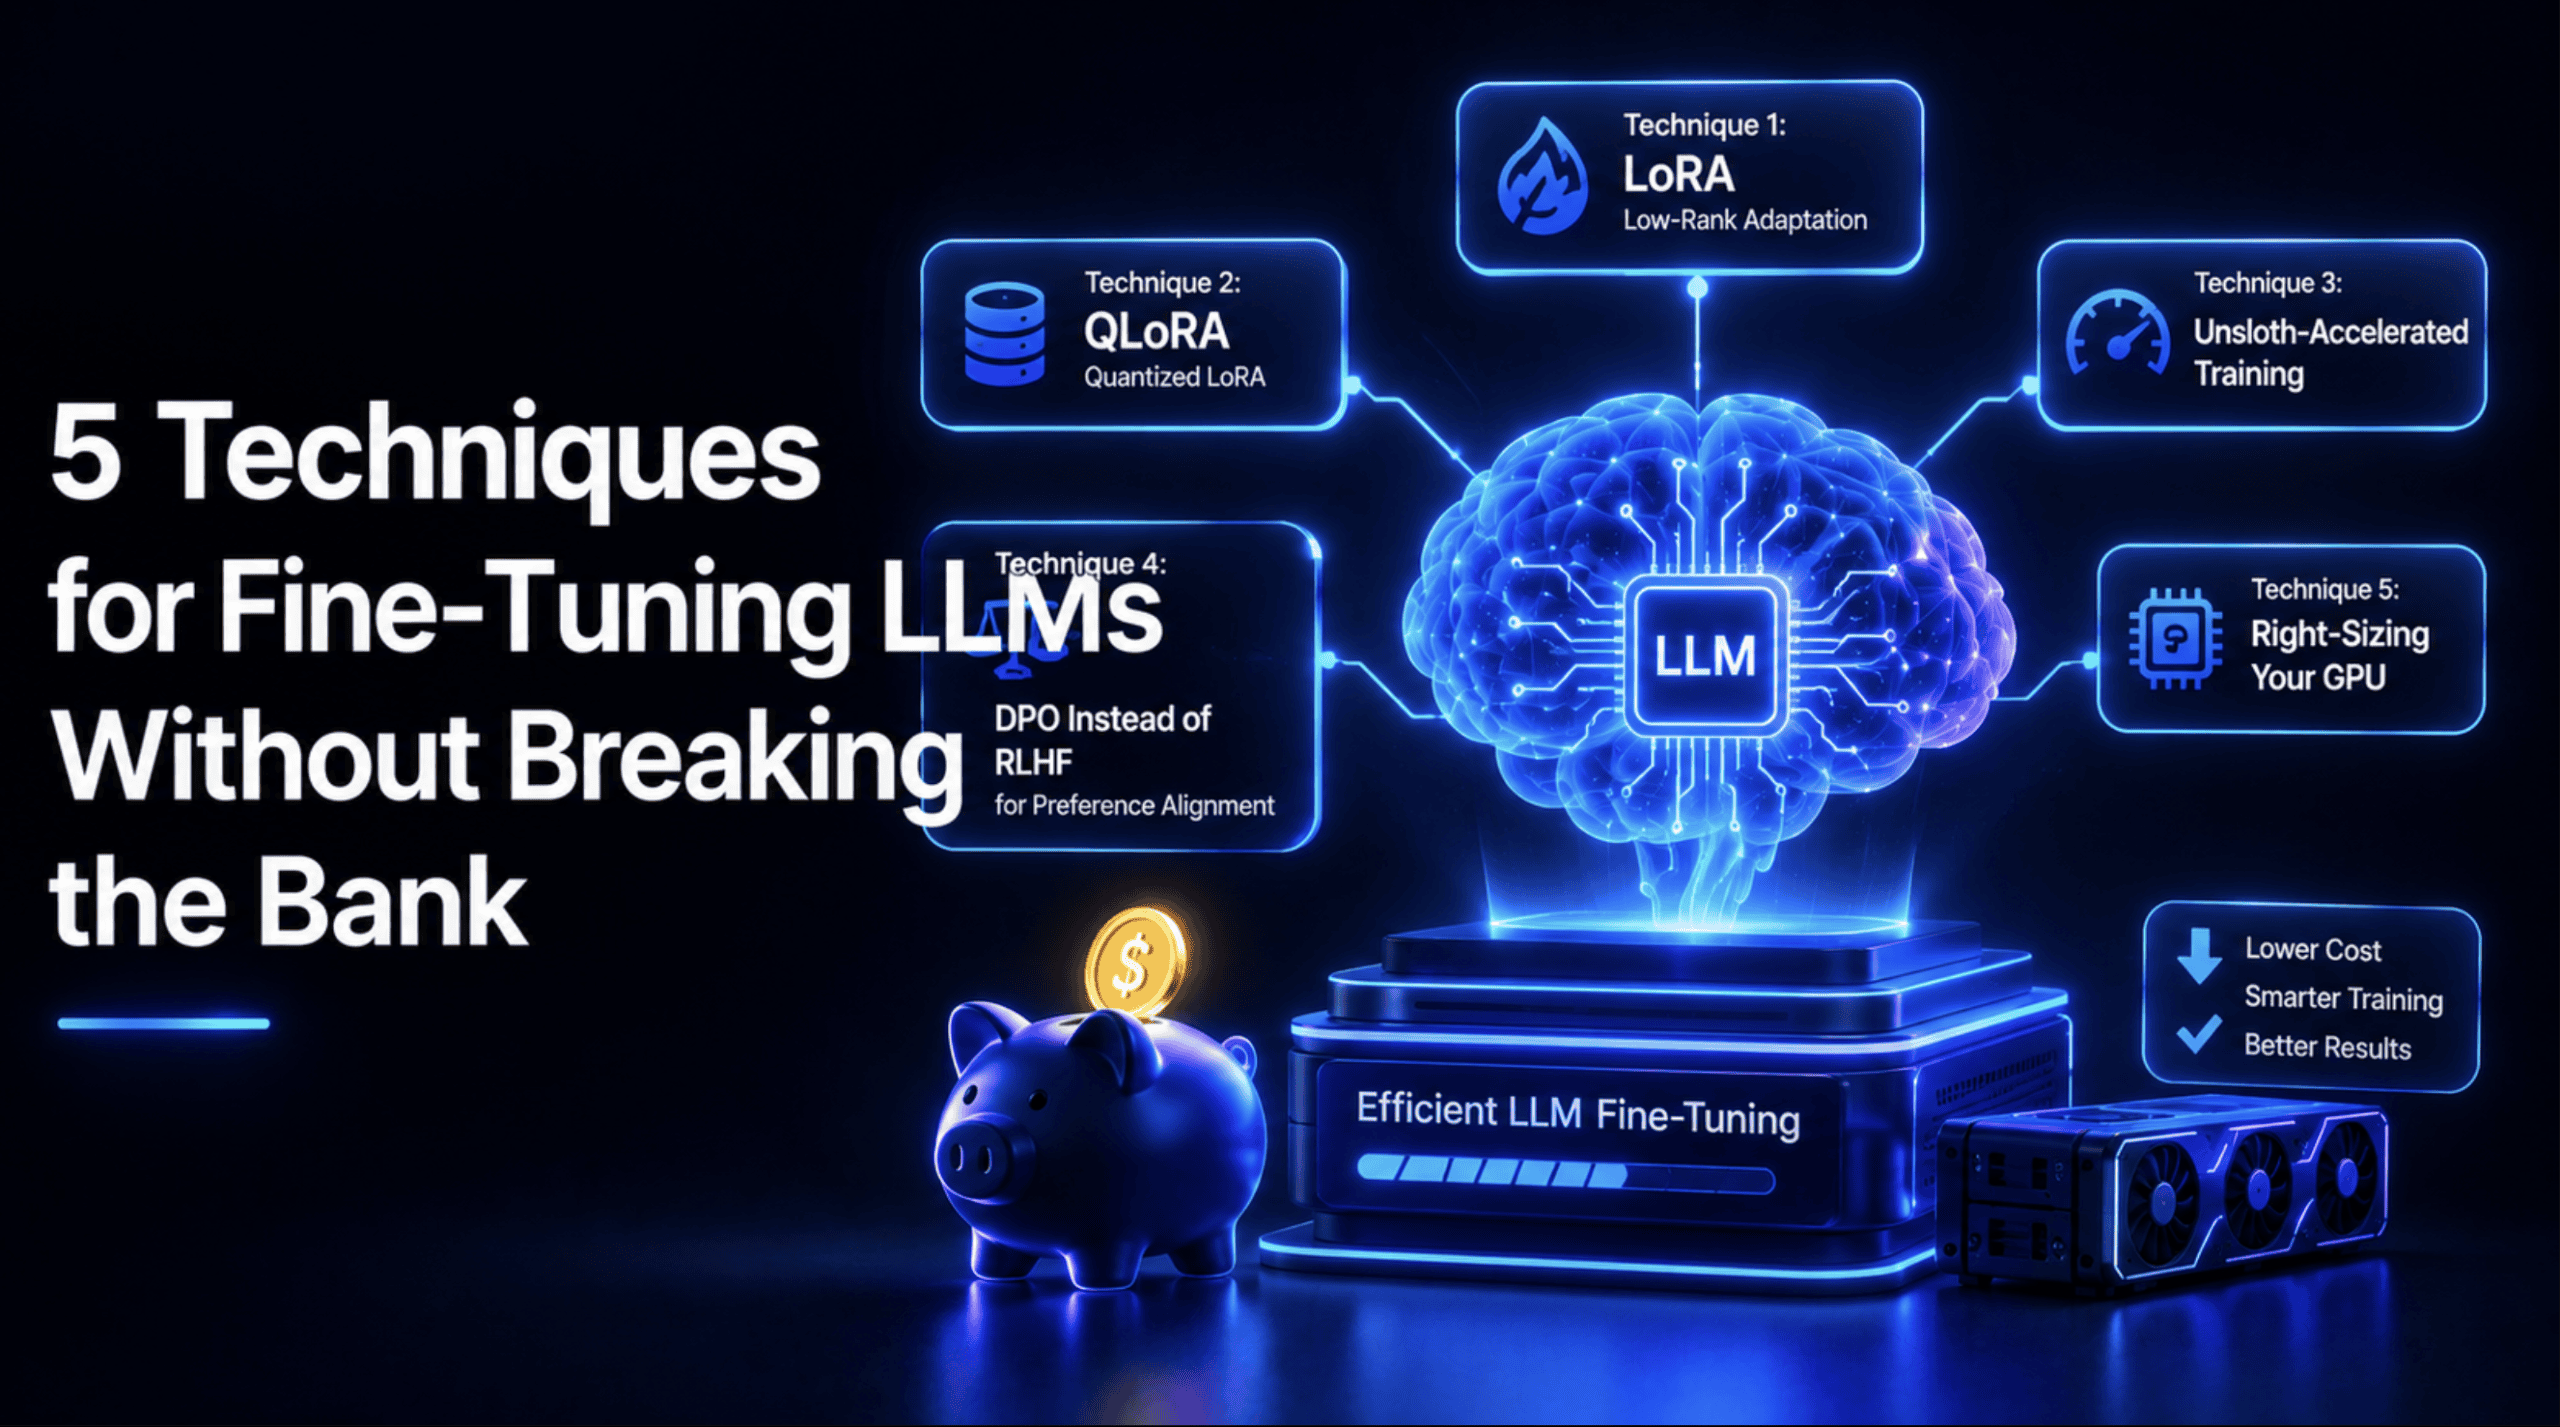
5 Techniques for Fine-Tuning LLMs Without Breaking the Bank

Learn five practical ways to fine-tune LLMs on a budget, from LoRA and QLoRA to Unsloth, DPO, and right-sizing your GPU, with working code for each technique.

Read source
blog.gopenai.com /1 week ago

How to Fine-Tune an LLM With LoRA: Rank, Target Modules and Evaluations That Prove It Worked

A Hands-On Guide to PEFT and TRL: Choosing Rank and Alpha, Masking the Loss Correctly and Measuring Whether the Adapter HelpedContinue reading on GoPenAI »

Read source
javacodegeeks.com /1 month ago

LLM Fine-Tuning: SFT, LoRA, QLoRA, RAG and Prompting

Large language models can perform many tasks without any additional training. They can answer questions, summarize text, generate code, classify information, and interact with tool...

Read source
kdnuggets.com /3 days ago

Comment on How To Fine Tune Your Machine Learning Models To Improve Forecasting Accuracy by https://luckyhillsvip.ca

<strong>... [Trackback]</strong> [...] Read More here on that Topic: kdnuggets.com/2019/01/fine-tune-machine-learning-models-forecasting.html [...]

Read source
aws.amazon.com /1 month ago

Fine-tune a search agent with multi-turn RL on Amazon SageMaker AI

Fine-tuning teaches a small search agent your tools and environment, giving it the reliability of a frontier model at lower latency and cost. In this post, we fine-tune an LLM-powe...

Read source
aws.amazon.com /3 days ago

Full Fine-Tuning (FFT) on SageMaker AI Serverless Model Customization

Amazon SageMaker AI Serverless Model Customization now supports Full Fine-Tuning (FFT). This post explores when FFT outperforms LoRA across key benchmarks, examines the spectral pr...

Read source
medium.com /2 weeks ago

Tuning Strata: A Practical Guide to Faster Tokens, Smarter Memory and Longer Context

How to measure, then tune, the settings that decide how fast a 125B MoE model runs on a home PCContinue reading on Medium »

Read source
aws.amazon.com /1 month ago

Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod

Learn how we fine-tuned GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod, and how to decide between supervised fine-tuning (SFT) and reinforcement learning with...

Read source
machinelearningmastery.com /3 weeks ago

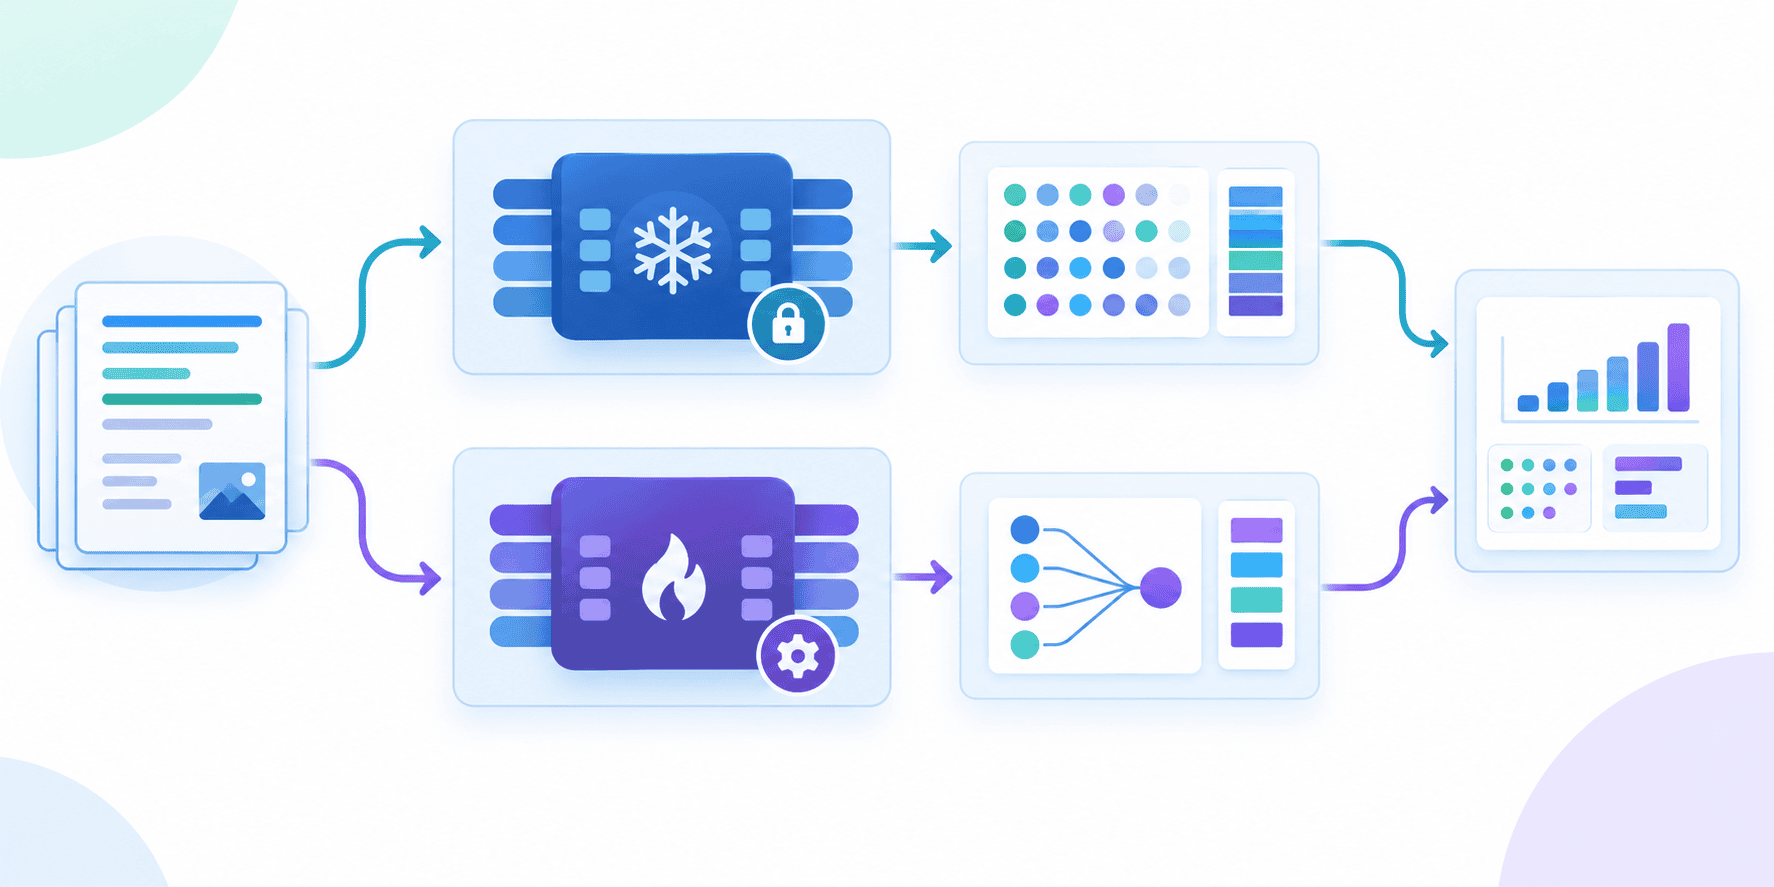
Fine-Tuning vs. Frozen Embeddings: When to Adapt the LLM vs. the Sklearn Head

In this article, you will learn how to compare two strategies for adapting a large language model to a specific domain: fine-tuning with LoRA versus...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.