How LLMs Work: Transformer Architecture Explained | Simplilearn
TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...
Search fresh public links, source activity, and ready-to-use post angles for Large Language Models.
Fresh curated links around Large Language Models are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...
A small language model runs on ordinary hardware fast enough to serve one user, and an LLM is one that does not. SLM vs LLM compared, with 200 measured runs.
Large Language Models can now process hundreds of thousands, and sometimes even millions, of tokens.Continue reading on Medium »
Large Language Models (LLMs) have transformed the way applications process and generate natural language. They are widely used in chatbots, search systems, coding assistants, docum...
Large language models have become easier to integrate into applications, but running them efficiently is still a major engineering challenge. As the number of users and requests in...
Large language models can write essays, generate code, explain concepts, summarize documents, and hold conversations.Continue reading on Medium »
Fine-tuning large language models isn’t a one-size-fits-all exercise anymore. What started as a technique mostly discussed in AI research…Continue reading on Medium »
Large language models can perform many tasks without any additional training. They can answer questions, summarize text, generate code, classify information, and interact with tool...
Даже идеальная модель с бесконечным объемом текста не восстановит ту часть смысла, которая никогда не была закодирована в языковой форме.Представьте фразу в рабочем чате: «он снова...
Large language models can summarize reports, explain technical ideas, draft content, generate code, and answer complicated questions within seconds. Their fluency is useful. It is...
Large Language Models (LLMs) are commonly accessed through cloud APIs provided by services such as OpenAI, Anthropic, or Google Gemini. However, there are many situations where dev...
TL;DR: LLM evaluation metrics are measurements used to assess the performance of large language models. They cover areas such as output quality, factual grounding, safety, and oper...
The biggest shift in local AI is no longer benchmark leadership but the ability to deliver language intelligence directly inside desktop and mobile applications without depending o...
Когда речь заходит о ЛЛМ и классификации, первая мысль — попросить модель сгенерировать класс через промптирование модели с описанием правил и добавлением примеров. Для небольшого...
But by keeping these limits in mind, and planning for them, we can effectively use these small, local models for the following broad operations scenarios.
Running a 70B model in production is expensive, and for many tasks, unnecessary. If you're building a focused pipeline, a well-trained 3B model will match or beat the 70B on your s...
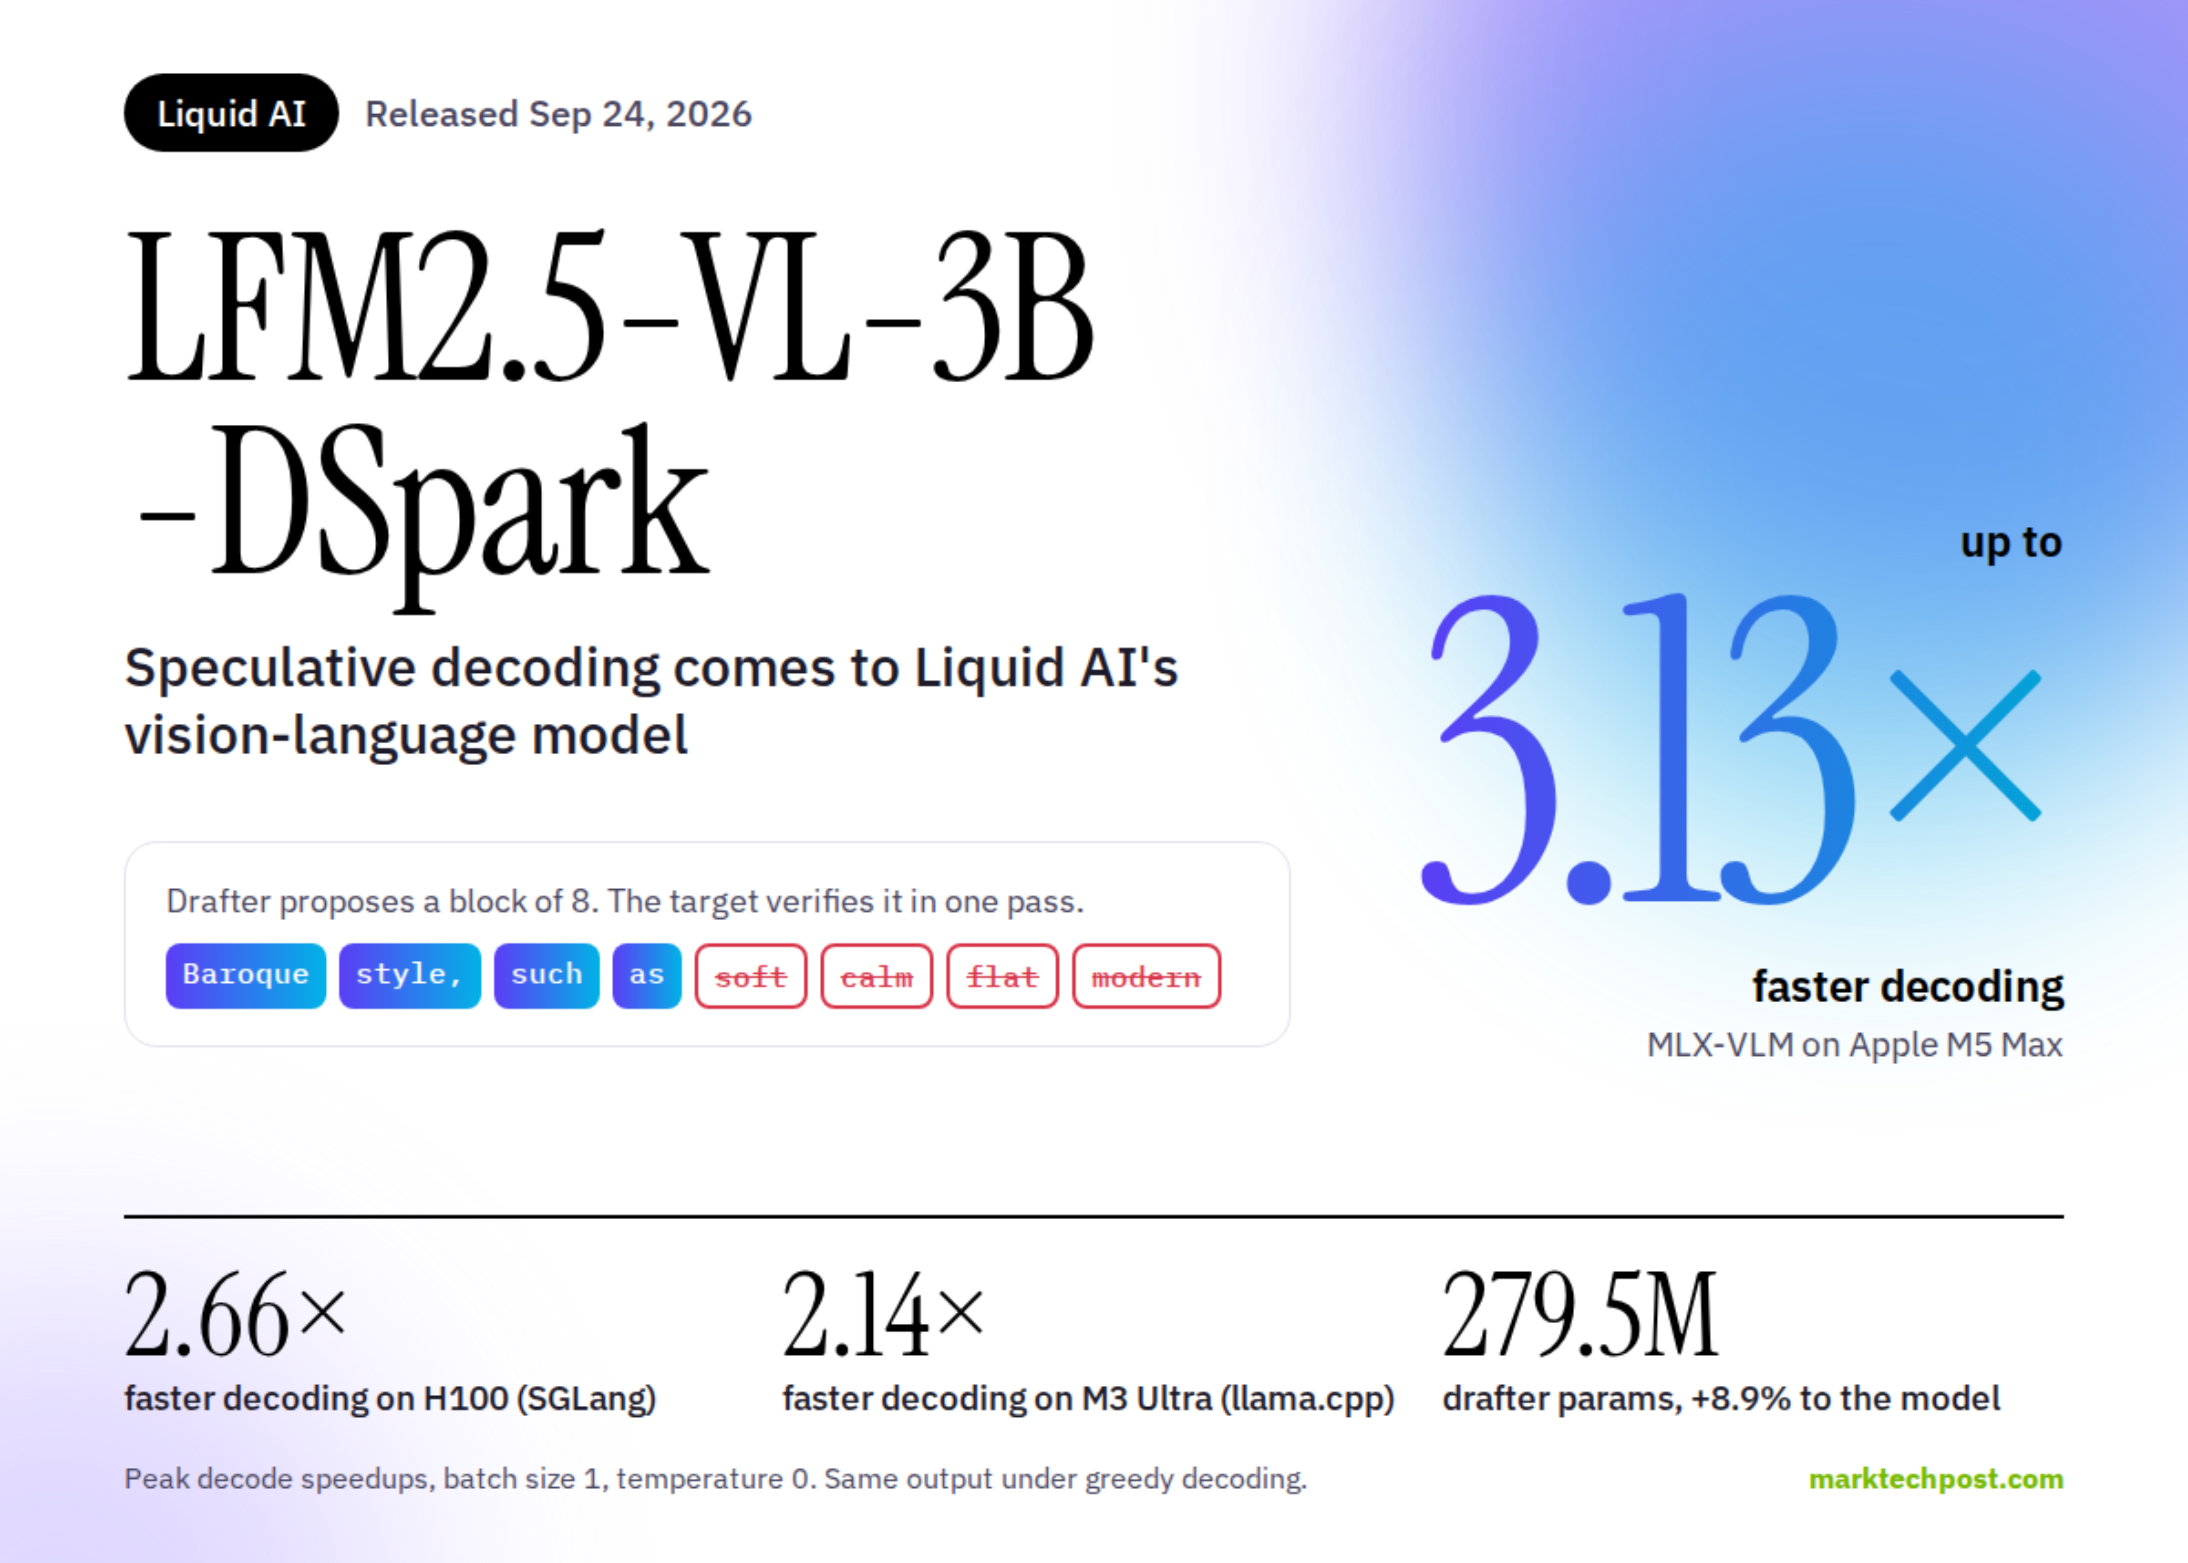
Liquid AI has released LFM2.5-VL-3B-DSpark, a 279.5M-parameter draft model that brings speculative decoding to its LFM2.5-VL-3B vision-language model. It delivers up to 3.13x faste...
Aleph Alpha has released Kolibri, a 78.1B-parameter English-German Mixture-of-Experts model that activates only 3.46B parameters per token. It has a 1M-token context and per-reques...
This post was originally published on our collaborative substack site. Visit the site to follow us and read more similar posts. Jointly authored by Chris Brown, Scott Spillias, Car...
Why use it? How to implement it? What can we do when it fails? The post How to Implement Structured Output with Local LLMs appeared first on Towards Data Science.
How co-occurrence in large language models shapes brand visibility, why AI answers vary between runs, and how to adapt your content strategy.
Large Language Models are fundamentally stateless. If an application sends the question “What is my favorite programming language?” to a model, the model cannot automatically know...
The Uncomfortable Truth You’ve spent days prompt-engineering your LLM. You’ve benchmarked Claude against GPT. You’ve debated whether to use Mixtral. But your RAG pipeline is still...
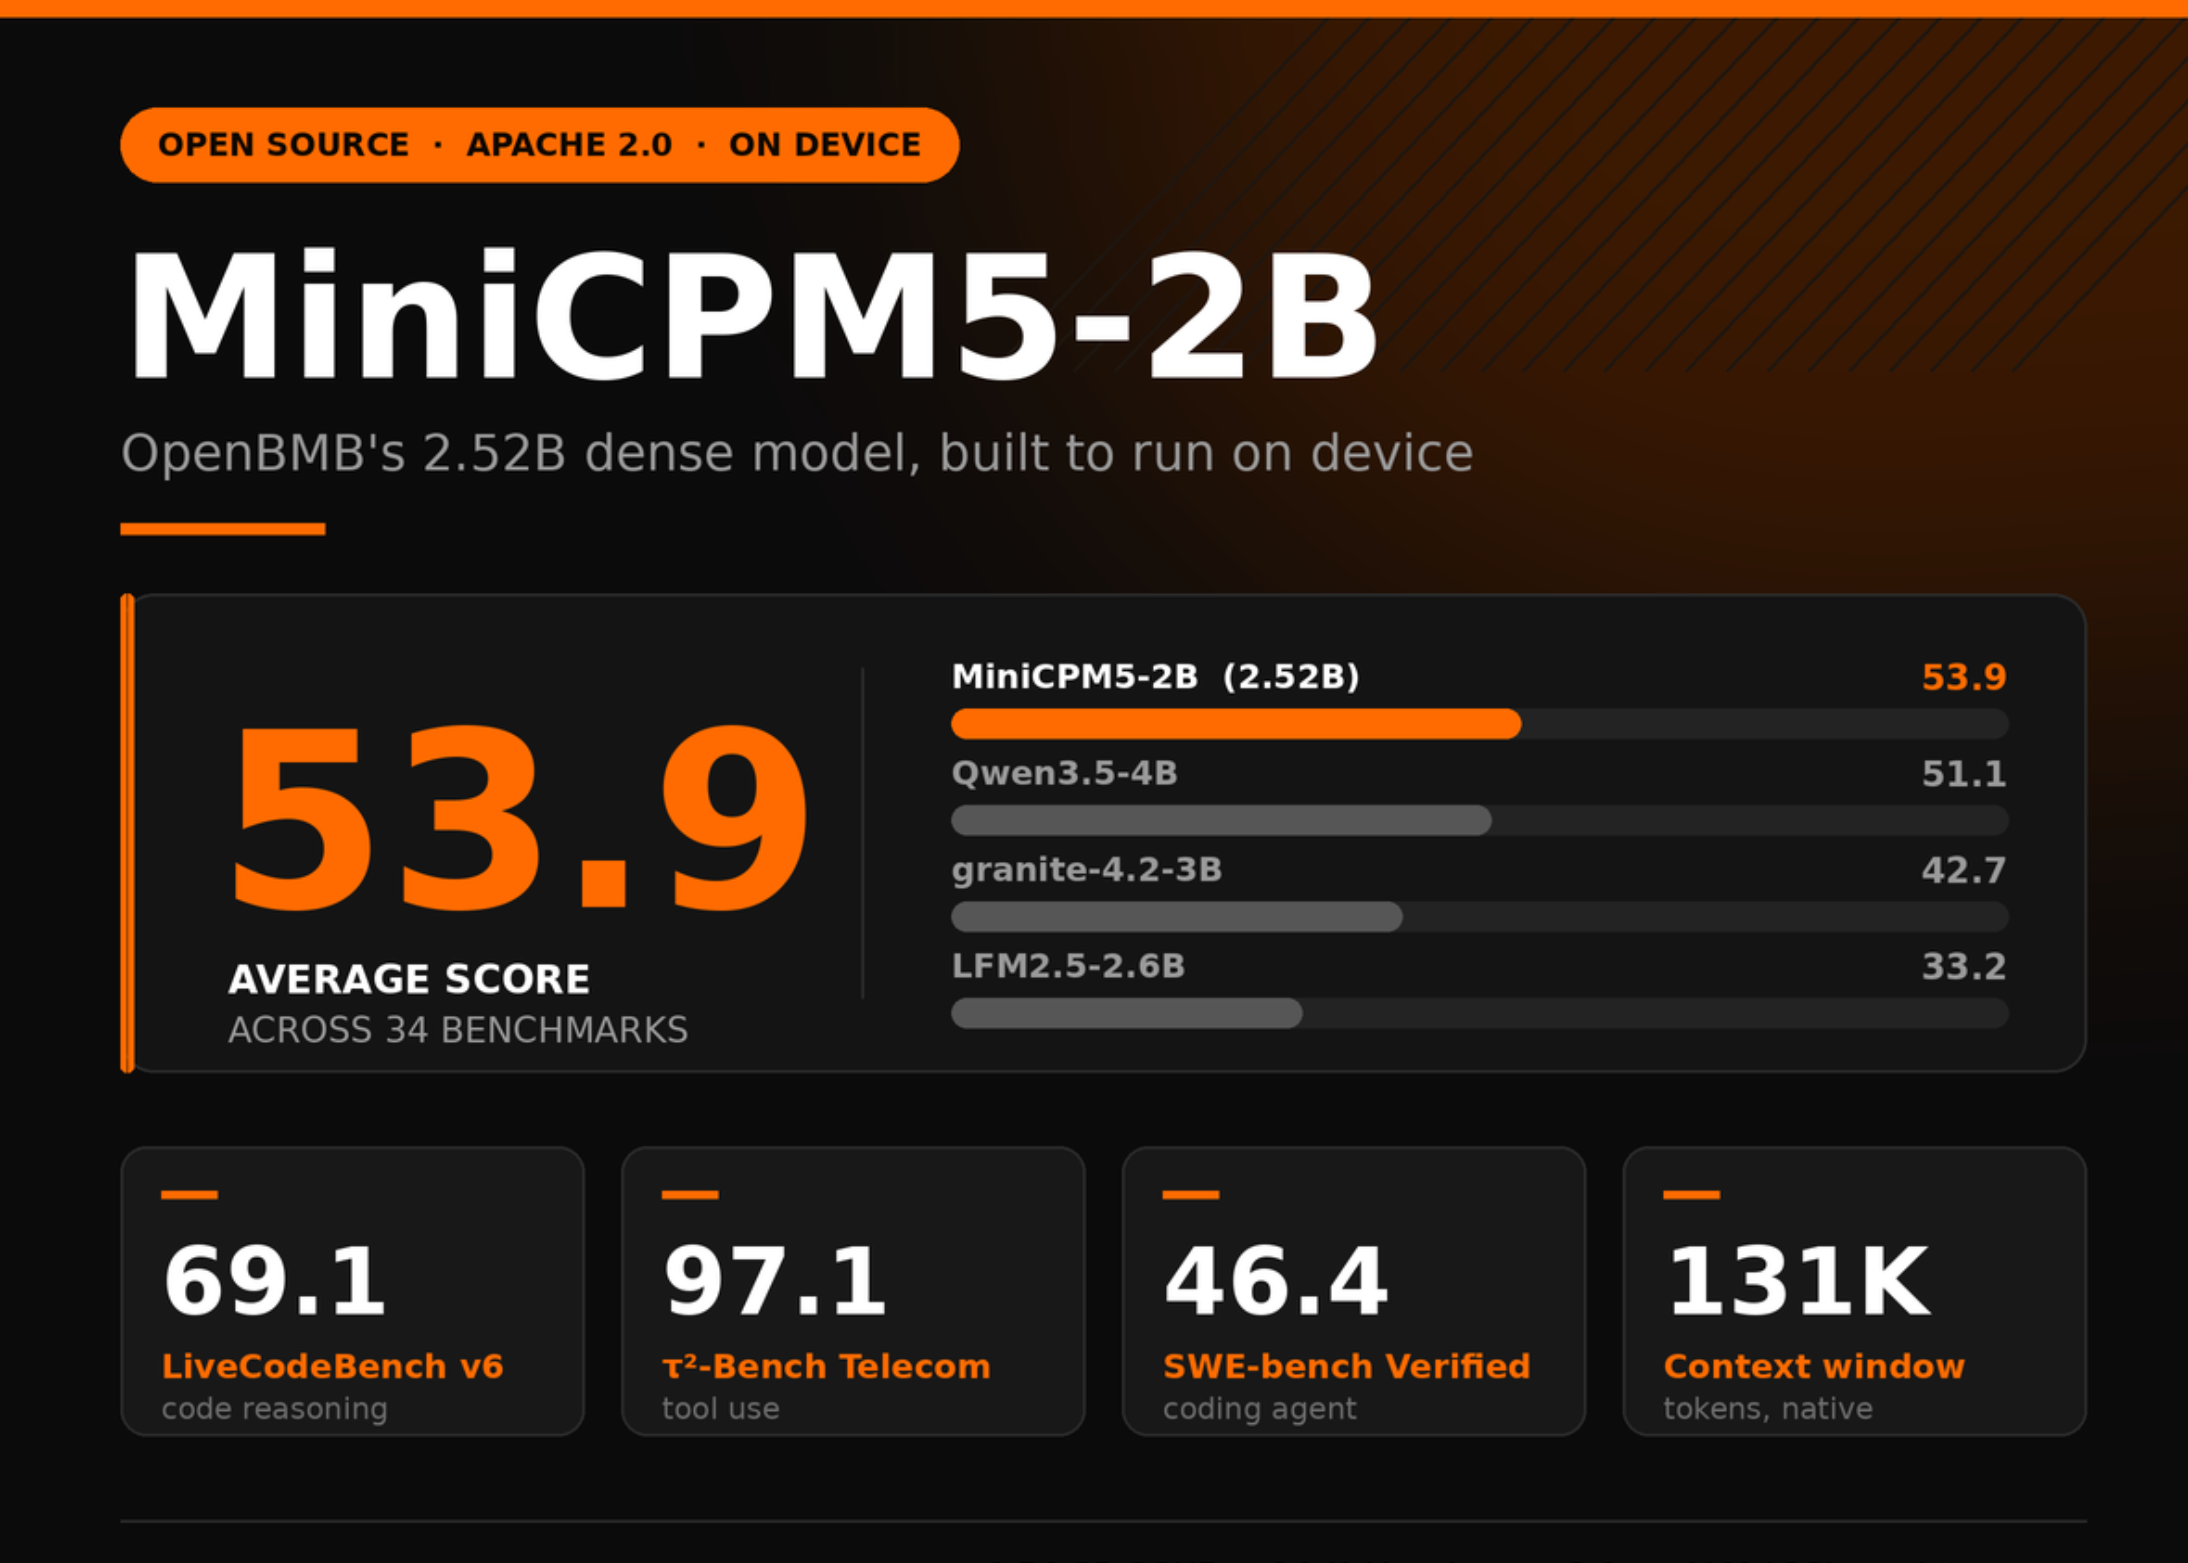
OpenBMB has released MiniCPM5-2B, a dense causal language model with 2,516,756,480 parameters and a native 131,072 token context. It averages 53.9 across the 34 benchmarks in its m...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.