habr.com /1 month ago

LSWM 2.0 is all you need

Снова всем привет!Прошло всего два дня с того момента как я выложил LSWM.В общем я протестировал и поэкспериментировал эту сеть ещё раз и нашёл СТОЛЬКО проблем, сколько даже ваниль...

Read source
nitarithm.medium.com /1 month ago

SliteView — Forecasting Electrical Motor Signals with Bi-LSTM

Notes on FFT, Simulation Modeling, and Time-Series ForecastingContinue reading on Medium »

Read source
medium.com /1 month ago

LLM Coding Interview Series: 6/30 [Multi-Head, Multi-Query, and Grouped-Query Attention from…

Part 6 of the LLM Coding Interview Series ·Continue reading on Models to Systems »

Read source
freecodecamp.org /1 week ago

Build and Train a GLM-5.3-Flash Model From Scratch with Python

GLM-5.3-Flash combines linear and sparse attention, a mixture-of-experts design, and manifold constrained hyperconnections. A scaled-down version with 25 million parameters can be...

Read source
medium.com /1 month ago

Understanding Large Language Models (LLMs)

The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »

Read source
medium.com /5 days ago

Test-Time Training Layers: What If the Hidden State Is Itself a Model?

Day 76 of an ongoing daily series on advanced machine learning conceptsContinue reading on Medium »

Read source
kdnuggets.com /3 weeks ago

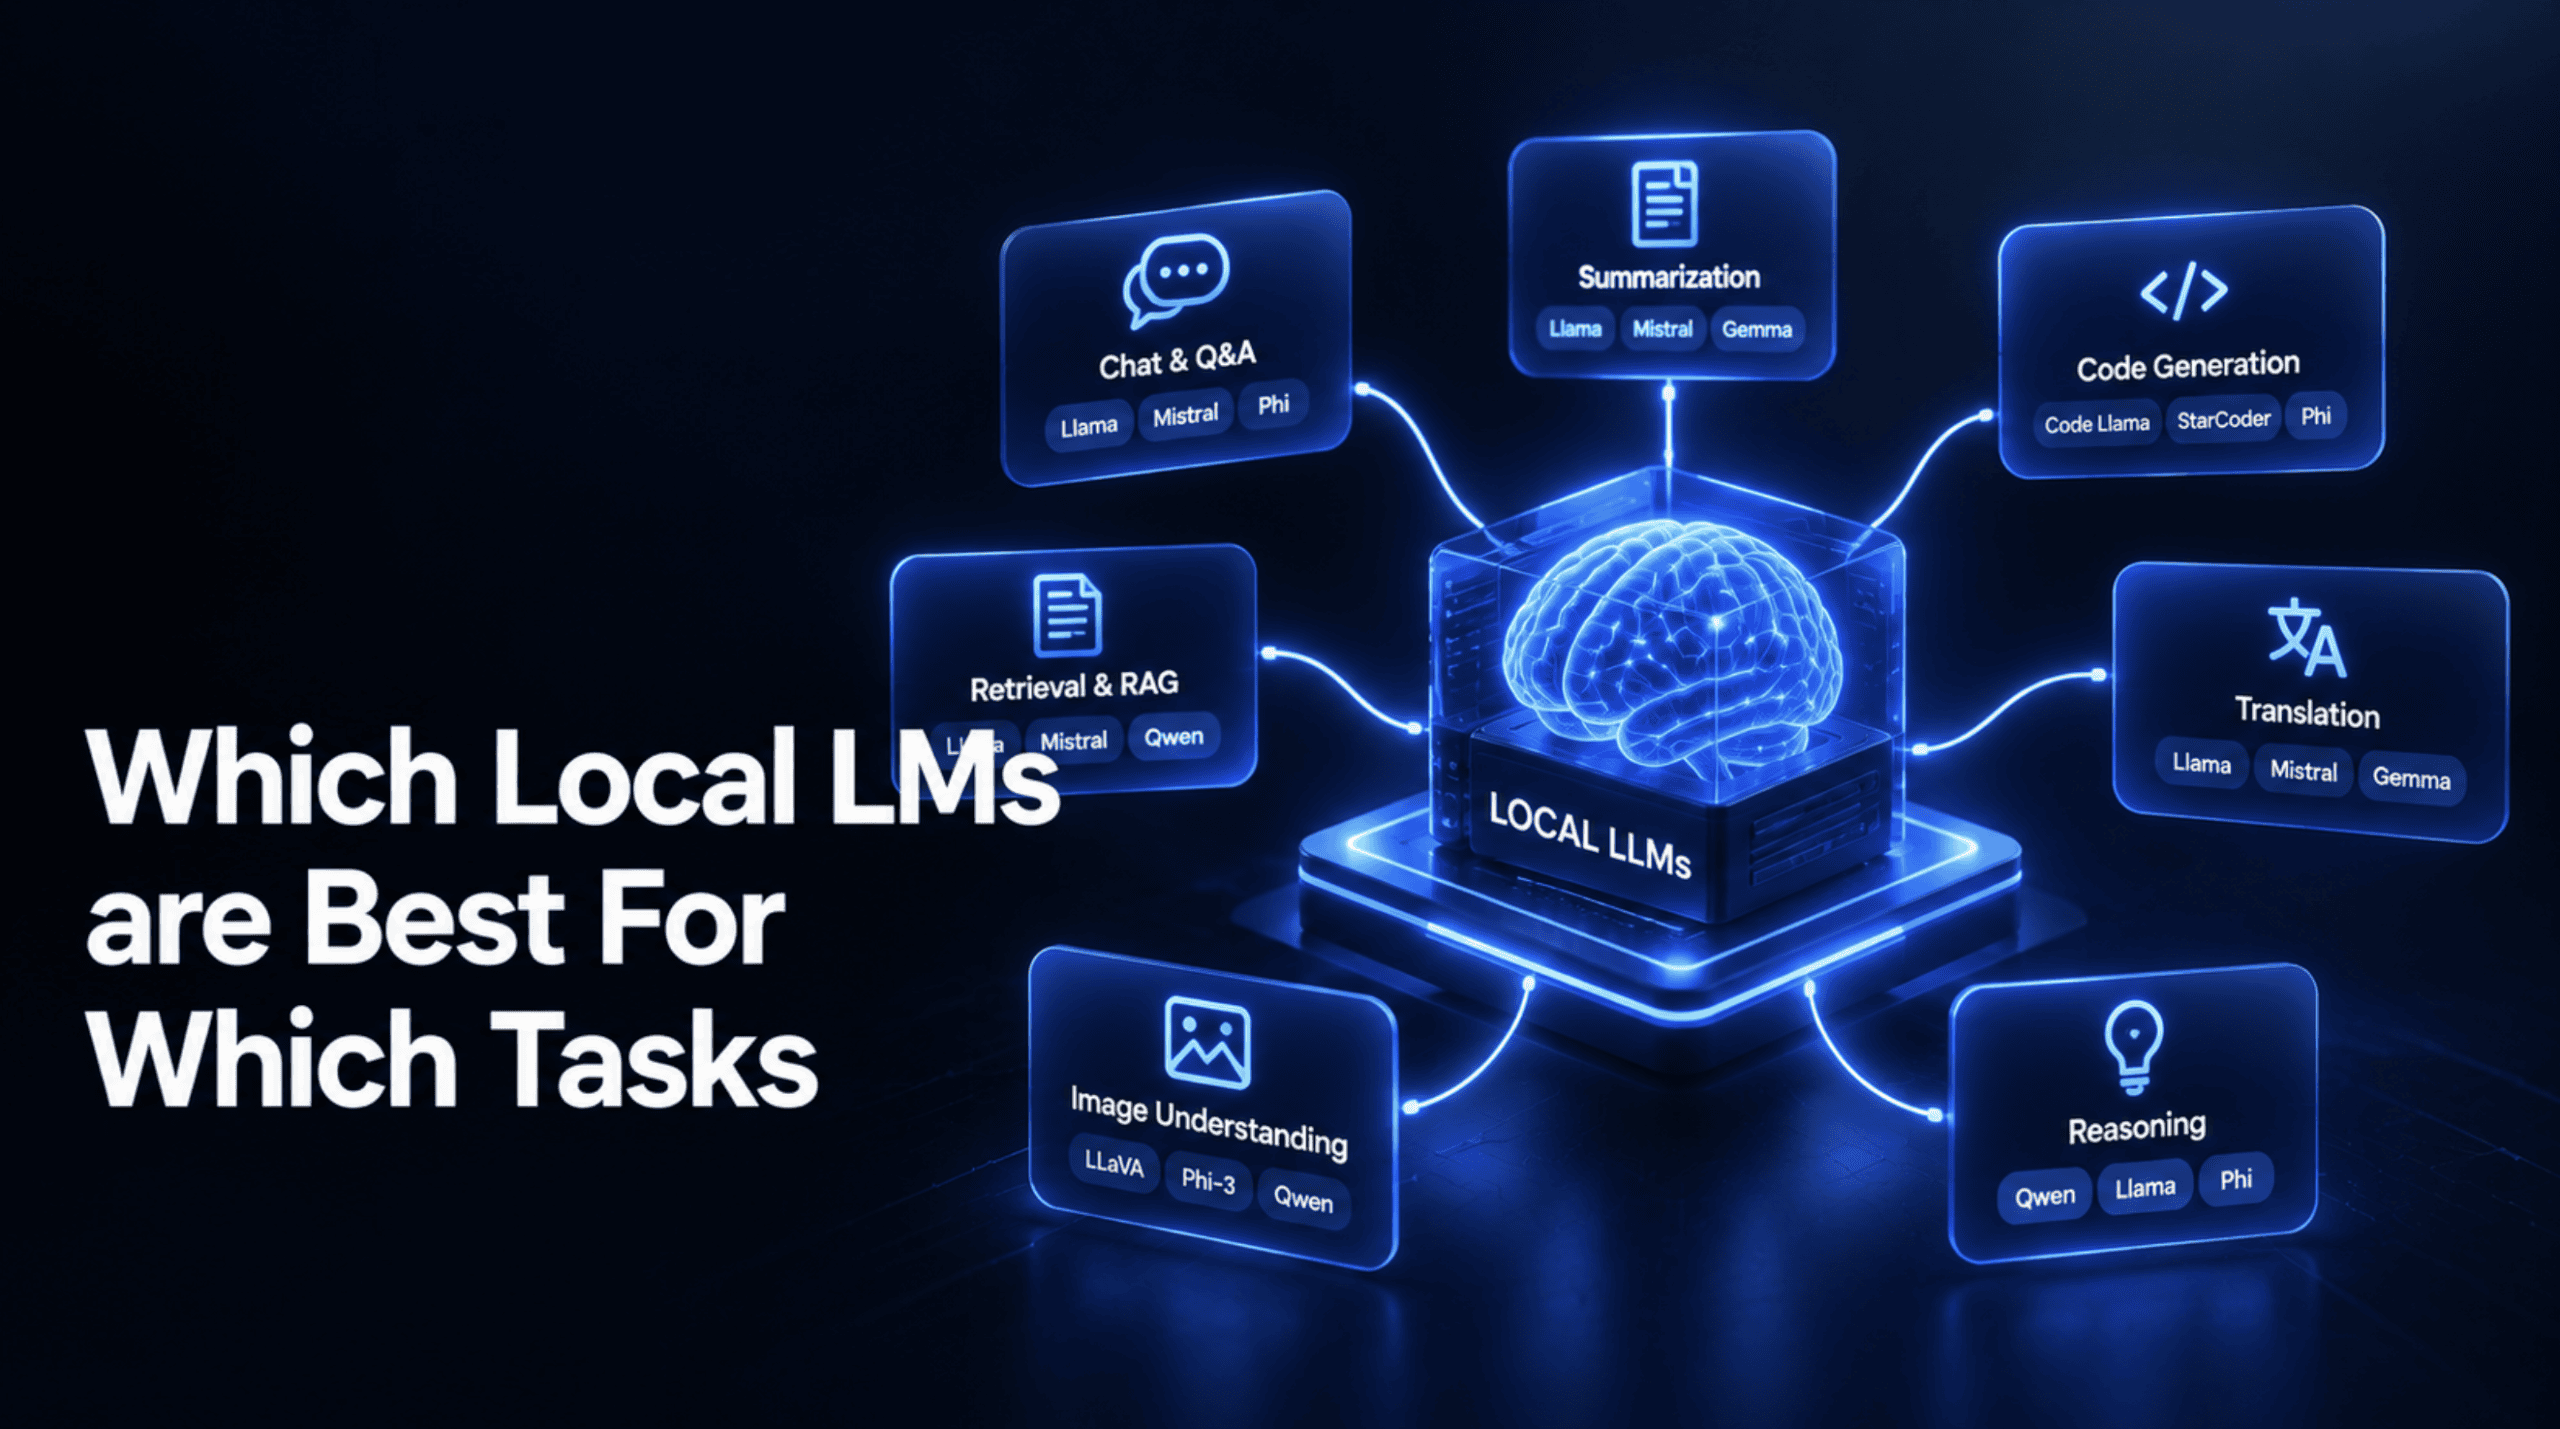
Which Local LMs are Best For Which Tasks

A local language model is one whose actual weights, the enormous file of learned numbers that constitutes the trained model, you download and run entirely on your own hardware.

Read source
towardsdatascience.com /2 weeks ago

Beyond Classical: A Quantum Approach to Time-Series Prediction

Introducing CoQS-LSTM, a Coherent Quantum Long Short-Term Memory Architecture The post Beyond Classical: A Quantum Approach to Time-Series Prediction appeared first on Towards Data...

Read source
habr.com /1 month ago

Моя собственная Gated RNN: как работает? (и бенчмарки, конечно же)

Всем привет!Не давно сделал свою Gated RNN, то есть с другой математикой, ни как у LSTM, GRU и подобного.Я хочу (для вас) разобрать её теоретически, практически, замерить (я не уме...

Read source
medium.com /3 days ago

Bigger Neural Networks are Not Always Better

LLMs tend to get lost in trivial logic. But why? Is their size a problem?Continue reading on Medium »

Read source
pub.towardsai.net /2 weeks ago

Catastrophic Forgetting in LLMs & Its Solutions: Fine-Tune Without Losing Skills!

Replay, LoRA, EWC, KL anchoring, merging, and RAG explained with Python code, so you can fine-tune on your data without regressions.Continue reading on Towards AI »

Read source
kdnuggets.com /2 weeks ago

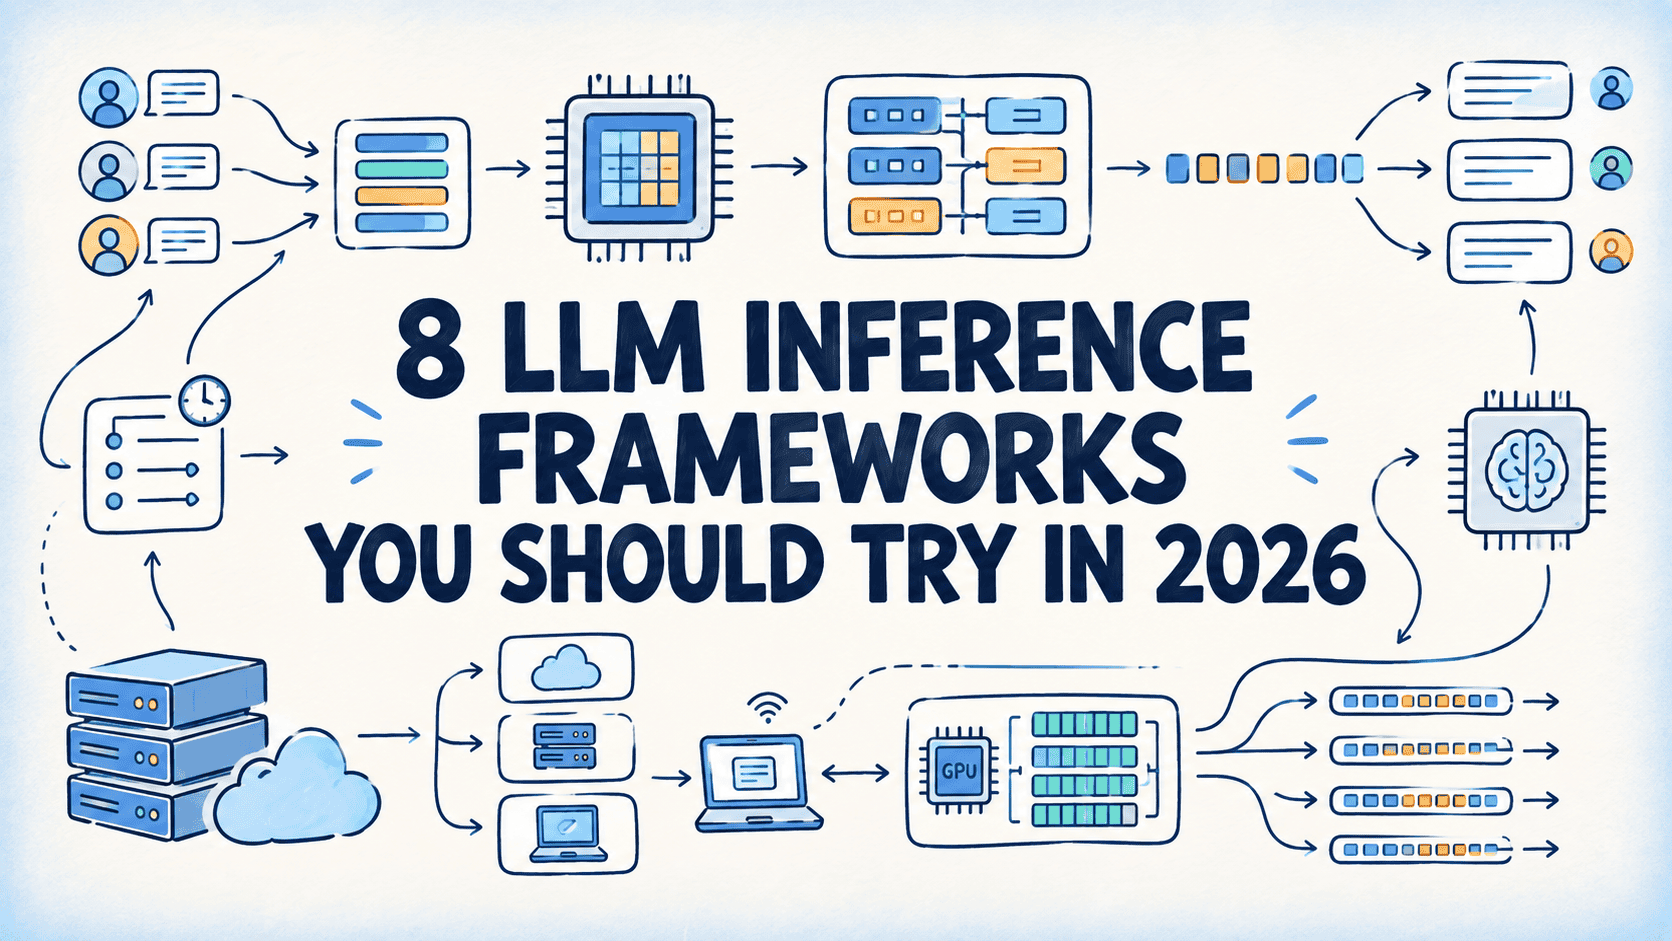
8 LLM Inference Frameworks You Should Try in 2026

Compare LLM inference frameworks for production serving, request batching, KV cache management, and efficient deployment.

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.