freecodecamp.org /1 week ago

Build and Train a GLM-5.3-Flash Model From Scratch with Python

GLM-5.3-Flash combines linear and sparse attention, a mixture-of-experts design, and manifold constrained hyperconnections. A scaled-down version with 25 million parameters can be...

Read source
medium.com /3 weeks ago

Krea 2 LoRAs Explained. Train on RAW, Create With Turbo.

A practical way to separate model choice, dataset preparation, and the test that tells you whether training actually helped.Continue reading on Futura Creative »

Read source
mql5.com /1 month ago

Astra Neural Engine: Gold M30 Demo Setup and Personal Model Training

Read source
medium.com /1 month ago

Train your own decision model: the decision tier is now a 40-minute fine-tune

On 28 September Unsloth began serving Laya, an open decision model, at a Jev-compatible endpoint on a CPU. On 7 October it shipped…Continue reading on Medium »

Read source
databricks.com /1 month ago

Reducing Qwen training time by 6x on AI Runtime

Training or finetuning a multi-billion parameter foundation model requires significant compute...

Read source
machinelearningmastery.com /2 weeks ago

How to Train Your own Decision Model like Jev using Unsloth

In this article, you will learn how to turn an open-weight language model into a decision model that classifies user intent, by fine-tuning Qwen3.5-4B on...

Read source
towardsdatascience.com /1 week ago

Scikit-Learn Matched or Beat Jev's Calibration on BANKING77

Jev needs no training and at most three examples per intent; the open rebuild needs labels. Both still fall into the none-of-the-above trap. The post Scikit-Learn Matched or Beat J...

Read source
medium.com /5 days ago

Test-Time Training Layers: What If the Hidden State Is Itself a Model?

Day 76 of an ongoing daily series on advanced machine learning conceptsContinue reading on Medium »

Read source
snowflake.com /2 weeks ago

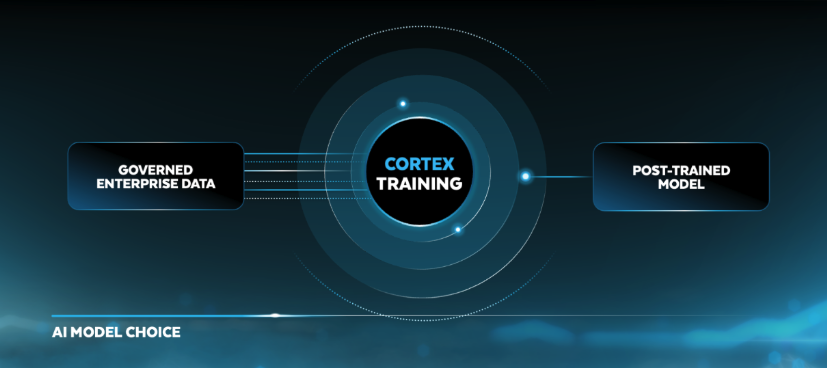
Cortex Training: Serverless Fine-Tuning for Open-Weight LLMs

Customize open-weight LLMs with SFT, RL and custom training loops on serverless GPUs. Cortex Training is now in public preview on Snowflake.

Read source
dzone.com /1 month ago

Building and Serving a Custom Model With Azure ML, Then Wiring It Into a Foundry Agent

The Foundry model catalog covers a lot of ground, but it doesn't cover everything. If you need a model trained on your own proprietary, tabular data, a churn predictor built on you...

Read source
ministryoftesting.com /1 week ago

Supervised Learning

Read source
towardsdatascience.com /1 month ago

Decision Models in Action: Build a Hybrid LLM Workflow

A hands-on guide to building browser automation by combining decision models with LLMs. The post Decision Models in Action: Build a Hybrid LLM Workflow appeared first on Towards Da...

Read source
medium.com /1 month ago

Building an LLM From Scratch: What It Really Takes to Train a Language Model

You don’t need a billion-dollar AI lab to understand how large language models work. You can build a small one yourself — and learn why…Continue reading on Data Science Collective...

Read source
aws.amazon.com /4 weeks ago

Announcing new ways to customize models with SageMaker AI, without managing GPUs

Amazon SageMaker AI serverless model customization now includes training sessions, generally available today. You write and coordinate your own post-training loop (custom loss func...

Read source
blog.gopenai.com /1 week ago

How to Fine-Tune an LLM With LoRA: Rank, Target Modules and Evaluations That Prove It Worked

A Hands-On Guide to PEFT and TRL: Choosing Rank and Alpha, Masking the Loss Correctly and Measuring Whether the Adapter HelpedContinue reading on GoPenAI »

Read source
medium.com /1 month ago

Module 3: ML for Classification

In module 3 of Machine Learning for Classification, I learned how to: 🔷 Train and use logistic regression models. 🔷Encode categorical…Continue reading on Medium »

Read source
mql5.com /3 days ago

How ONNX Artificial Intelligence Is Trained and Maintained in Quantitative Trading

Read source
prunderground.com /1 month ago

Mind Lab Opens Mint Recursive Post-Training to Enterprises Building Industry-Specific AI Models

Mind Lab's Mint Recursive covers benchmark design, data, post-training, inference and deployment in one workflow, with specialist training starting at $1,000 The post Mind Lab Open...

Read source
medium.com /1 month ago

LLM Coding Interview Series: 1/30 [Tensor Thinking]

NumPy and PyTorch Skills Every LLM Interview TestsContinue reading on Models to Systems »

Read source
medium.com /1 month ago

Model Merging: Combining Many Fine-Tuned Models Into One, Without Training

Day 47 of an ongoing daily series on advanced machine learning conceptsContinue reading on Medium »

Read source
kdnuggets.com /1 week ago

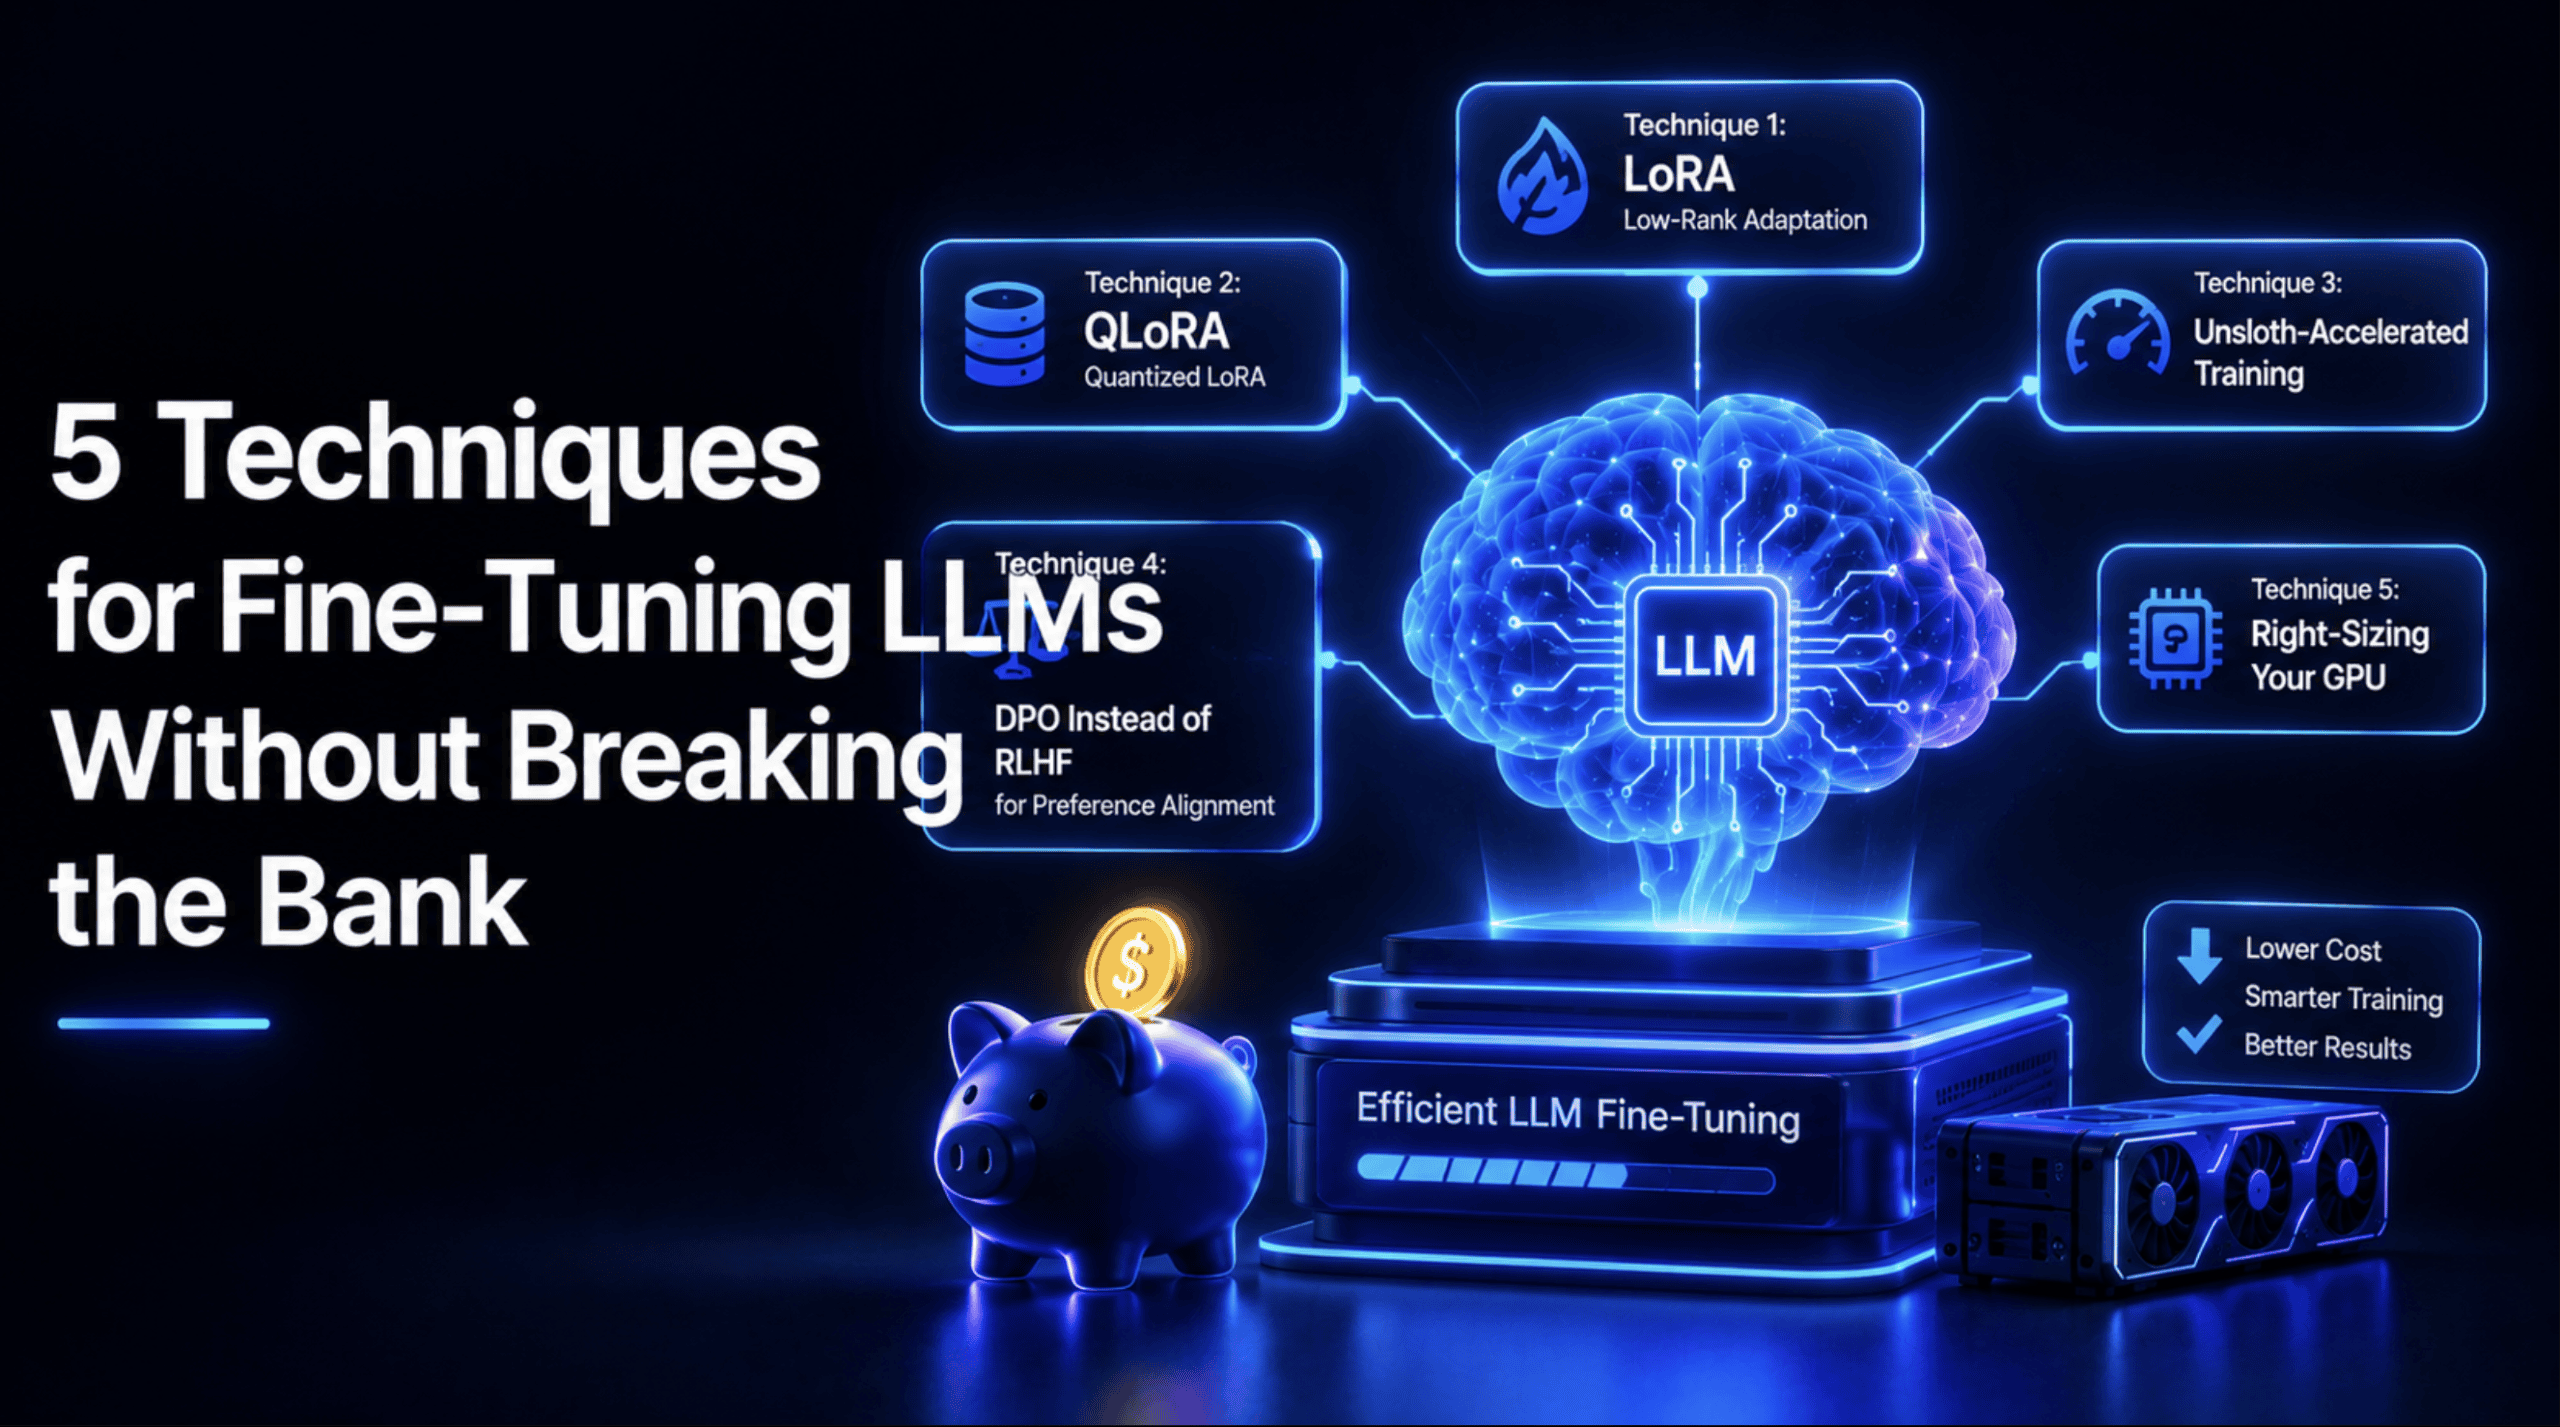
5 Techniques for Fine-Tuning LLMs Without Breaking the Bank

Learn five practical ways to fine-tune LLMs on a budget, from LoRA and QLoRA to Unsloth, DPO, and right-sizing your GPU, with working code for each technique.

Read source
elearningindustry.com /2 days ago

Actionable Course Evaluation Insights: How to Build a Simulated Dataset?

The best way to test your machine learning or GenAI approach for course evaluation analysis is to create a simulated dataset that includes planned themes and common traps. This pos...

Read source
medium.com /3 weeks ago

Snowflake ML in Practice: Train, Register, Promote and Serve Models

A dev-to-prod model lifecycle with the Snowflake Model Registry — and what has changed since early Snowflake MLContinue reading on Medium »

Read source
medium.com /1 month ago

Machine Learning Pipeline and Data Preprocessing: A Complete Practical Guide

From Raw Data to a Trained, Evaluated, and Deployment-Ready Machine Learning ModelContinue reading on Medium »

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.