towardsdatascience.com /2 days ago

LightGBM vs. a Four-Week Average for Forecasting Bike-Share Rentals

A 48-hour Capital Bikeshare experiment pits XGBoost, Ridge, SARIMA, and Prophet against simple baselines, with care for missing hours and leakage. The post LightGBM vs. a Four-Week...
Read source
machinelearningmastery.com /5 days ago

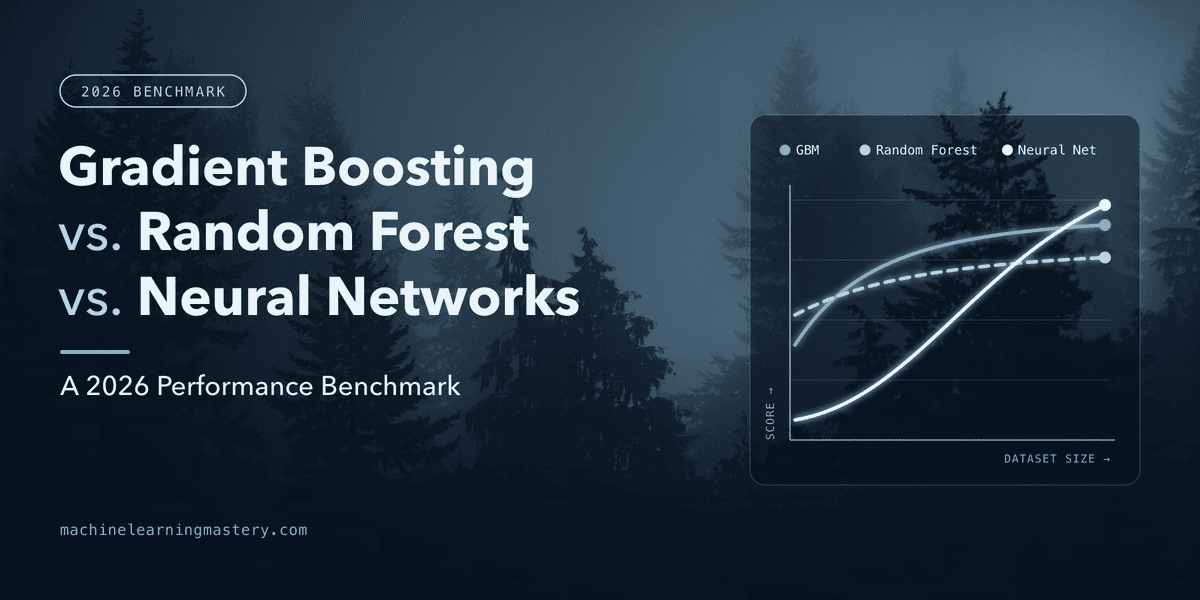
Gradient Boosting vs. Random Forest vs. Neural Networks: A 2026 Performance Benchmark

In this article, you will learn how gradient boosting, random forest, neural networks, and tabular foundation models compare on accuracy, speed, and data requirements in...

Read source
machinelearningmastery.com /2 weeks ago

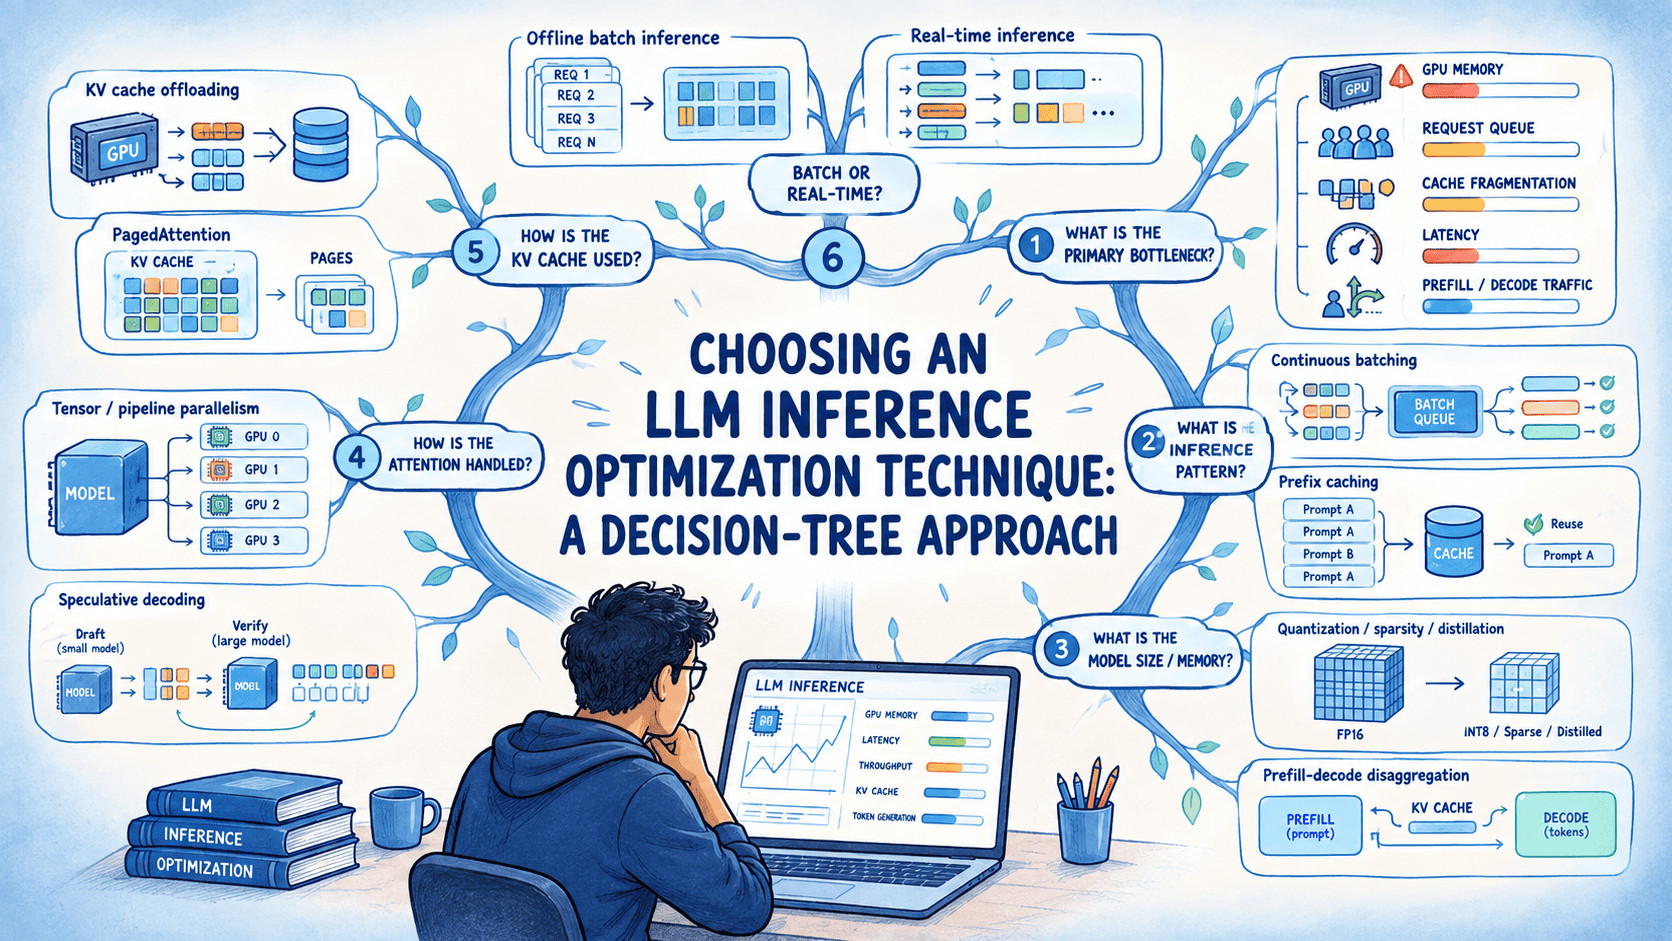
Choosing an LLM Inference Optimization Technique: A Decision-Tree Approach

In this article, you will learn how to match an LLM inference optimization technique to the actual bottleneck in your workload by working through a...

Read source
freecodecamp.org /1 week ago

Build and Train a GLM-5.3-Flash Model From Scratch with Python

GLM-5.3-Flash combines linear and sparse attention, a mixture-of-experts design, and manifold constrained hyperconnections. A scaled-down version with 25 million parameters can be...

Read source
kdnuggets.com /1 week ago

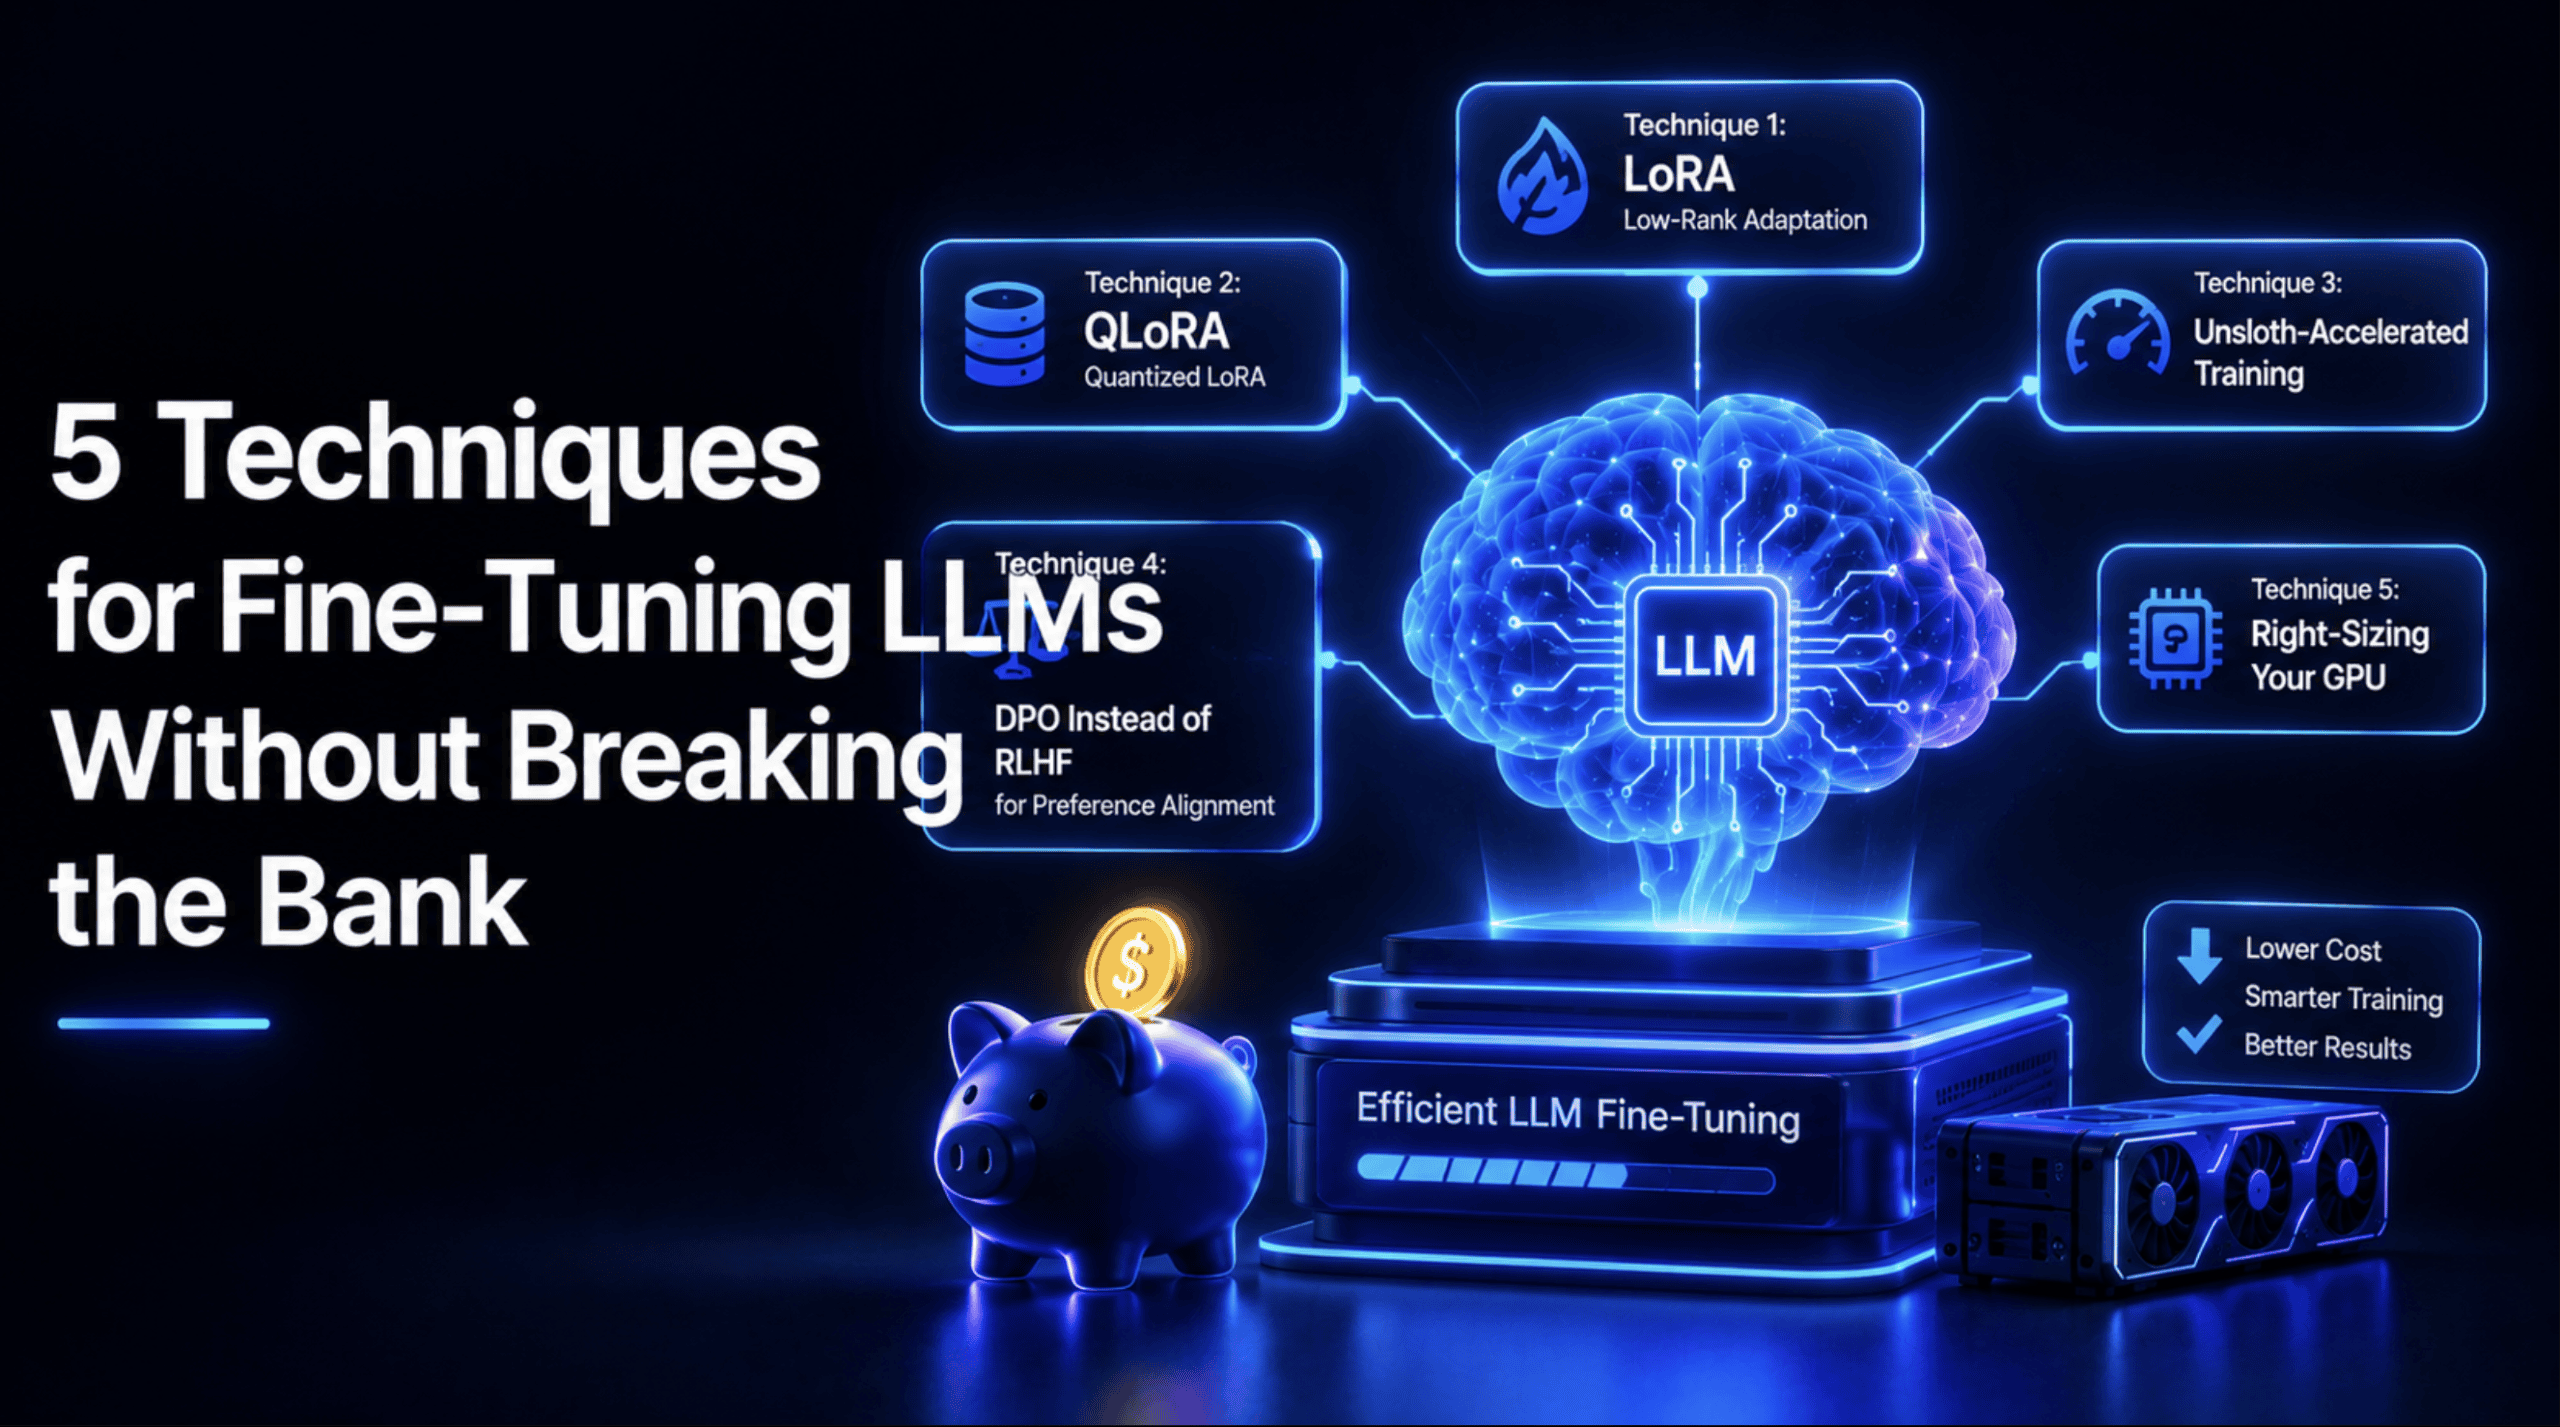
5 Techniques for Fine-Tuning LLMs Without Breaking the Bank

Learn five practical ways to fine-tune LLMs on a budget, from LoRA and QLoRA to Unsloth, DPO, and right-sizing your GPU, with working code for each technique.

Read source
medium.com /1 month ago

OOB Score vs. GridSearchCV for Random Forest Classification: Macro F1 and Search Time

On a three-class problem with imbalanced classes (50%, 35% and 15%), GridSearchCV over 648 Random Forest configurations took about 16.6…Continue reading on Medium »

Read source
kdnuggets.com /2 days ago

Comment on What are the Assumptions of XGBoost? by b"asta binance h"anvisningskod

I don't think the title of your article matches the content lol. Just kidding, mainly because I had some doubts after reading the article.

Read source
blog.gopenai.com /1 week ago

How to Fine-Tune an LLM With LoRA: Rank, Target Modules and Evaluations That Prove It Worked

A Hands-On Guide to PEFT and TRL: Choosing Rank and Alpha, Masking the Loss Correctly and Measuring Whether the Adapter HelpedContinue reading on GoPenAI »

Read source
pandaily.com /1 month ago

StartLux-Decision v1.1 Tops Decision Index 0.3.2 With Open Models That Think Only When Unsure

StartLux's 27B Instant model leads the community-run Decision Index 0.3.2 with a Full score of 69.12. The family spans eight open models from 0.8B to 27B under a non-commercial lic...

Read source
medium.com /5 days ago

The Rich and the Simple: On the Implicit Bias of Adam and SGD

GD implicitly biases towards ‘simpler’ solutions. Adam implicitly biases towards ‘richer’ solutions.Continue reading on Medium »

Read source
towardsdatascience.com /1 week ago

How to Check Local LLM Output with Ollama, Gemma 4, and Nimble

Gemma 4 E2B drafts the replies, Bespoke Labs' Nimble 9B picks accept, revise, or human review, and only flagged questions get a focused retry. The post How to Check Local LLM Outpu...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.