AI Agent Tracing: Spans, Tool Calls and OpenTelemetry
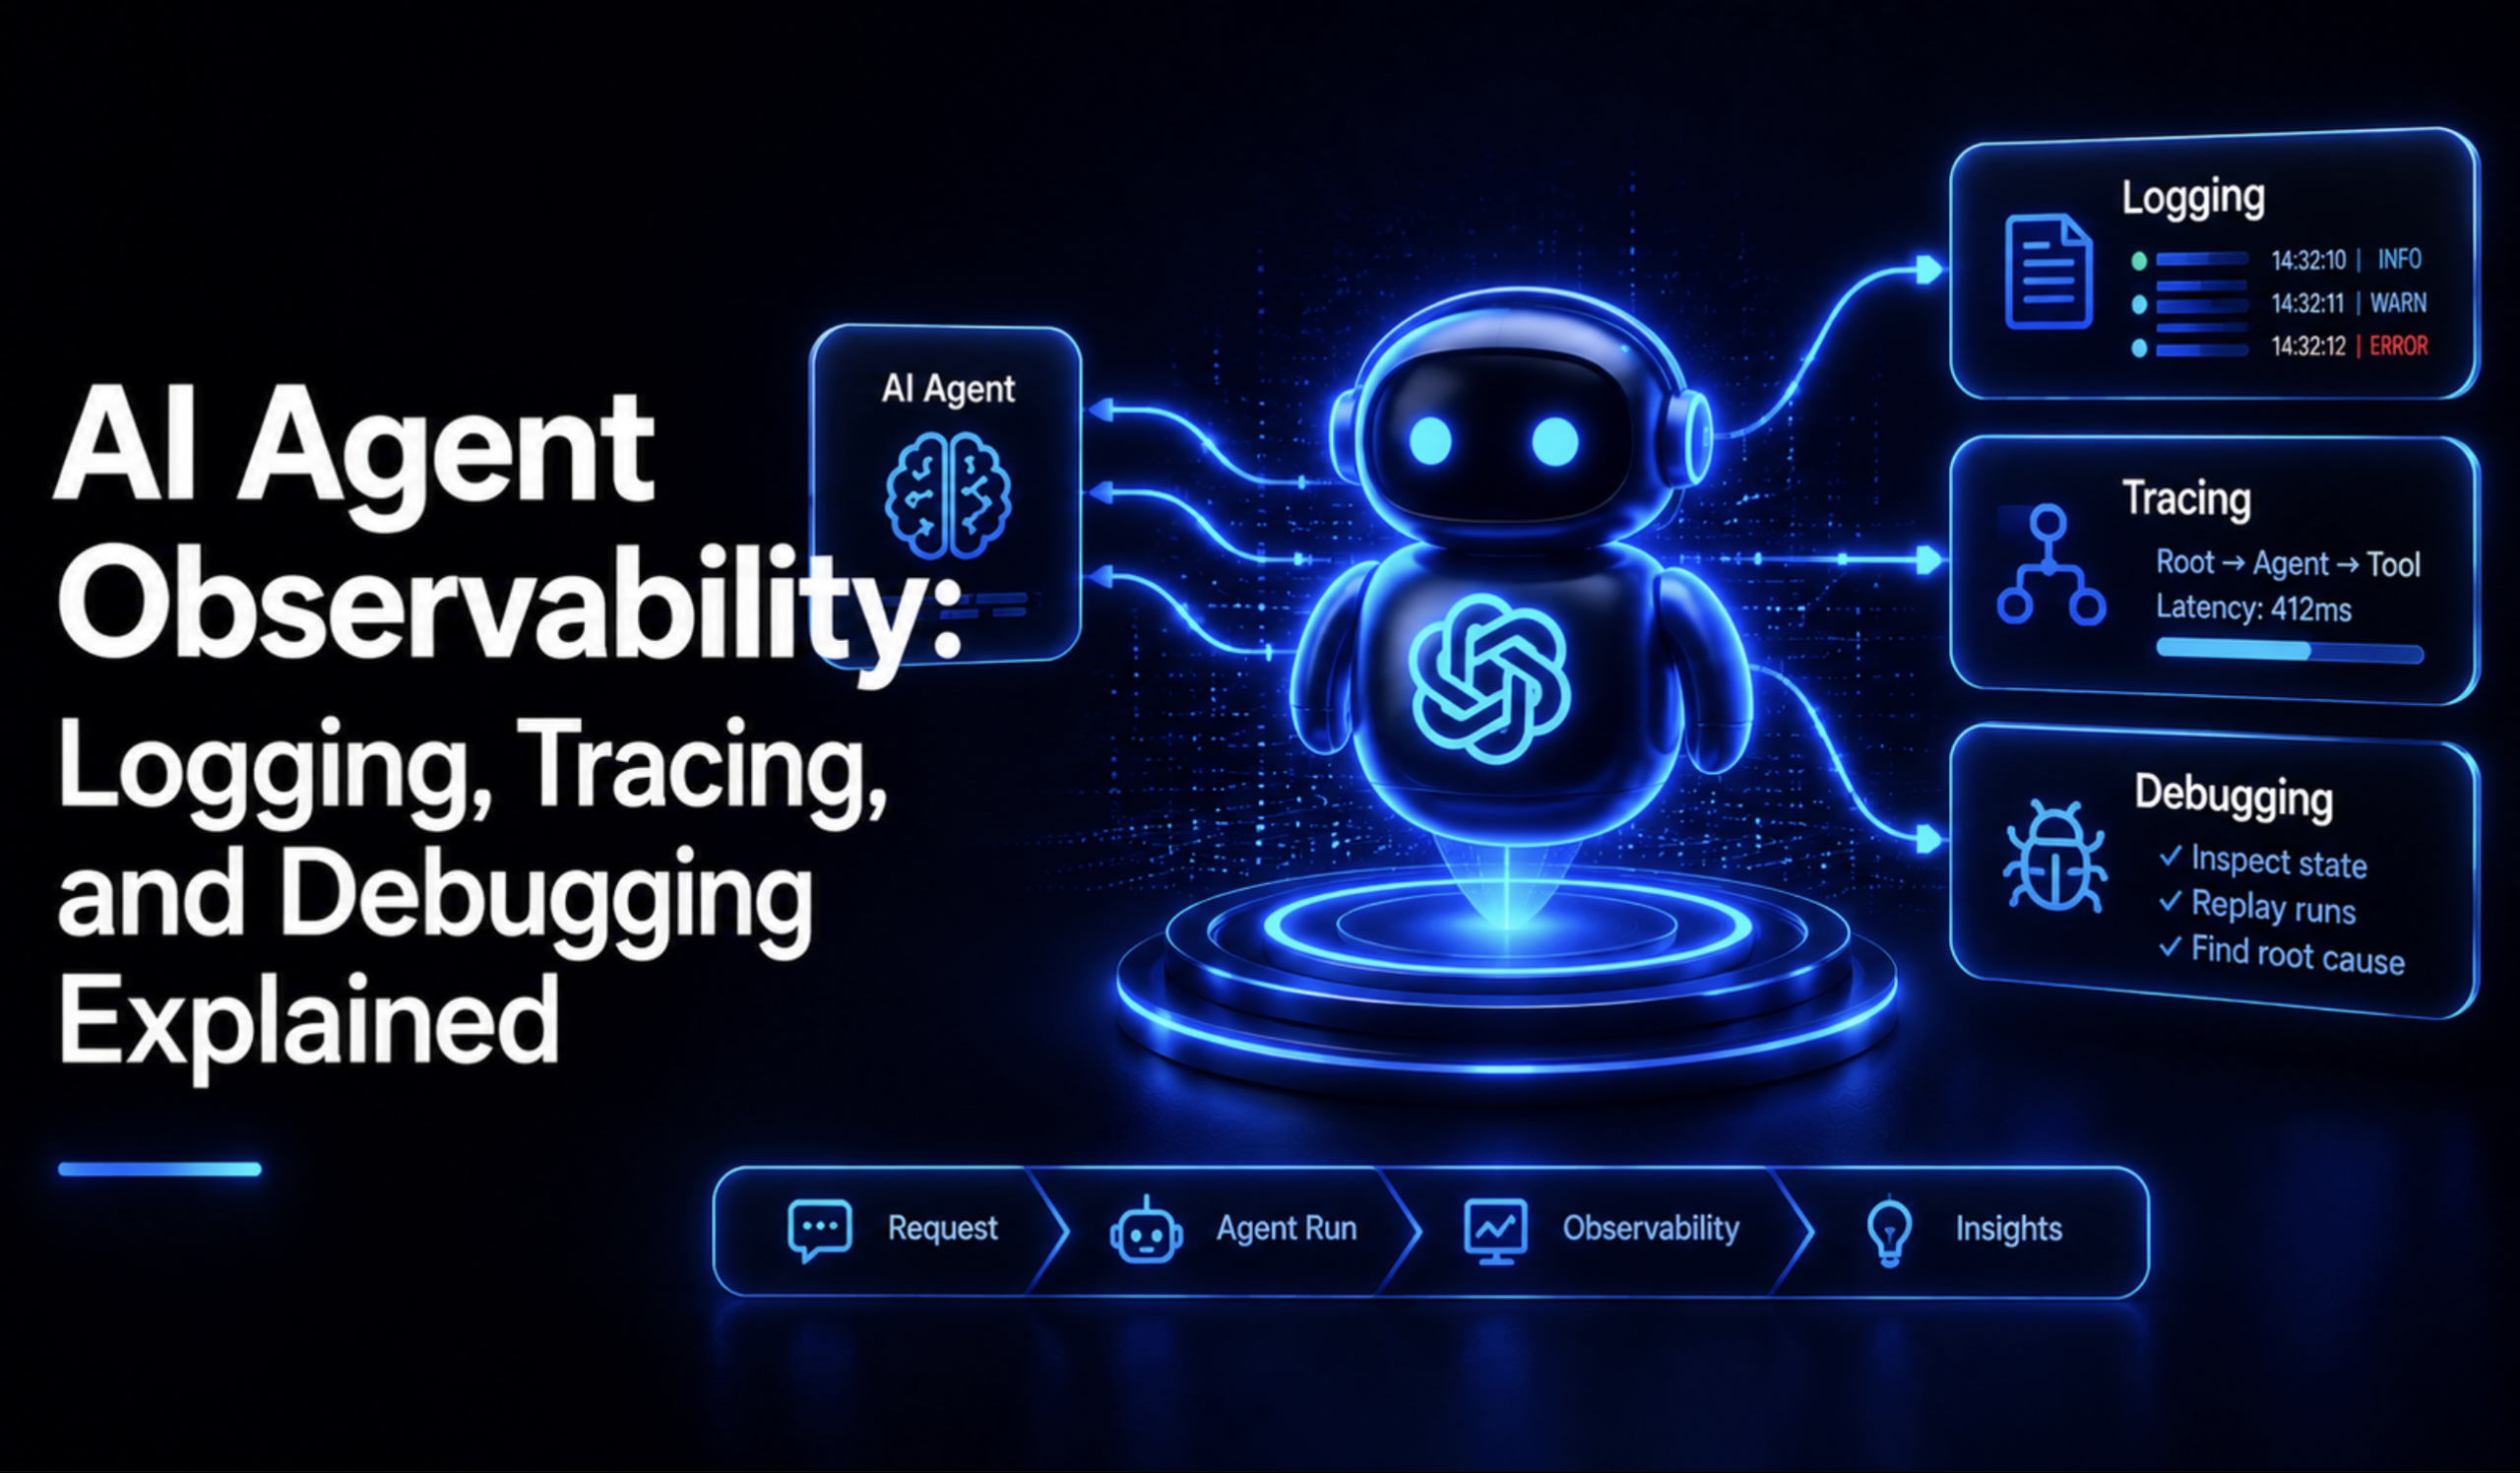
AI agent tracing explained: what an agent trace is made of, how OpenTelemetry names its spans, how context crosses MCP, and where a trace stops being evidence.
You’ve probably felt this one: GitHub Actions usage creeps up across your org, and your actual visibility into it doesn’t keep pace. Which workflows are slow? Which are flaky? How...
Getting code from a developer’s editor into production means building it, testing it, deploying it, and then understanding how it behaves once it’s running. Internal Developer Plat...
За время работы над разными проектами, в разных компаниях, я замечал одну похожую историю: все собирают трейсы, но пользы от них мало. Их просто никто не смотрит, потому что они не...
Enterprise context — Acme FinServ. SOC 2 CC7 (system monitoring) requires that Acme can detect and investigate anomalous activity. When an agent-driven workflow touches customer da...
OpenTelemetry (OTel) is a vendor-neutral, open-source standard for collecting traces, metrics, and logs from an application — collectively called telemetry. Before OTel, every obse...
Tracing, LLM-as-judge evaluations, and a Cost Optimizer that tests cheaper models on your own traffic.Continue reading on Medium »
Short answer: capture the error once, attach it to the agent turn that caused it, and record the retry as a separate event. For a logistics agent, the useful unit is not a red erro...
The last post was about the development toolbar Muru adds to each HTML page under muructl run, with the record Muru keeps of each request. That record can say a lot about how a req...
An agent built in Microsoft Foundry makes many decisions in a single run. It calls a model, selects a tool, reads the tool result, and calls the model again. When the answer is slo...
Chain Visualization: Reading the Trace Waterfall The spans from the last section don't mean much as a raw list.
Throughout my career, observability and monitoring systems have played a very important role in system stability, availability, and scalability when architecting, whether a system...
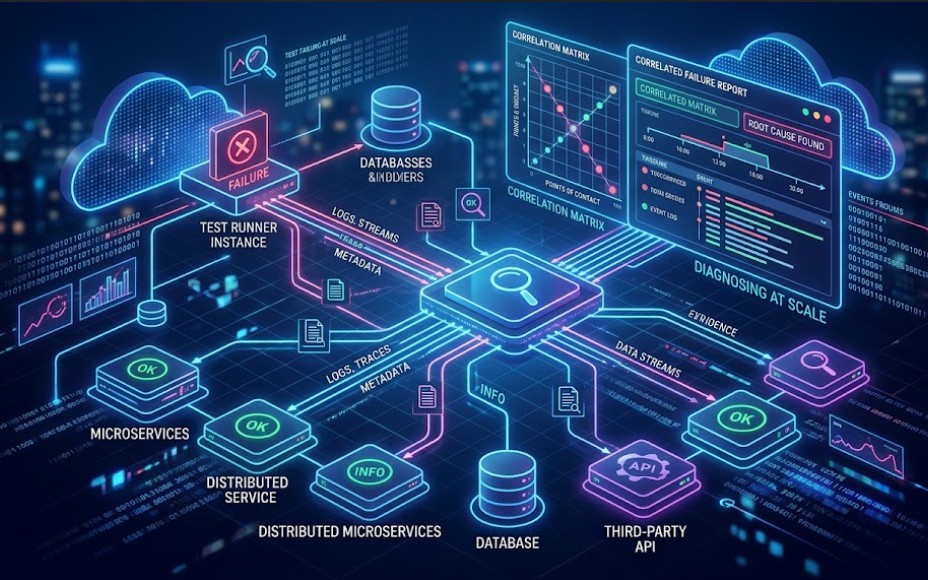
Intermittent test failures in a distributed CI/CD environment can slow down development and make failures harder to investigate. When an automated test suite fails on a local dev o...
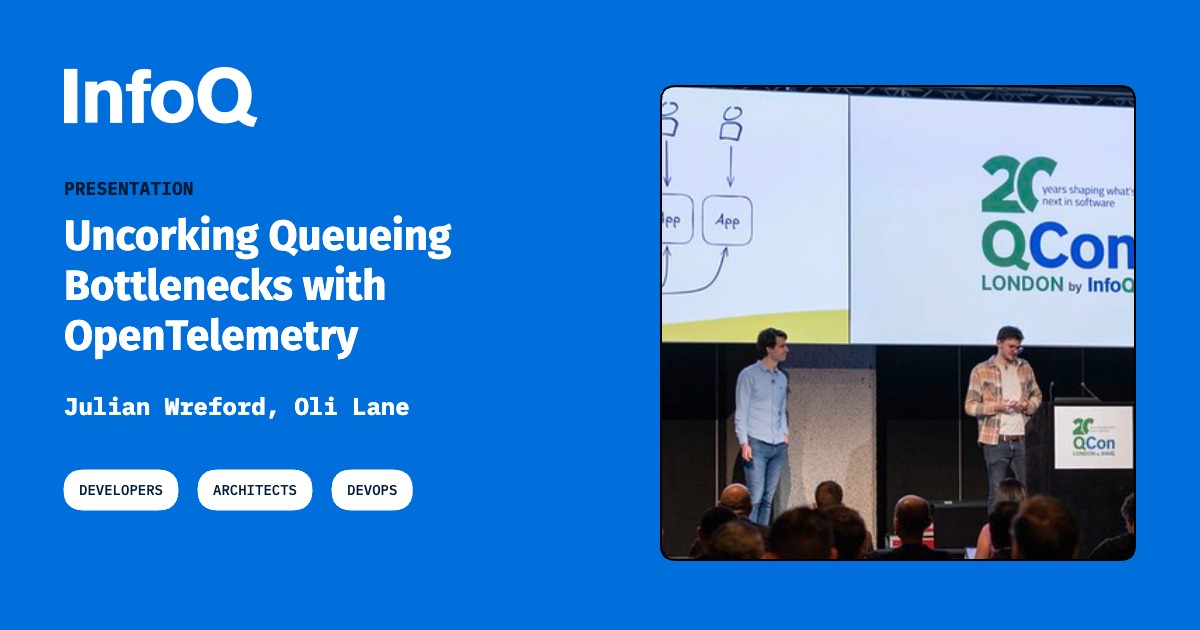
Oli Lane and Julian Wreford share how Gearset replaced guesswork in distributed asynchronous queues with OpenTelemetry tracing. They explain why traditional metrics fall short, how...
Learn how to trace two invisible threats in a multi-agent AI pipeline, prompt injection propagation and cross-tenant data exfiltration, using Amazon OpenSearch Service and Amazon B...
Cloud Tracing — сервис распределённой трассировки в VK Cloud. Приложения отправляют в него спаны по протоколу OpenTelemetry, сервис хранит их и отдаёт через Jaeger-совместимое API....
One trace, inside and outside Drupal: a proposal for Rosetta
Your JVM already ships with a profiler that is safe for production. Since JDK 14, it can also talk to you in real time. Why You May Not Need an Agent Many teams reach for a vendor...
Production bugs frequently arrive with too little evidence. A screenshot captures the final visual state, a crash report identifies a failing stack, and a support ticket describes...
Compare 11 AI observability tools for LLM tracing and monitoring in 2026: tracing model, OpenTelemetry support, self-hosting, and which tools changed owners.
See how Observe by Snowflake's Context Graph turns raw telemetry into linked datasets, so engineers and AI agents can trace why incidents happen, not just what happened.
Every SaaS company has the same uncomfortable question after a major incident: who noticed first, the monitoring or the customers? For a long time our honest answer was “it depends...
Nicholas Herring shares how EVE Online tackles distributed tracing and observability across a 20-year-old MMO architecture. He discusses leveraging head-based, dynamic exponential...
For the past decade, the gold standard of Site Reliability Engineering (SRE) was "all your telemetry in one place, beautifully rendered." Centralized platforms allowed teams to bui...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.