medium.com /1 month ago

Choosing a Generative AI Model for a Task: A Practical Comparison Guide

How to compare useful answers, response time, cost, and constraints without relying on one impressive demonstrationContinue reading on Medium »
Read source
testmuai.com /1 month ago

Sauce AI vs KaneAI: 2026 AI Test Authoring Comparison

Sauce AI vs KaneAI: how each writes tests from natural language, heals them, exports code and is priced, plus how to try KaneAI on a flow from Sauce AI.

Read source
uploadarticle.com /1 month ago

MiniMax M3 vs DeepSeek V4: Flash and Pro Compared for Coding, Agents, and Cost

Choosing an AI model for development is no longer just about finding the model with... The post MiniMax M3 vs DeepSeek V4: Flash and Pro Compared for Coding, Agents, and Cost appea...

Read source
prunderground.com /1 month ago

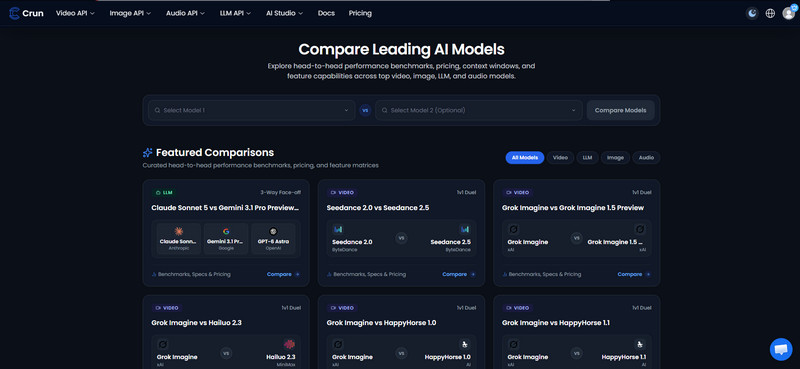
Crun AI Launches AI Leaderboard to Compare LLM, Video, Image, and Audio Models Side by Side

Crun AI unveils the AI leaderboard to compre leading models across LLM, Video, Image, and Audio by Performance and Price. The post Crun AI Launches AI Leaderboard to Compare LLM, V...

Read source
testmuai.com /1 month ago

11 Best AI Evaluation Tools for Production in 2026

The 11 best AI evaluation tools for production in 2026, ranked by seven criteria checked in vendor docs: online scoring, CI gates, alerts and self-hosting.

Read source
cryptobriefing.com /4 days ago

Epoch AI tests six leading LLMs, and none match its own employees

AI models excel in structured tasks but lag in nuanced human-like judgment, highlighting the need for human oversight in complex roles. The post Epoch AI tests six leading LLMs, an...

Read source
testmuai.com /4 weeks ago

LangSmith vs Braintrust: Evals, Tracing and CI Compared

LangSmith vs Braintrust, checked against each vendor's own docs: tracing, scorers, CI gates, pricing meters and self-hosting, plus a scorer test on 20 inputs.

Read source
towardsdatascience.com /1 month ago

Jev vs. LLMs: When AI Moves from Generation to Decision-Making

I tested TypeSafe AI’s Jev on 3,080 classification tasks to see how its accuracy, latency, calibration, and confidence compare with LLMs — and whether it works as a practical decis...

Read source
testmuai.com /1 month ago

9 Best AI Agent Observability Tools in 2026

Compare 9 AI agent observability tools on what each shows for a multi-step run: handoffs, sessions, MCP calls, agent evaluators, framework support and hosting.

Read source
visualcapitalist.com /3 days ago

Anthropic vs. OpenAI: Who’s Winning the AI Race?

Anthropic and OpenAI have traded the title of top AI model eight times since 2024. See who leads now, and how long they've held it.

Read source
digitalthoughtdisruption.com /1 month ago

ChatGPT vs Claude vs Gemini vs Grok vs Meta AI: Five Platforms, Five Different Approaches to AI

<p class="wp-block-paragraph"><strong>AI Assistant Decision Series</strong> | Part 1 of 6 | Product and source baseline: October 19, 2026.</p> TL;...

Read source
towardsdatascience.com /1 month ago

Jev Your Engines: Seven Open Decision Models vs. a Generative LLM

A hands-on Jev repo comparison of routing accuracy, latency, and output reliability The post Jev Your Engines: Seven Open Decision Models vs. a Generative LLM appeared first on Tow...

Read source
medium.com /1 month ago

When Are Two Mobile AI Runs Comparable?

A meaningful comparison starts with a shared question, a defined baseline, and a clear record of what changed.Continue reading on Medium »

Read source
blog.hubspot.com /1 month ago

Profound vs. Athena AI for AEO: How the tools compare

If you’ve searched “Profound versus Athena AI for AEO,” you’ve probably already hit a wall: every comparison you find is written by a competitor, an affiliate, or the vendors thems...

Read source
learn.g2.com /2 weeks ago

I Evaluated 12 AI Interview Agents: My Top 5 for Hiring Teams

TL;DR: Which is the best AI interview agent? Braintrust AIR leads G2’s Fall 2026 Grid® Report for AI Interview Agent with a G2 Score of 98. The right choice depends on whether y...

Read source
editorialge.com /2 days ago

GPT-6.2 Astra vs Claude Fable 5.2 vs Gemini 4 Carbon: What the AI Race Really Measures

GPT-6.2 Astra scores 62, Claude Fable 5.2 65 and Gemini Carbon 60. Explore the benchmark limits, earlier screenshots and Chinese competition. The post GPT-6.2 Astra vs Claude Fable...

Read source
thehackernews.com /1 month ago

AI Decision Models and Their Impact on AI SOC Platforms

In the space of a month, a new category of AI model went from nonexistent to everywhere. TypeSafe AI released Jev on September 15 and called it a System One model, a nod to Kahnema...

Read source
cryptobriefing.com /1 week ago

Artificial Analysis Coding Agent Index v2.1 refreshes its tests, and two Claude models tie at the top

The updated index highlights the evolving benchmarks in AI coding evaluation, emphasizing real-world applicability and comprehensive assessment. The post Artificial Analysis Coding...

Read source
testmuai.com /4 weeks ago

AI Hallucination Rate: What Each Benchmark Measures

An AI hallucination rate divides wrong answers by a count each benchmark picks. See what AA-Omniscience, Vectara, FACTS and SimpleQA Verified count, by model.

Read source
testmuai.com /1 month ago

BrowserStack Test Management vs TestMu AI (2026)

BrowserStack Test Management vs TestMu AI Test Manager: AI test case generation, Jira sync, imports, reporting, pricing model and how to move your test cases.

Read source
towardsdatascience.com /3 weeks ago

Is the #1 AI Model Really #1?

On a 2,000-question test, my top two models couldn't be told apart at the usual 5% level. On a 200-question version, a different model would have taken first place about three time...

Read source
onrec.com /3 weeks ago

Peec AI vs Scrunch vs GetMentions AI: Which One Turns AI Visibility Into a Usable Next Step?

Published by Onrec 28 Oct 2026|AI & AutomationPeec AI vs Scrunch vs GetMentions AI: Which One Turns AI Visibility Into a Usable Next Step?The harder buying question starts afte...

Read source
ministryoftesting.com /1 week ago

AI evals for quality engineers: a comprehensive guide to evaluating LLMs and agents

Read source
medium.com /1 month ago

Fixed Workflow vs. LLM Agent: Which Is Better for AI Automation?

Comparing traditional automation and AI agents through task success, execution time, cost, and reliability.Continue reading on Medium »

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.