Why Model Evaluation Matters: A Production Case Study
A model was already live, forecasting rain a day ahead. It looked done. Evaluating it properly is what showed it wasn’t.Continue reading on Medium »
G-Eval scores LLM output with model-written evaluation steps and a probability-weighted score. See how it works, a recount of its SummEval data, and its limits.
ROC, precision-recall, confusion matrix, calibration, learning curves, feature importance and SHAP — built straight from a classifier’s…Continue reading on Dev Genius »
On a 2,000-question test, my top two models couldn't be told apart at the usual 5% level. On a 200-question version, a different model would have taken first place about three time...
RAG evaluation metrics with formulas and a worked example: precision@k, recall@k, MRR, nDCG, faithfulness and answer relevancy, plus why frameworks disagree.
<strong>... [Trackback]</strong> [...] Find More to that Topic: kdnuggets.com/2020/05/model-evaluation-metrics-machine-learning.html [...]
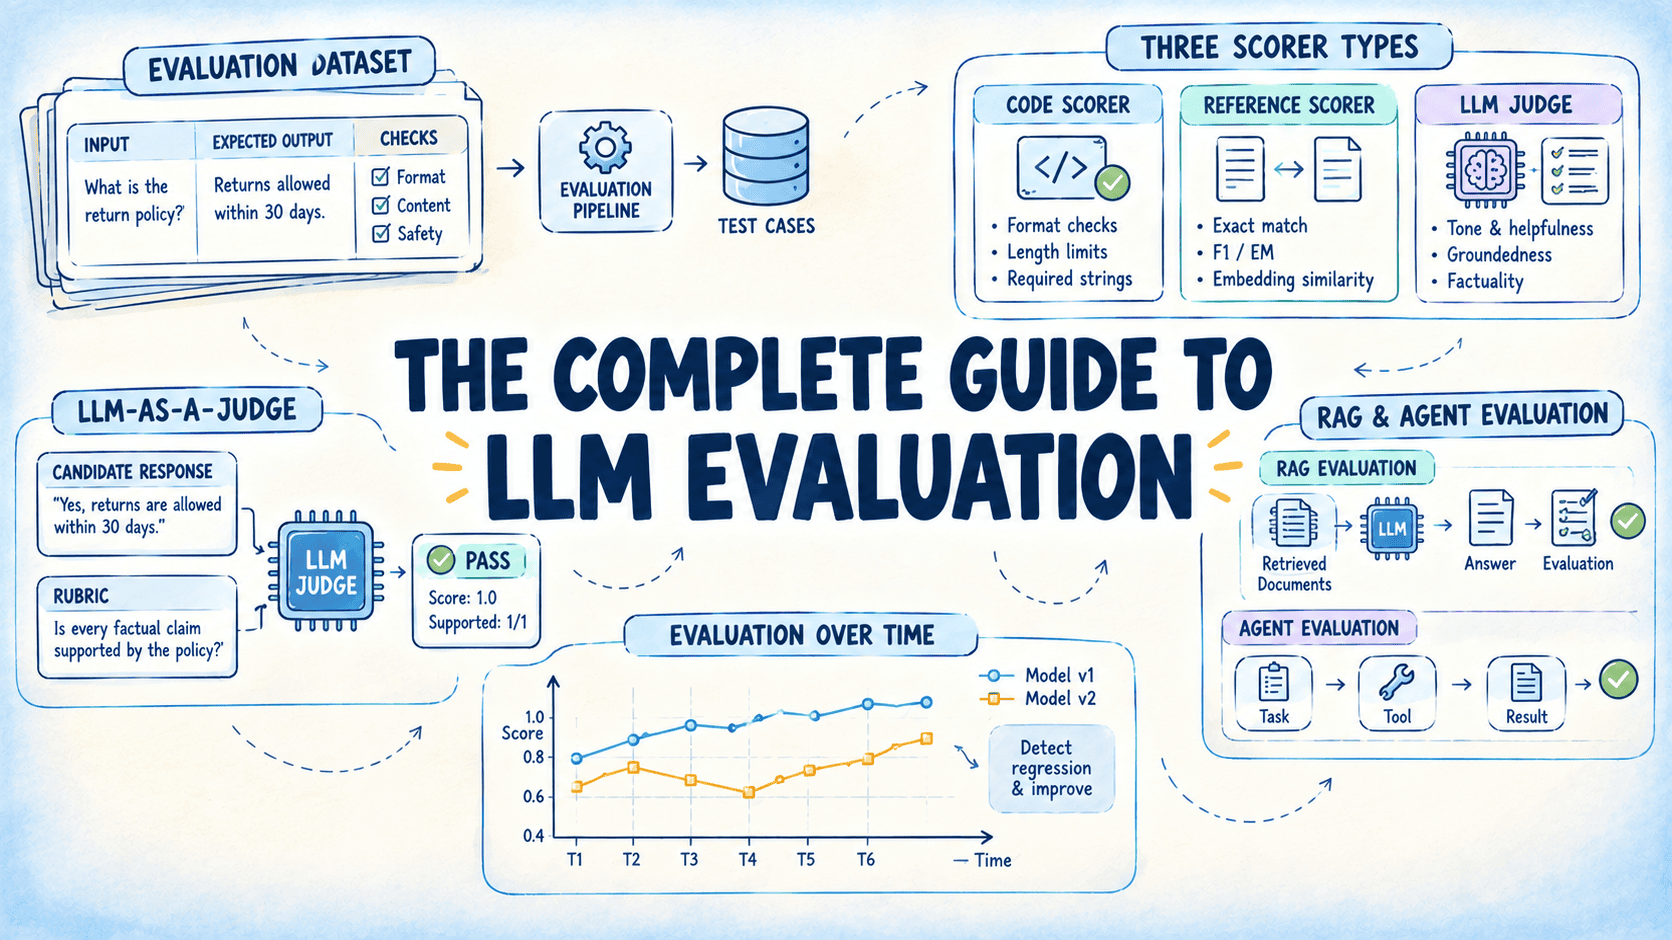
In this article, you will learn how to evaluate LLM applications systematically, from choosing scorers and designing reliable LLM judges to evaluating RAG systems and...
Some agent-evaluation questions are narrow and repeatable, and decision models answer exactly that kind of question. This post shows how to connect two decision models, Jev and Str...
How vague rubrics, reviewer disagreement, and weak data-quality processes can distort LLM performance resultsContinue reading on Medium »
Large language models (LLMs) can generate human-like responses, but fluent output does not necessarily mean correct or reliable output. An AI application may produce inaccurate ans...
LangSmith vs Braintrust, checked against each vendor's own docs: tracing, scorers, CI gates, pricing meters and self-hosting, plus a scorer test on 20 inputs.
Originally published on the Folkbench blog: https://folkbench.com/en/blog/did-the-model-get-dumber?utm_source=luntan&utm_campaign=mediumContinue reading on Medium »
The MMLU benchmark tests models on four-option questions in 57 subjects. See per-subject question counts and margins, label errors, variants and top scores.
Four gaps that sit between an offline number and what people actually experience — and the one test that exposes all of them.Continue reading on Medium »
Eval показывает 96% качества, тесты проходят, а после релиза LLM‑ассистент допускает критическую ошибку. Проблема может скрываться в самой системе оценки, которая пропускает опасны...
An LLM application can post a higher evaluation score and still become less useful in production. The contradiction is only apparent. An evaluation score is not quality itself, but...
All four time-series foundation models scale, patch, and predict quantiles; the real split is how series share information. The post Timestral, t0, Tabby, and Morpheus-2.0 Compared...
The 11 best AI evaluation tools for production in 2026, ranked by seven criteria checked in vendor docs: online scoring, CI gates, alerts and self-hosting.
AI agent evaluation metrics with a formula for each: task completion, tool accuracy, trajectory, cost and pass^k, trace fields needed and when each misleads.
A hands-on Jev repo comparison of routing accuracy, latency, and output reliability The post Jev Your Engines: Seven Open Decision Models vs. a Generative LLM appeared first on Tow...
Всем привет! В этом разборе расскажу, как в оценке агентных систем перейти от ощущений к измеримым показателям: как проверять траекторию вызовов инструментов, как калибровать LLM-с...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.