
cloud.google.com
/1 month ago
Google has announced a completely rewritten second edition of Site Reliability Engineering: How Google Runs Production Systems, ten years after the original book was published by O...
Cloud SLAs promise uptime statistically, not absolutely. This article shows how to treat observability as a control plane that detects regional degradation, triggers automated fail...
It’s 3:00 a.m. on a Saturday. An alert fires. Someone on call wakes up, logs into four tools, and starts piecing together what changed, what broke, and whether the two are related....
If your day starts with questions about reliability, performance, observability, incidents, scaling, or what is going to break next, there is no shortage of places to spend your ti...

Kubernetes observability: for regulated workloads Scale converts an informal convention into an outage mechanism. For kubernetes observability for regulated workloads, the decisi...
If you are responsible for keeping a production system alive, you have probably been pitched an "AI SRE" in the last few months. Maybe more than one. Maybe more than one this week....
For the past decade, the gold standard of Site Reliability Engineering (SRE) was "all your telemetry in one place, beautifully rendered." Centralized platforms allowed teams to bui...
GitLab is the intelligent orchestration platform for DevSecOps. GitLab enables organizations to increase developer productivity, improve operational efficiency, reduce security and...

Even well-designed systems can experience failure, especially in large modern environments that rely on cloud services, third-party services, and distributed systems. Instead of le...

вљЎ TL;DR: Ship without downtime or big-bang risk by matching recreate, rolling, blue-green, or canary to the change. Add automated analysis with rollback, and use feature flags to...

If you’re evaluating AI SRE products, you probably own most of one already. The coding agent your engineers use, whether that’s Claude Code, Codex or Cursor, can already investigat...
ПРЕДПРОСМОТР ДЛЯ ХАБРА · 7 НОЯБРЯ 2026 · ОКОЛО 12 МИНУТ«А что у нас менялось?» - с этого вопроса, к сожалению, начинается решаться очень много инцидентов. Ответ обычно собирается п...
Headquarters: Remote (USA - New York City, NY) PagerDuty, Inc. (NYSE: PD) is the global leader in AI-first digital operations. By automatically detecting, diagnosing, and remedia...

Resumo. Sistemas distribuídos em nuvem estão sujeitos a falhas parciais que dificilmente são reproduzidas por testes funcionais convencionais. Neste artigo, apresento o Chaos Engin...
Grafana Labs is the company behind Grafana Cloud, the fully managed observability platform trusted by more than 10,000 organizations to ensure reliability, resolve incidents faster...
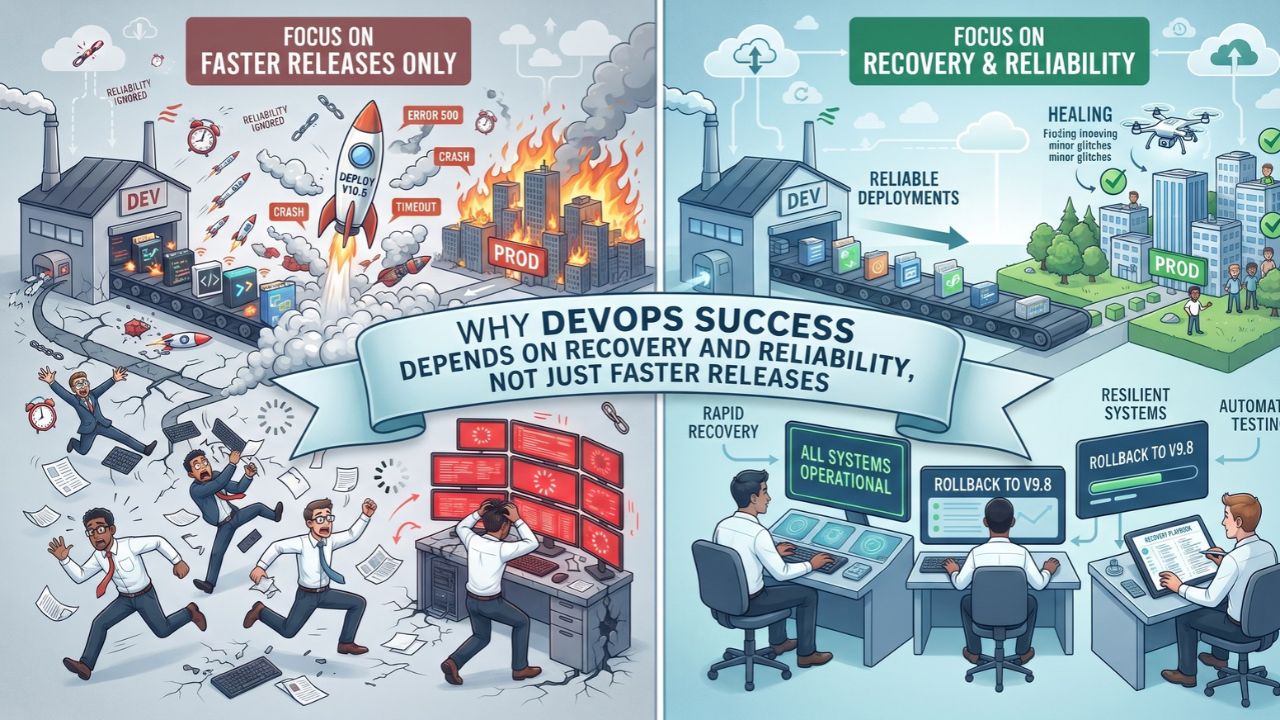
Release frequency has become one of the most visible indicators of DevOps maturity, and many... The post Why DevOps Success Depends on Recovery and Reliability, Not Just Faster Rel...
There is a meeting that repeats across a lot of European engineering organizations right now. Someone from legal or risk brings a NIS2 control, a DORA article, or a “can we evidenc...
Agents stall between demo and release when teams lack a repeatable way to measure how good an agent is and whether the last change helped. This post covers three agent properties t...
Distributed systems rarely fail as a single unit. More often, one dependency slows down, one shard becomes unavailable, one region loses capacity, or one pool saturates while neigh...
Learn an agent-driven approach to synthetic monitoring using Amazon Nova Act and Amazon Bedrock AgentCore. The post covers the architecture and patterns for resilient, managed user...
Role Description As an Infrastructure Software Engineer on Dropbox’s Orchestration team, you’ll build and operate the platforms that help engineering teams run services reliably...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.