Latest updates for Self Attention

Fresh curated links around Self Attention are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • What Is Attention Calculating?
  • Attention Is All You Need — The Birth of Transformers
  • You Don’t Actually Understand Attention. Neither Did I, Until I Rebuilt It From Scratch.

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

medium.com /3 weeks ago

What Is Attention Calculating?

Follow five tokens through dot products and causal masking to the weighted vector an attention head actually produces.Continue reading on Medium »

Read source
medium.com /4 weeks ago

Attention Is All You Need — The Birth of Transformers

If you have followed this series from the beginning, you’ve probably noticed a pattern. Every major breakthrough in deep learning solved…Continue reading on Medium »

Read source
medium.com /1 month ago

You Don’t Actually Understand Attention. Neither Did I, Until I Rebuilt It From Scratch.

A tutorial disguised as a confession, walking through the mechanism that quietly runs almost every frontier model, one honest step at a…Continue reading on Medium »

Read source
medium.com /1 week ago

LLM Coding Interview Series: 6/30 [Multi-Head, Multi-Query, and Grouped-Query Attention from…

Part 6 of the LLM Coding Interview Series ·Continue reading on Models to Systems »

Read source
medium.com /2 weeks ago

Where Do Queries, Keys, and Values Come From?

Calculate how learned projection matrices turn a token state into attention inputs, then change one weight and inspect the scores.Continue reading on Medium »
Read source
medium.com /2 weeks ago

Attention Is All You Need — for Retrieval Too?

Wait, is external retrieval in RAG actually redundant?Continue reading on AI Exploration Journey »

Read source
medium.com /2 weeks ago

Why Can’t Transformers Just Rearrange Their Matrix Multiplications?

Linear attention unlocks a matrix multiplication trick that standard attention can't use, but the speedup comes at a cost.Continue reading on Medium »
Read source
towardsdatascience.com /1 month ago

CBAM Paper Walkthrough: The Double-Attention Mechanism

Understanding and implementing CBAM (Convolutional Block Attention Module) from scratch with PyTorch The post CBAM Paper Walkthrough: The Double-Attention Mechanism appeared first...

Read source
dev.to /1 month ago

Attention Is All You Need: The Translation Problem That Led to ChatGPT

In the spring of 2017, Aidan Gomez was twenty years old, interning at Google, and sleeping in the office. At three in the morning, he and Ashish Vaswani were still working in a Go...

Read source
marktechpost.com /1 month ago

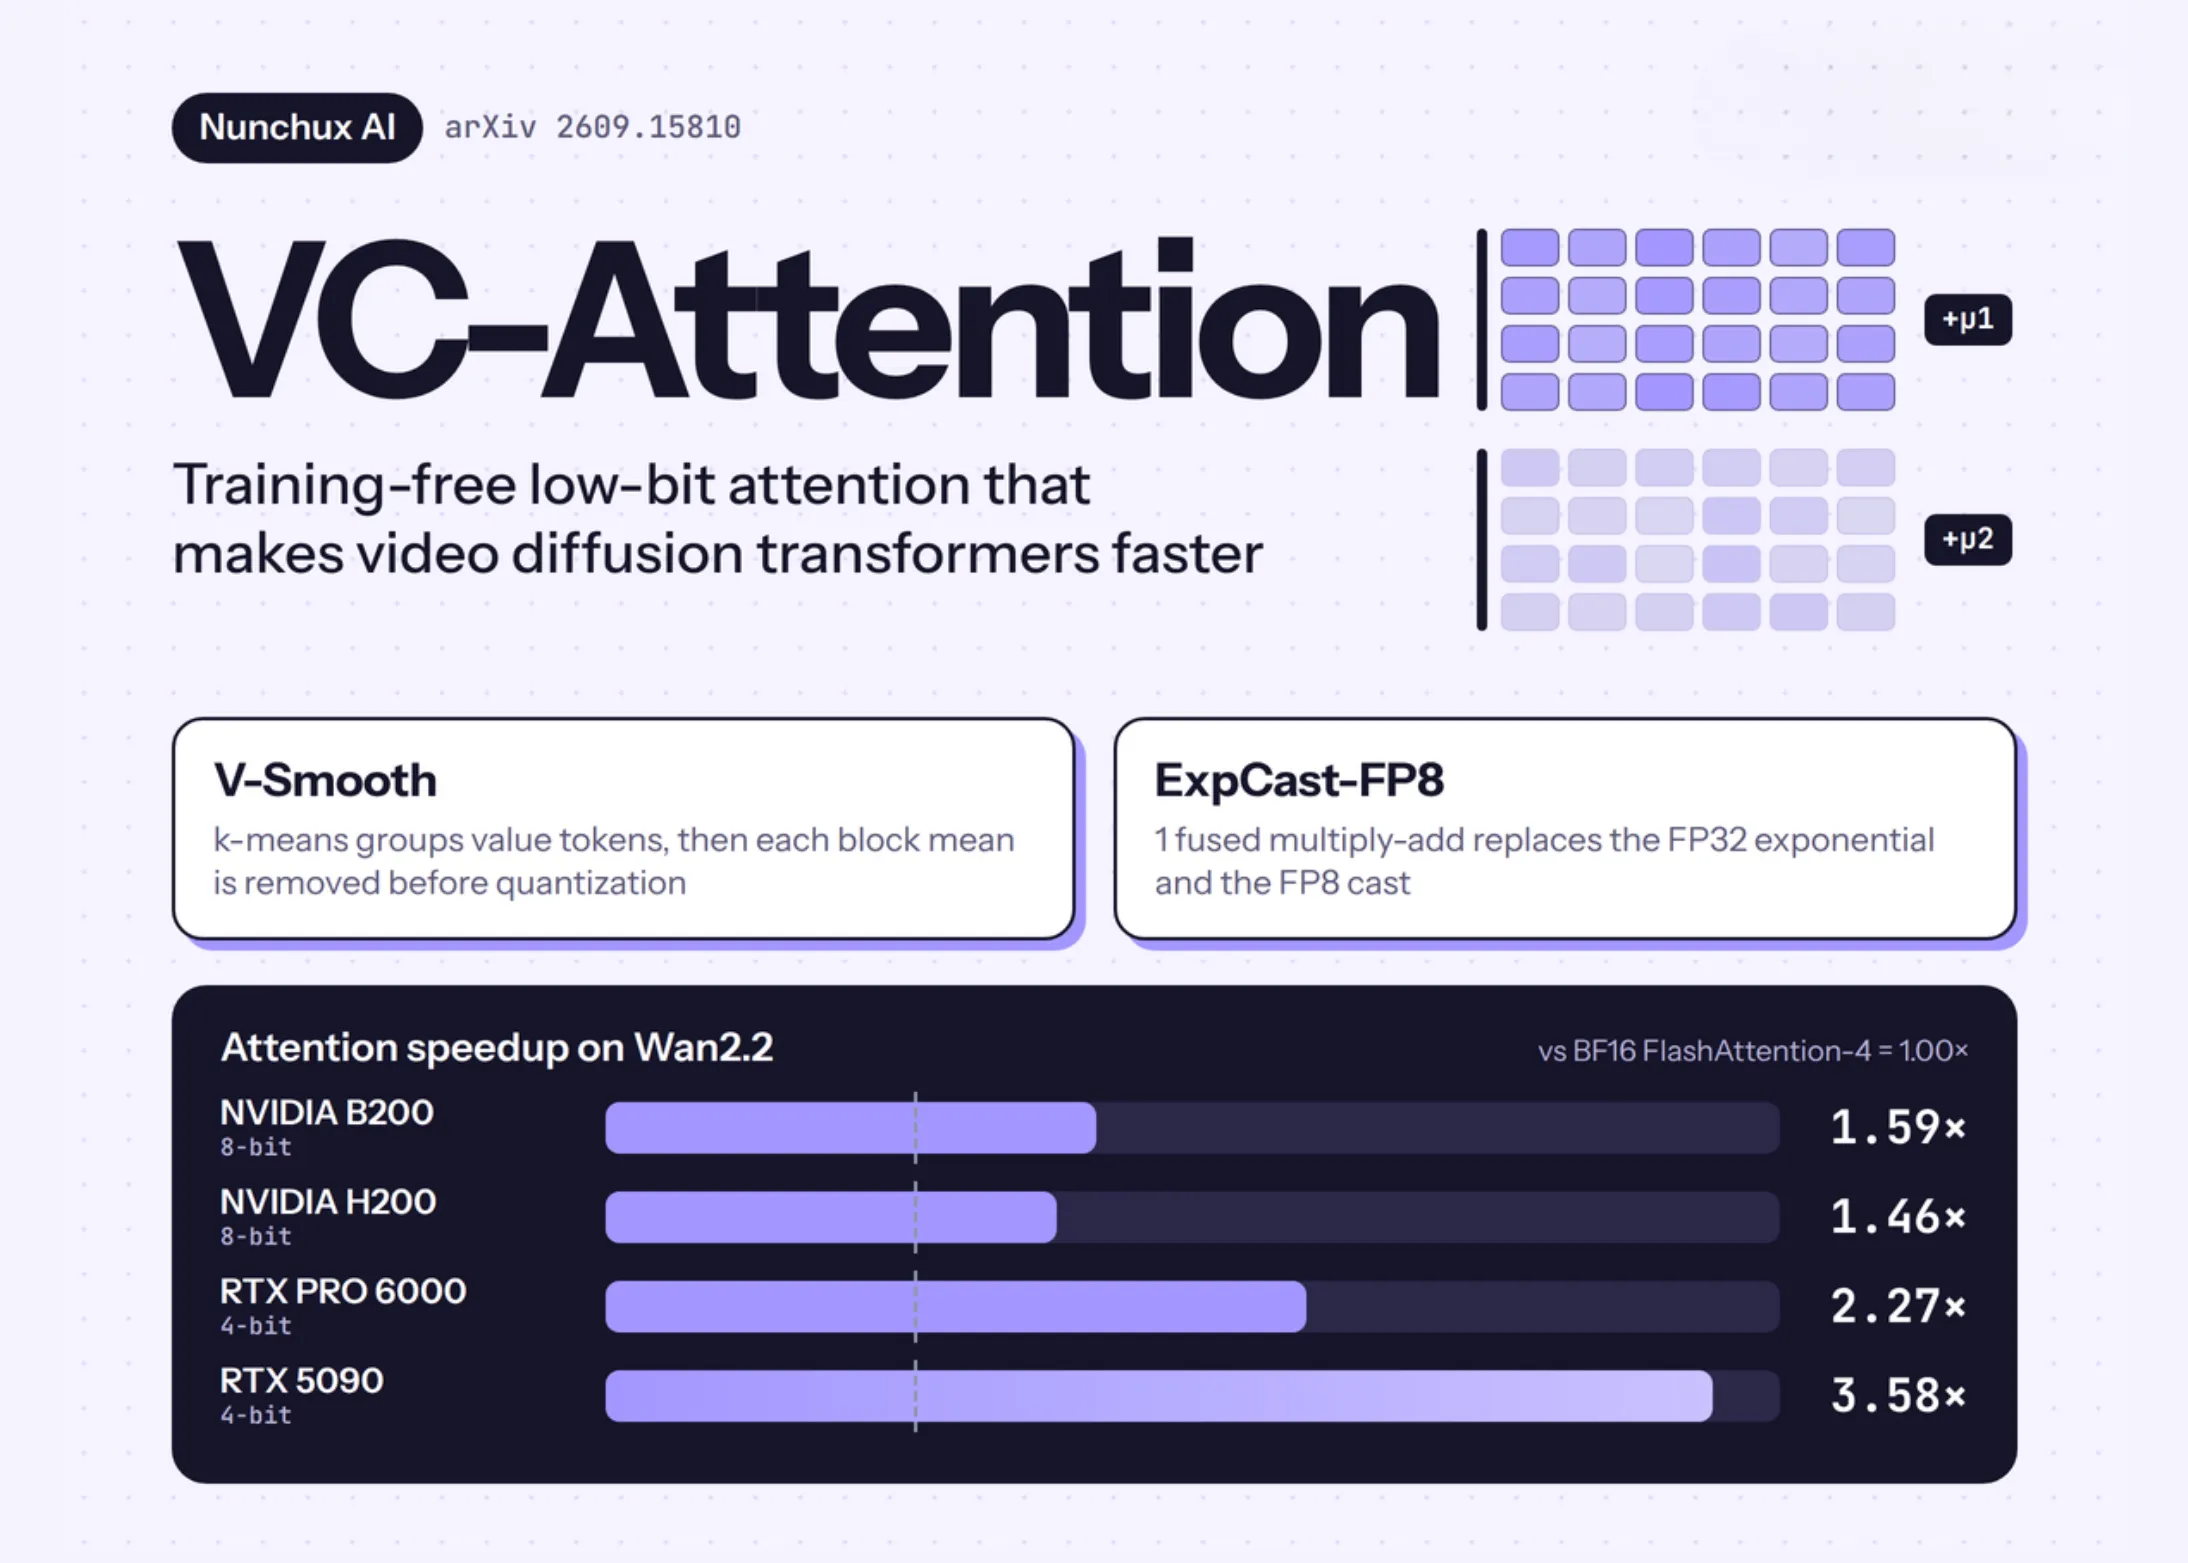
Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up Video Diffusion Transformers

Nunchux AI has released VC-Attention, a training-free low-bit attention kernel built for video Diffusion Transformers (DiTs). It targets 2 problems at once: value quantization erro...

Read source
uxdesign.cc /3 weeks ago

The economics of attention in the age of AI

When machines pay attention, what deserves ours?AI filtering the information reaching us, shaping the economics of human attention. AI-generated visual, Aurélie Radom ©For decades,...

Read source
themarginalian.org /1 month ago

How We Render Reality: Attention as an Instrument of Love

"Since our consciousness plays some part in what comes into being, the play of attention can both create and destroy, but it never leaves its object unchanged."

Read source
towardsdatascience.com /1 month ago

Why Transformers Need Positional Encoding For Time Series: A Visual Guide

From scalar observations to self-attention, and how positional information restores sequence order The post Why Transformers Need Positional Encoding For Time Series: A Visual Guid...

Read source
aws.amazon.com /4 days ago

Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch

Learn how i14 trained and served Laplace 3B, a linear attention model, on AWS Trainium2 using native PyTorch. Its recurrent state stays fixed at 29.5 MB per sequence regardless of...

Read source
bioengineer.org /2 weeks ago

New Attention-Driven AI Matches People Across Cameras Without Any Labels

Researchers have developed DELTA, an unsupervised domain adaptation model that combines a grouped divergence attention module with self-paced deep clustering to match people across...

Read source
towardsdatascience.com /4 weeks ago

Your LLM Has a Curved Space of Paragraphs

Inside a transformer, token index is a coordinate. Paragraph structure is what turns it into a metric. The post Your LLM Has a Curved Space of Paragraphs appeared first on Towards...

Read source
uxdesign.cc /4 days ago

Human attention is the new old bottleneck. We have to design for it even more.

A wide office floor where one person reads at a desk while dozens of screens around them keep filling with new work for them to address.Agents at Anthropic now log six hours for ev...

Read source
mindful.org /6 days ago

Attention Is Our Original and Shared Vocation

A reflection on the late poet Mary Oliver, and what her work modeled for us and asks of us now. The post Attention Is Our Original and Shared Vocation appeared first on Mindful.

Read source
habr.com /1 month ago

MoVA: новая архитектура внимания

Про архитектуру Mixture of Experts (MoE) слышал каждый, кто следит за ML: Mixtral и DeepSeek доказали эффективность динамического роутинга. Но пока индустрия осваивает базовый MoE,...

Read source
medium.com /1 month ago

Why I Couldn’t Just Prompt My Way to a Working Small Model

I fine-tuned Gemma-3–270M on 379 examples of one reasoning step.Continue reading on Medium »

Read source
pandaily.com /1 month ago

OPPO ColorOS 17 Adds On-Device Linear-Attention Model and Persona X Agents

At ODC 2026, OPPO unveiled ColorOS 17 with an on-device Linear Attention model (128K context, lower memory and energy), Persona X memory engine, and Agent Matrix upgrades for Breen...

Read source
simplilearn.com /1 month ago

How LLMs Work: Transformer Architecture Explained | Simplilearn

TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...

Read source
dzone.com /2 weeks ago

Does a Bigger Context Window Mean Better Memory: Understanding Context Windows, Model Memory, and RAG

The Confusion Starts With the Word Memory Imagine giving an AI assistant a large software repository, several months of incident reports, and a complete set of operating procedures...

Read source
medium.com /1 week ago

What If AI’s Biggest Skill Was Knowing What to Ignore?

Intelligence is often associated with learning more, remembering more, and processing more information. But what if one of the most…Continue reading on Medium »
Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Self Attention

feeds.dzone.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

bioengineer.org

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source

medium.com

Recent coverage from public sources
Public source