RAG vs Long-Context LLMs: Why Bigger Context Windows Do Not Solve Retrieval
Large Language Models can now process hundreds of thousands, and sometimes even millions, of tokens.Continue reading on Medium »
Search fresh public links, source activity, and ready-to-use post angles for Large-Language-Models.
Fresh curated links around large-language-models are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Large Language Models can now process hundreds of thousands, and sometimes even millions, of tokens.Continue reading on Medium »
Large Language Models (LLMs) have transformed the way applications process and generate natural language. They are widely used in chatbots, search systems, coding assistants, docum...
Aleph Alpha has released Kolibri, a 78.1B-parameter English-German Mixture-of-Experts model that activates only 3.46B parameters per token. It has a 1M-token context and per-reques...
Ant Group's inclusionAI published Ling-3.1-flash weights on Hugging Face under the MIT license, a 560B hybrid-linear MoE with 25B active parameters per token and a 1M-token context...
iFLYTEK's wholly-owned subsidiary launched and open-sourced Spark X2.5-4B and X2.5-1.7B, which it says are the first edge models to natively support up to one million tokens of con...
The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »
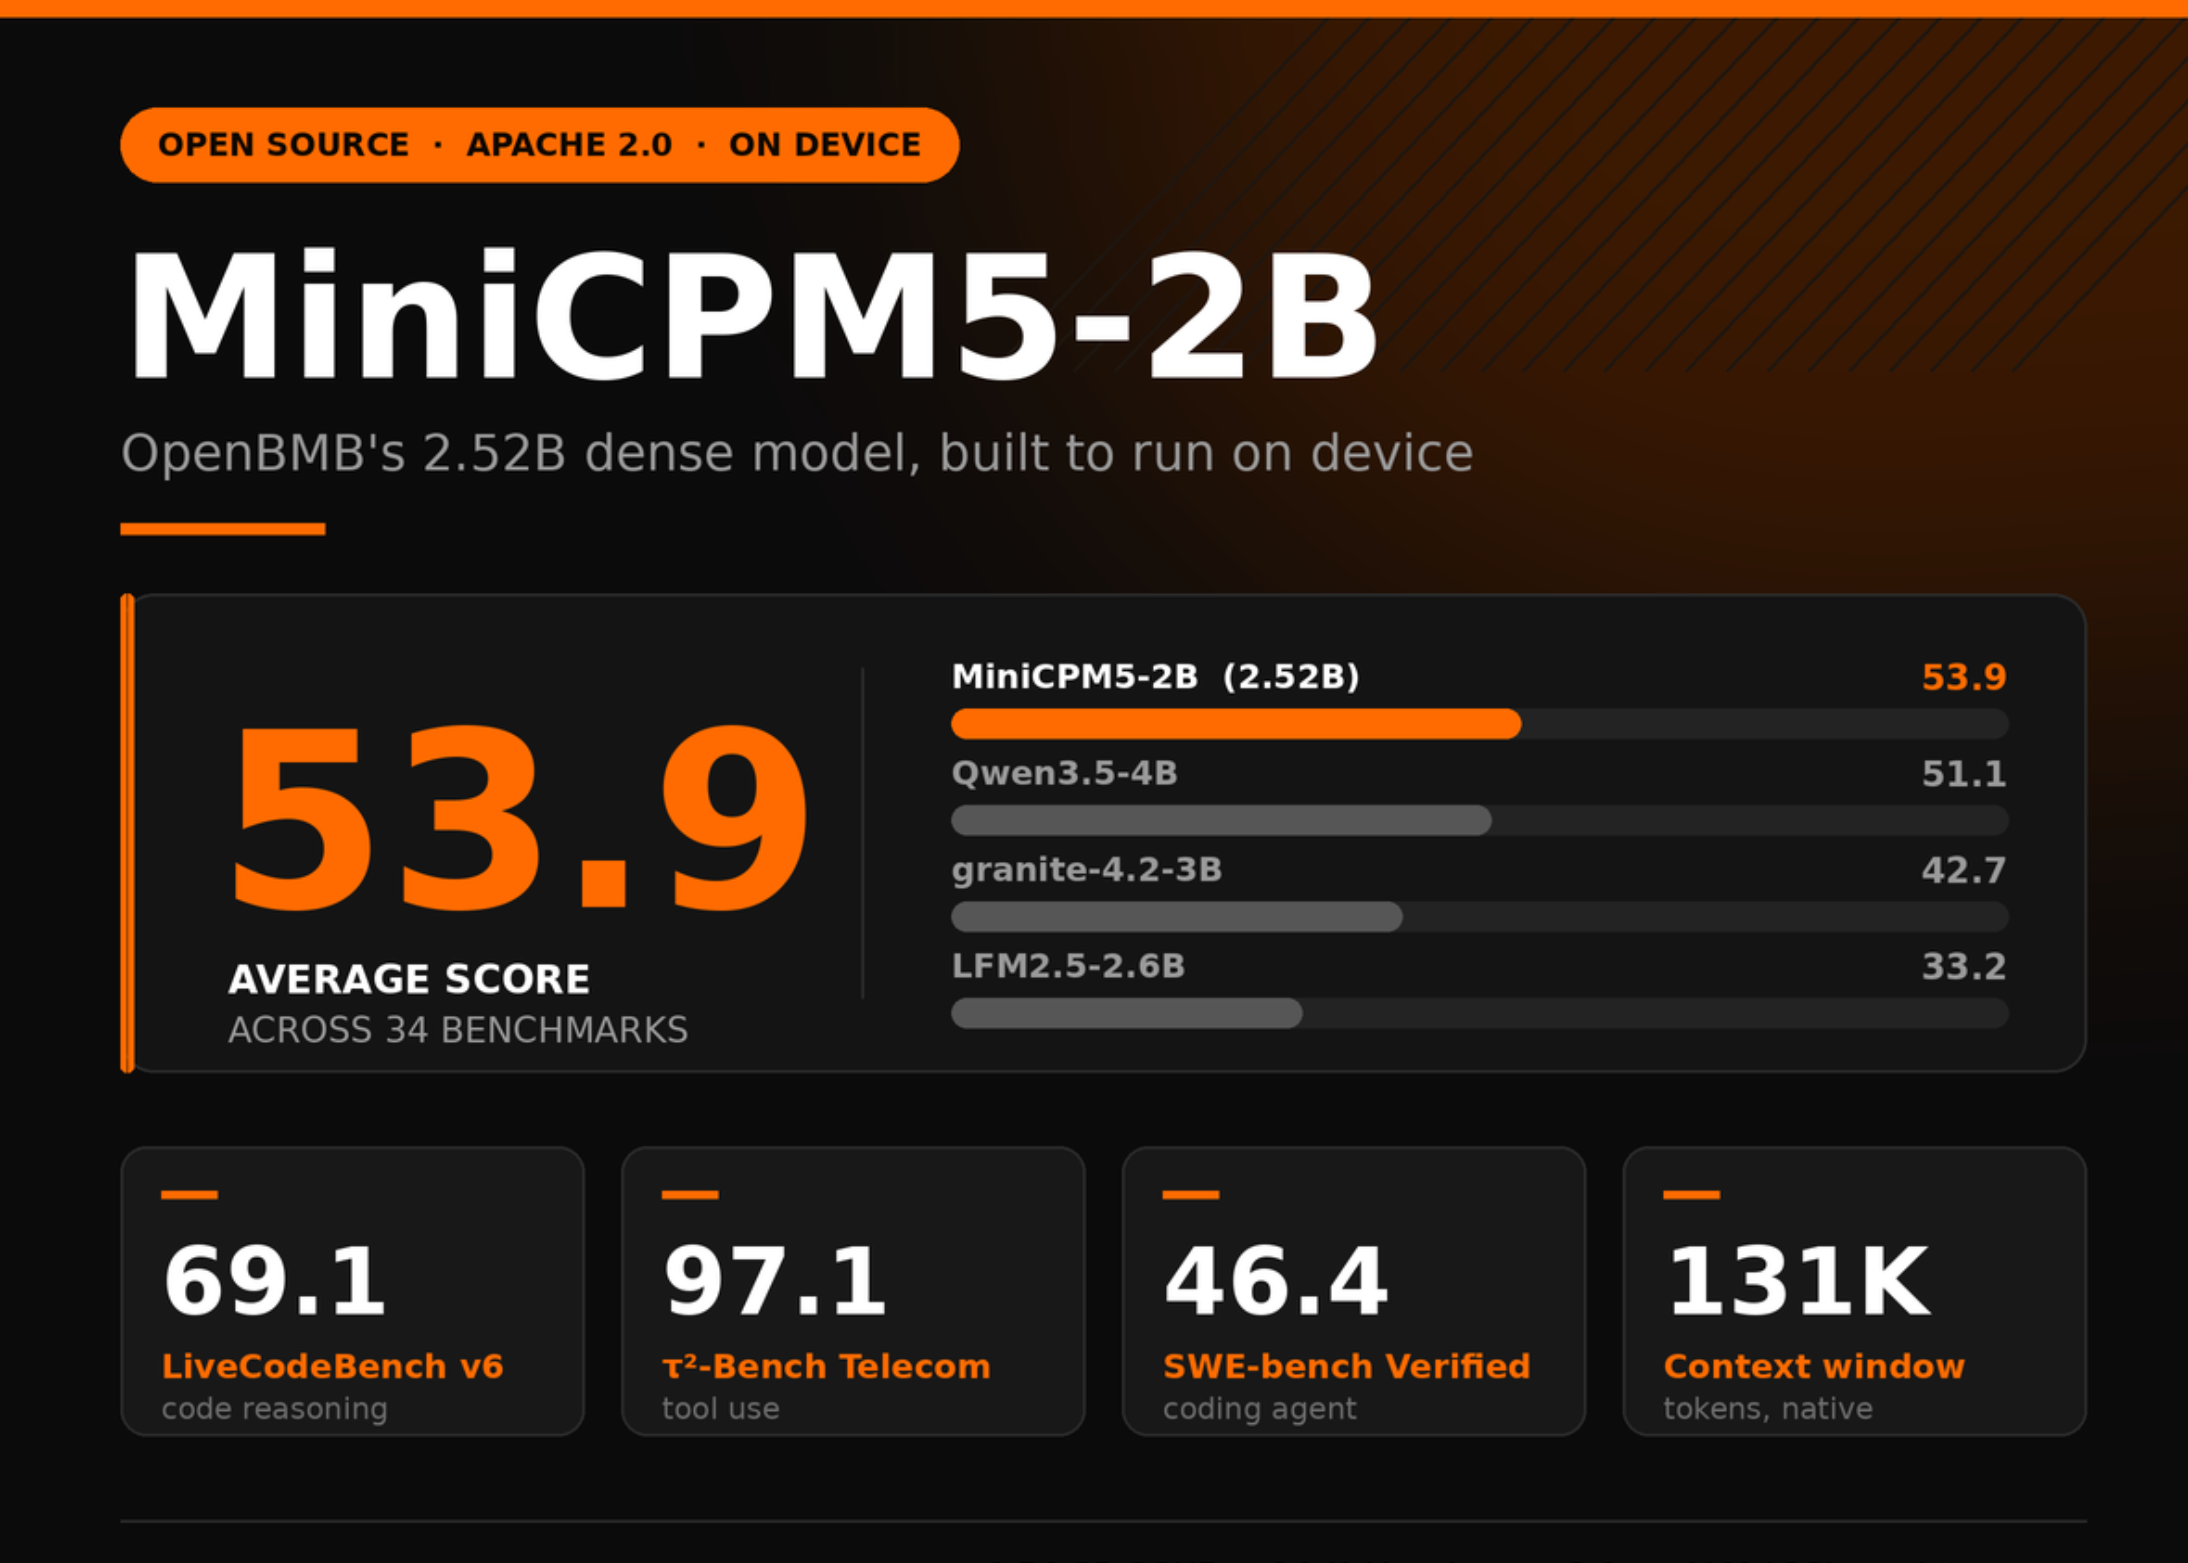
OpenBMB has released MiniCPM5-2B, a dense causal language model with 2,516,756,480 parameters and a native 131,072 token context. It averages 53.9 across the 34 benchmarks in its m...
Cohere has released North Small Translate, an open-weight Mixture-of-Experts model built for machine translation across 50 languages. It uses 25B of its 218B parameters per token a...
TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...
On August 28, Tencent Hunyuan released and open-sourced Hy4 preview, its next-generation large language model with 770 billion total parameters and a context window exceeding 1 mil...
Bilibili's Index LLM team released Index-Translate under Apache-2.0: 2B, 9B and 35B-A3B preview text models for 150 languages, plus dubbing, syllable-control and long-document vari...
A 24GB M4 Pro Mac mini can run a surprising number of AI models. I would still be careful with the word run. A model that opens…Continue reading on Medium »
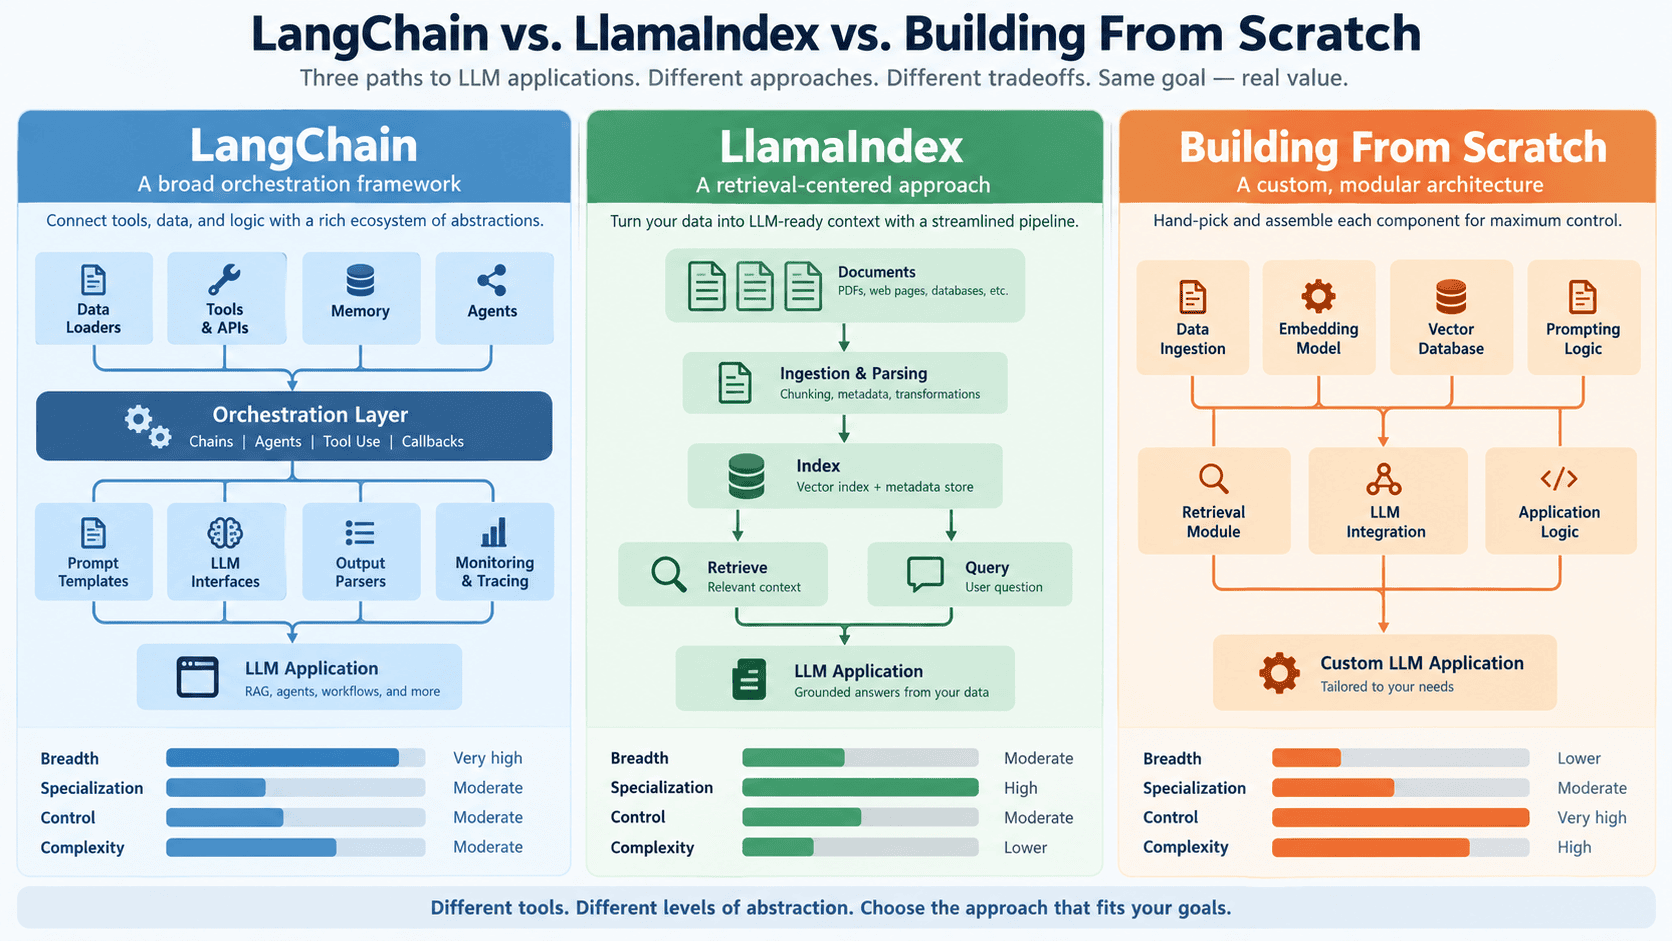
Choosing the right framework for your large language model application comes down to one question: what are you actually optimizing for?
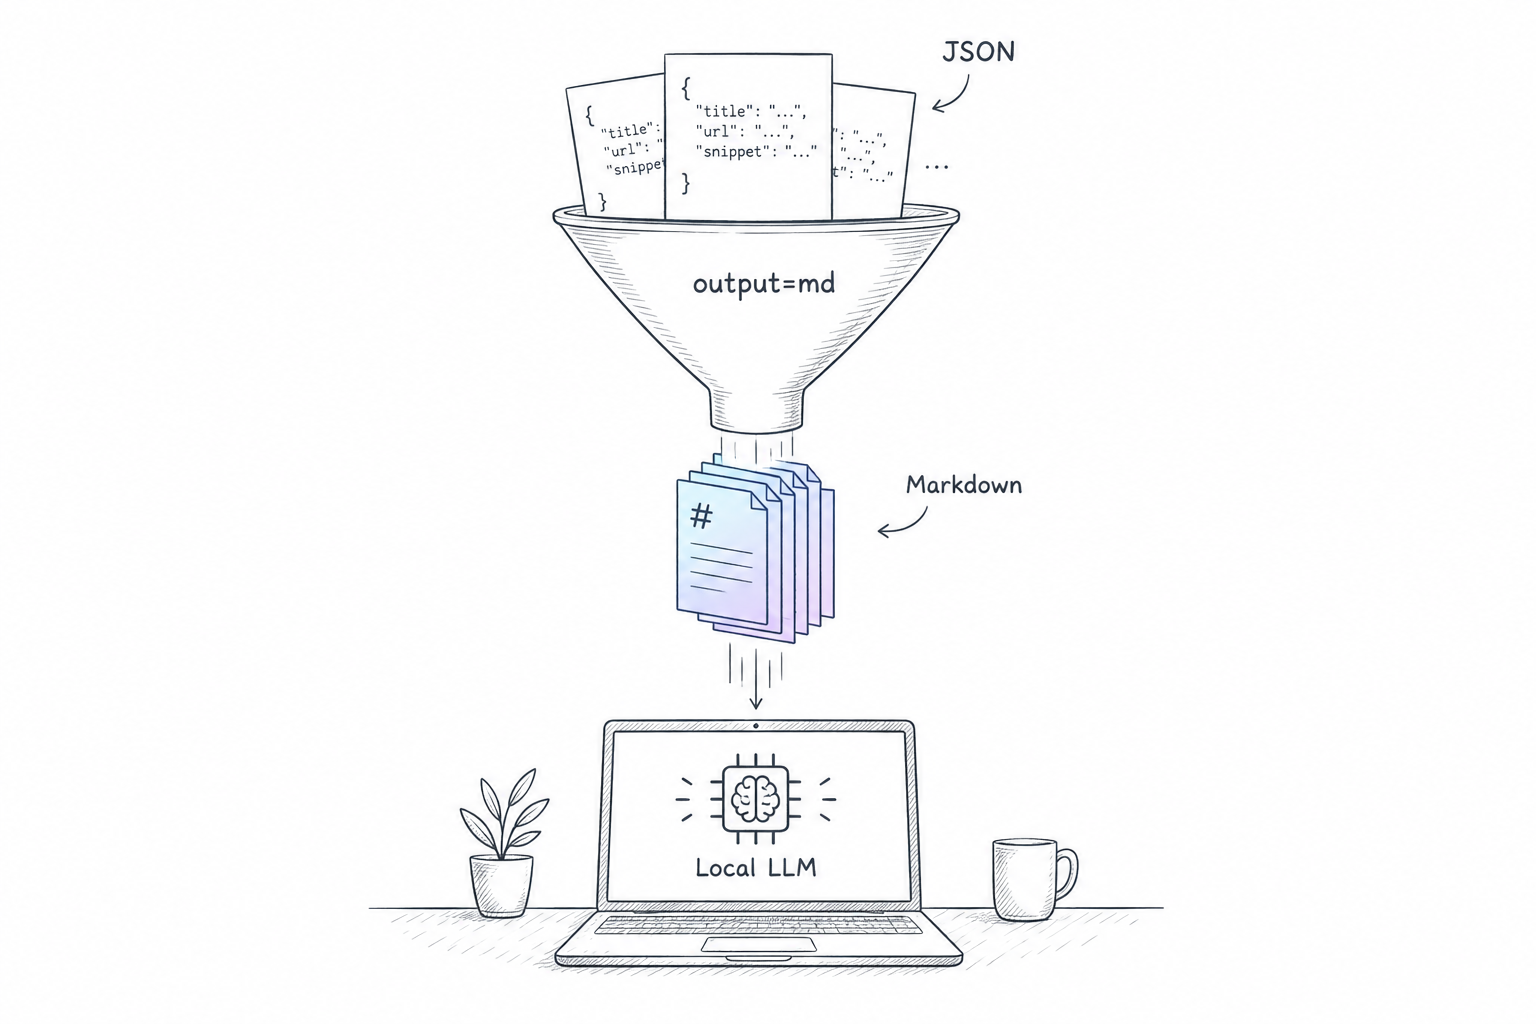
Use SerpApi's Markdown output and the JSON Restrictor to give a local LLM more web search data in the same context window, tested on four models in LM Studio.
Даже идеальная модель с бесконечным объемом текста не восстановит ту часть смысла, которая никогда не была закодирована в языковой форме.Представьте фразу в рабочем чате: «он снова...
Liquid AI has released Open d1, two open-weight multimodal models in its d1 decision model family. d1-3B reads text and images. d1-omni-600M reads text with an image, or text with...
Alibaba's Qwen team launched Qwen3.8-Omni-Flash, a native text/image/audio/video model with 1M context, ~26% average gains vs Omni-Plus, open Qwen-Live Harness, and steep API audio...
Ant Group and inclusionAI open-sourced Ling-3.0-flash-VL, a 124B MoE multimodal model with 5.5B active parameters. BF16 and FP8 weights arrived September 9 with a vision feedback l...
NaiveAI released Naive-N0.5-Flash as MIT open weights: a 309B MoE with 15.5B active, hybrid SWA–DSA native 1M context for coding and AI R&D, built on MiMo-V2.5 without full-att...
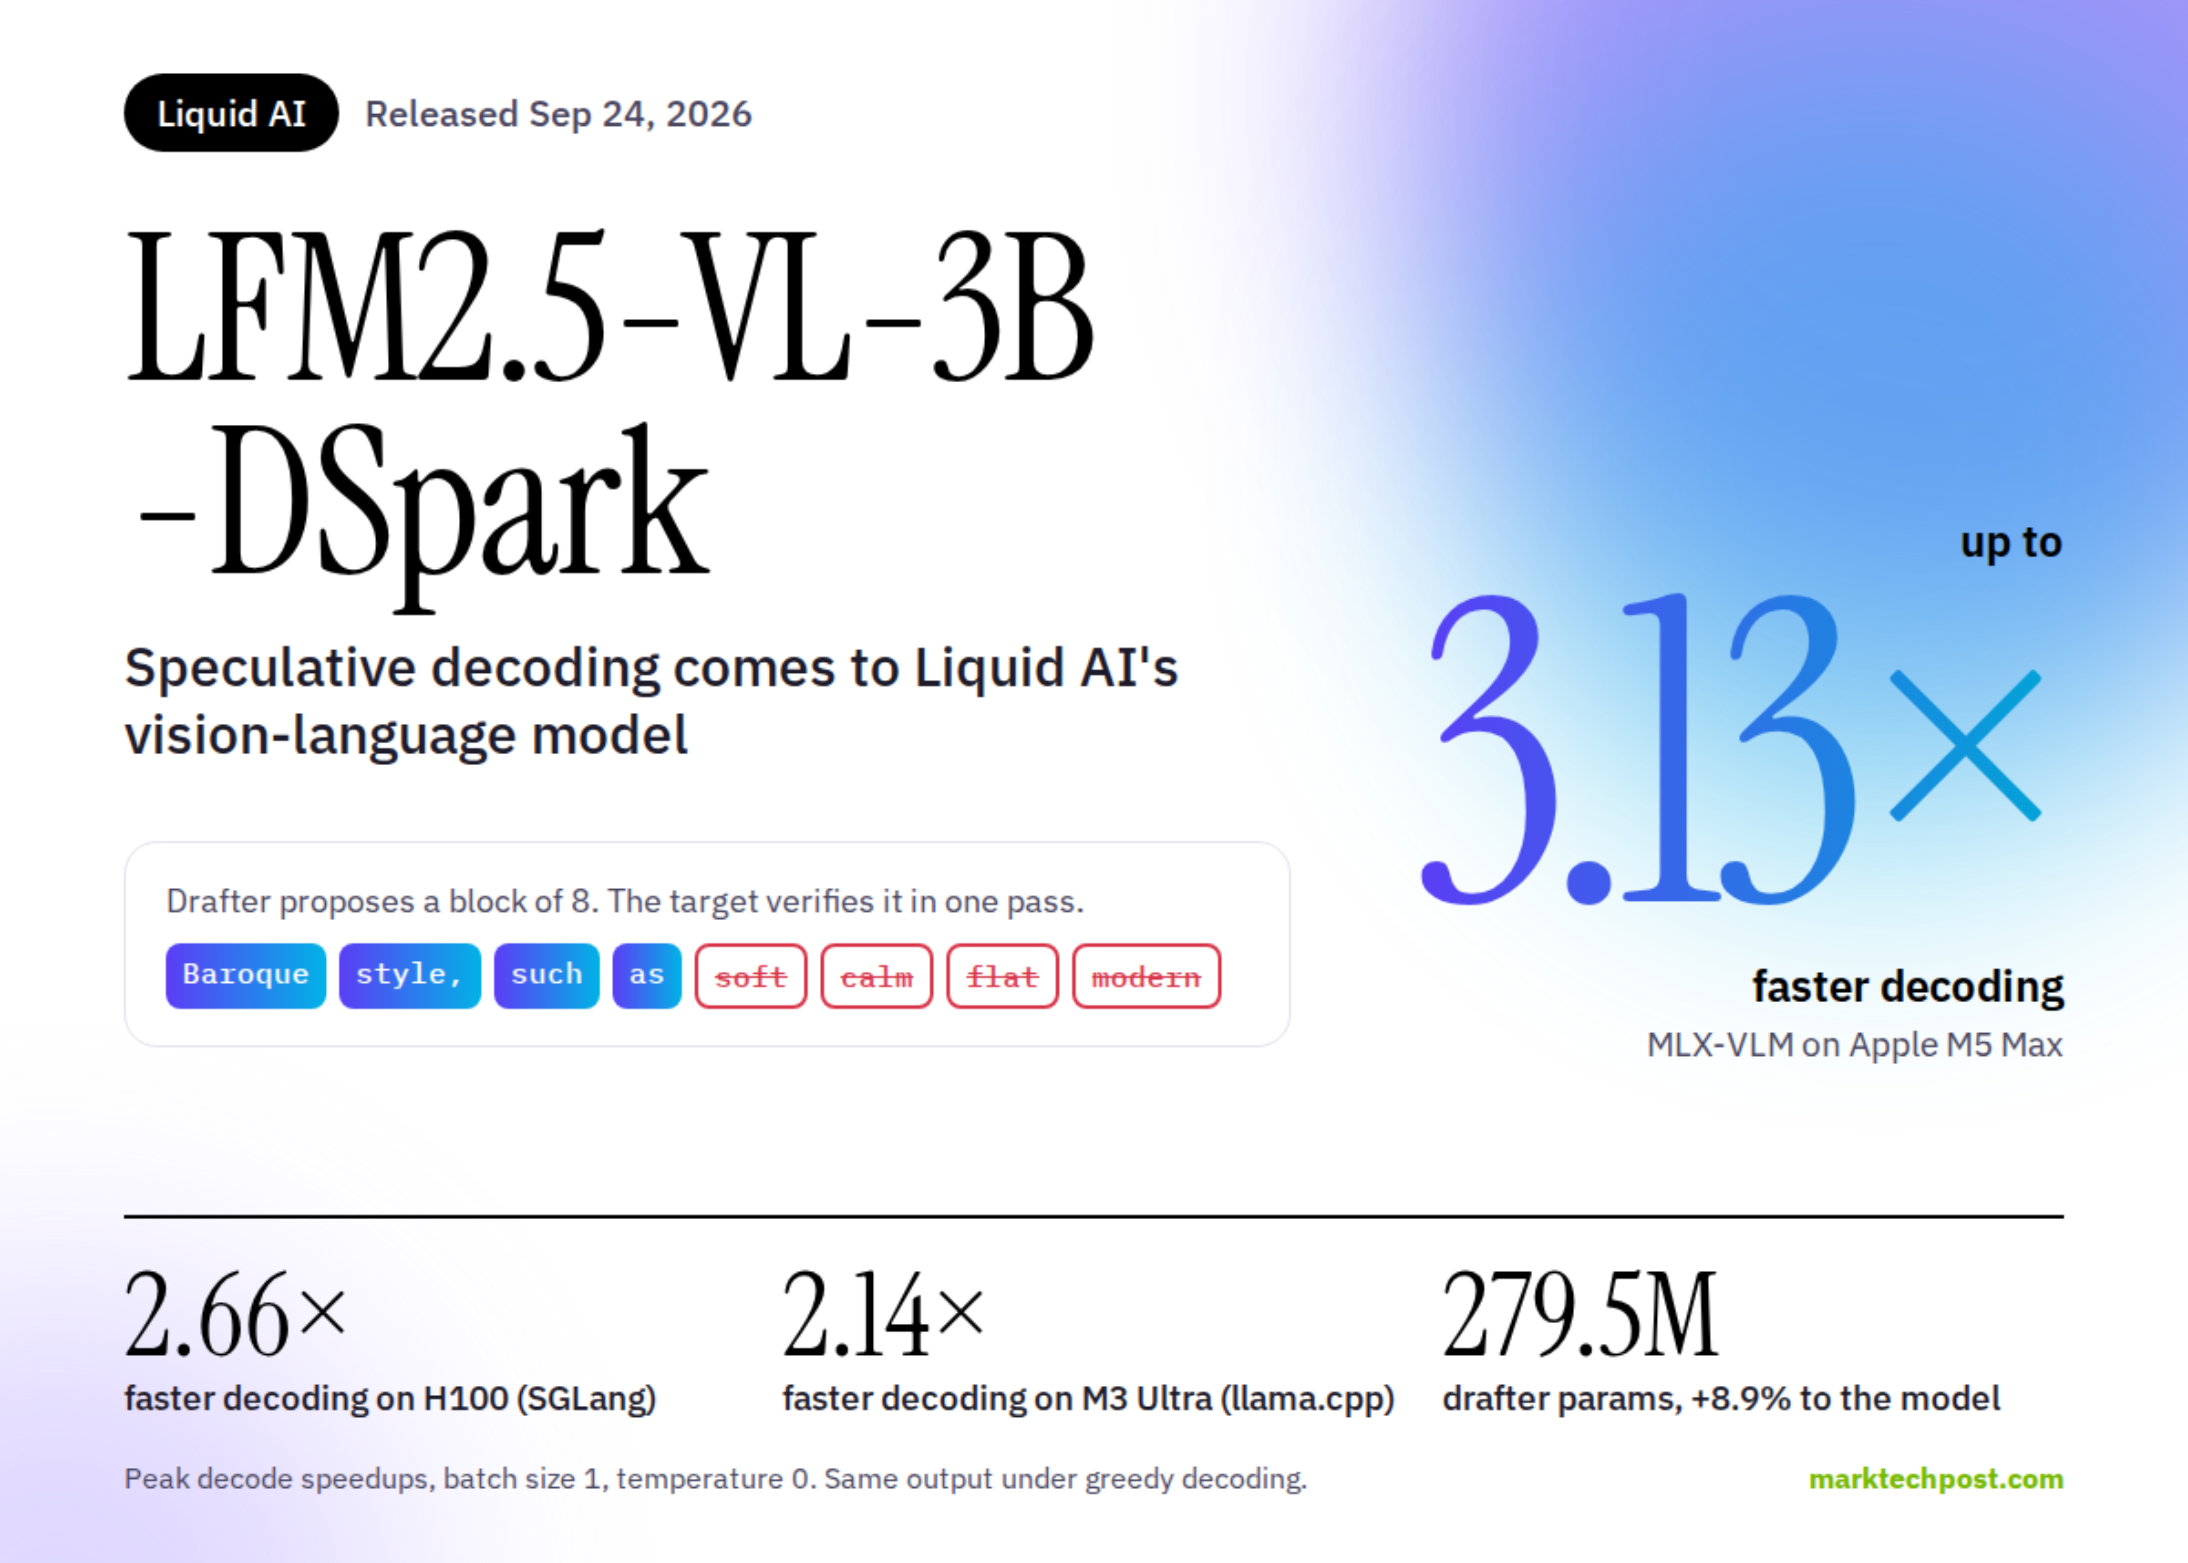
Liquid AI has released LFM2.5-VL-3B-DSpark, a 279.5M-parameter draft model that brings speculative decoding to its LFM2.5-VL-3B vision-language model. It delivers up to 3.13x faste...
Open-source large language models are AI systems you can study, adapt, and use without being locked into one company’s platform or rules. In 2025, they’re giving rese...
One RTX 5090, 128 GB of RAM, and four open models from 125B to 748B parameters. Over the past weeks I got each of them running on the same workstation, on three different runtimes....
Large language models have become easier to integrate into applications, but running them efficiently is still a major engineering challenge. As the number of users and requests in...
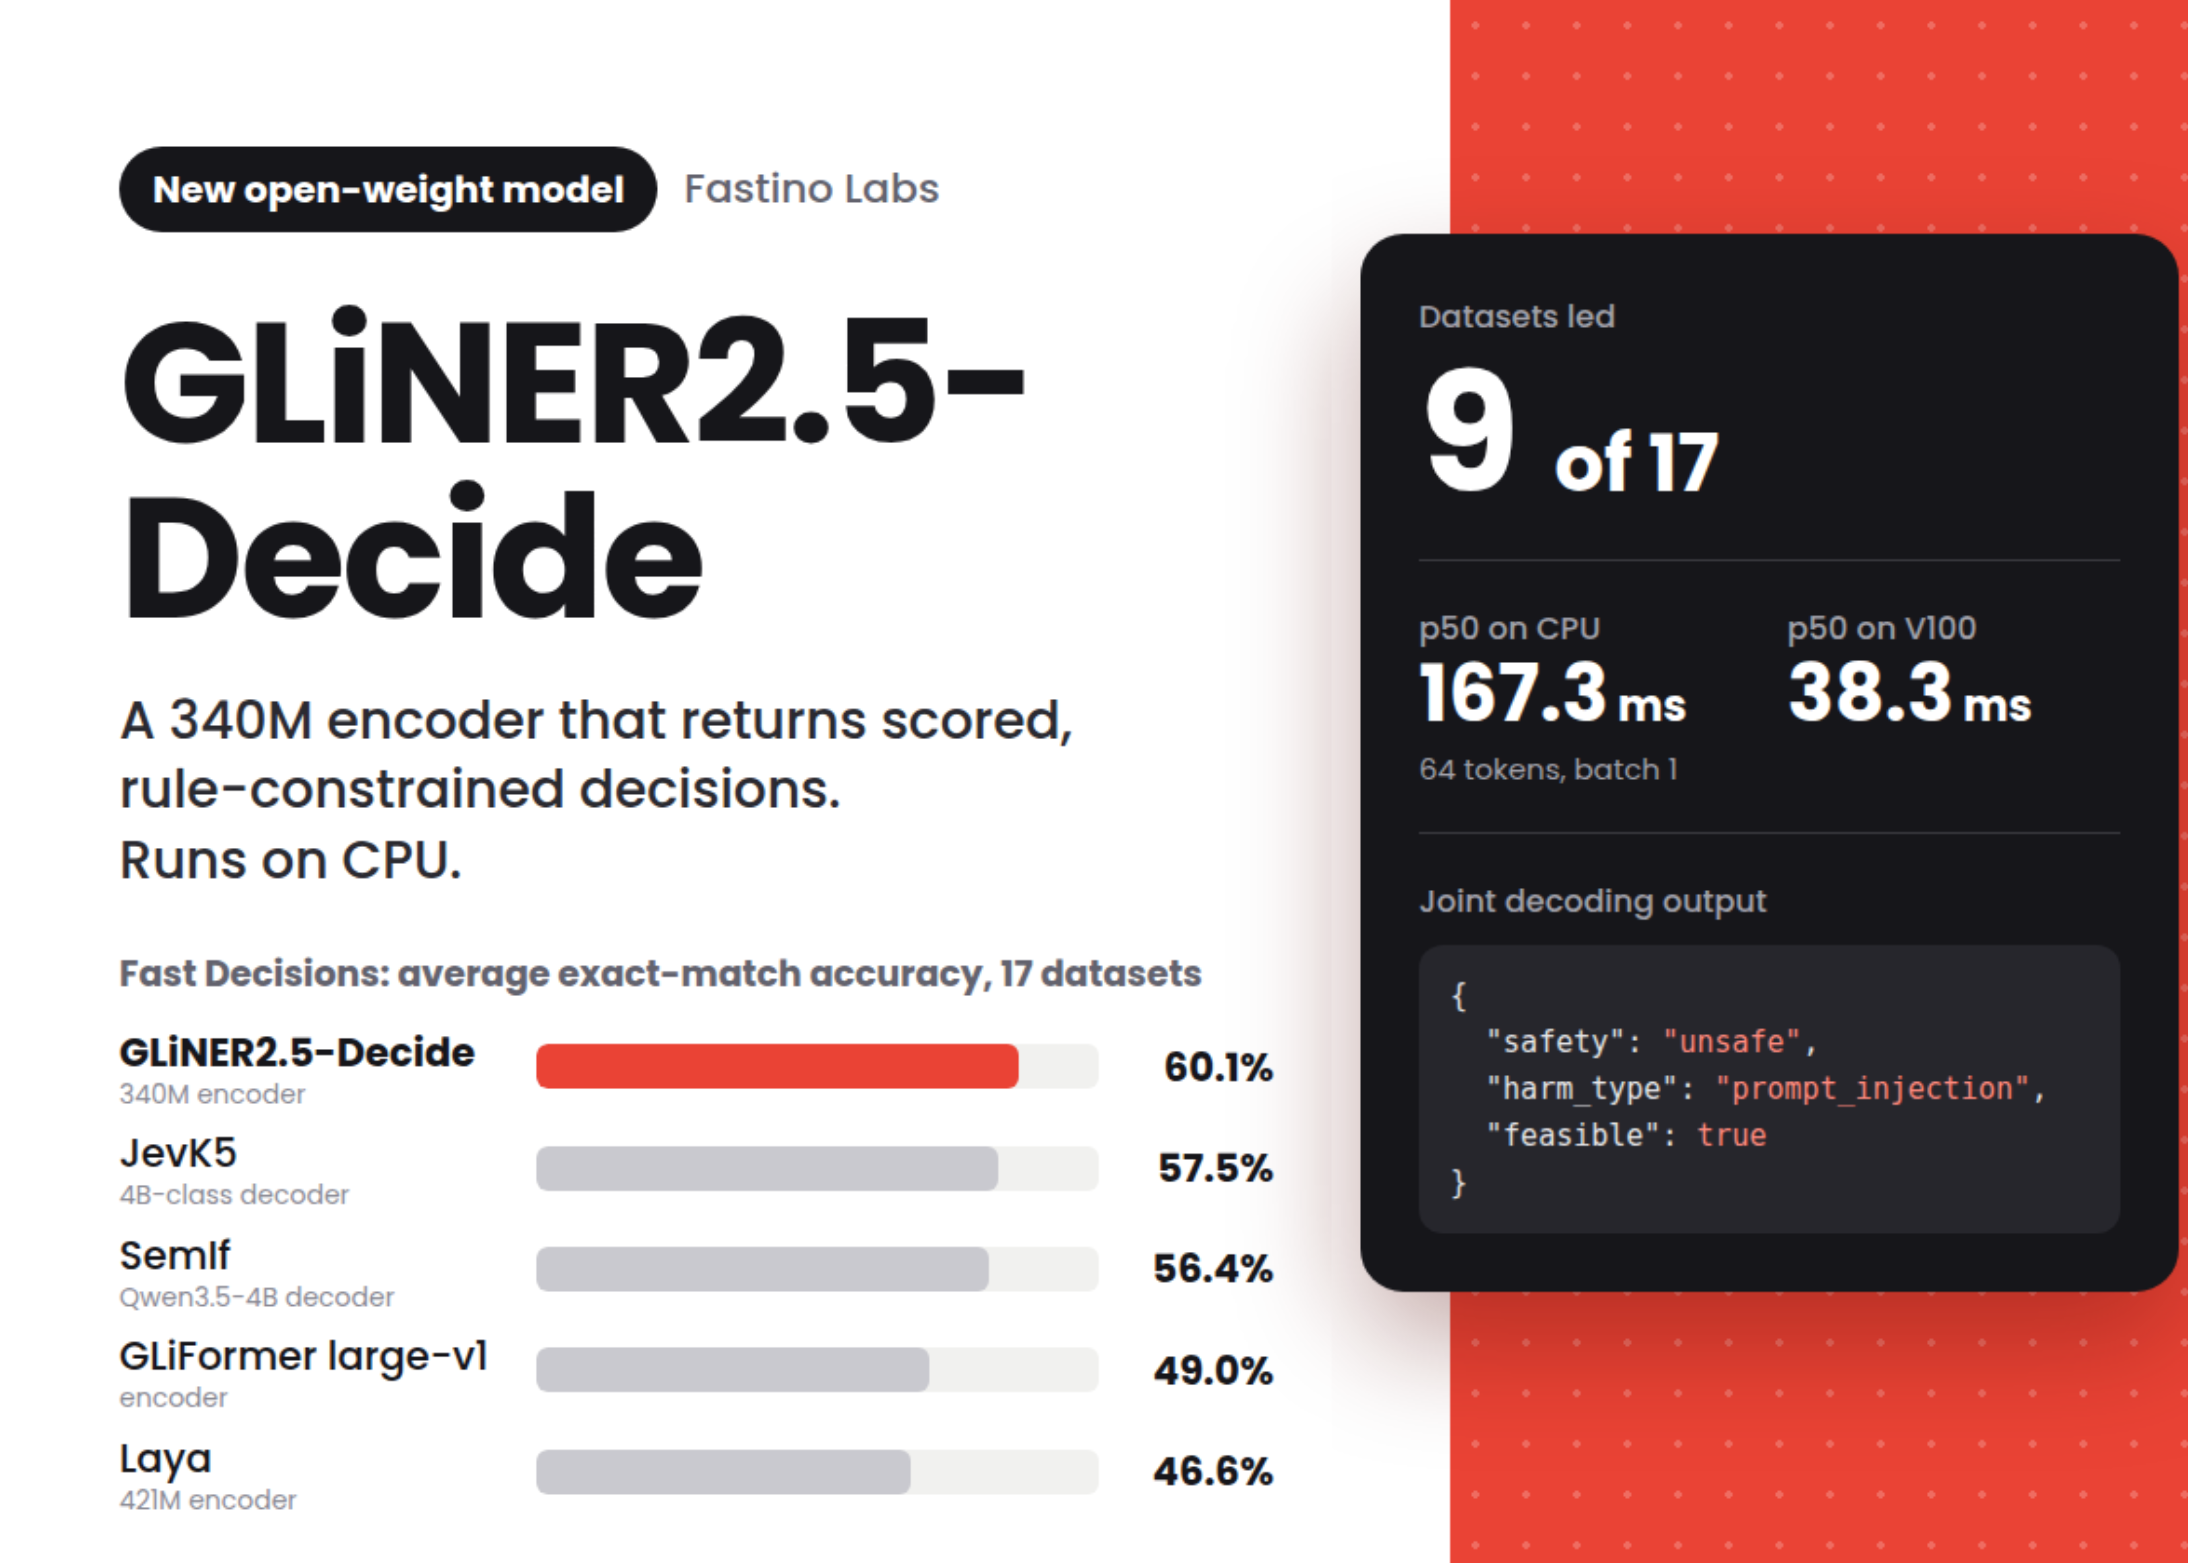
Fastino Labs has released GLiNER2.5-Decide, a 340M-parameter open-weight decision model. It takes text and a schema of typed questions and returns structured answers. Each answer c...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.