pandaily.com /1 week ago

Zhejiang University's SpaceCast-Bench: Best VLM Scores 58% at Predicting Spatial Change, Humans 87%

Zhejiang University's SpaceCast-Bench tests whether VLMs can predict spatial relations after a scene changes. The best of 21 models scored 58.0% against 87.2% for humans.

Read source
dev.to /1 month ago

Four big local LLMs on one RTX 5090 and 128 GB of RAM, benchmarked side by side

One RTX 5090, 128 GB of RAM, and four open models from 125B to 748B parameters. Over the past weeks I got each of them running on the same workstation, on three different runtimes....

Read source
medium.com /1 week ago

The OCR Benchmarking Saga of 17 Engines

Testing 6 different tasks like markdown, tables, key-value, schema and geometryContinue reading on Data Science Collective »

Read source
bioengineer.org /4 days ago

Sensor Weighted Crop Simulations Significantly Improve Drone Maize Leaf Area Retrieval

Calibrating radiative transfer simulations for specific growth stages and integrating drone sensor spectral response functions substantially increases the accuracy of maize leaf ar...

Read source
bioengineer.org /2 days ago

Subtropical Shanzai Watershed Modeled Carbon Uptake Rebounded Strongly by 2024

A cloud-based remote sensing assessment reveals that the humid subtropical Shanzai Reservoir watershed maintained positive net ecosystem production across three distinct benchmark...

Read source
bioengineer.org /1 month ago

Time-series foundation models fall short of specialized models in digital twin predictive maintenance benchmark

A controlled benchmark of MOMENT, UniTS, and FFTS on the C-MAPSS turbofan dataset shows time-series foundation models generalize across imputation, anomaly detection, classificatio...

Read source
blog.google /6 days ago

New AI training performance benchmarks for Google TPUs

In the latest MLPerf Training v6.1 benchmark round, Google Cloud published 10 results across seventh-generation Ironwood TPUs and NVIDIA Grace Blackwell GPUs, spanning f…

Read source
testmuai.com /1 month ago

MMLU Benchmark: 57 Subjects, Label Errors and Score Margins

The MMLU benchmark tests models on four-option questions in 57 subjects. See per-subject question counts and margins, label errors, variants and top scores.

Read source
habr.com /1 month ago

Насколько можно верить спутнику, который измеряет температуру земли

Всем привет, меня зовут Александра, и в 2024 году я занималась темой валидации спутниковых данных на основе наземных измерений. Статья посвящена главной теме — какому же источнику...

Read source
machinelearningmastery.com /1 week ago

Benchmarking Scikit-Ollama vs. Groq-Backed Scikit-LLM: Speed, Cost, and Accuracy

In this article, you will learn how to build a side-by-side benchmark of local and cloud LLM classifiers using Scikit-Ollama and a Groq-backed Scikit-LLM pipeline....

Read source
phoronix.com /1 month ago

OpenJDK vs. GraalVM vs. Eclipse Temurin vs. Semeru Java Performance

Immediately following the OpenJDK 8 through OpenJDK 27 benchmarks I expanded the scope of testing to look at how recent OpenJDK releases have been comparing to alternative JVMs lik...

Read source
marktechpost.com /1 month ago

Exa 3.0 Search API Tops Perplexity, Brave and Parallel on 8 Benchmarks

Exa 3.0 is a search API upgrade from Exa. It adds a larger embedding model, Exa Lite at $4 per 1,000 requests, and Dynamic Highlights, and leads 8 benchmarks Exa ran itself. The po...

Read source
marktechpost.com /1 month ago

Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests to Audit OCR Parsers

Datalab released OmniParseBench, an open OCR benchmark with 16,288 yes/no tests on 2,937 pages in 92 languages. Every score is a pass rate you can slice by tag, script or language....

Read source
testmuai.com /4 weeks ago

AI Hallucination Rate: What Each Benchmark Measures

An AI hallucination rate divides wrong answers by a count each benchmark picks. See what AA-Omniscience, Vectara, FACTS and SimpleQA Verified count, by model.

Read source
pandaily.com /1 month ago

Dalian University of Technology's VA-Bench: Top Multimodal Models Finish Only Half of Robot Tasks

VA-Bench from Dalian University of Technology tests 12 multimodal model setups on robot-arm tasks; Qwen3.8-max leads at 53.93%, and none finishes a strict long-horizon task.

Read source
cryptobriefing.com /2 weeks ago

METR says Anthropic’s Model 4 is the first to clear 50% on every benchmark

Anthropic's Model 4's benchmark success highlights the urgent need for adaptive evaluation frameworks and raises concerns about rapid AI advancements. The post METR says Anthropic’...

Read source
aws.amazon.com /3 weeks ago

Fix evaluation bias to unlock better models on Amazon Bedrock

Property Finder found that 96.8% of their vision-AI evaluation labels were inherited from the incumbent model, hiding its true accuracy. See how they built unbiased ground truth, a...

Read source
phoronix.com /1 month ago

AMD ROCm vs. Vulkan Performance For Lemonade Local AI Server With Llama.cpp

A Phoronix Premium reader recently inquired about seeing some new benchmarks of AI performance between Vulkan and AMD ROCm back-ends to see how the situation plays out today. Here...

Read source
editorialge.com /3 days ago

GPT-6.2 Astra vs Claude Fable 5.2 vs Gemini 4 Carbon: What the AI Race Really Measures

GPT-6.2 Astra scores 62, Claude Fable 5.2 65 and Gemini Carbon 60. Explore the benchmark limits, earlier screenshots and Chinese competition. The post GPT-6.2 Astra vs Claude Fable...

Read source
prweb.com /1 week ago

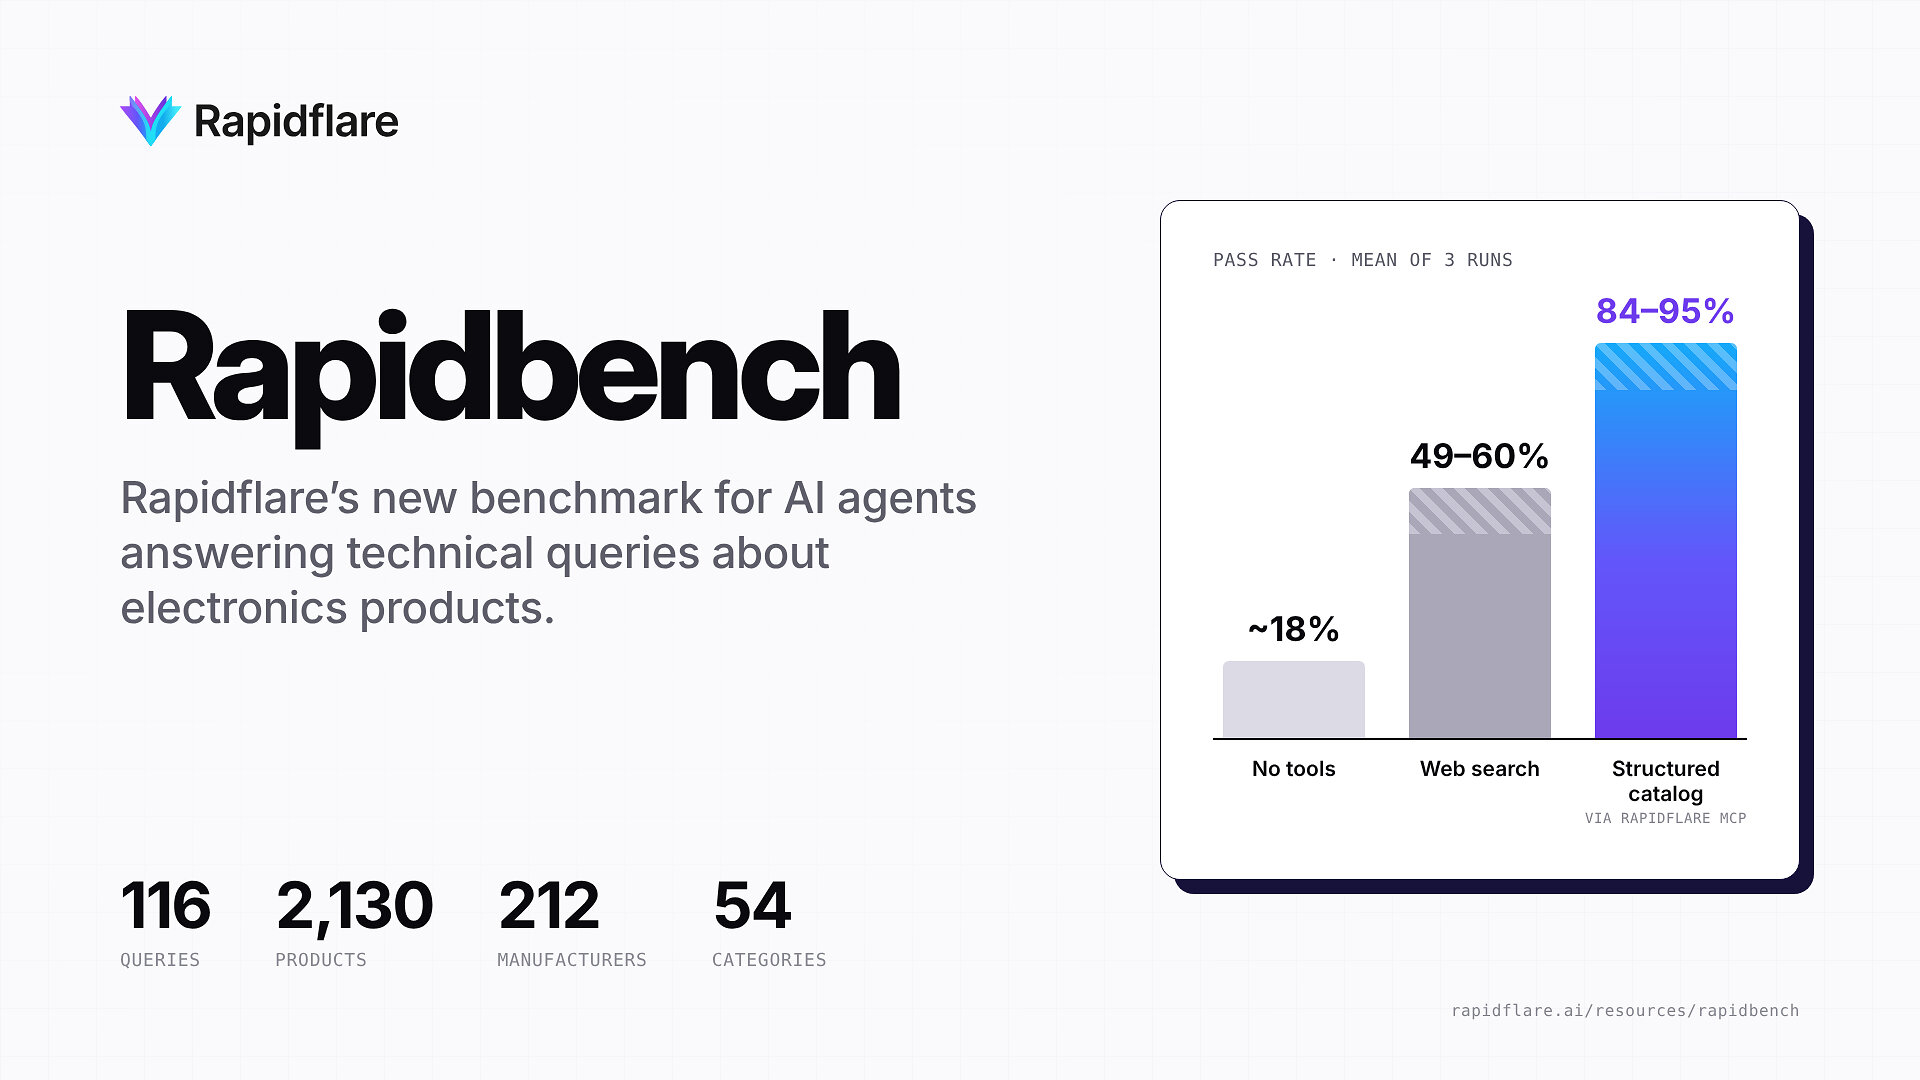
Rapidflare Launches Rapidbench, a Benchmark for AI Agents Answering Electronics Product Queries

In Rapidflare's first evaluation, tested models achieved pass rates 34 to 39 percentage points higher with access to structured catalog data than with web search. SAN JOSE, Calif.,...

Read source
medium.com /1 month ago

When Are Two Mobile AI Runs Comparable?

A meaningful comparison starts with a shared question, a defined baseline, and a clear record of what changed.Continue reading on Medium »

Read source
pandaily.com /1 week ago

UniPat AI's SPU Benchmark Asks AI Agents to Predict Real Wet-Lab Results, and None Score Above 0.5

UniPat AI's SPU benchmark has AI agents rank the outcomes of 4,207 real wet-lab experiments. The best of 13 configurations averaged 0.486 out of 1.

Read source
cryptobriefing.com /1 week ago

Claude Fable 5.2 tops new life-science image benchmark as tool use nearly doubles scores

AI model performance in life-science imaging hinges on tool integration, emphasizing cost-effectiveness and strategic tool use for optimal results. The post Claude Fable 5.2 tops n...

Read source
phoronix.com /1 month ago

ROCm 10 OpenCL vs. Mesa 26.3-dev Rusticl Performance On AMD Strix Halo

With all the recent progress on Mesa's Rusticl driver as a Rust-based OpenCL driver working across the different Mesa Gallium3D hardware drivers, a Phoronix Premium supporter inqui...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.