How to Check Local LLM Output with Ollama, Gemma 4, and Nimble
Gemma 4 E2B drafts the replies, Bespoke Labs' Nimble 9B picks accept, revise, or human review, and only flagged questions get a focused retry. The post How to Check Local LLM Outpu...
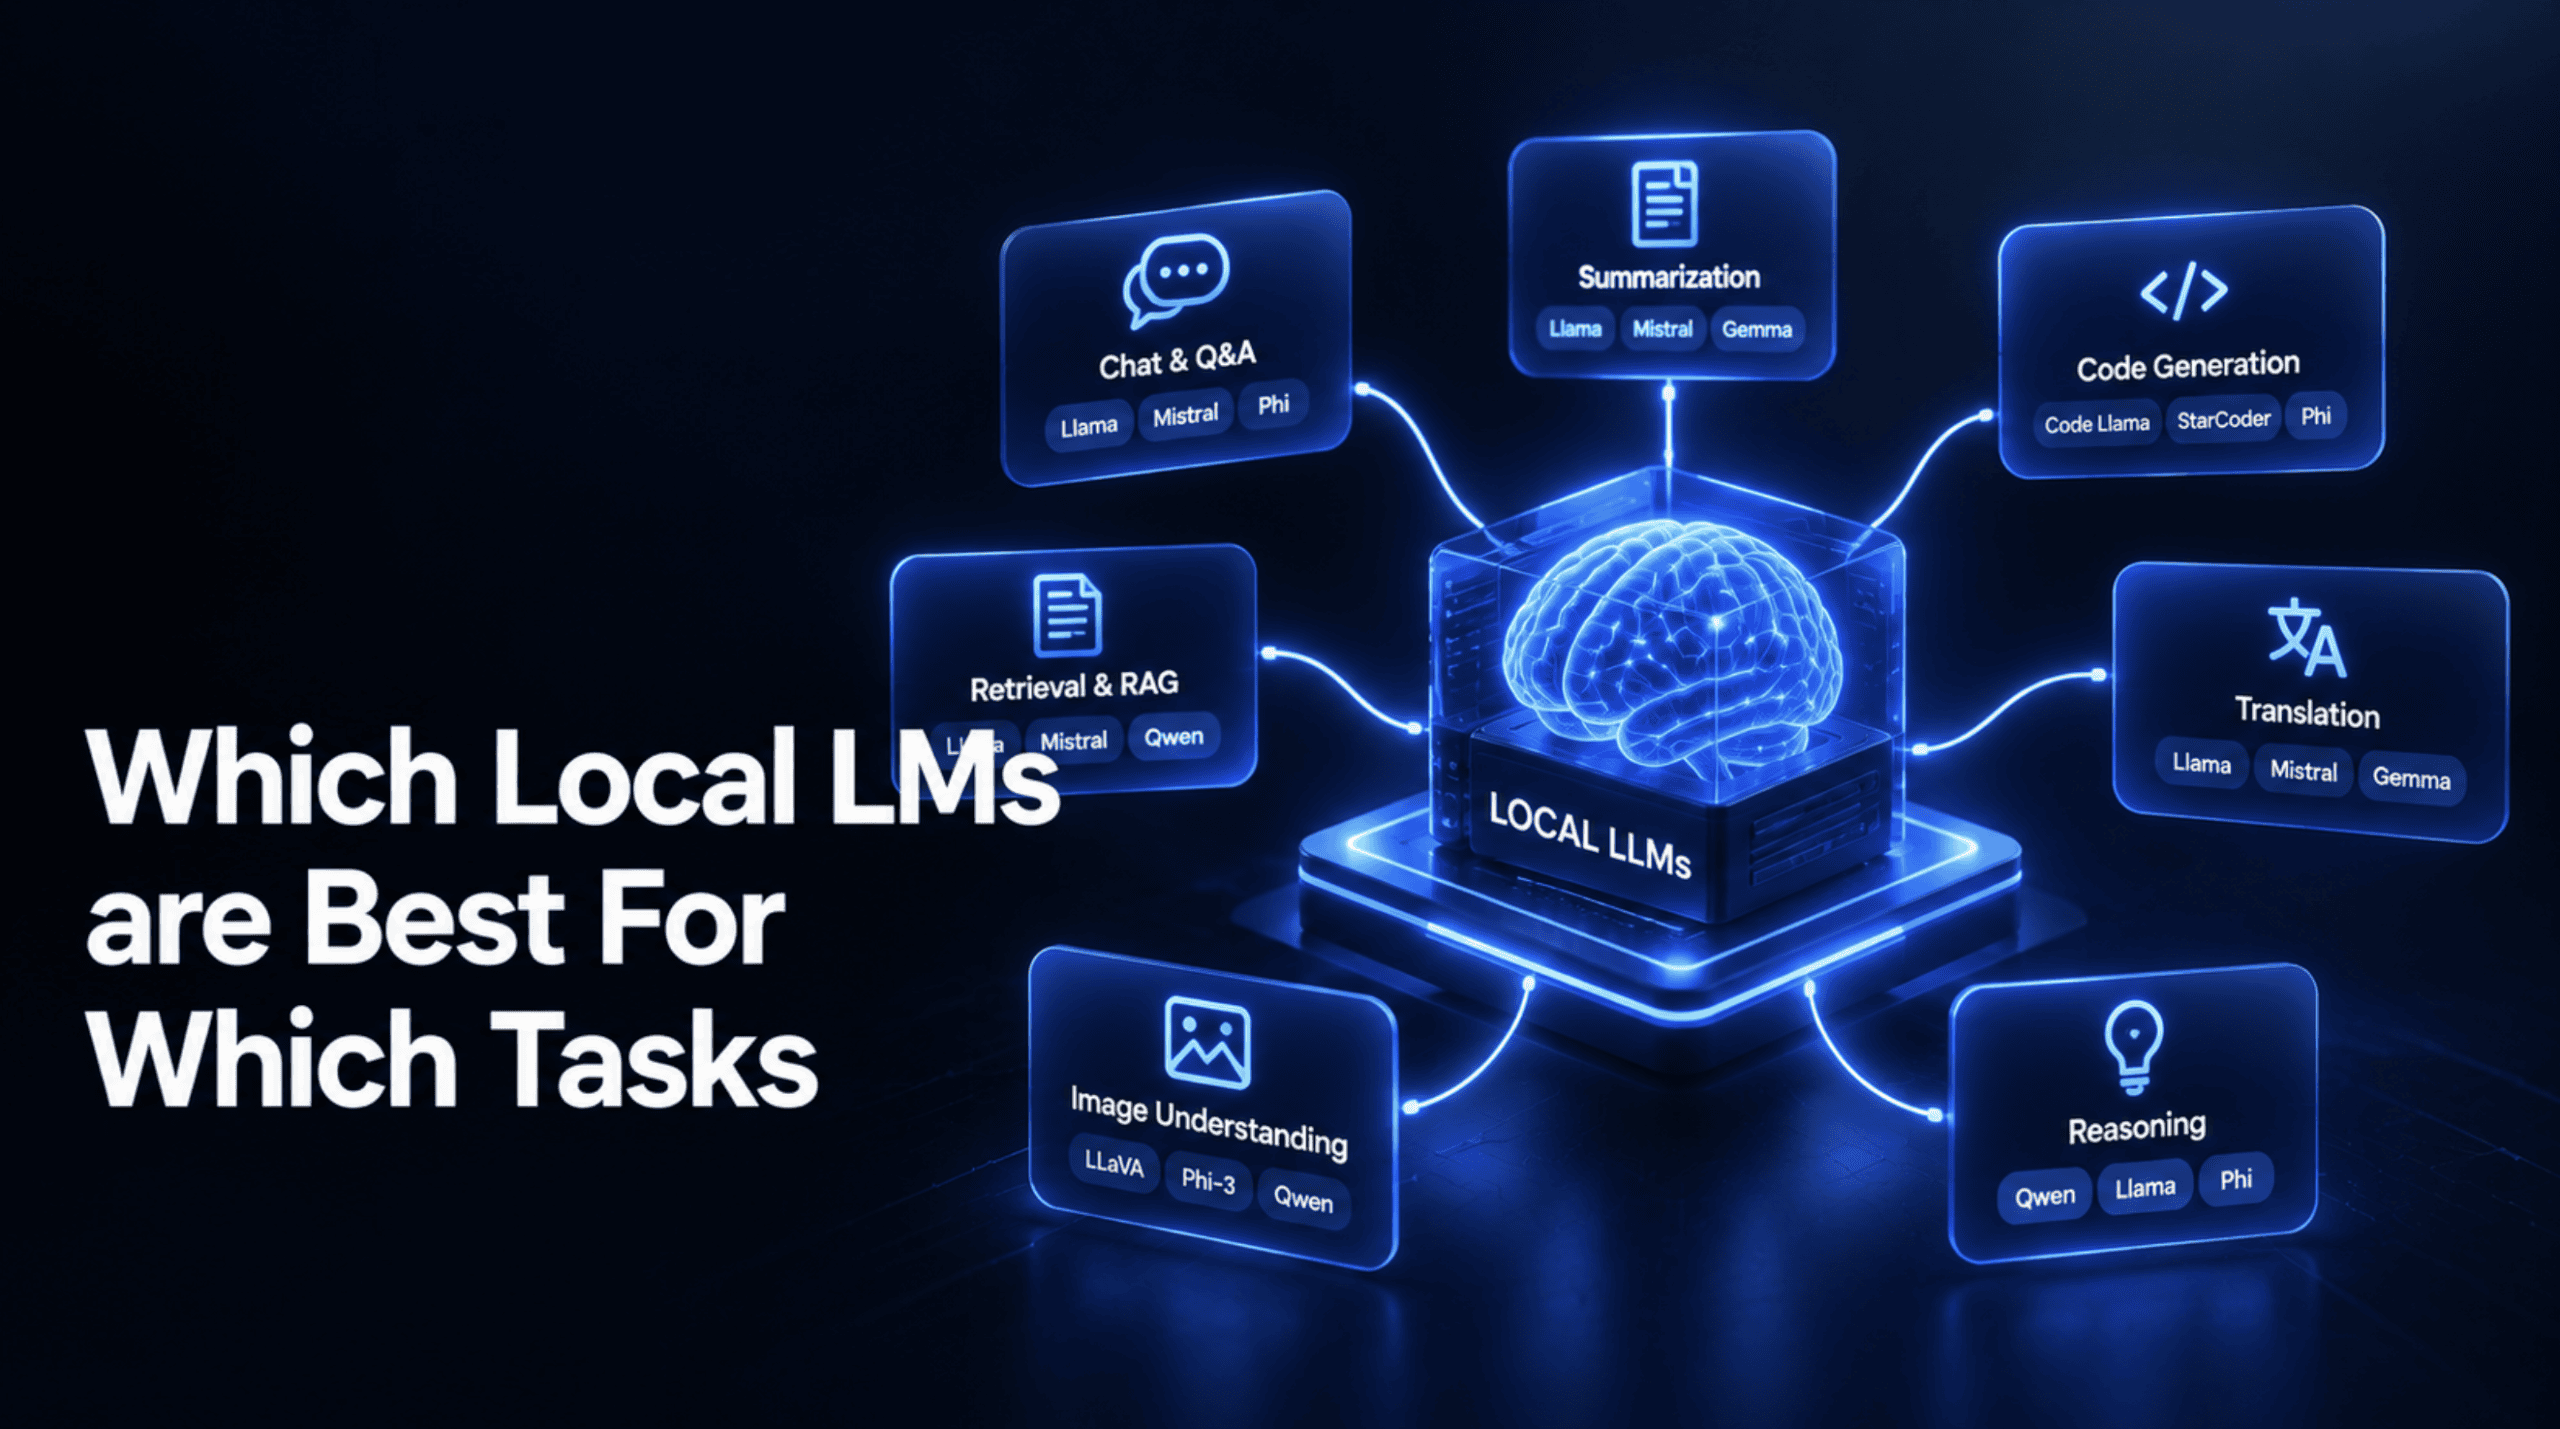
A local language model is one whose actual weights, the enormous file of learned numbers that constitutes the trained model, you download and run entirely on your own hardware.
Choose Ollama for simpler local development and model management, and vLLM for high-throughput inference when your app needs to handle [...] Read More... The post vLLM vs. Ollama:...
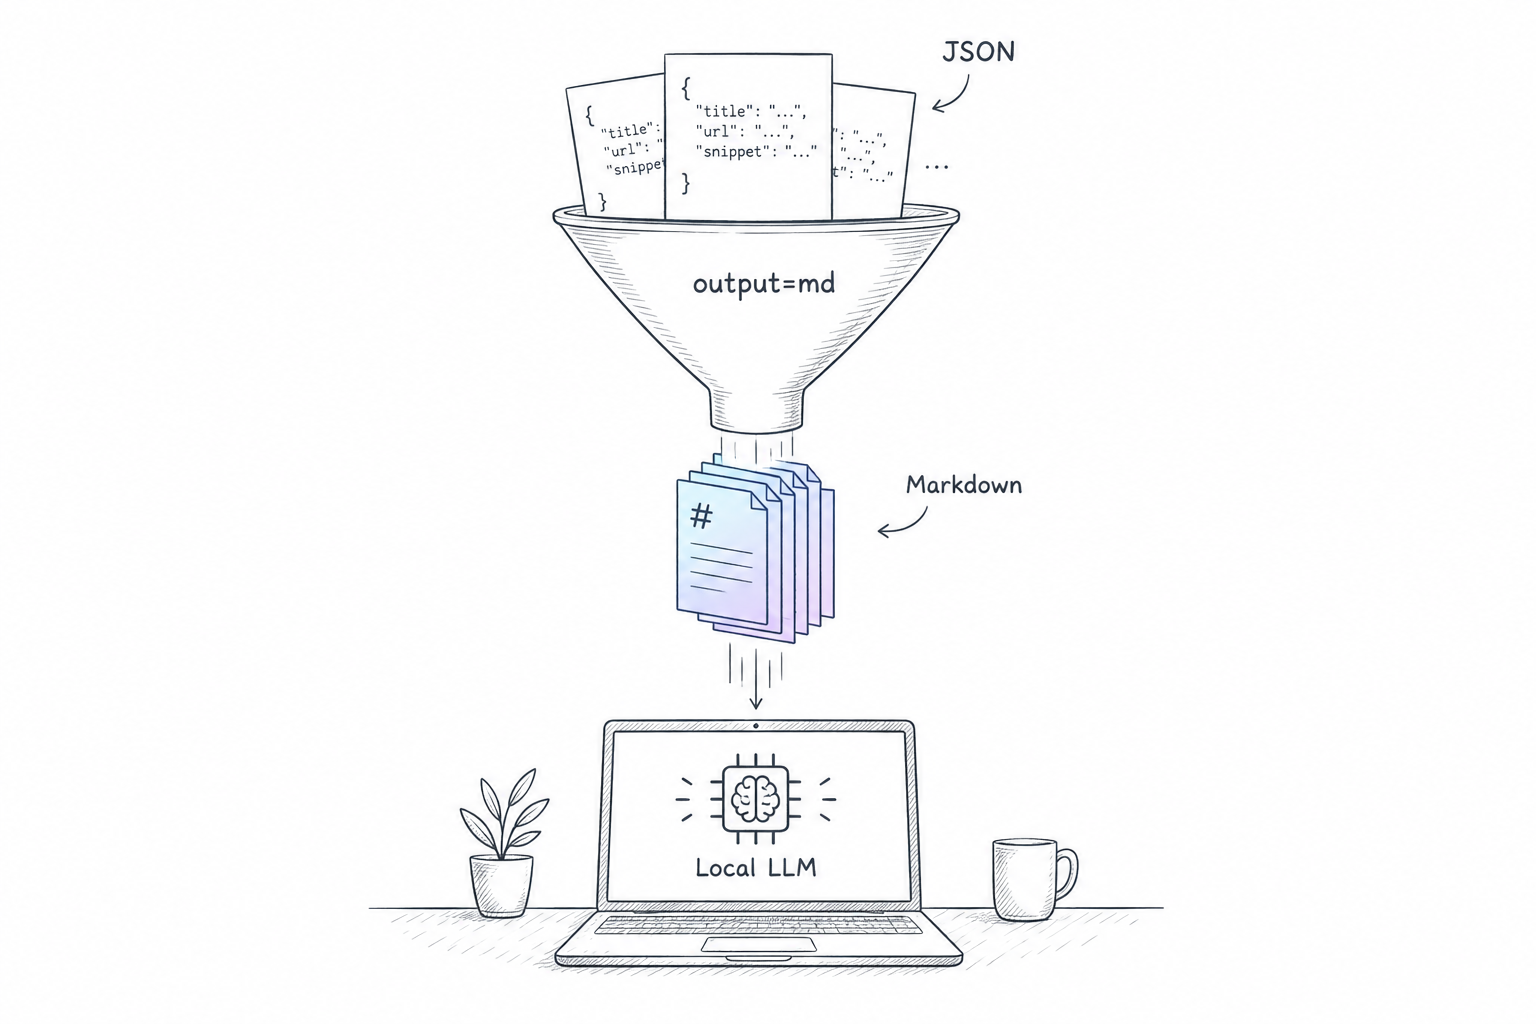
Use SerpApi's Markdown output and the JSON Restrictor to give a local LLM more web search data in the same context window, tested on four models in LM Studio.
llm_cost_tracker is self-hosted LLM cost tracking for Rails: every call through RubyLLM, the OpenAI and Anthropic SDKs, Gemini, or any OpenAI-compatible API is logged with tokens,...
LLM testing checks that an LLM app gives correct, grounded, safe answers after every change. Learn the test types, metrics, a CI regression gate and tools.
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.