dzone.com /1 month ago

Beyond Batch: Engineering Enterprise Systems for Real-Time Decisioning

The Batch Processing Problem Batch processing isn't inherently a disadvantage. It becomes a problem when the business needs a decision now, but the architecture was designed to mak...
Read source
dzone.com /1 month ago

Jakarta Batch in Practice: Reliable Chunk-Oriented Processing for Enterprise Workloads

Batch processing remains vital because many business operations aren't suited to interactive requests. Tasks such as recalculating prices, reconciling transactions, migrating recor...

Read source
dzone.com /1 month ago

Going All In On the JVM 25 Virtual Threads

The project AngularAndSpring has been refactored from Spring Reactor to Spring blocking APIs using JDK 25 and virtual threads. The Old Architecture The reason AngularAndSpring was...

Read source
sourcetrail.com /3 weeks ago

Mastering Memory Management with Arena.ofConfined and the FFM API

Unlock high-performance Java with Arena.ofConfined. Learn how to manage off-heap memory safely and boost your app's speed with the FFM API. The post Mastering Memory Management wit...

Read source
blogs.vmware.com /2 weeks ago

Optimizing Columnar Storage in Tanzu Greenplum, Part 1: Accelerating Filters with Implied Indexing

<div><img width="300" height="157" src="https://blogs.vmware.com/wp-content/uploads/2026/07/vmw-blogtile-tanzu-greenplum-v2-1.png" class=&quo...

Read source
databricks.com /1 month ago

Load terabytes of data in minutes into Lakebase Postgres

Operational databases like Postgres are built to reliably execute highly concurrent...

Read source
dzone.com /1 week ago

From Database Changes to Real-Time Actions at Scale: Oracle GoldenGate and Java

DB changes can be streamed in real time via Oracle GoldenGate. Java applications can then consume them to validate/act on/route events without polling the DB. Goal Listen to real-t...

Read source
javacodegeeks.com /1 month ago

LLM Streaming with Embabel

Large Language Models can take several seconds, or sometimes much longer, to produce a complete response. In a traditional blocking application, the caller waits until the entire r...

Read source
dev.to /1 month ago

Filtering a 2 GB CSV in the browser without uploading it: streams, a Web Worker and a 64-bit hash set

Excel stops at 1,048,576 rows. Most online CSV tools want you to upload the file first, which is a non-starter for a customer list or an accounting export. I wanted something in be...

Read source
dev.to /3 weeks ago

Agent Memory Just Became Infrastructure

Every vendor shipped "agent memory" this month. Not one of them shipped "bigger context window." That difference is the whole story of where agents are going. Last week, Databric...

Read source
databricks.com /1 month ago

MemCurrent: Designing Persistent Memory for Production Agents

AI tools have made it easy to vibe code agents. Building and maintaining an enterprise...

Read source
dev.to /1 month ago

Stream 50 million rows without OOM: Lazy chunked Query Streaming.

Stream 50 million rows without OOM: Lazy chunked Query Streaming. Day 09 of the WClickHouse Open-Source Engineering Series. You don't need 64GB of RAM to process millions of C...

Read source
habr.com /1 week ago

Параллельная обработка данных в режиме конкурирующих потребителей (competing consumers)

Сразу отмечу что это всего лишь один частный случай распараллеливания обработки больших объемов данных.Схема: Читать далее

Read source
blogs.cisco.com /2 weeks ago

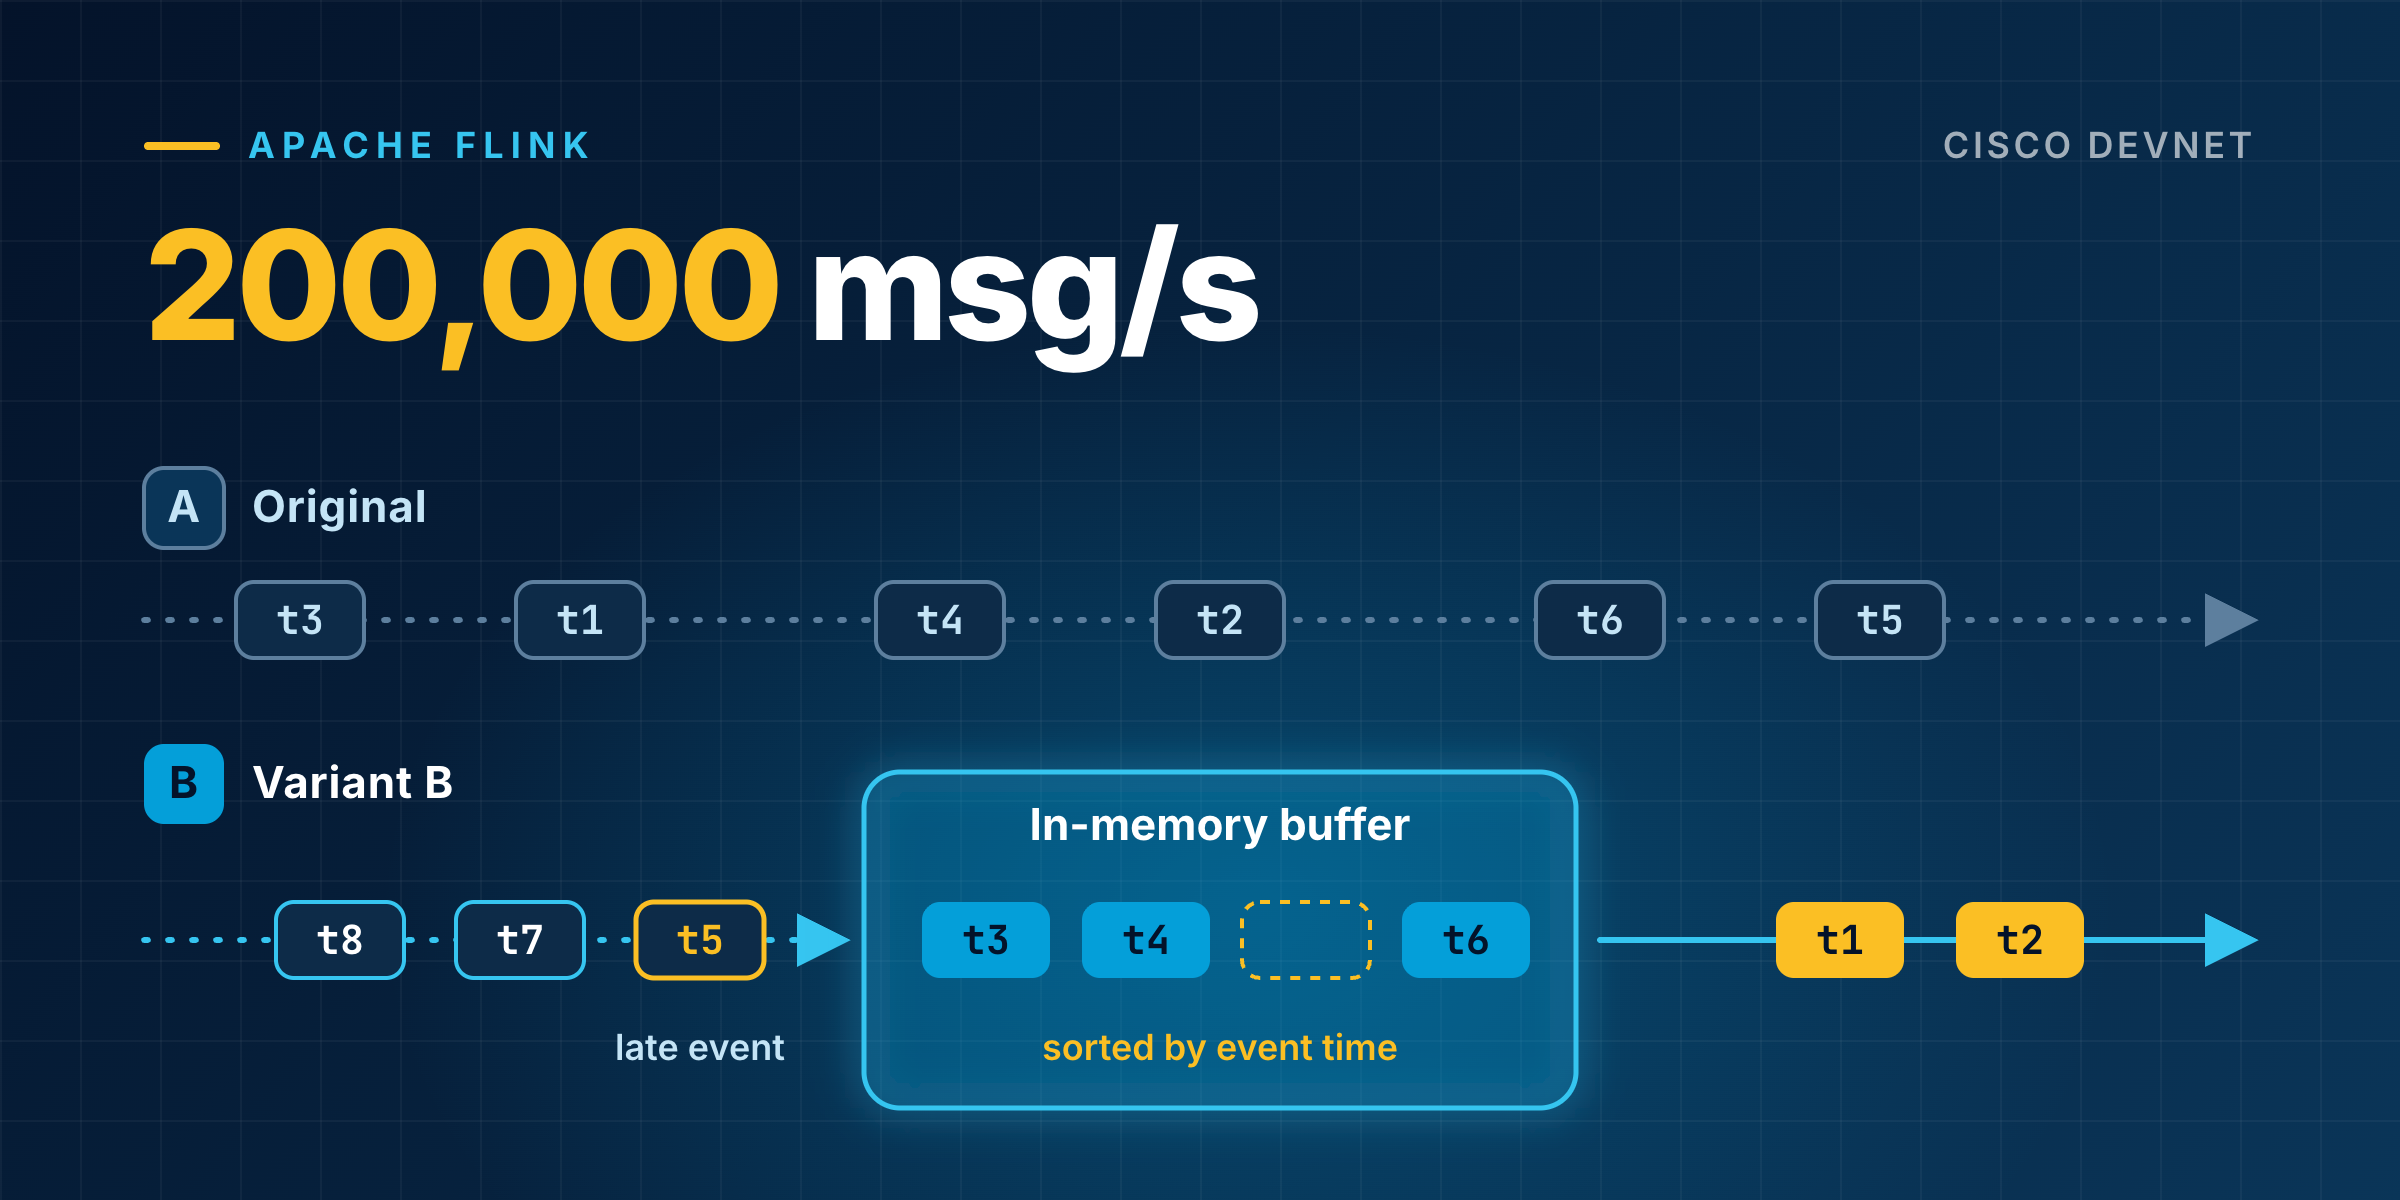
Mastering stateful stream reordering at 200,000 messages per second

Our Flink job hit a wall at 200,000 messages per second because of RocksDB. Here is the in-memory reordering pattern that fixed it, and how A/B development proved it safe.

Read source
dev.to /1 month ago

Feeding the OLAP beast: ClickHouse massive bulk ingestion steps.

Feeding the OLAP beast: ClickHouse massive bulk ingestion steps. ClickHouse is a columnar beast, but treating it like MySQL by inserting row-by-row will bring your cluster to its...

Read source
rubyflow.com /1 month ago

SolidJobs + SolidTrace + Warm IPC perform worker 2000 alloc/s vs 200 alloc/s sidekiq

We are told that to scale Ruby background workloads across multiple CPU cores, we have two choices: process forking (e.g., Pitchfork) which incurs massive Copy-on-Write memory over...

Read source
javacodegeeks.com /3 weeks ago

The Disruptor and Mechanical Sympathy: Ring Buffers Against Queues

Most Java developers reach for a queue whenever two threads need to talk. It feels natural, and it usually works well. However, at the extreme end of performance, that habit can qu...

Read source
dev.to /1 month ago

Procesa 50 millones de filas sin OOM: Query Streaming por bloques.

Procesa 50 millones de filas sin OOM: Query Streaming por bloques. Día 09 de la serie técnica WClickHouse Open Source. No necesitas 64GB de RAM para procesar millones de regis...

Read source
medium.com /1 month ago

Why Flat JSON Agent Memory Fails: Building a Copy-on-Write Multi-Agent Memory Mesh on FalkorDB

Replacing flat context bloat with sub-millisecond linear algebra graphs, air-gapped sandboxes, and deterministic Graph-PACC compaction (<…Continue reading on Medium »

Read source
dzone.com /1 month ago

OpenSearch Heap Sizing: Swap, Page Cache, and the 50% Rule

OpenSearch is an open-source, distributed search and analytics suite derived as a fork of Elasticsearch and maintained under the Apache 2.0 license. When it comes to memory configu...

Read source
salesforce.com /4 weeks ago

Optimize Data 360 Ingestion for Cost Efficiency

Explore ingestion strategies to optimize credit consumption while maintaining business value.

Read source
kdnuggets.com /5 days ago

Comment on New Computing Paradigm for AI: Processing-in-Memory (PIM) Architecture by synthetic cocaine

<strong>... [Trackback]</strong> [...] Information on that Topic: kdnuggets.com/2021/10/samsung-computing-paradigm-ai-in-memory.html [...]

Read source
aws.amazon.com /1 month ago

Push-based KV transfer to improve TTFT and TPOT for disaggregated inference in vLLM

vLLM's prefill-decode disaggregation splits LLM inference across engine instances but must transfer the KV cache between them. This post introduces a push-based NIXL connector that...

Read source
javacodegeeks.com /2 weeks ago

Zero-Copy and the Page Cache: Why Kafka Is Fast, Using FileChannel.transferTo

Kafka moves enormous amounts of data, yet its brokers do surprisingly little work per byte. The secret is not clever Java code. It is the opposite: Kafka avoids touching the data a...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.