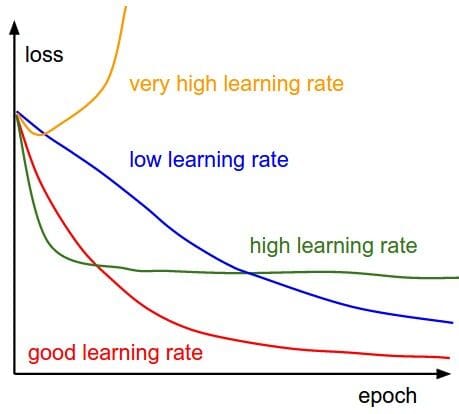
Cross-Validation and Hyperparameter Tuning: A Complete Guide to Building Better Machine Learning…
IntroductionContinue reading on Medium »
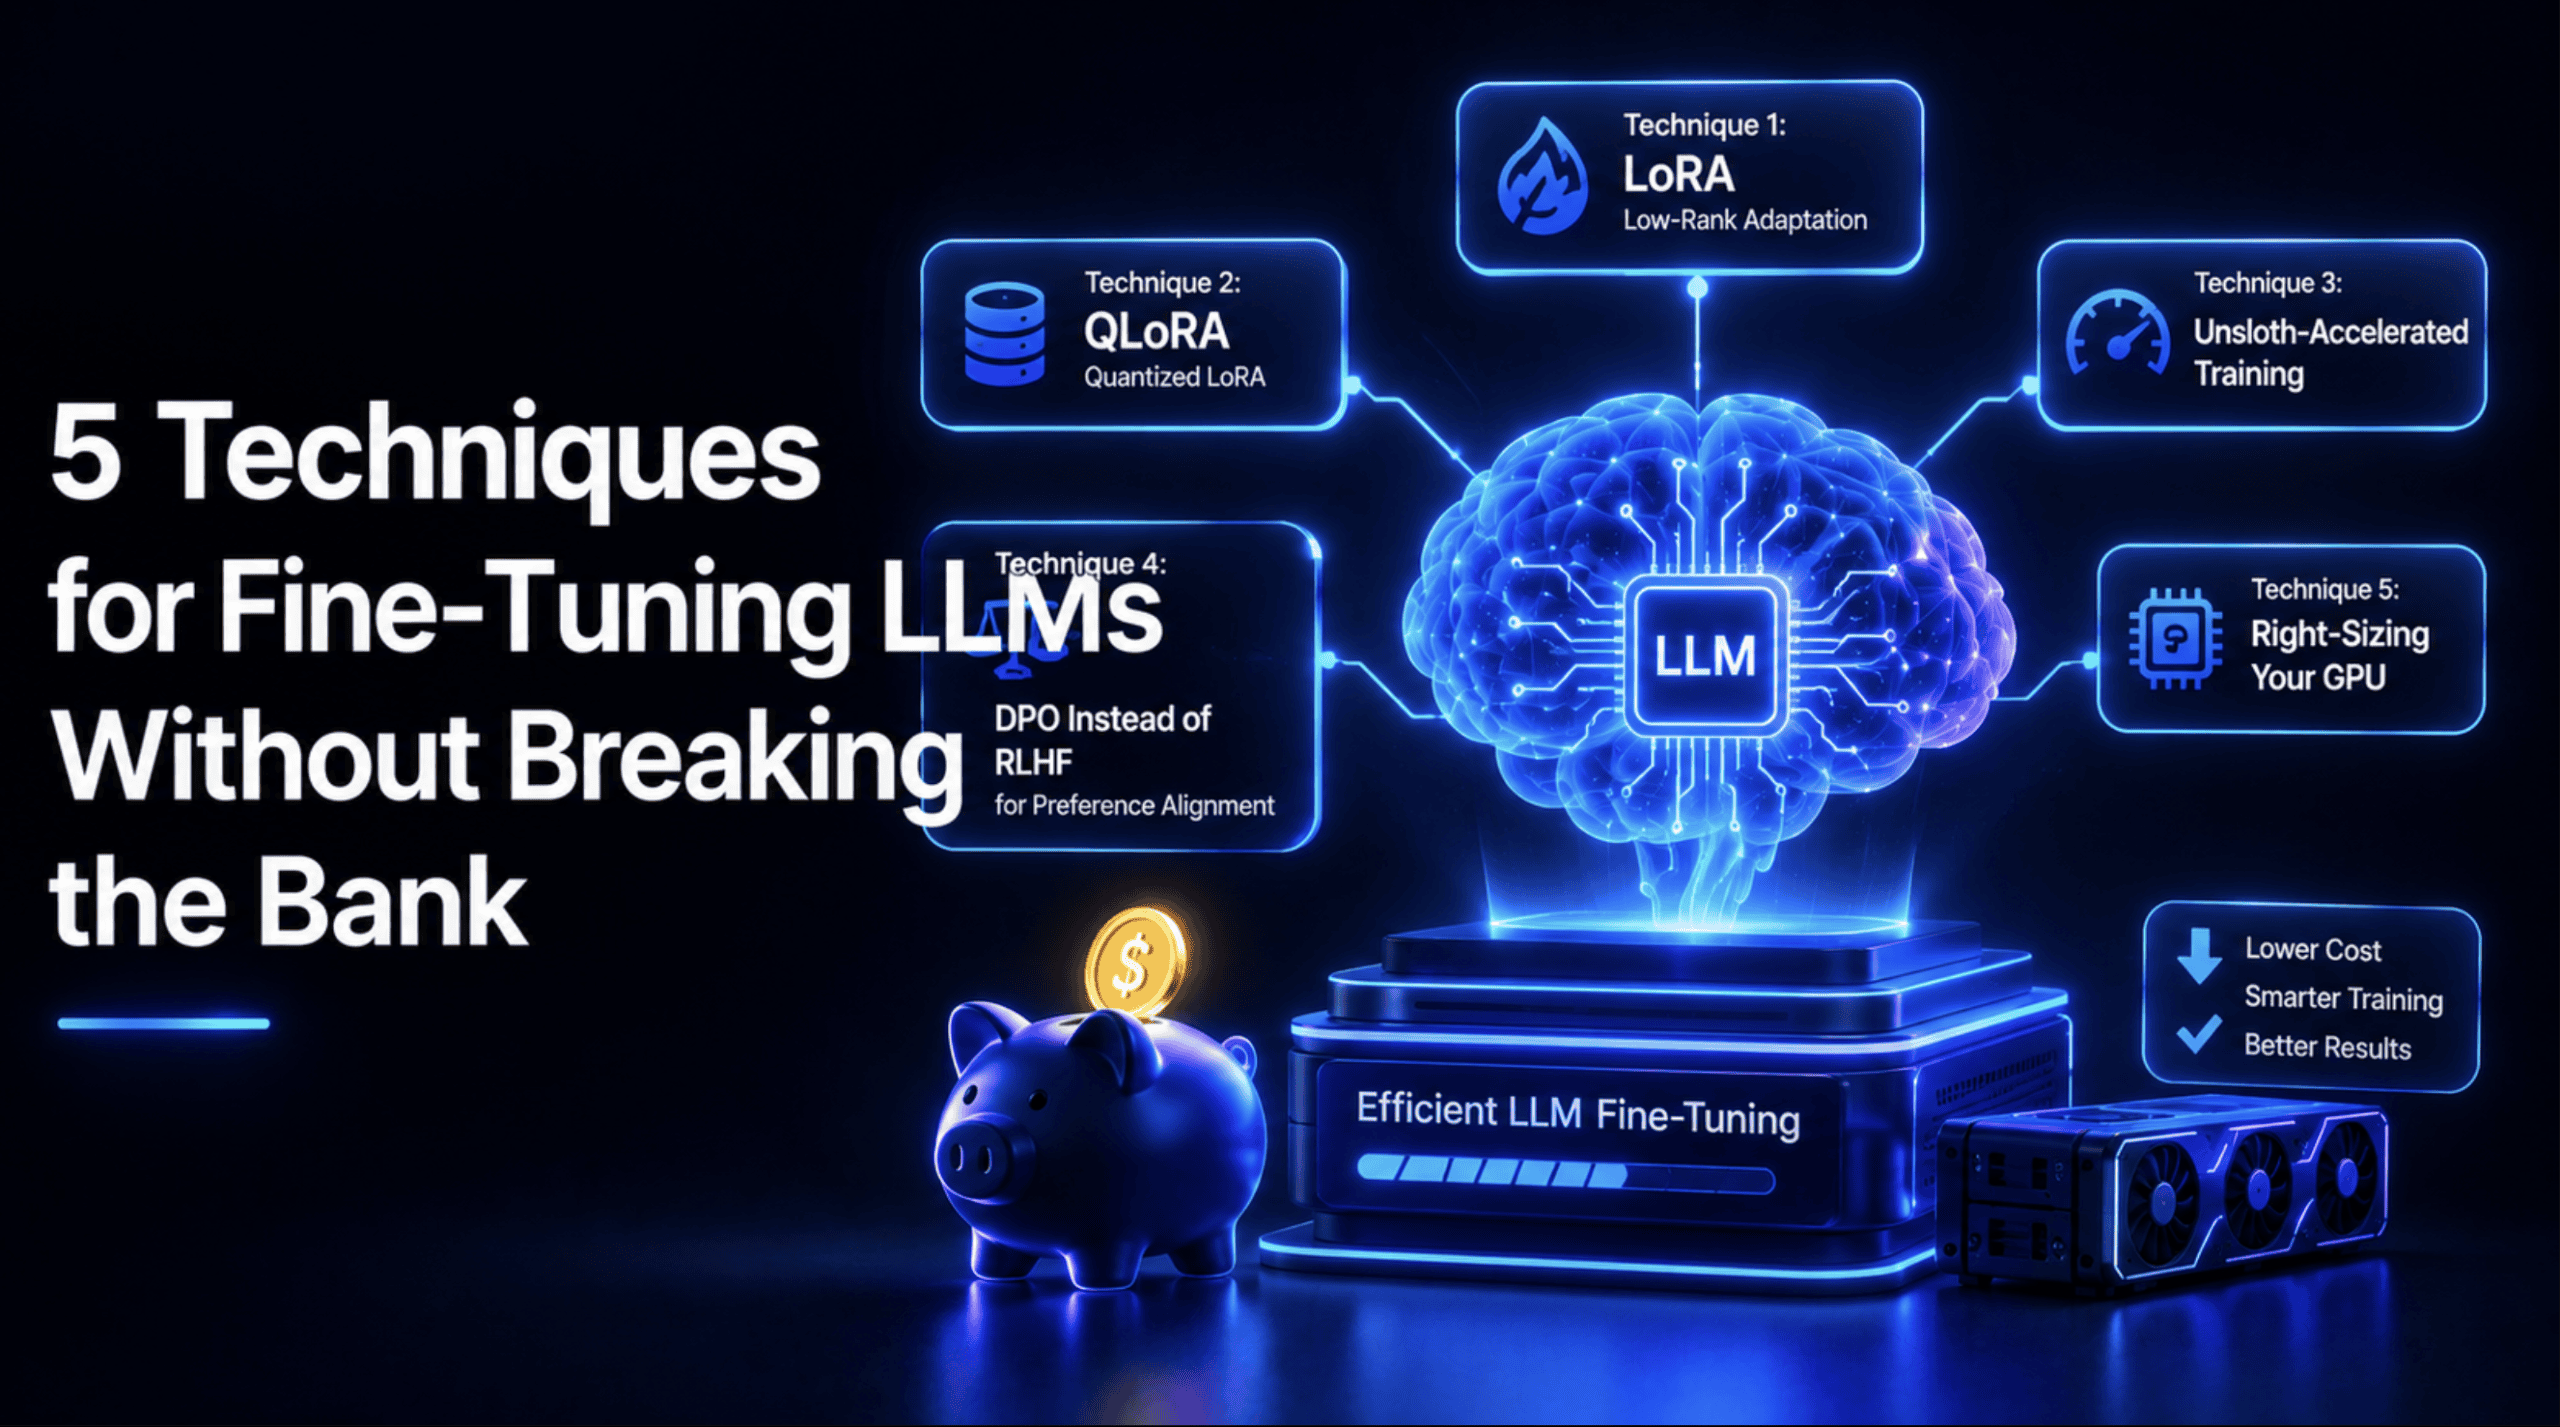
Learn five practical ways to fine-tune LLMs on a budget, from LoRA and QLoRA to Unsloth, DPO, and right-sizing your GPU, with working code for each technique.
How to measure, then tune, the settings that decide how fast a 125B MoE model runs on a home PCContinue reading on Medium »
AWS engineers share kernel optimizations for fused Mixture-of-Experts (MoE) models on Amazon SageMaker AI: Swap-AB for WGMMA utilization, Triton backend routing for FP8 quantizatio...
Abacus.AI applied the same fine-tuning recipe to three very different open-weight models. The gains landed in completely different places & that tells you more than any single...
<strong>... [Trackback]</strong> [...] Read More here to that Topic: kdnuggets.com/2019/06/automate-hyperparameter-optimization.html [...]
Which knob moves latency, which moves throughput, and which one quietly breaks accuracy, with a worked build sequence on YOLO26 and a…Continue reading on Medium »
Amazon SageMaker AI Serverless Model Customization now supports Full Fine-Tuning (FFT). This post explores when FFT outperforms LoRA across key benchmarks, examines the spectral pr...
Learn how we fine-tuned GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod, and how to decide between supervised fine-tuning (SFT) and reinforcement learning with...
A Hands-On Guide to PEFT and TRL: Choosing Rank and Alpha, Masking the Loss Correctly and Measuring Whether the Adapter HelpedContinue reading on GoPenAI »
Most gains in a supervised learning project don't come from switching algorithms; they come from what you feed the algorithm. Feature engineering is the process of transforming raw...
I don't think the title of your article matches the content lol. Just kidding, mainly because I had some doubts after reading the article.
Fine-tuning teaches a small search agent your tools and environment, giving it the reliability of a frontier model at lower latency and cost. In this post, we fine-tune an LLM-powe...
<strong>... [Trackback]</strong> [...] Read More here on that Topic: kdnuggets.com/2019/01/fine-tune-machine-learning-models-forecasting.html [...]
Optuna v5 and Rustuna adopt PED-ANOVA for fast hyperparameter importance evaluation with support for conditional search spaces.Continue reading on Optuna »
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.