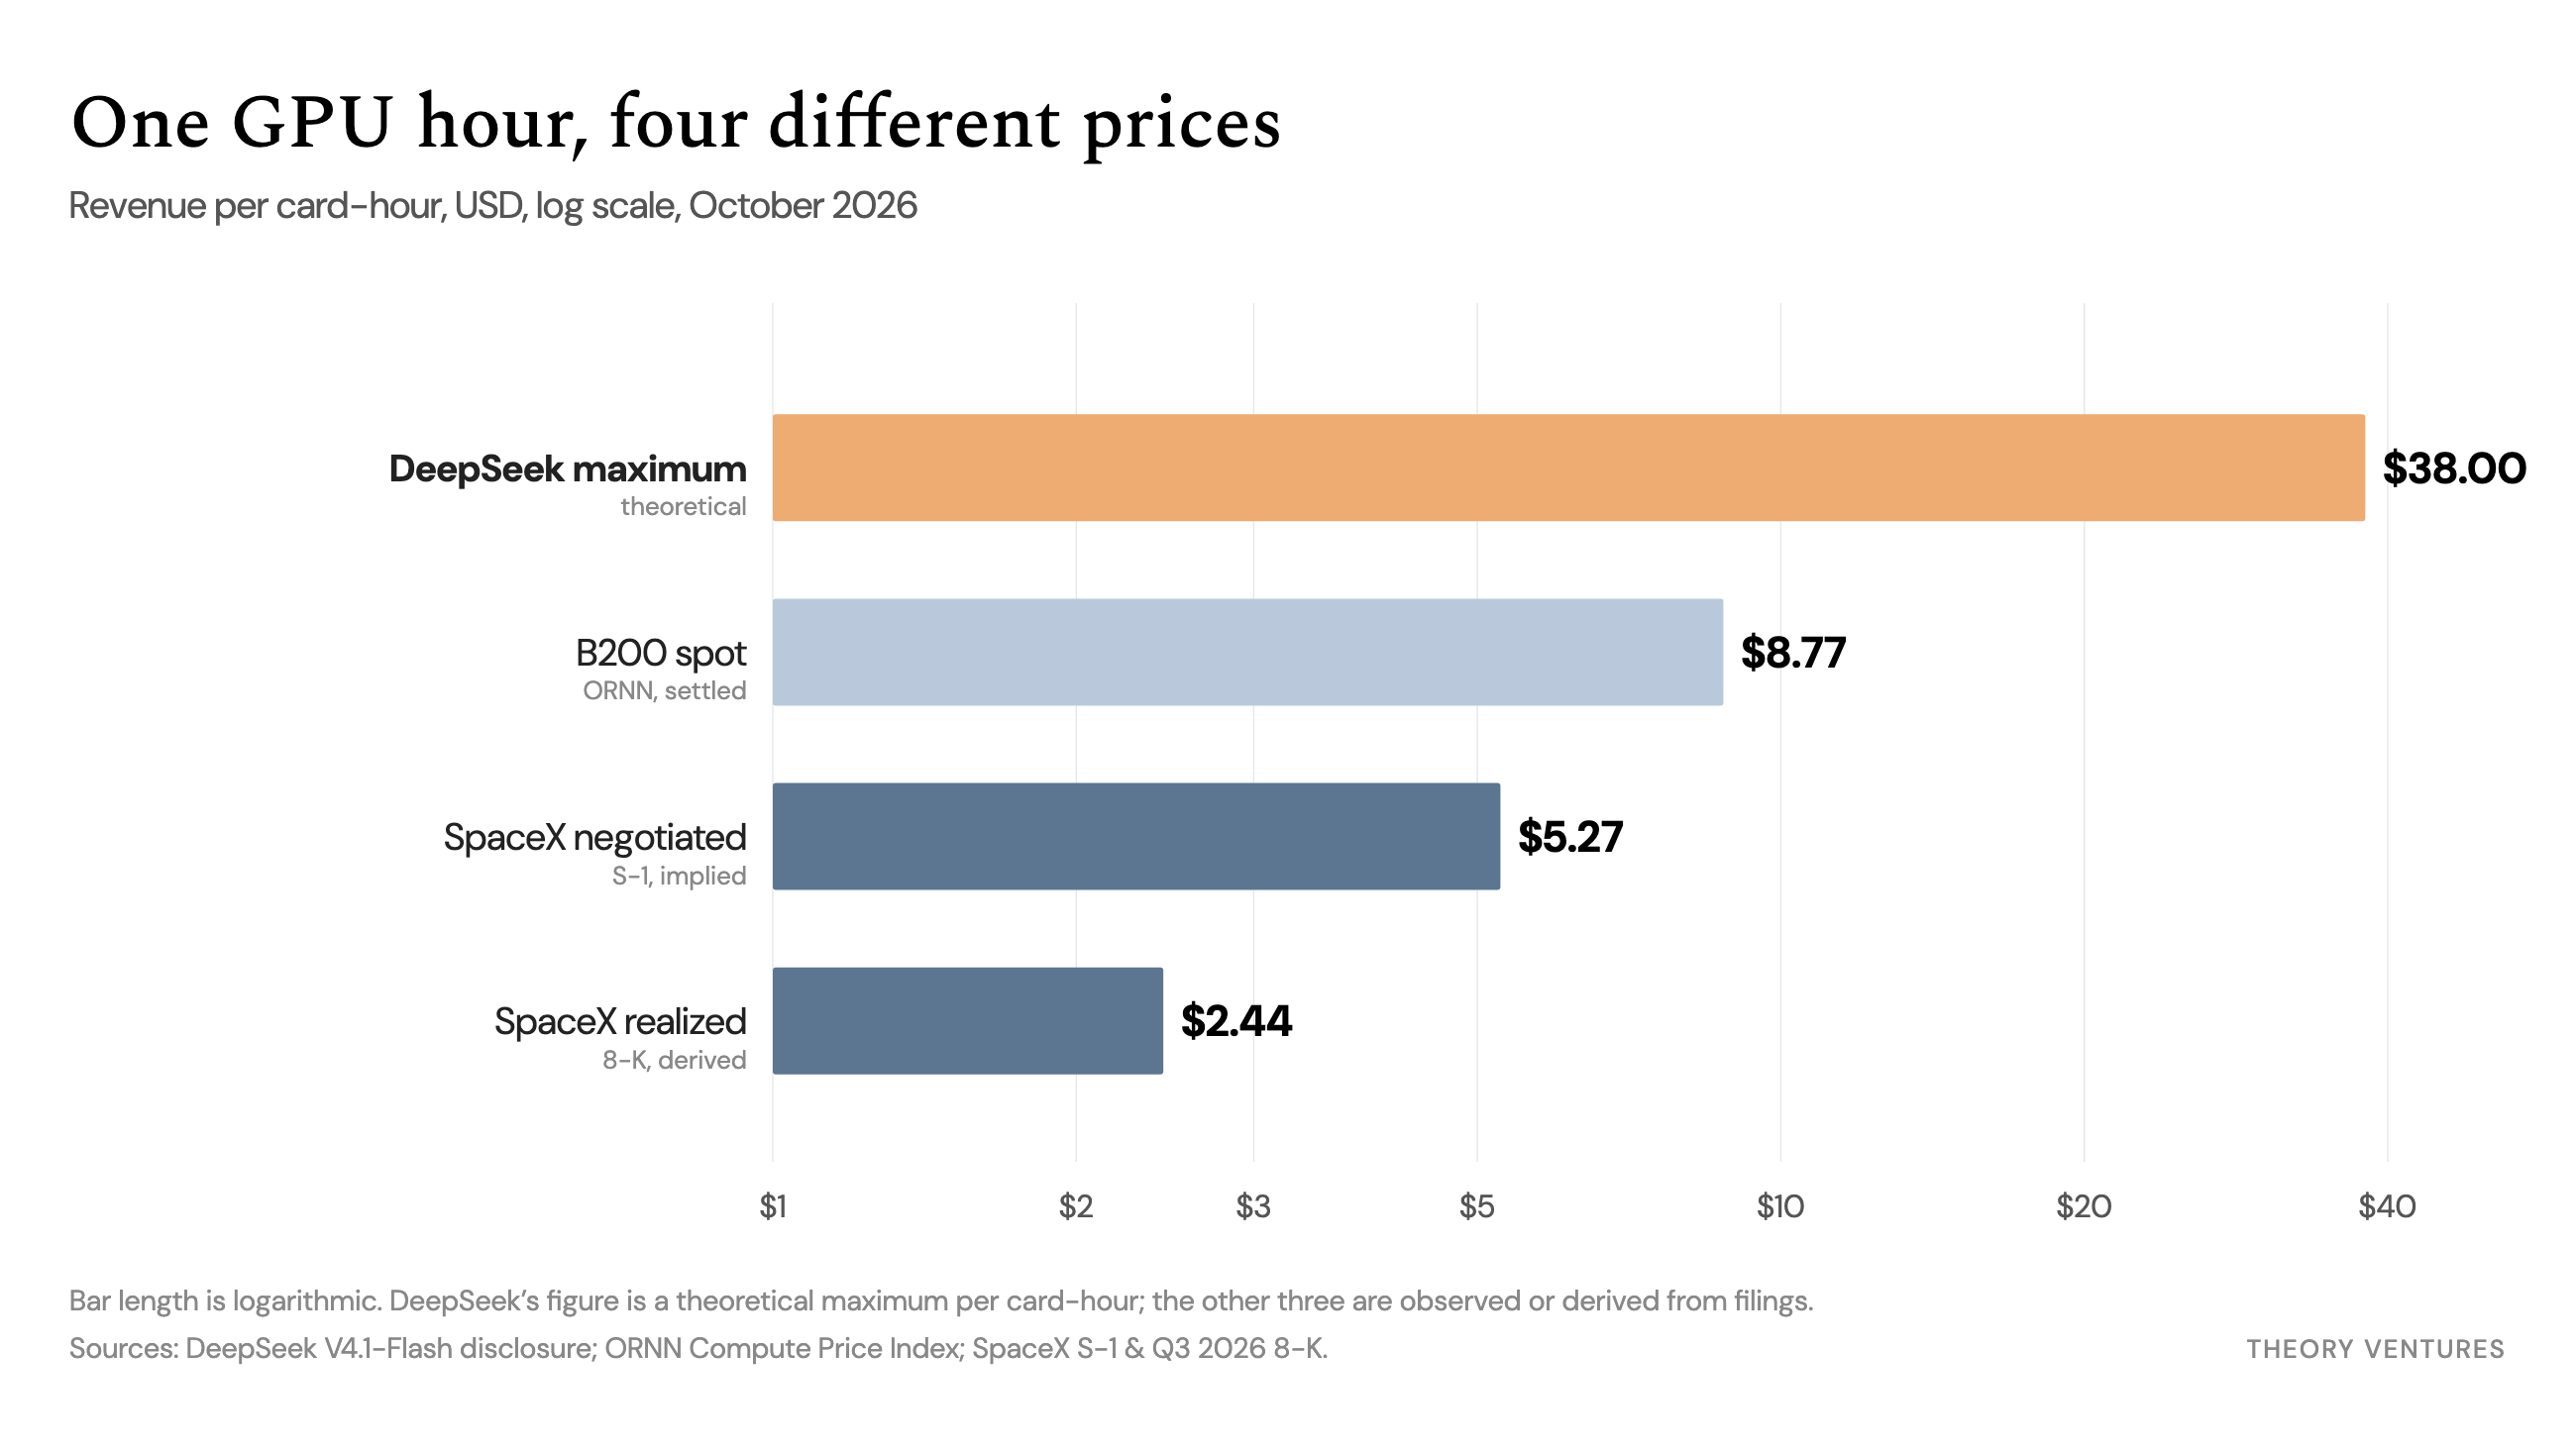
pandaily.com /2 weeks ago

GPUWorks Open-Sources 40MB Inference Platform Running Ascend, PPU, Hygon and NVIDIA in One Cluster

Open-sourced under Apache-2.0, GPUWorks pools Ascend, T-Head PPU, Hygon and NVIDIA GPUs in one cluster; its developers say one server ran 1,003 GPU machines.

Read source
levelup.gitconnected.com /1 week ago

Everything an AI Engineer Needs to Know About GPUs

What is inside a GPU, how training and inference use it differently, the generations, what you actually rent, NVIDIA’s competitors, and…Continue reading on Level Up Coding »

Read source
pandaily.com /3 weeks ago

Iluvatar CoreX Shows Its Tiangai 300 GPU Running Live, Claiming 1.05x H200 Throughput

Iluvatar CoreX gave the Tiangai 300 general-purpose GPU its first live demo and says third-party tests put single-card throughput at 1.05 times the H200. The test method was not di...

Read source
indiandefensenews.in /1 month ago

IIT-Delhi Unveils India’s First Indigenous Micro-GPU, Eyes Advanced Multi-Core Graphics Future

Researchers at IIT-Delhi have developed India’s first working and demonstrable indigenously designed micro Graphics Processing Unit (micro-GPU), marking a significant step towards...

Read source
techbuzzireland.com /1 month ago

How to Choose the Right GPU Hosting Plan for AI Workloads

AI development is no longer limited to large technology companies. Developers and businesses are increasingly using GPU infrastructure for model inference, image generation, video...

Read source
telecomtalk.info /1 month ago

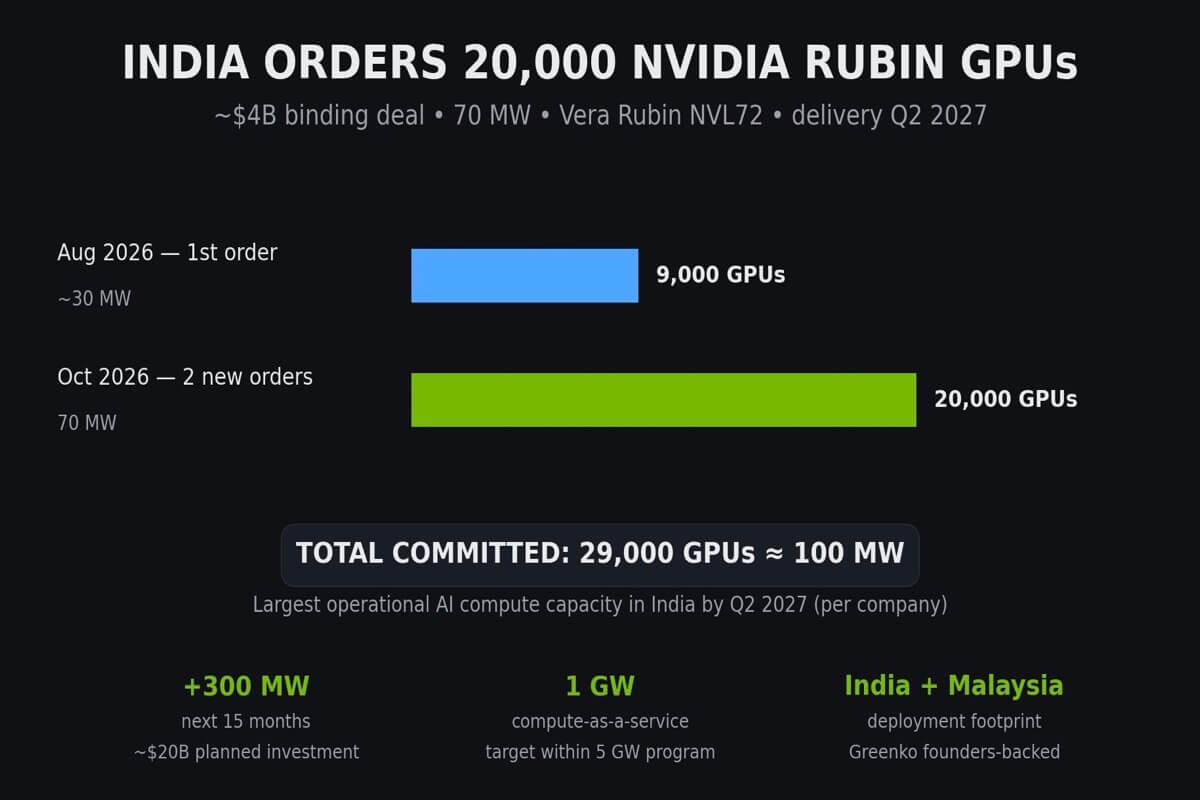
NVIDIA Sends 20000 Rubin Gpus to India

India is preparing for a major AI computing expansion. AM Intelligence, backed by the people behind Greenko, has ordered another ... Read More

Read source
tomtunguz.com /1 month ago

The GPU Revenue Ladder

SpaceX's third-quarter report & DeepSeek's inference disclosure together price one GPU card-hour four ways, from DeepSeek's theoretical $38 maximum to SpaceX's realized $2.44....

Read source
pandaily.com /2 weeks ago

Moore Threads' 2,112-GPU Wuxi Cluster Reaches 92.9% Utilization After Going Commercial

Moore Threads' MTT S5000 cluster in Wuxi runs 2,112 GPUs for 55 customers at 92.9% utilization, with DeepSeek V4 Flash inference tests reaching 92% of an H800 setup.

Read source
computerra.ru /2 weeks ago

Выделенный GPU-сервер: кому и зачем нужна физическая изоляция в эпоху облаков

Источник: Компьютерра - Журнал о науке и технологиях Для обучения нейросети или запуска собственной LLM сегодня достаточно арендовать виртуальную машину с GPU. Однако когда модель...

Read source
3dnews.ru /1 month ago

Giga Computing развернула ИИ-полигон GAIFA на базе NVIDIA GB300 NVL72

Компания Giga Computing, являющаяся подразделением Gigabyte, объявила о создании площадки GAIFA (Gigabyte AI Factory Accelerator) — своего первого вычислительного центра в области...

Read source
habr.com /1 week ago

От нуля до GPUaaS, или Как завести в Kubernetes технологии InfiniBand, RDMA и GPUDirect

На рынке мало экспертизы по запуску GPU-стека и InfiniBand именно внутри Kubernetes (обычно их настраивают на "голом железе" / bare-metal), а официальная документация NVIDIA имеет...

Read source
asia.nikkei.com /1 month ago

AI data centers increasingly built on GPU collateral, other novel financing

Read source
runet.news /1 month ago

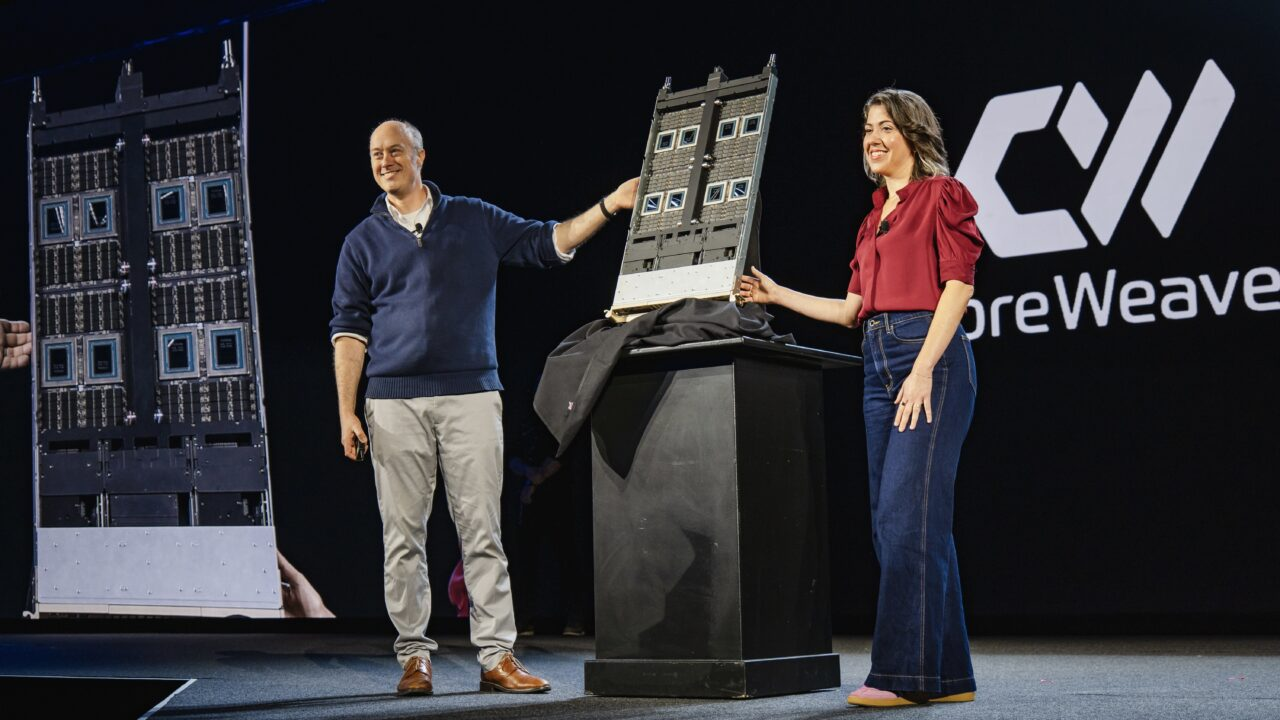
Nvidia Vera Rubin NVL72 запустили в облаке, результаты оказались выше GB200

Облачный провайдер CoreWeave запустил в своей инфраструктуре систему Nvidia Vera Rubin NVL72. Компания Cognition стала первым клиентом, разместившим на ней производственные ИИ-нагр...

Read source
pcworld.com /2 weeks ago

Can You Run Your Own AI Locally on a Gaming GPU?

Run powerful AI locally with MSI RTX 50-Series GPUs Explore the range and find the right GPU for your needs Shop on Amazon AI might be everywhere and in e...

Read source
phoronix.com /1 month ago

Intel Announces The GPU D Series For Crescent Island

Intel announced today the GPU D Series for the enterprise-focused, inference-optimized GPU accelerators known to now as Crescent Island...

Read source
medium.com /1 month ago

Infrastructure for Large-Scale AI Model Training on Dedicated GPU Clusters

How enterprise AI teams evaluate GPU clusters, interconnects, storage, and managed infrastructure for large-scale AI training programs.Continue reading on Medium »

Read source
theregister.com /1 month ago

Nvidia's grand plan for speeding up datacenter deployments: AI trailer parks

GPUzilla boasts modular bit barns could speed up deployments from six months to just two weeks

Read source
cryptobriefing.com /1 month ago

Google Cloud plans to scale Vera Rubin infrastructure to 960,000 GPUs

Google Cloud's GPU expansion could significantly enhance AI capabilities, impacting cloud computing efficiency and global tech infrastructure. The post Google Cloud plans to scale...

Read source
computerra.ru /1 week ago

ITGLOBAL.COM развернула для Qooqa Tech GPU-инфраструктуру на NVIDIA H200

Источник: Компьютерра - Журнал о науке и технологиях Компания Qooqa Tech модернизировала вычислительную инфраструктуру для своего ИИ-рекрутера, чтобы обрабатывать растущее число о...

Read source
hostinger.com /3 days ago

10 best GPUs for AI in 2026

The best GPUs for AI in 2026 include the RTX 5090 for local AI exploration and the RTX PRO 6000 [...] Read More... The post 10 best GPUs for AI in 2026 appeared first on Hostinger...

Read source
pandaily.com /2 weeks ago

Moore Threads Adds Day-Zero Kimi K3.1 Pro Support on MTT S5000 GPUs

Moore Threads says MTT S5000 and MUSA can load and serve Kimi K3.1 Pro with text and image inference, including sparse-attention and online weight-conversion support.

Read source
techmeme.com /5 days ago

Nvidia unveils its Rubin HPC GPU with "more than 50,000" CUDA cores, up from 28,672 in the current Rubin GPU, for agenti...

Jeffrey Kampman / Tom's Hardware: Nvidia unveils its Rubin HPC GPU with “more than 50,000” CUDA cores, up from 28,672 in the current Rubin GPU, for agentic workflows and scientific...

Read source
dev.to /2 weeks ago

SambaNova and Supermicro's inference plan puts the handoff between chips in focus

SambaNova announced a collaboration with Supermicro on November 3 to develop and sell inference systems combining NVIDIA GPUs with SambaNova SN50 Reconfigurable Dataflow Units, or...

Read source
medium.com /1 month ago

Zero-Host-Copy Inference: Keeping the CPU Out of the Hot Path in a C++/CUDA Pipeline (165 FPS)

1. Introduction: Anatomy of the BottleneckContinue reading on Medium »

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.