LLM Streaming with Embabel
Large Language Models can take several seconds, or sometimes much longer, to produce a complete response. In a traditional blocking application, the caller waits until the entire r...
Validating a streaming pipeline beyond current peak takes production-scale test data. This post shows how the stream multiplier pattern on Amazon Managed Service for Apache Flink t...
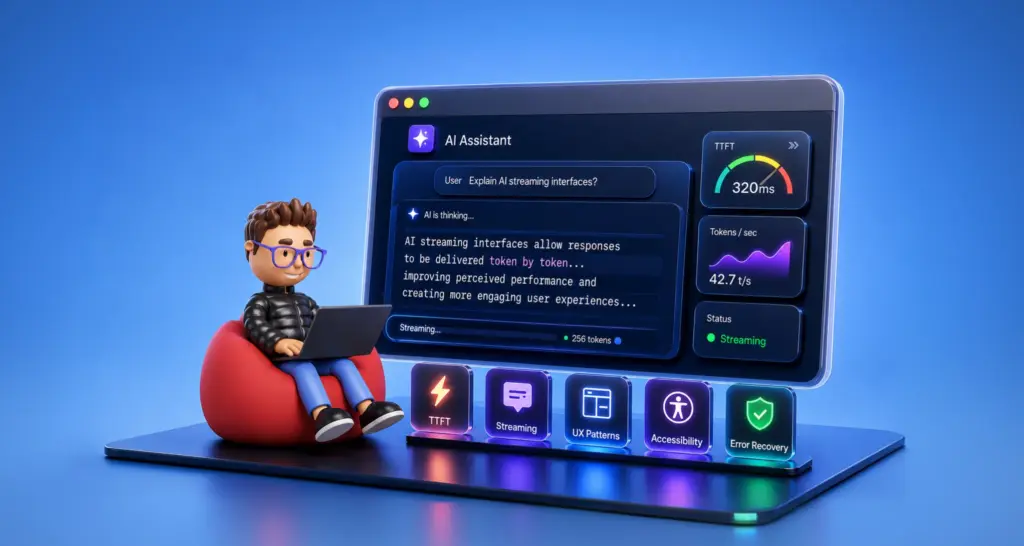
Learn AI streaming UX patterns for TTFT, HTTP streaming, partial-response handling, Generative UI, accessibility, and production monitoring.
AWS Marketplace now supports usage-based metering for Amazon SageMaker bidirectional streaming inference, so model providers can charge for what customers actually consume during a...
Каждые 10 минут в русскоязычном эфире Twitch и VK Видео Live в среднем 7 200 каналов. Писать их как есть - больше миллиона строк в сутки. Я храню агрегаты, и за четыре недели вышло...
Stream 50 million rows without OOM: Lazy chunked Query Streaming. Day 09 of the WClickHouse Open-Source Engineering Series. You don't need 64GB of RAM to process millions of C...
Snowflake benchmarked Elastic Channels for Snowpipe Streaming at 41 GB/s and 133M rows/sec on a single table — 3.5x faster with linear horizontal scaling.
Your point of view caught my eye and was very interesting. Thanks. I have a question for you.
An AI inference service makes a model available to an application through an API. When you ask an inference API a question, the application sends your prompt to the service. The se...
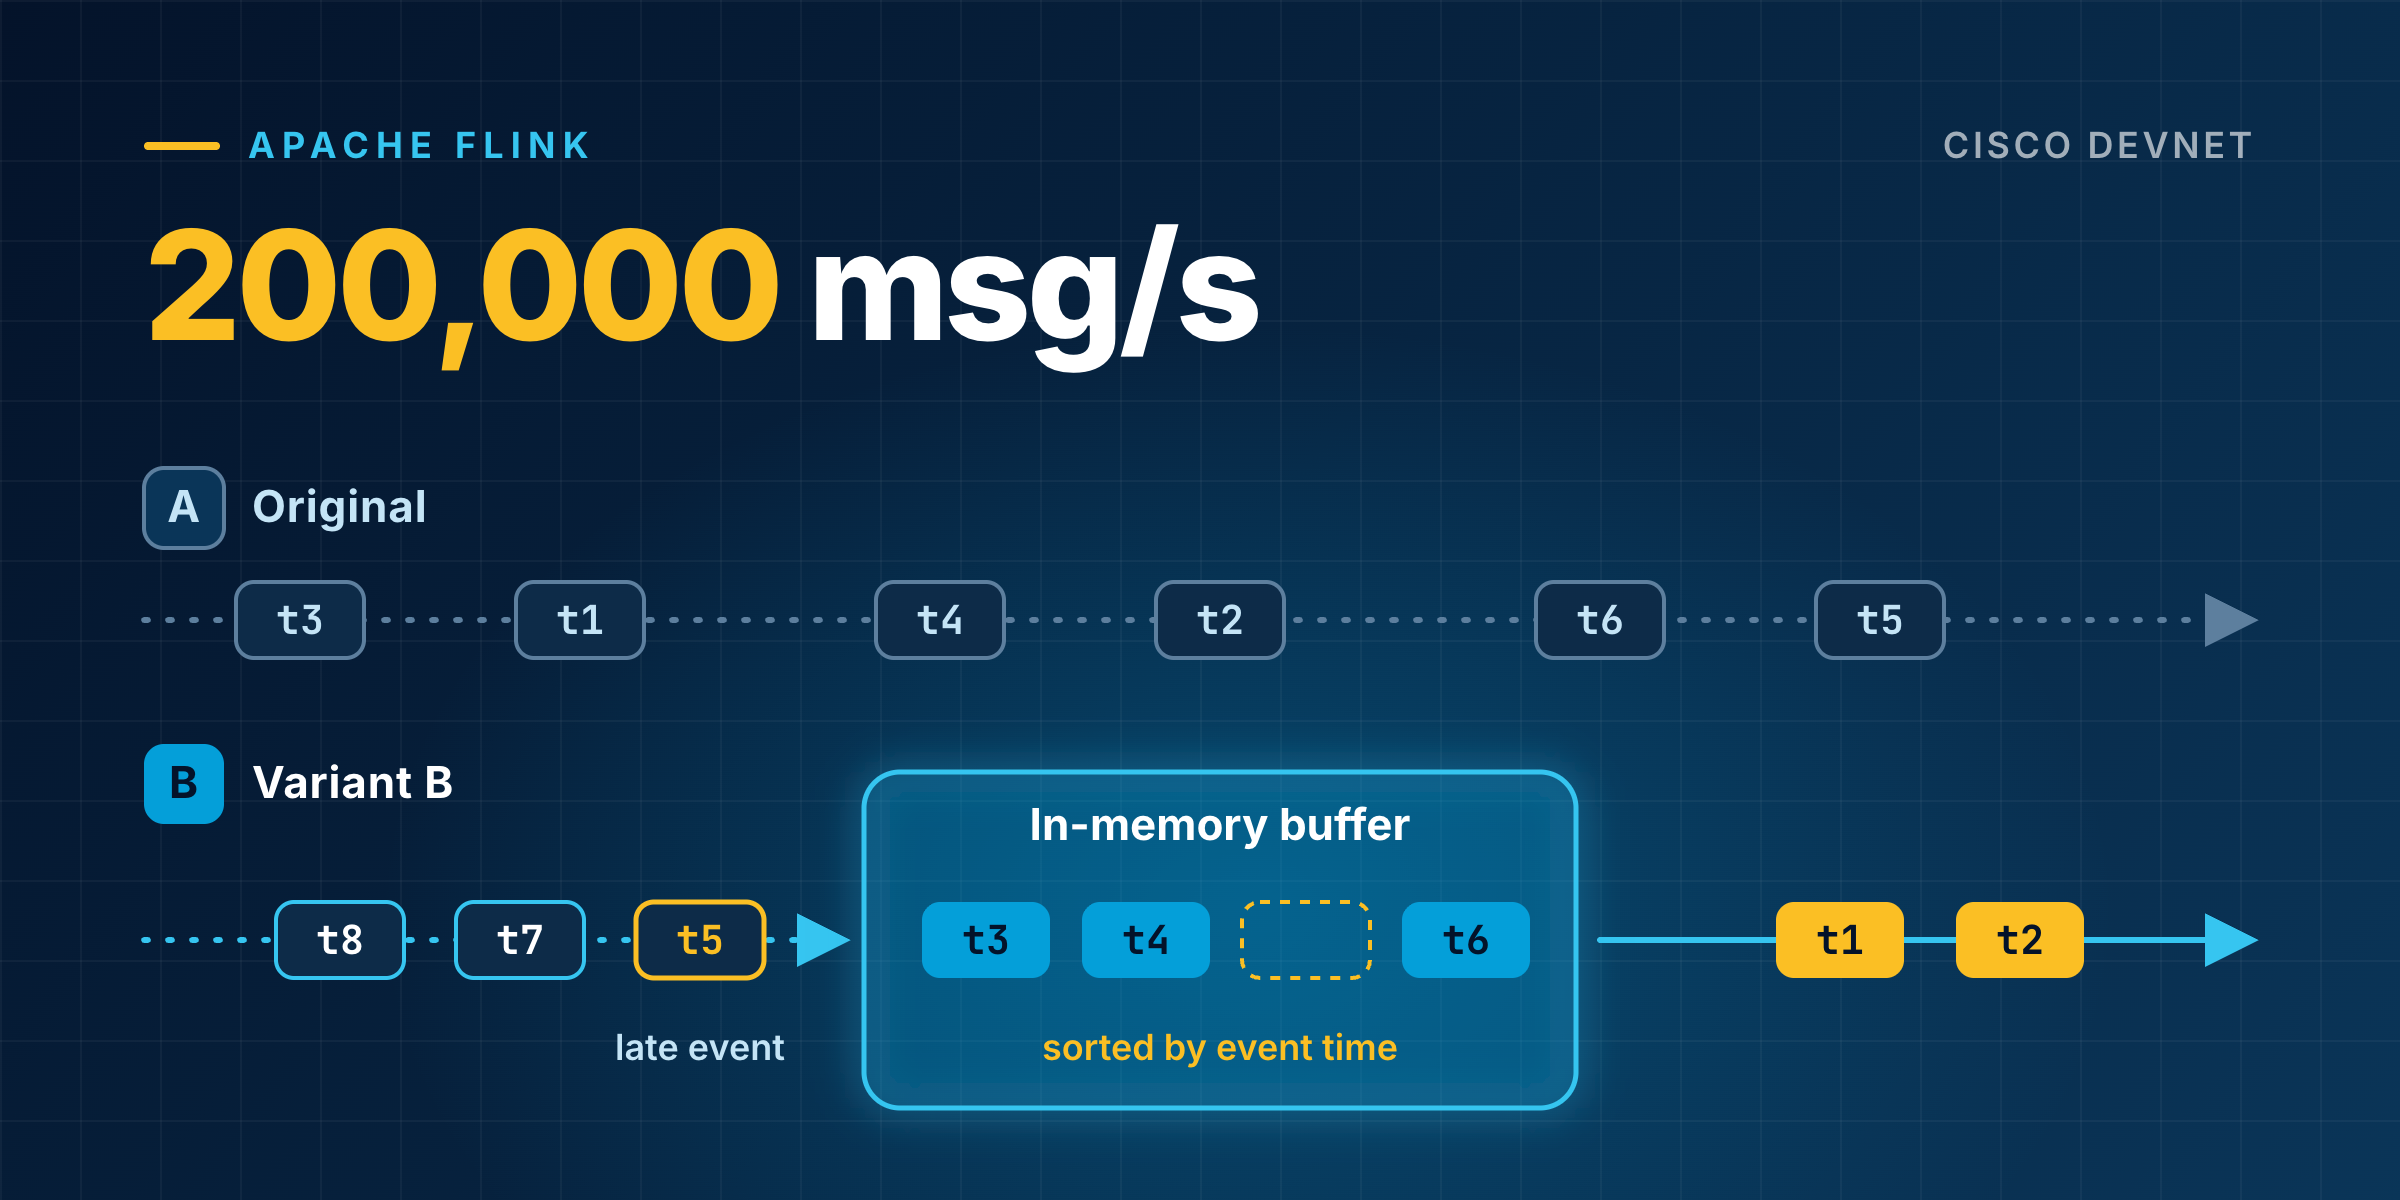
Our Flink job hit a wall at 200,000 messages per second because of RocksDB. Here is the in-memory reordering pattern that fixed it, and how A/B development proved it safe.
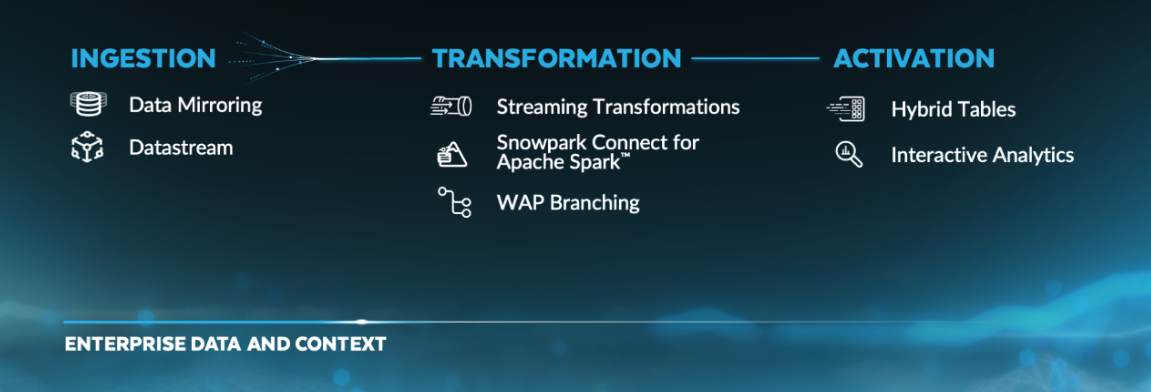
Build real-time analytics on Snowflake. Stream data in, keep it fresh and serve subsecond answers.
The post Streaming appeared first on Film Advance.
Now tracking viewership and ad exposure across 600+ streaming apps globally: a single linear-and-streaming foundation for identity, planning, content insights, targeting, and measu...
Data integration used to be treated as back-office plumbing. Difficult, yes, and always operationally critical, but rarely seen as strategic. That has changed. The Data Integration...
For anyone running an inference server: a zero-variance control, five traffic traces, and an engine-vs-scheduler split show where the gains come from. The post Continuous Batching...
The choice between Pipes and Streams for data processing hinges on specific workloads. Optimal selection requires benchmarking based on the application's data handling needs.
Modern data platforms are increasingly responsible for powering critical decisions, applications, analytics systems, and AI workloads. As organizations move more business processes...
Voice agents often wait for an agent's full response before starting speech synthesis, adding latency users feel directly. This post shows how to stream each sentence to a Kokoro-8...
What started as a recovery tool for streaming pipelines ended up as a full-fledged self-service platform, with scheduled watermark-based incremental ingestion, ad-hoc/one-time data...
Production inference is fundamentally a scheduling problem. Once you've addressed serving architecture and memory, the next question isn’t whether the GPU can do the work; it's how...
Procesa 50 millones de filas sin OOM: Query Streaming por bloques. Día 09 de la serie técnica WClickHouse Open Source. No necesitas 64GB de RAM para procesar millones de regis...
Amazon Kinesis Data Streams now offers queues, a new way to consume the records of an on-demand stream. A queue delivers records one by one, tracks each record's delivery state, re...
Learn how Delivery Hero rebuilt its ad measurement pipeline from hourly batch processing to real time on Amazon Managed Service for Apache Flink, cutting the gap between an event a...
We introduced Real-Time Mode (RTM) last year which enabled customers to build low-latency, operational use cases...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.