Latest updates for Contrastive Language Model

Fresh curated links around Contrastive Language Model are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

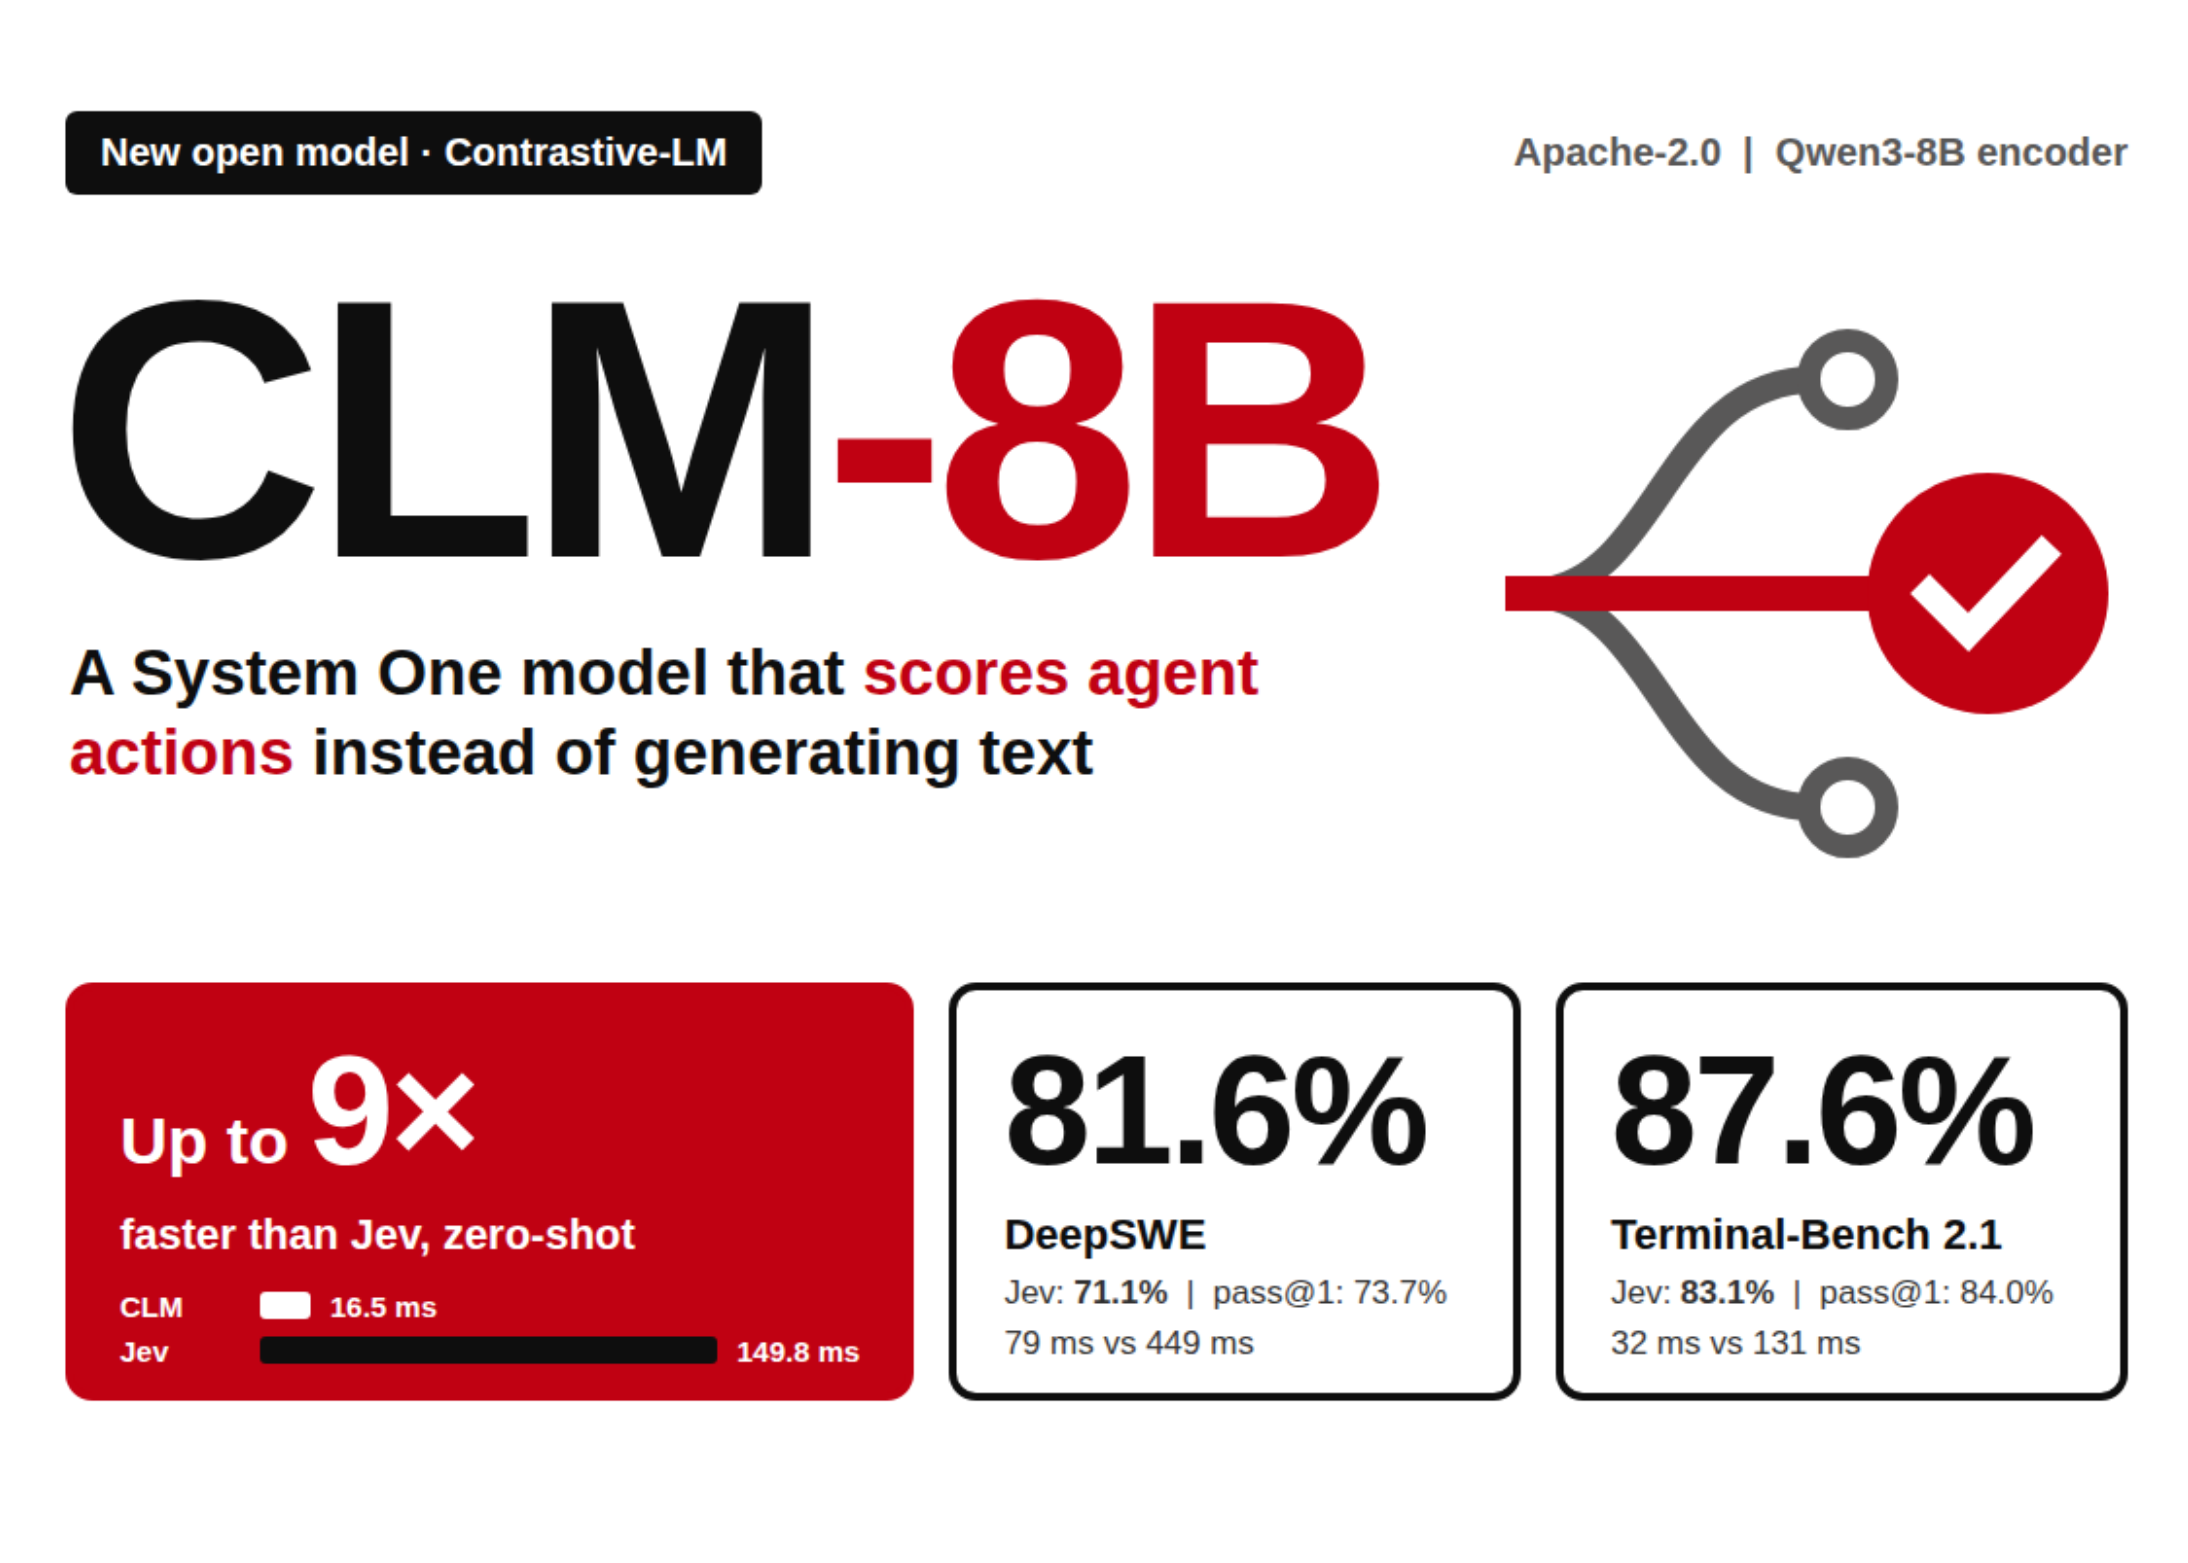
  • Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev
  • LLMSignal #003 — А что если агенту вообще не нужно генерировать текст, чтобы выбрать следующее действие
  • Отличие языковой модели LLM от человека

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

marktechpost.com /4 weeks ago

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

Contrastive-LM has released CLM-8B, an open System One model that scores candidate actions against a state instead of generating text. It adds 2 small projection heads to a frozen...

Read source
habr.com /4 weeks ago

LLMSignal #003 — А что если агенту вообще не нужно генерировать текст, чтобы выбрать следующее действие

Исследователи Stanford Hazy Research представили CLM-8B - Contrastive Language Model, открытую 8B-модель для быстрых решений внутри агентных систем. В отличие от обычной LLM, котор...

Read source
habr.com /1 month ago

Отличие языковой модели LLM от человека

Не собирался писать статью — эту нишу уже отжали у людей орда всевозможных LLM. Но оставил коммент в статье Как ChatGPT создал Культ Роя для сотен AI‑нейросетей: вся правда про взл...

Read source
habr.com /1 month ago

Почему LLM не могут овладеть человеческим языком в совершенстве

Даже идеальная модель с бесконечным объемом текста не восстановит ту часть смысла, которая никогда не была закодирована в языковой форме.Представьте фразу в рабочем чате: «он снова...

Read source
javacodegeeks.com /3 weeks ago

Extracting Reliable Structured Data from LLMs

Large language models are good at understanding natural language, but applications usually need information in a predictable form. A customer support application, for example, may...

Read source
medium.com /3 weeks ago

RAG vs Long-Context LLMs: Why Bigger Context Windows Do Not Solve Retrieval

Large Language Models can now process hundreds of thousands, and sometimes even millions, of tokens.Continue reading on Medium »

Read source
javacodegeeks.com /2 weeks ago

Semantic Caching for Large Language Models

Large Language Models (LLMs) have transformed the way applications process and generate natural language. They are widely used in chatbots, search systems, coding assistants, docum...

Read source
dev.to /1 month ago

# Beyond Transformers: A Mathematical Critique of Cross-Lingual Diffusion Architectures

Beyond Transformers: A Mathematical Critique of Cross-Lingual Diffusion Architectures The current state of multilingual NLP is dominated by transformer-based architectures that o...

Read source
javacodegeeks.com /3 weeks ago

LLM Fine-Tuning: SFT, LoRA, QLoRA, RAG and Prompting

Large language models can perform many tasks without any additional training. They can answer questions, summarize text, generate code, classify information, and interact with tool...

Read source
towardsdatascience.com /2 weeks ago

The Reversal Curse: Why a Language Model That Knows “A Is B” Can’t Tell You “B Is A”

A model can recall a fact in the direction it learned it and fail in the other. Here's a toy version of why The post The Reversal Curse: Why a Language Model That Knows “A Is B” Ca...

Read source
testmuai.com /1 month ago

Rethinking Ranking in the LLM Era [Testμ 2026]

Rhea Goel of Amazon on replacing a re-ranker with an LLM: natural language objectives, fine-tuning, DPO, hard and soft constraints, distillation and LLM judges.

Read source
pandaily.com /3 weeks ago

Bilibili Open-Sources Index-Translate, a Qwen3.5-Based Translation Model Family for 150 Languages

Bilibili's Index LLM team released Index-Translate under Apache-2.0: 2B, 9B and 35B-A3B preview text models for 150 languages, plus dubbing, syllable-control and long-document vari...

Read source
javacodegeeks.com /1 month ago

How to Switch Between AI Models Automatically

AI applications do not always need the same language model for every request. A simple factual question may only require a small, fast model, while a request involving multiple con...

Read source
kdnuggets.com /3 days ago

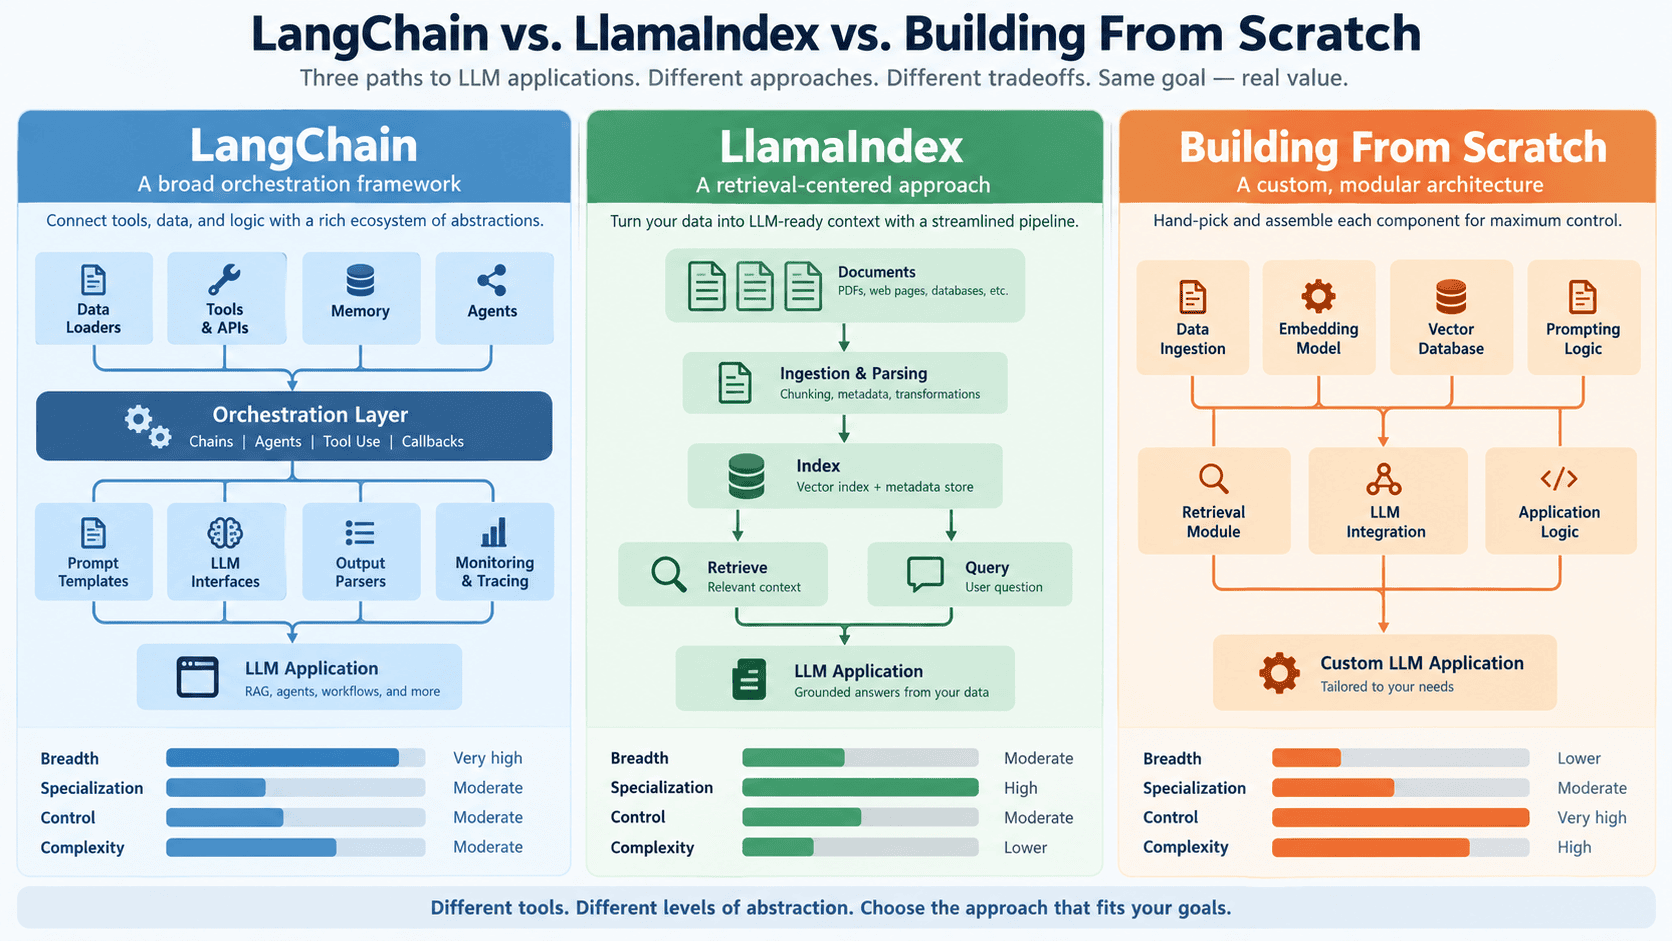
LangChain vs. LlamaIndex vs. Building From Scratch: Here’s What I Suggest

Choosing the right framework for your large language model application comes down to one question: what are you actually optimizing for?

Read source
medium.com /6 days ago

Understanding Large Language Models (LLMs)

The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »

Read source
habr.com /1 month ago

«Один нип осторожно замифрил», или как лингвисты разбирают язык внутри LLM

Неважно, что делает LLM. Задача все равно приходит словами, и одно пропущенное не может испортить уже вполне материальное действие. Смотрю на LLM глазами лингвиста и разбираюсь, к...

Read source
serpapi.com /6 days ago

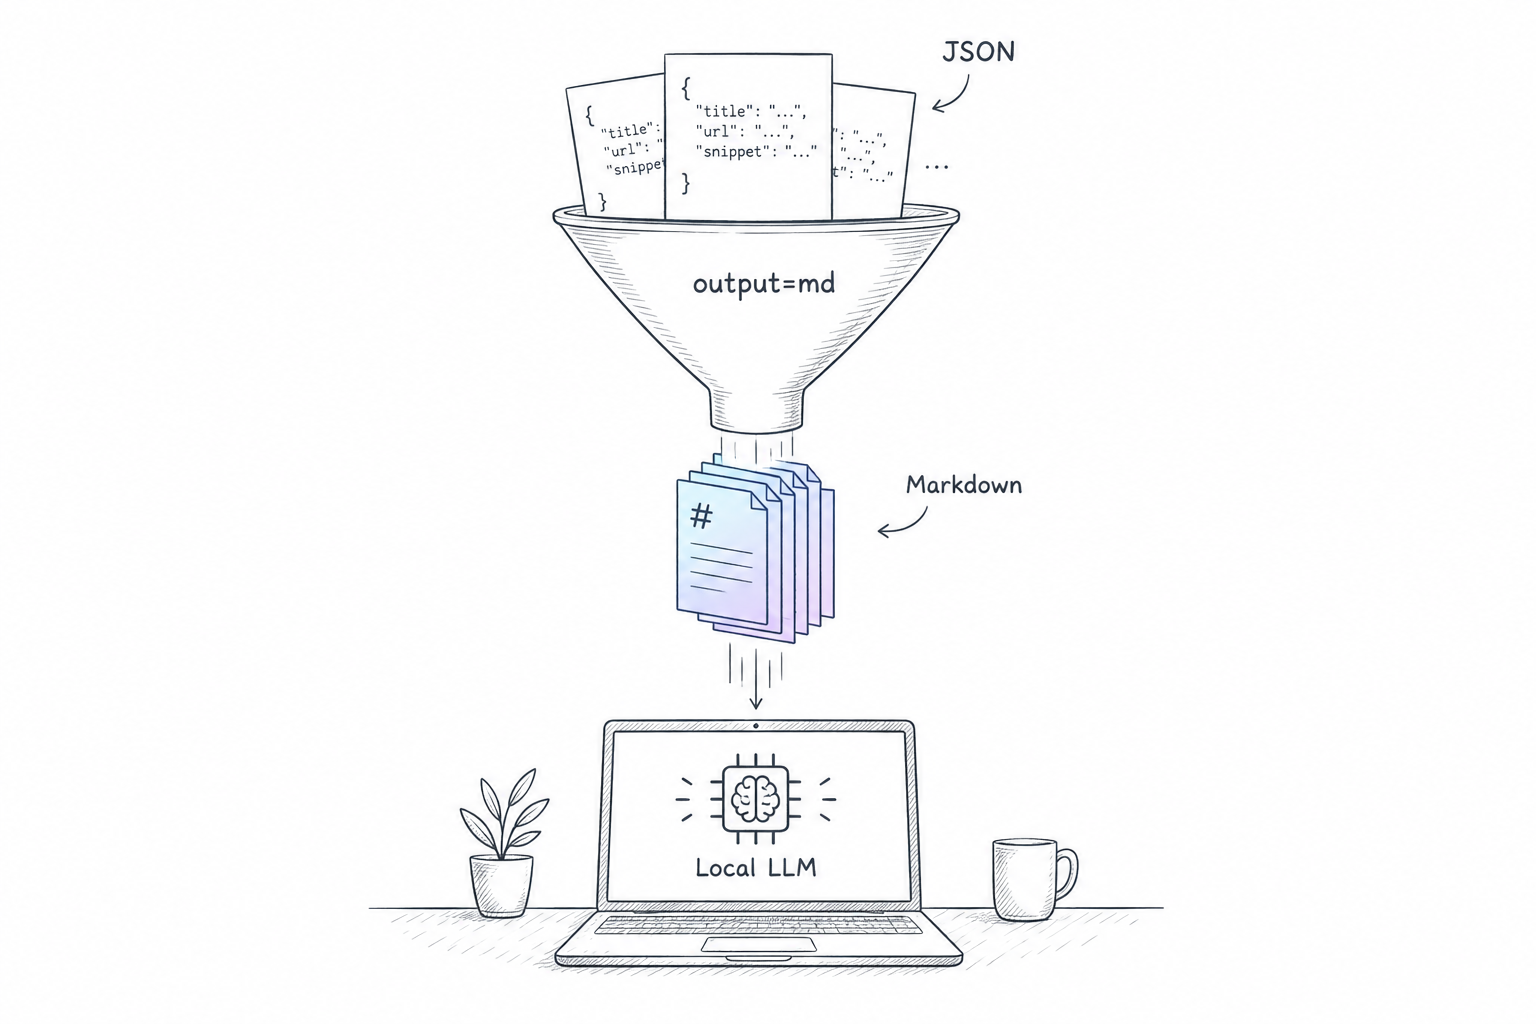
How to Fit More Web Search Data into a Local LLM

Use SerpApi's Markdown output and the JSON Restrictor to give a local LLM more web search data in the same context window, tested on four models in LM Studio.

Read source
habr.com /3 days ago

[Перевод] Коллапс модели при обучении на сгенерированных данных

Сейчас уже ясно, что большие языковые модели (LLM) никуда не денутся и существенно изменят экосистему текстов и изображений в интернете. Исследовательская группа из Оксфорда, Кембр...

Read source
dzone.com /1 month ago

Prompt Caching: Overriding Tokenization for Faster and More Cost-Effective AI

As Large Language Models (LLMs) become increasingly integrated into enterprise applications, optimizing response time and reducing operational costs have become critical priorities...

Read source
simplilearn.com /1 month ago

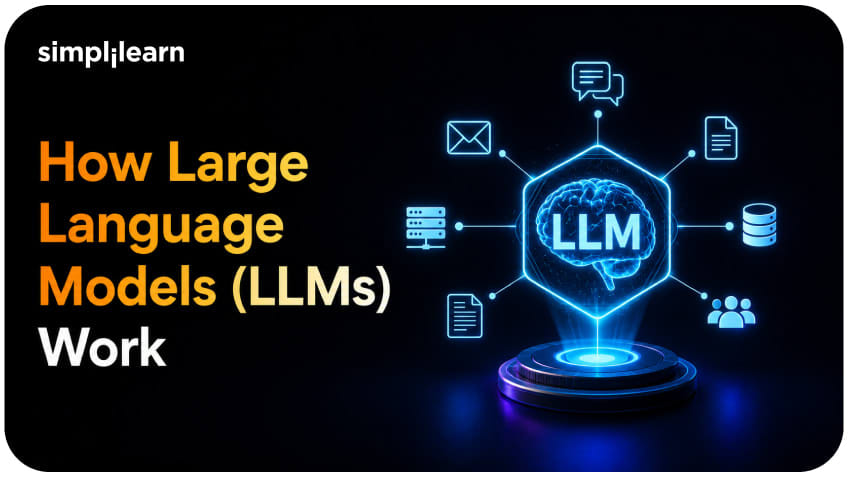
How LLMs Work: Transformer Architecture Explained | Simplilearn

TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...

Read source
marktechpost.com /1 month ago

Cohere Releases North Small Translate: A 218B MoE Translation Model That Scores 83.6 on WMT26 Across 50 Languages

Cohere has released North Small Translate, an open-weight Mixture-of-Experts model built for machine translation across 50 languages. It uses 25B of its 218B parameters per token a...

Read source
dev.to /3 days ago

Someone built a programming language to break LLMs. I ran it.

Dominik Picheta built a programming language whose design goal is to be unusable by LLMs. It's called KillSwitch, it hit Hacker News yesterday, and the pitch is specific: the spec...

Read source
computerra.ru /1 month ago

Российская модель определяет язык речи в 10 раз быстрее и в 5 раз легче аналога

Источник: Компьютерра - Журнал о науке и технологиях Компания «Криптонит» (входит в «ИКС Холдинг») разработала компактную модель для определения языка по короткому фрагменту речи....

Read source
marktechpost.com /3 weeks ago

Perplexity Releases pplx-embed-v2-context-9b-preview: A Contextual Embedding Model That Retrieves Answers and Their Supp...

Perplexity Research and turbopuffer have released pplx-embed-v2-context-9b-preview, a contextual embedding model for RAG pipelines. Each chunk is embedded with the full document in...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Contrastive Language Model

feeds.dzone.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source

medium.com

Recent coverage from public sources
Public source

pandaily.com

Recent coverage from public sources
Public source

serpapi.com

Recent coverage from public sources
Public source