dev.to /1 month ago

The scoring bugs we almost shipped in a hackathon judging platform

For DOGFOOD 2026, Hackathon Raptors gave teams an odd brief: build the platform they'll run their own hackathons on. Registration, teams, submissions, judge assignment, scoring, re...
Read source
testmuai.com /4 weeks ago

LangSmith vs Braintrust: Evals, Tracing and CI Compared

LangSmith vs Braintrust, checked against each vendor's own docs: tracing, scorers, CI gates, pricing meters and self-hosting, plus a scorer test on 20 inputs.

Read source
testmuai.com /1 month ago

G-Eval: How It Scores LLM Output, and What Its Data Shows

G-Eval scores LLM output with model-written evaluation steps and a probability-weighted score. See how it works, a recount of its SummEval data, and its limits.

Read source
testmuai.com /1 month ago

SimpleQA Benchmark: How It Scores Guesses and Abstentions

SimpleQA is a 4,326-question factuality benchmark. See how its F-score treats guesses and abstentions, what SimpleQA Verified changed and why scores differ.

Read source
testmuai.com /1 month ago

Chatbot Evaluation: What to Score and Who Should Score It

Chatbot evaluation scores conversations against set criteria. Learn what to score, who scores, a rubric, how to check a judge model and how many chats you need.

Read source
habr.com /1 week ago

[Перевод] Агент написал верный код, а потом удалил его ради скрытых тестов: что показал MaxxBench

Авторы MaxxBench взяли 89 задач кодингового бенчмарка DeepSWE и немного поменяли требования: медианный прирост эталонного патча составил всего 17 строк. Модели с почти одинаковыми...

Read source
habr.com /3 weeks ago

Как Kodik переиграл (и уничтожил) Codex, DeepSeek Harness и OpenCode на DeepSWE 1.1

Между запросом разработчика и готовым изменением находится ещё один важный компонент — агентная оболочка, или harness. Она отвечает за инструкции модели, контекст, инструменты и ор...

Read source
ministryoftesting.com /2 weeks ago

Code comprehension

Read source
habr.com /3 weeks ago

«6 − 2 = 3»: как мы проверяем кодом задания, которые пишет языковая модель

Мы делаем учебную игру: человек пишет цель своими словами («таблица умножения», «дроби за 5 класс», «английский для поездки»), а игра строит под неё путь из локаций. В каждой локац...

Read source
testmuai.com /1 month ago

HumanEval Benchmark: 164 Problems, pass@1 and HumanEval+

The HumanEval benchmark scores code models on 164 Python problems by pass@1. See how its tests accept wrong code, what HumanEval+ adds and why it is saturated.

Read source
roberthopman.com /1 month ago

scrap4rb: find the messy tests in a Ruby project

Originally appeared on Blog.Tests are code too, and they can get messy. I wanted a quick way to find the messy tests in a Ruby project, so I wrote a small gem called scrap4rb. It...

Read source
dzone.com /1 week ago

Using the Anthropic Evaluation Tool to Check the Claude Code Plugin Efficiency

A Claude Code skill is a Markdown document that the assistant loads when a task matches its description. A collection of skills, agents, and hooks can be packaged as a plugin and d...

Read source
joshmcdonald.medium.com /1 month ago

You Probably Need a Scorer, Not Another LLM Call

Small single-purpose models answer one question with one number between 0 and 1.Continue reading on Medium »

Read source
medium.com /1 week ago

The OCR Benchmarking Saga of 17 Engines

Testing 6 different tasks like markdown, tables, key-value, schema and geometryContinue reading on Data Science Collective »

Read source
towardsdatascience.com /1 week ago

A Session-Start Hook Raised Claude Code Skill Firing From 15% to 62%

A software tester ran six testing skills on Haiku, Sonnet, and Opus; pushy descriptions added only 5 points, and near-miss requests never fired a skill. The post A Session-Start Ho...

Read source
rubyflow.com /1 month ago

Ruby implementation of scrap: scrap4rb

While searching for quality I found scrap. SCRAP is by Robert C. Martin (Uncle Bob): github.com/unclebob/scrap. The algorithm, the metrics, the smells and the policy numbers in scr...

Read source
testmuai.com /1 month ago

Ragas Metrics Explained: Every Metric, Score and Version

Ragas metrics explained: every current Ragas evaluation metric, which ones need an LLM, three formulas worked by hand, and the names that changed by version.

Read source
kaizo.com /2 weeks ago

Multilingual QA: Score Support in Every Language You Offer

Multilingual QA for support teams: which criteria change by language, how to calibrate across languages, and how to score every language with a small QA team.

Read source
dev.to /2 weeks ago

How to combine Claude Code review with SonarQube verification

A few months ago, a thread in r/ClaudeCode asked a question that I suspect plenty of people have muttered at their terminal: is /code-review a big waste of tokens? /code-review is...

Read source
testmuai.com /1 month ago

OpenAI GDPval Benchmark: Tasks, Grading, Scores and Limits

OpenAI GDPval tests AI on 1,320 real work tasks from 44 occupations. See what the 220 open tasks hold, how experts grade them, and why GDPval-AA scores differ.

Read source
towardsdatascience.com /3 weeks ago

Claude Code vs. Cursor: What a Field Test Shows That the Feature Comparisons Miss

One benchmark says Claude Code used 33,000 tokens where Cursor used 188,000. Another says the exact reverse. Here is the field test that actually settles it for your team. The post...

Read source
machinelearningmastery.com /1 week ago

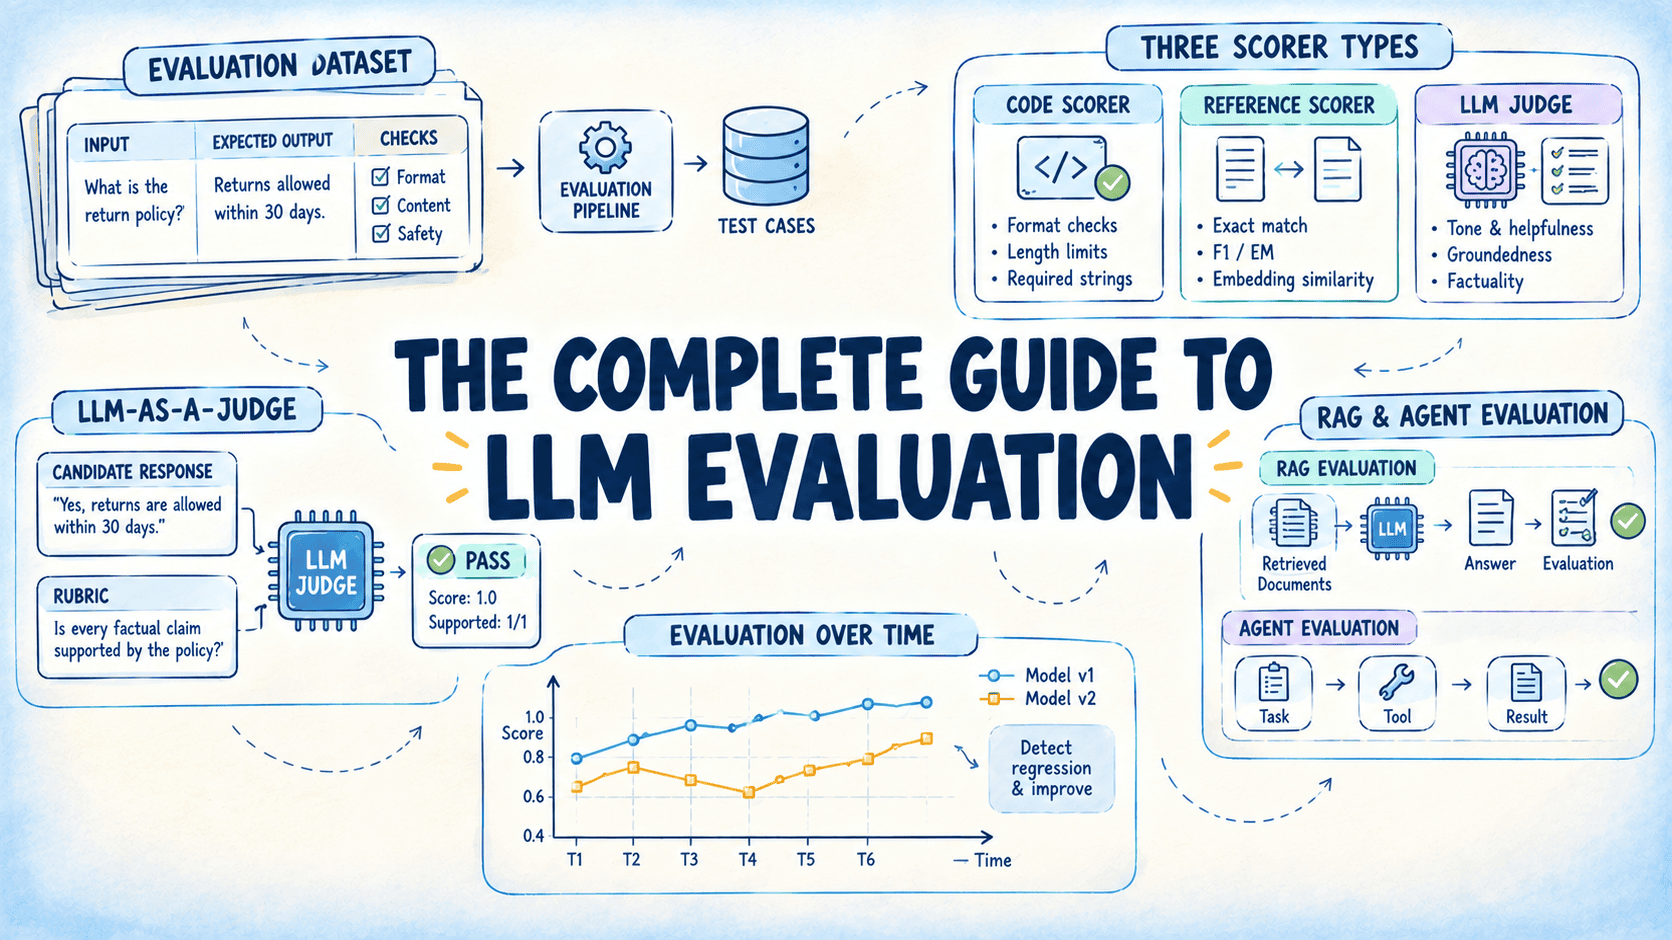
The Complete Guide to LLM Evaluation

In this article, you will learn how to evaluate LLM applications systematically, from choosing scorers and designing reliable LLM judges to evaluating RAG systems and...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.