The wrong setting for AI cache can cost you a lot of cash
Beware of the temptation to drop just a few more dollars to get the work done
Intel, AMD, and Arm each made agentic AI announcements this week at OCP 2026, covering rack processor units, rack architecture, and benchmarking
«AI-агент» упоминают в 1 458 вакансиях на hh.ru, а «кэширование промптов» только в 13. Хотя именно кэш и токены решают, сколько стоит агент.Разбираю по порядку 14 слов из вакансий:...
AI is shifting from training to inference, and two pressures now define the business: the end-user experience and the return on investment. RCR’s AI Infrastructure Forum returns to...
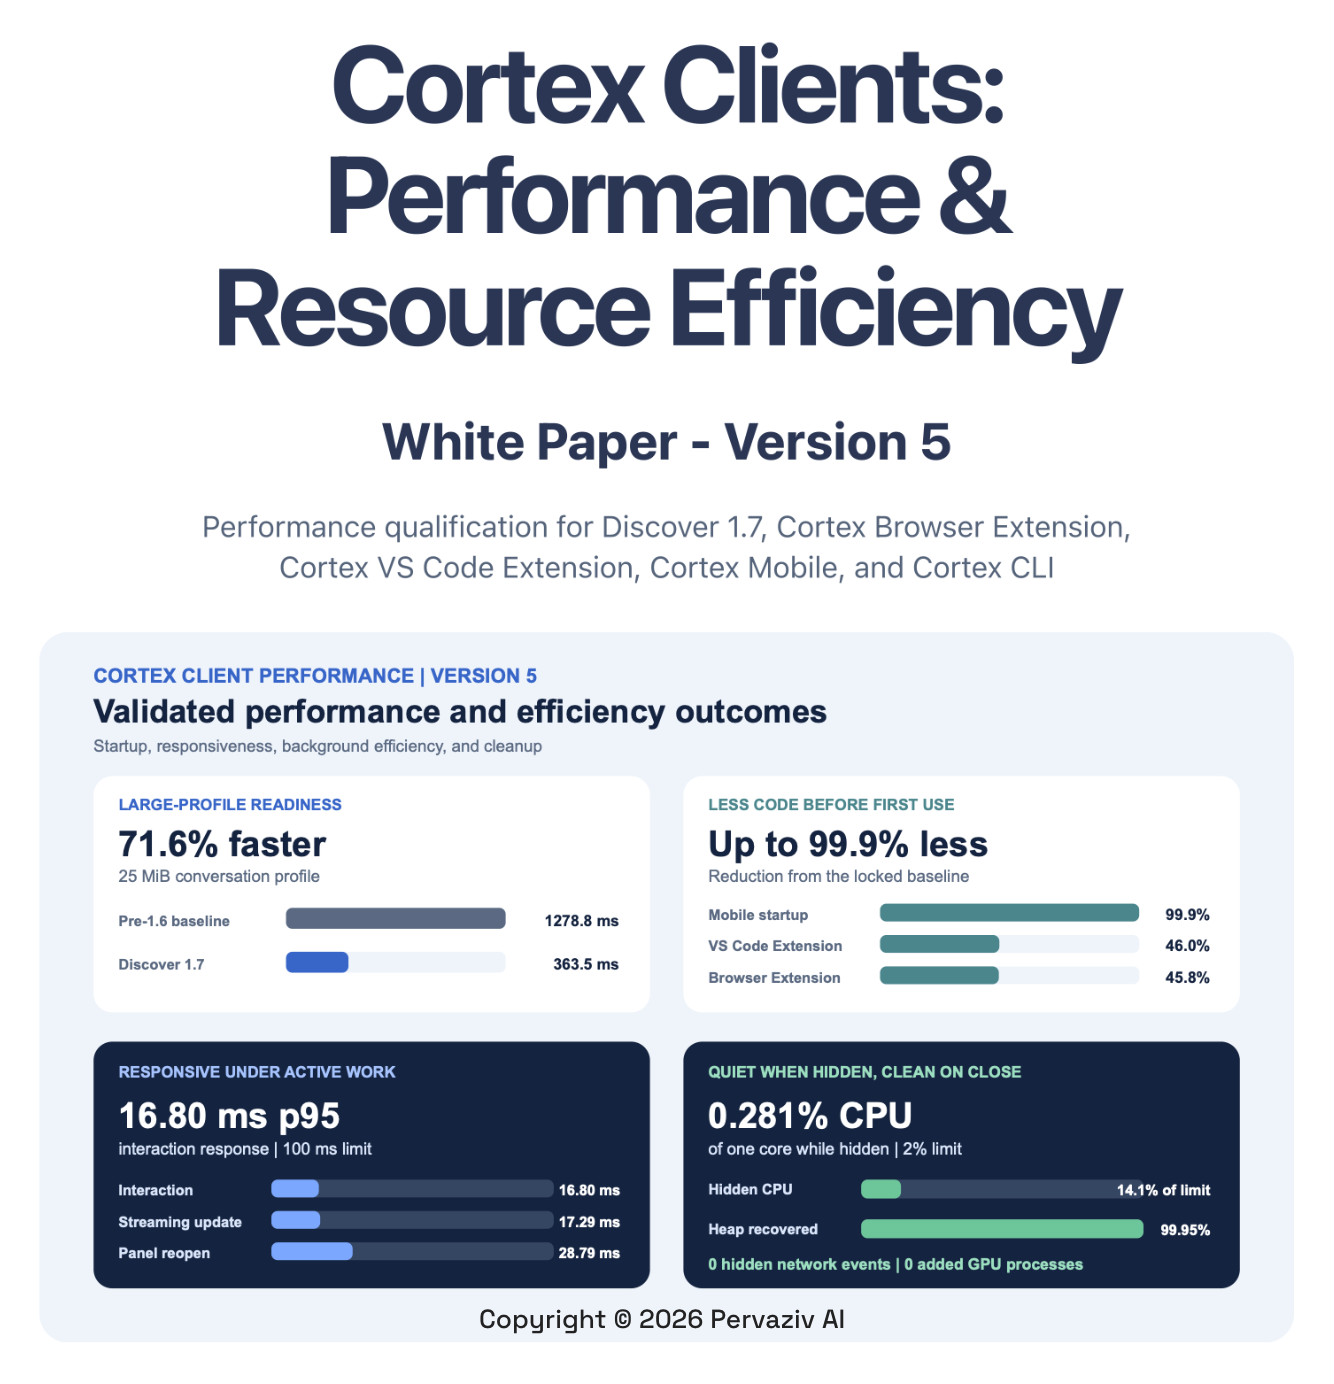
New performance release accelerates large workspace recovery by 71.6%, cuts first-use code by up to 99.9%, and quiets background activity across the Cortex experience. The post Per...
AAI is taking its advanced agency analytics further, using artificial intelligence to turn data into clearer insights for agency owners. WESTMINSTER, Colo., October 19, 2026: Affor...
Monitoring, Reliability and AI Operations Anonymous (not verified) Wed, 10/14/2026 - 17:44 AIS402 402 AIS AIS402 Monitoring, Reliability and AI...
Rapid software advancements in AI models can significantly alter capacity planning and cost structures, impacting scalability strategies. The post DeepSeek V4.1 Flash hits 848 toke...
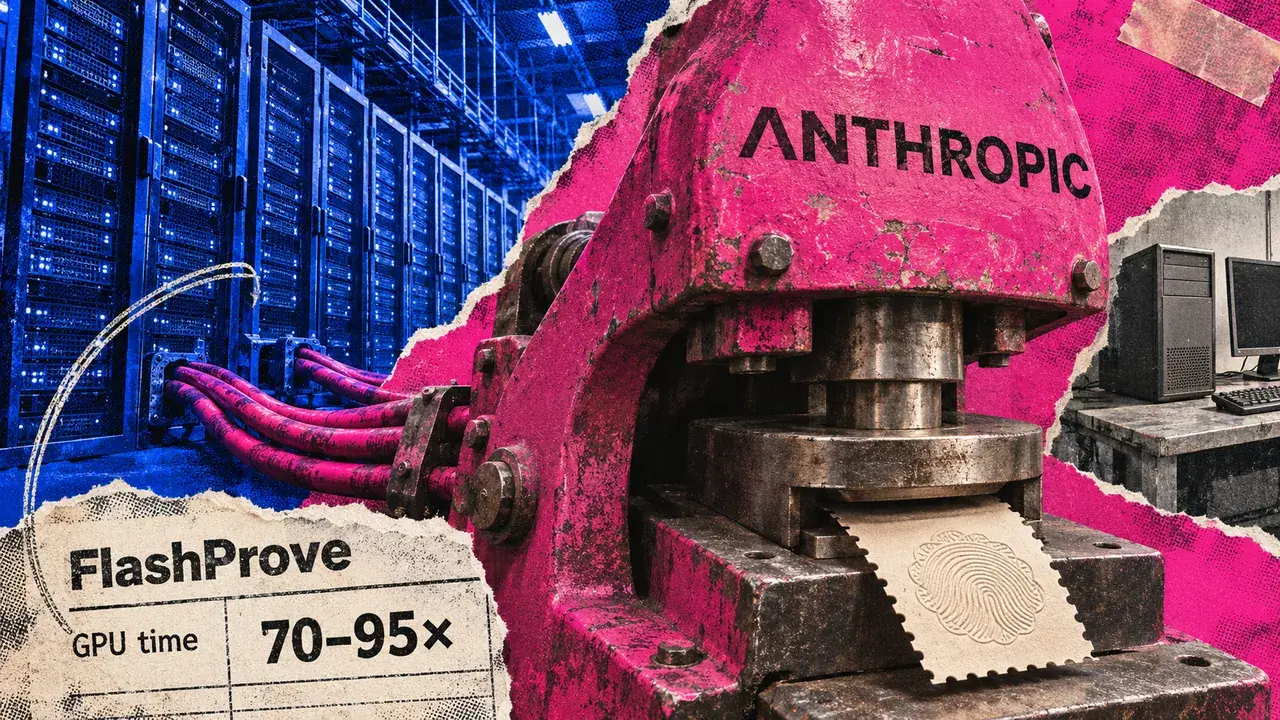
FlashProve could help verify model computation, but its benchmark takes roughly 70 to 95 times the GPU work of ordinary inference. Read the full story on CryptoSlateUnderstand the...
Last quarter a team I worked with proudly turned on a semantic cache in front of their support-drafting agent. The dashboard said 38% hit…Continue reading on Medium »
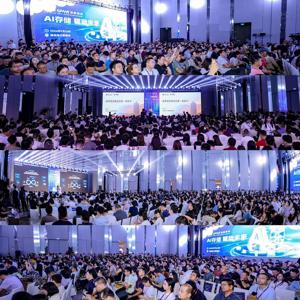
SHENZHEN, China, Oct. 18, 2026 /PRNewswire/ -- The 5th GMIF Innovation Summit (Global Memory Innovation Forum 2026, GMIF2026) recently concluded at the Renaissance Shenzhen Bay Hot...
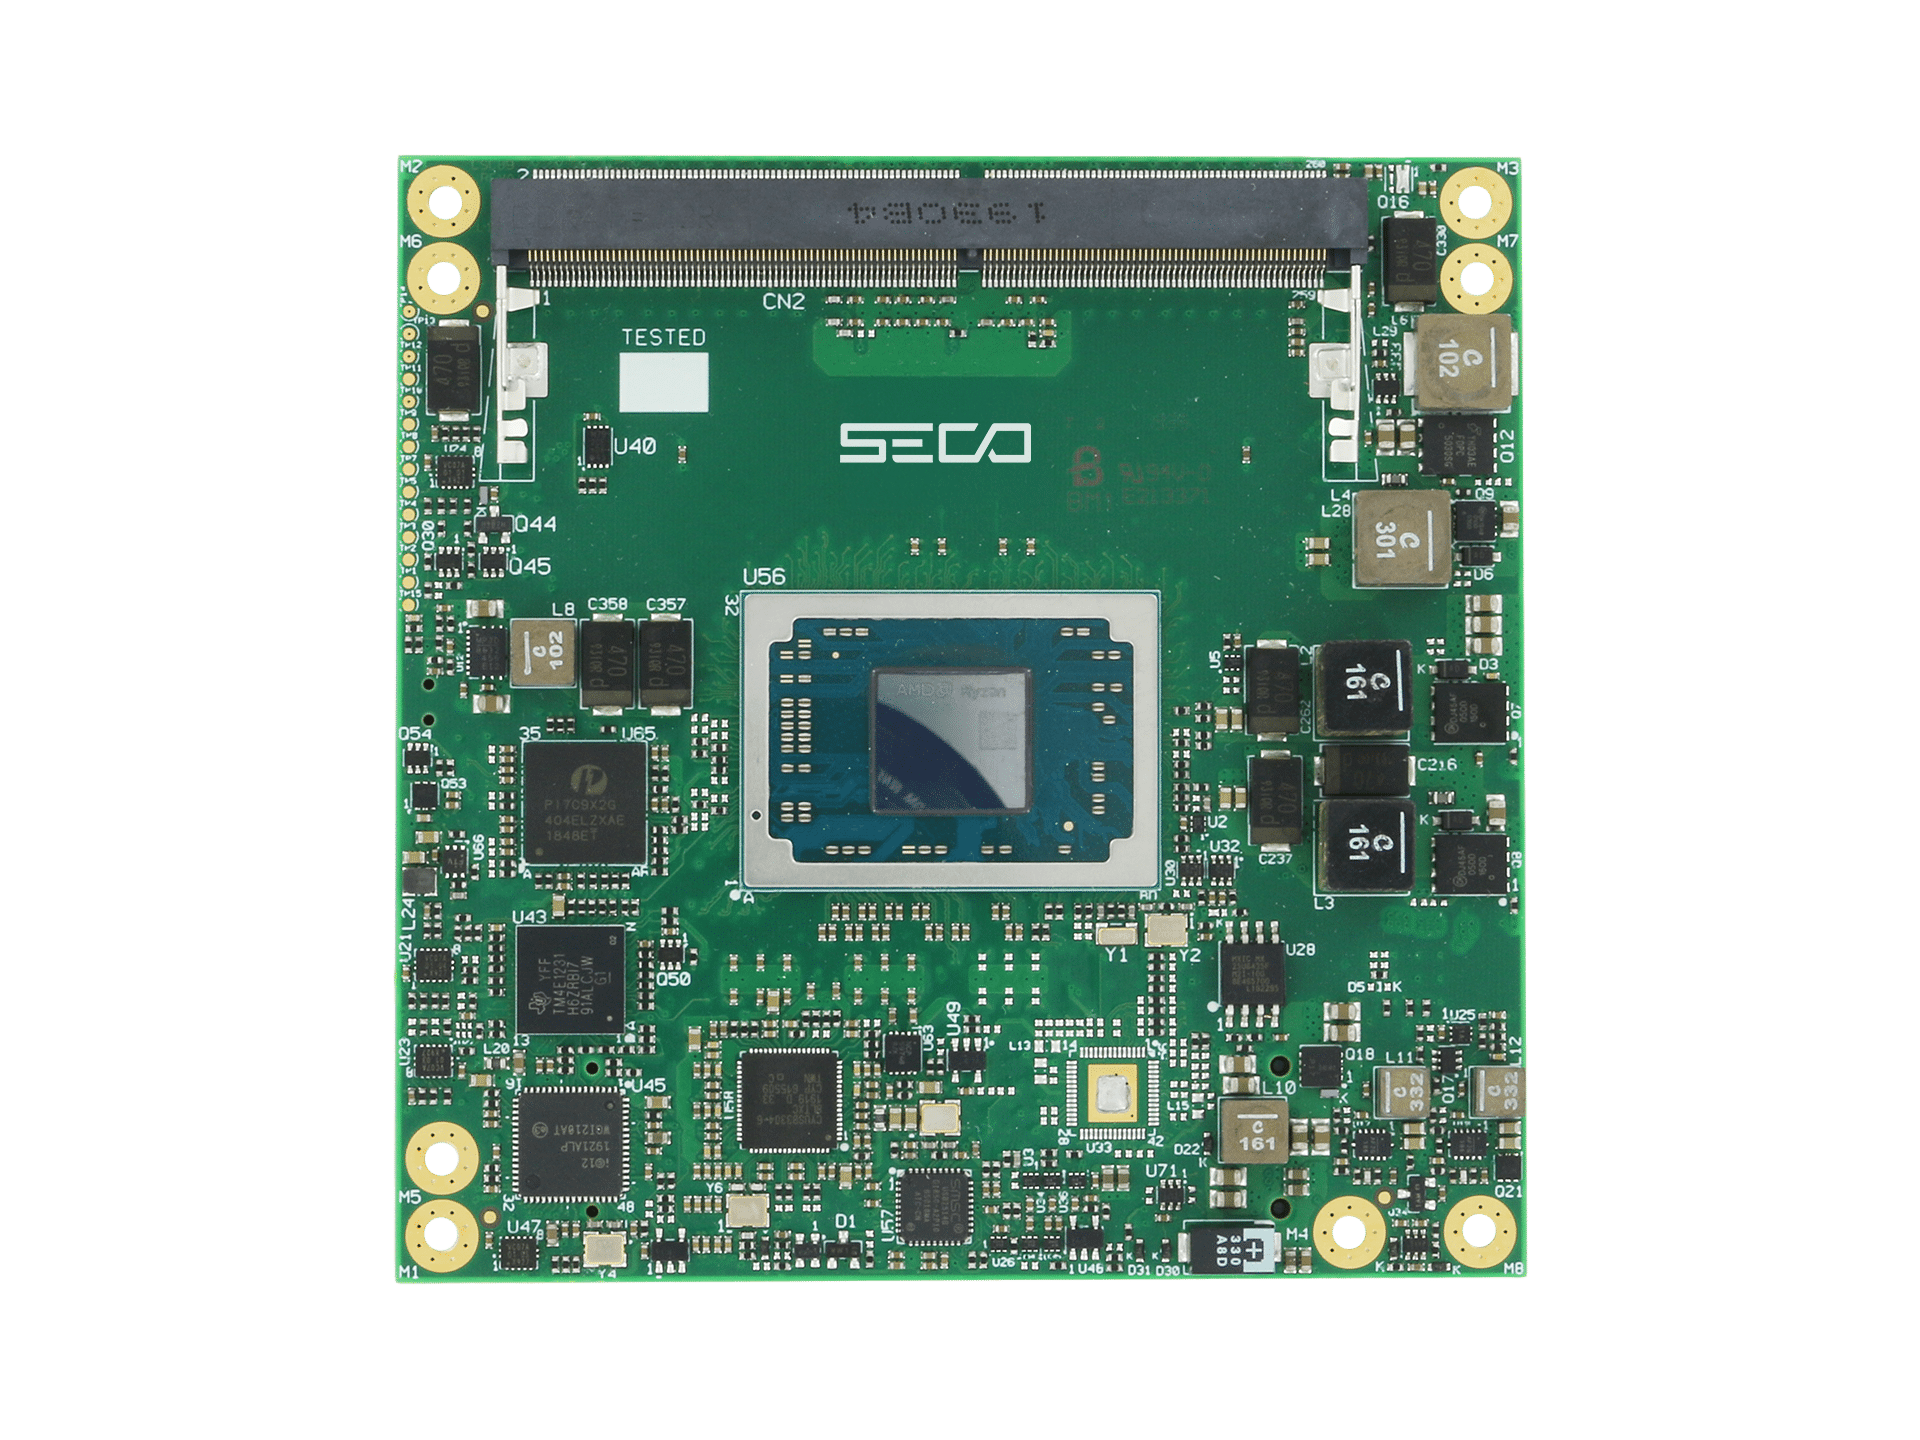
A compact computing module combines processing, graphics and AI capabilities for industrial applications. SECO has launched the SOM-COMe-CT6-R8000, its COM Express 3.1 Type 6 Compa...
PARTNER CONTENT: HPE Alletra MP X10000 cache offload delivers up to 20× faster time to first token in testing validated by Kamiwaza. Apparently, remembering things beats calculatin...
At CIIF 2026, Axera launched the 6nm AX8860 for on-site large-model inference, with AXLink cascading, PCIe 5.0 and a vLLM/SGLang-friendly toolchain.
Chinese artificial intelligence chipmaker Iluvatar CoreX claims that its new Tiangai 300 graphics processing unit (GPU) can match and even surpass Nvidia’s H200 in real-world AI wo...
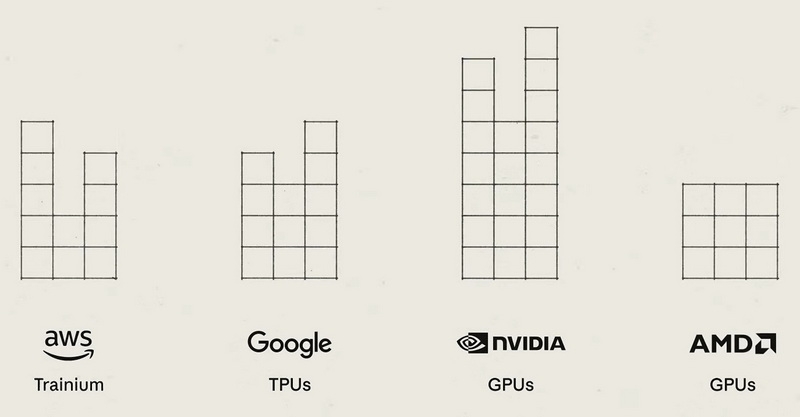
Anthropic заявила, что избавилась от зависимости от аппаратного обеспечения Nvidia благодаря стратегии использования различных типов чипов. По словам компании, ей удалось перенести...
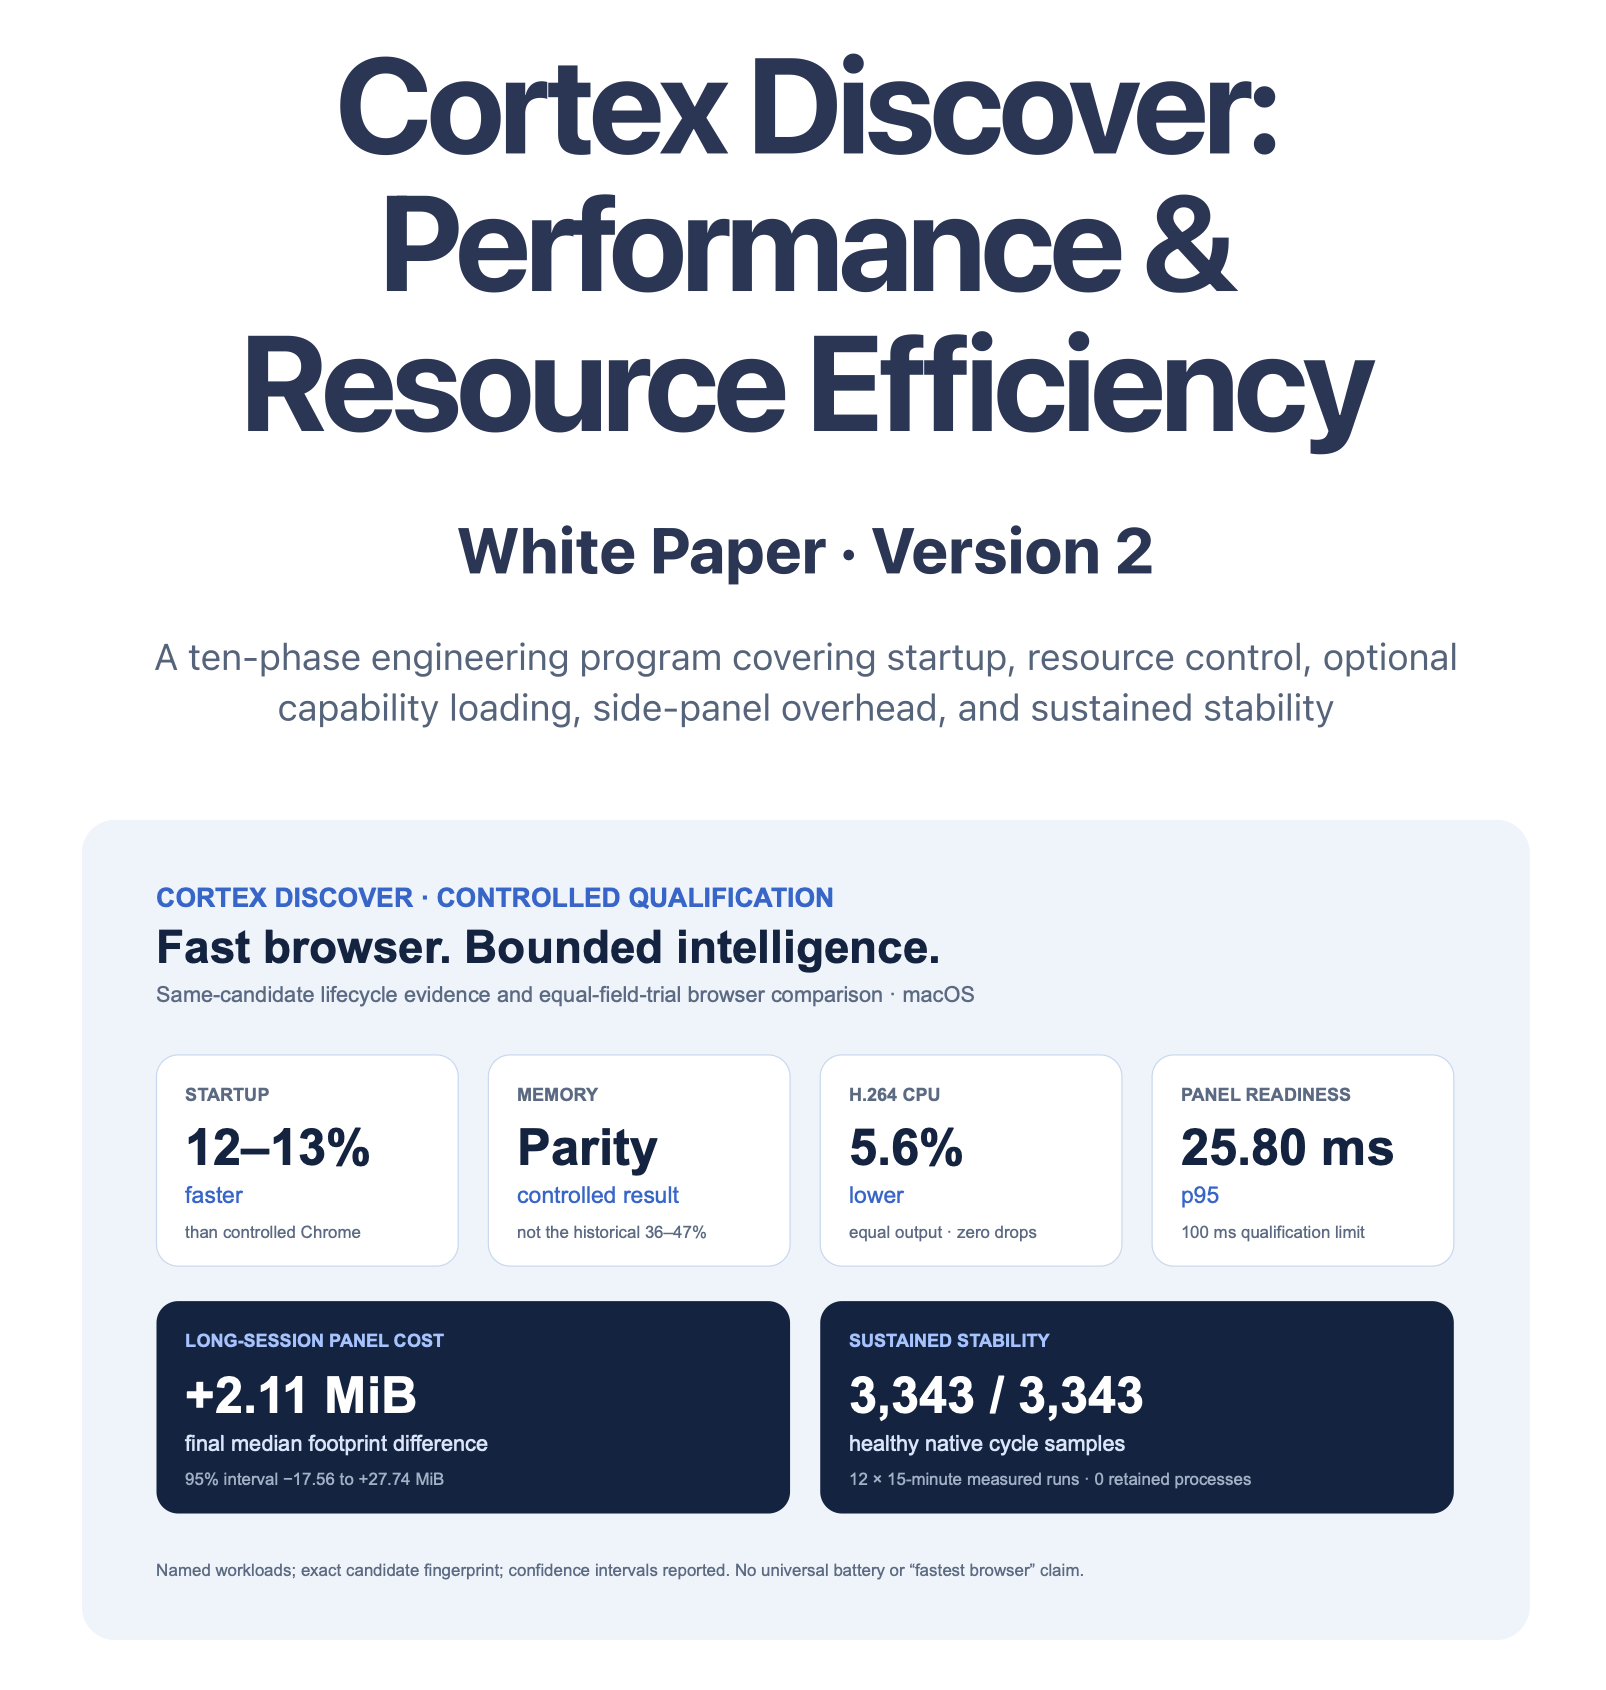
New results show 13% faster startup, memory near parity, 5.6% lower H.264 CPU, 25.8 ms AI panel readiness and zero retained processes in sustained testing. The post Pervaziv AI Upd...
An AI agent and digital certificate inventory is a record of every AI agent and digital certificate an organization runs, with what each one does, who owns it, what it connects to...
<figure data-wp-context="{&quot;imageId&quot;:&quot;6afea4dd5ea19&quot;}" data-wp-interactive="core/image" data-wp-key="6afea4dd5ea19&qu...
Avalue Expands AI Computing Portfolio From data center infrastructure to intelligent edge applications Mark Hembree Thu, 10/15/2026 - 12:02 Off...
Tsinghua researchers released AKV, an SGLang-based serving system for cache engineering. LLM agents drop and reposition KV cache instead of summarizing history, cutting average cos...
USD.AI’s published terms put recovery with lenders and agents, while sUSDai withdrawals depend on cash across monthly epochs. Read the full story on CryptoSlateUnderstand the crypt...
Integrating GPU, DRAM, and SSD Resources to Accelerate Enterprise AI Inference and Deployment
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.