From weeks to minutes: The new agentic era of data pipelines
Data pipelines are the backbone of the modern enterprise, yet a barrier to entry exists for orchestrating them, making this critical capability unavailable to many data professiona...
Search fresh public links, source activity, and ready-to-use post angles for Datapipeline.
Fresh curated links around datapipeline are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Data pipelines are the backbone of the modern enterprise, yet a barrier to entry exists for orchestrating them, making this critical capability unavailable to many data professiona...
Pipeline setup {pipeflow} builds a pipeline by adding one R function per step with pip_add (see also the Get started article). In this post, we’ll work with the following toy pipel...
Pipelines distribuidos y desacoplados: Registro remoto de workers en wpipe Construir pipelines de datos que escalen en múltiples servidores o contenedores efímeros suele generar...
AWS Glue 6.0 introduces Spark Declarative Pipelines. In this post, you build a single declarative AWS Glue 6.0 job that turns raw order records into validated, aggregated tables th...
With AWS Glue 6.0, you can build real-time, near-real-time, and batch data pipelines on a single platform. Using a financial market-risk example, learn how to flag high-risk trades...
Feeding the OLAP beast: ClickHouse massive bulk ingestion steps. ClickHouse is a columnar beast, but treating it like MySQL by inserting row-by-row will bring your cluster to its...
Learn how to set up Amazon Redshift Data Sharing between a producer and consumer cluster and use dbt Cloud to transform the shared data into analytics-ready models, with live, zero...
Operating large data pipelines requires an orchestration layer that scales smoothly as workloads expand. When your pipelines process millions of complex data points every day to fe...
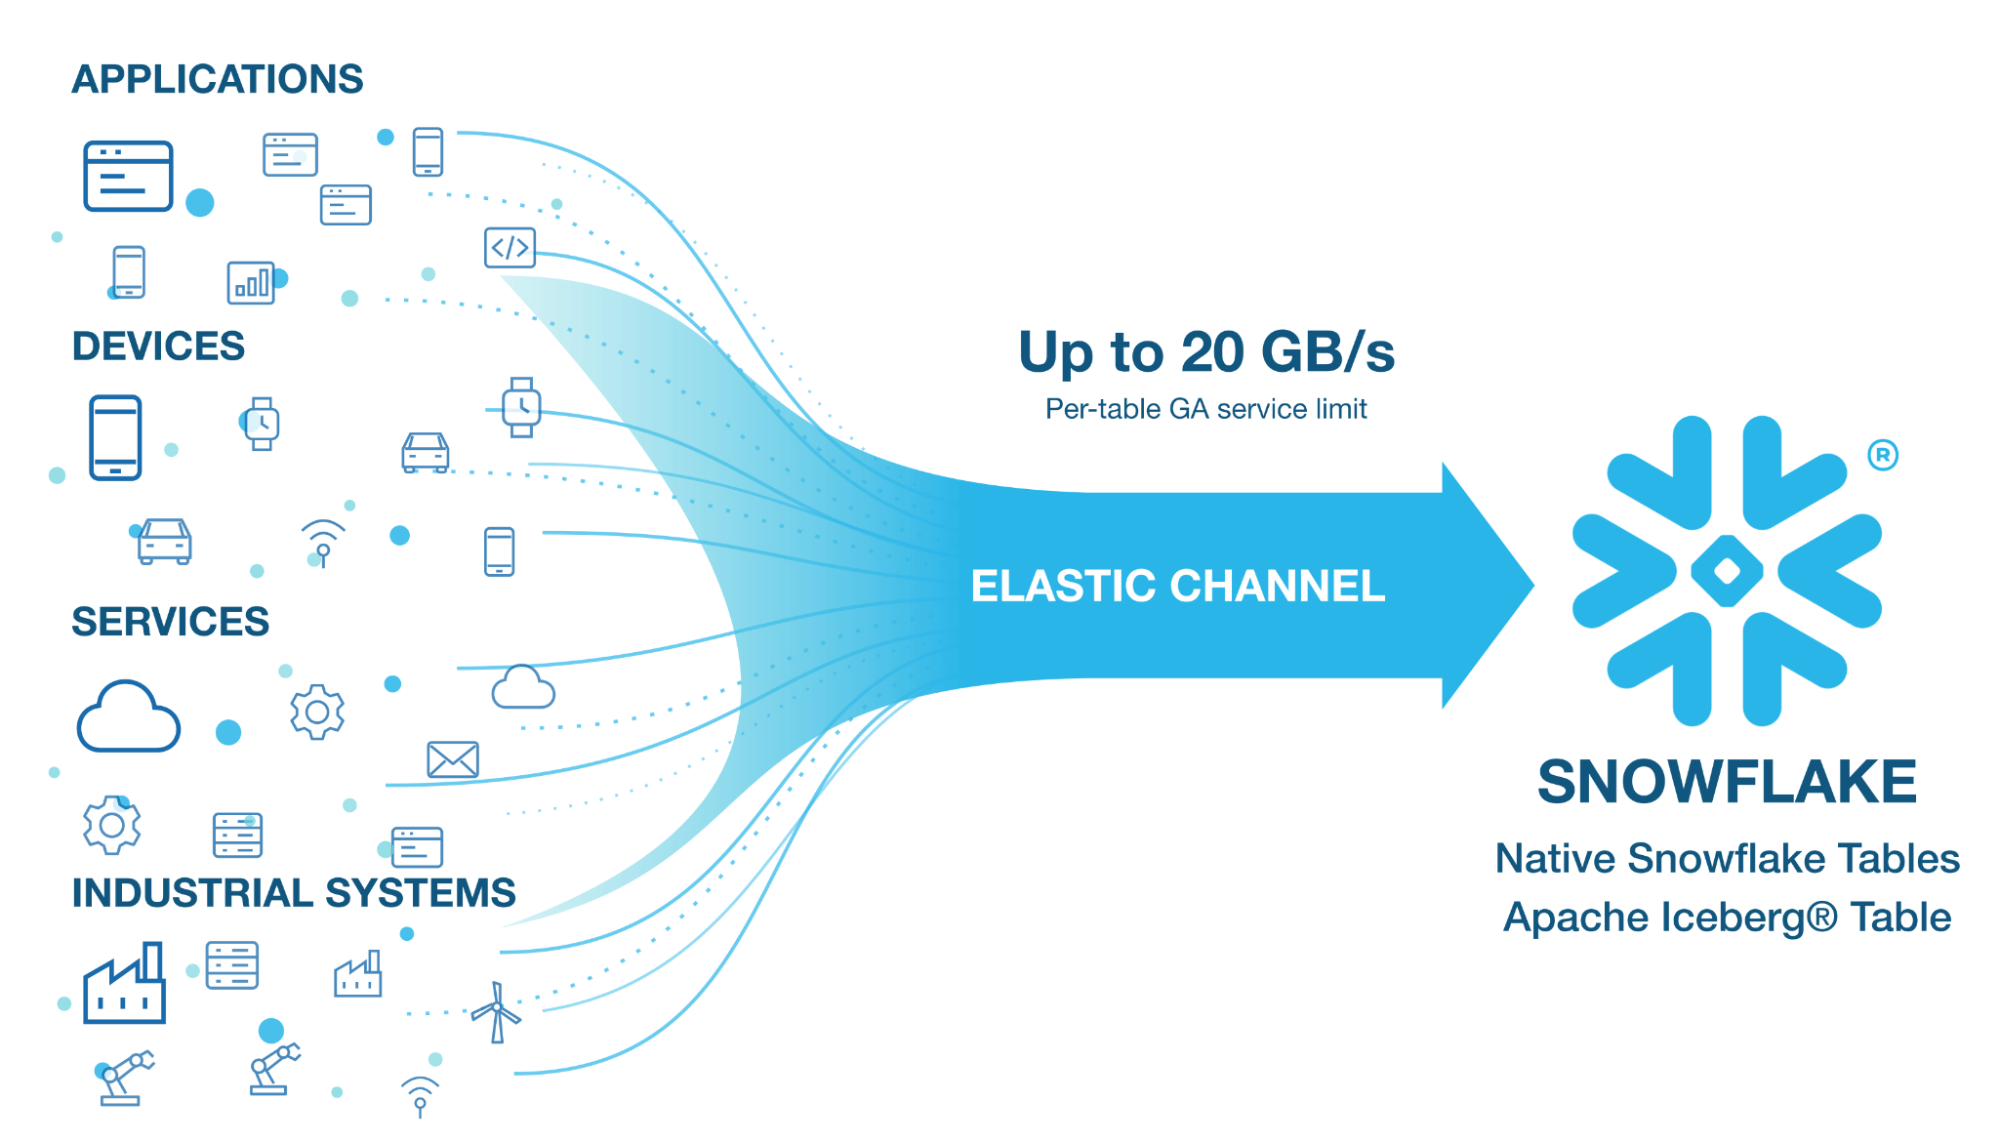
Snowpipe Streaming Elastic Channels and durable acknowledgments are now generally available — stream data directly from any producer into Snowflake.
How we automated the migration of 500+ orchestration activities across 37 data factories — with zero manual JSON editing Target audience: Data engineers migrating Azure… The post...
About a year ago, I was building a terminal-based workflow manager called Glyph.Flow. It was mostly a learning project. I wanted to understand Python better, experiment with Textu...
Building an incremental pipeline with dbt snapshots, and the API that quietly lied to me along the way. The post I Built a Pipeline to Track the Job Market I'm Trying to Break Into...
Troubleshooting a multi-service, MWAA-orchestrated ETL pipeline often means hunting across scattered Amazon CloudWatch log groups. This post shows how to centralize your ETL logs i...
How we split a tightly coupled Python pipeline into independently deployable services The post When One Process Becomes Too Much: Splitting a Pipeline into MCP Services appeared fi...
Amazon Aurora PostgreSQL zero-ETL integration with Amazon SageMaker replicates your operational data to a lakehouse in near real time, without building custom ETL pipelines. Learn...
If your business runs on Stripe, your application needs access to Stripe data at...
Snowflake's data team built an AI agent that diagnoses monitored pipeline failure and opens a proposed fix in under 16 minutes. Here's how.
Agentic data engineering uses AI agents to build, repair, and optimize data pipelines. Learn how it works, its limitations, and the skills engineers need.
AI agents now write a growing share of production data pipelines (over 70% of SDP...
Learn how to build a dynamic streaming data lake on Amazon Managed Service for Apache Flink that adapts to new event types and schema changes without stopping the pipeline, using A...
A few years back, I sat through a production incident review where the root cause turned out to be a single stored procedure nobody on the team had touched in four years. The origi...
Learn how to pair DuckDB with AWS Glue 6.0 to run SQL-centric ETL on a single worker, reading Parquet from Amazon S3 and writing Apache Iceberg tables to Amazon S3 Tables. This pos...
Data engineers managing batch SQL pipelines on Snowflake, BigQuery, and increasingly Databricks, and streaming pipelines on Apache Flink face a familiar problem: two toolchains, tw...
Snowflake benchmarked Elastic Channels for Snowpipe Streaming at 41 GB/s and 133M rows/sec on a single table — 3.5x faster with linear horizontal scaling.
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.