Snowflakeを使用したApache Icebergへのデータのストリーミング
Snowpipe Streamingを使用して、SnowflakeマネージドのApache Icebergテーブルにデータを簡単にストリーミングする方法をご紹介します。
Search fresh public links, source activity, and ready-to-use post angles for Apache Iceberg.
Fresh curated links around apache iceberg are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Snowpipe Streamingを使用して、SnowflakeマネージドのApache Icebergテーブルにデータを簡単にストリーミングする方法をご紹介します。
В феврале этого года проект с красивым именем Polaris незаметно стал полноценным проектом фонда Apache. Новость прошла как-то мимо, ну стал и стал, мало ли. Между тем это одна из т...
Discover how to easily stream data into Snowflake-managed Apache Iceberg tables using Snowpipe Streaming.
Learn how to build a dynamic streaming data lake on Amazon Managed Service for Apache Flink that adapts to new event types and schema changes without stopping the pipeline, using A...
Спор о формате таблиц для lakehouse, похоже, закончился, Iceberg сегодня поддерживают Trino, Spark, ClickHouse, Snowflake и дальше по списку, так что следующим приходится выбирать...
The data lakehouse has become the default architecture for analytics on AWS in 2026. It combines the best of both worlds: the low-cost, schema-flexible storage of a data lake (S3)...
Learn how to query Amazon S3 Tables from Trino on Amazon EMR using the Apache Iceberg REST catalog endpoint. This post shows how to deploy the integration with AWS CloudFormation,...
AWS Aurora PostgreSQL now queries Iceberg and Parquet data in S3 without ETL, using DuckDB and familiar SQL. See versions, setup, limits, and costs. The post AWS Aurora PostgreSQL...
Open table formats are metadata layers that sit on top of data files in object storage, adding ACID transactions...
As customers modernize to lakehouse architectures, they are standardizing on open formats such as Apache Iceberg to create a shared data estate across compatible engines. This enab...
Benchmarking the impact of fewer, larger files across three SQL workloads The post I Compacted 1,000 Apache Iceberg Files Into 6. Here’s What Happened to Query Performance. appeare...
Razor Group, one of Europe's leading ecommerce aggregators managing 250+ brands, migrated from always-on Amazon Redshift clusters to an open lakehouse on Apache Iceberg, Amazon S3...
Amazon Kinesis Data Streams now supports streaming tables, a fully managed capability that continuously delivers your streaming data as queryable Apache Iceberg tables on Amazon S3...
Accelerate slow, repetitive Apache Spark analytical queries on Apache Iceberg tables without rewriting any SQL. This post shows how automatic query rewrite in Amazon EMR and AWS Gl...
AWS Glue 6.0 with Apache Spark 4.1 adds support for Apache Iceberg v3: native geospatial types, nanosecond-precision timestamps, the VARIANT type, and DEFAULT column values. This p...
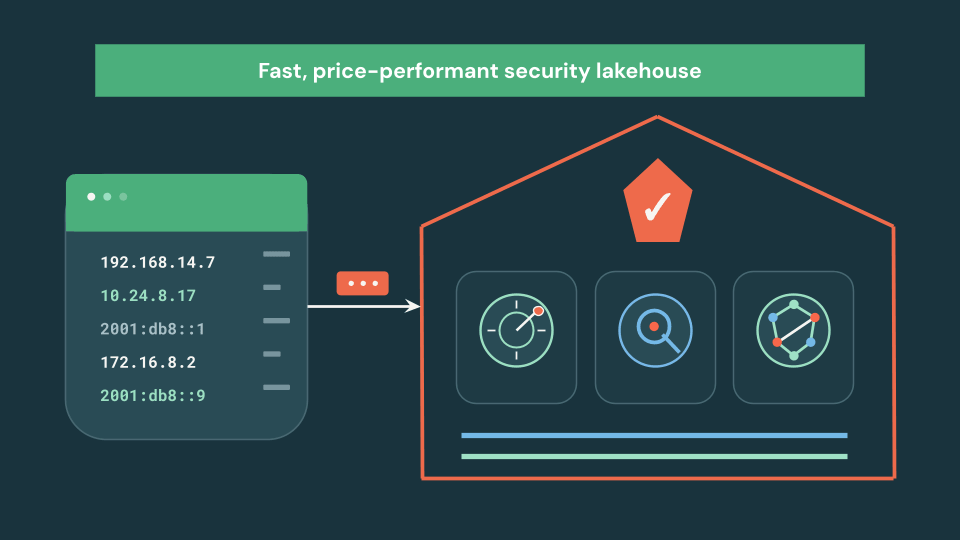
IP data is warehousing dataEvery firewall, load balancer, VPN, CDN edge, DNS resolver,...
Amazon Redshift now supports evolving Apache Iceberg table schemas and partition layouts through ALTER statements, with no data rewrites or pipeline rebuilds. In this final post of...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.