Latest updates for Transformer Model

Fresh curated links around Transformer Model are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • The Transformer’s Footprints II
  • Attention Is All You Need — The Birth of Transformers
  • How LLMs Work: Transformer Architecture Explained | Simplilearn

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

optimustechnica.medium.com /1 month ago

The Transformer’s Footprints II

бЂ•бЂјбЂ®бЂёбЂЃбЂІбЂ·бЂђбЂІбЂ· post бЂ™бЂѕбЂ¬бЂ†бЂ­бЂЇбЂ›бЂ„бЂє hidden state бЂђбЂЅбЂ±бЂЎбЂЂбЂјбЂ±бЂ¬бЂ„бЂєбЂёбЂЂбЂ­бЂЇ бЂ›бЂѕбЂ„бЂєбЂёбЂ•бЂјбЂЃбЂІбЂ·бЂ•бЂјбЂ®бЂёбЂ–бЂјбЂ…бЂєбЂђбЂІ...

Read source
medium.com /4 weeks ago

Attention Is All You Need — The Birth of Transformers

If you have followed this series from the beginning, you’ve probably noticed a pattern. Every major breakthrough in deep learning solved…Continue reading on Medium »

Read source
simplilearn.com /1 month ago

How LLMs Work: Transformer Architecture Explained | Simplilearn

TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...

Read source
dramarnathgiri.blogspot.com /2 weeks ago

TRANSFORMER MAIN COMPONENTS

 вљЎ TRANSFORMER MAIN COMPONENTS рџ”Њрџ›ЎпёЏA transformer transfers electrical energy between circuits through electromagnetic induction, changing voltage levels w...

Read source
medium.com /2 weeks ago

Why Can’t Transformers Just Rearrange Their Matrix Multiplications?

Linear attention unlocks a matrix multiplication trick that standard attention can't use, but the speedup comes at a cost.Continue reading on Medium »

Read source
towardsdatascience.com /4 weeks ago

Your LLM Has a Curved Space of Paragraphs

Inside a transformer, token index is a coordinate. Paragraph structure is what turns it into a metric. The post Your LLM Has a Curved Space of Paragraphs appeared first on Towards...

Read source
towardsdatascience.com /1 month ago

Why Transformers Need Positional Encoding For Time Series: A Visual Guide

From scalar observations to self-attention, and how positional information restores sequence order The post Why Transformers Need Positional Encoding For Time Series: A Visual Guid...

Read source
medium.com /1 month ago

Why Transformers Scale: The Math of Scaling Laws

Power laws, log-log plots, and what they predict about the future of AIContinue reading on Medium »

Read source
bioengineer.org /2 weeks ago

New Transformer Splits Static Roads From Dynamic Traffic to Sharper Forecasts

A new decoupled graph-augmented transformer architecture separates static road topology from dynamic traffic patterns to reduce optimization interference and achieve state-of-the-a...

Read source
dramarnathgiri.blogspot.com /1 day ago

Transformer Troubleshooting Guide

Transformer Troubleshooting GuideCommon Transformer Problems, Causes & SolutionsA transformer is a critical electrical component used to transfer electrical energy between circ...

Read source
computerweekly.com /1 month ago

Transformers: More than meets the eye in datacentre grid connection

As hyperscale AI data centres scale up to handle intense workloads, advanced super-grid transformers are emerging as the hidden linchpin for resilient, sustainable capacity

Read source
marktechpost.com /1 month ago

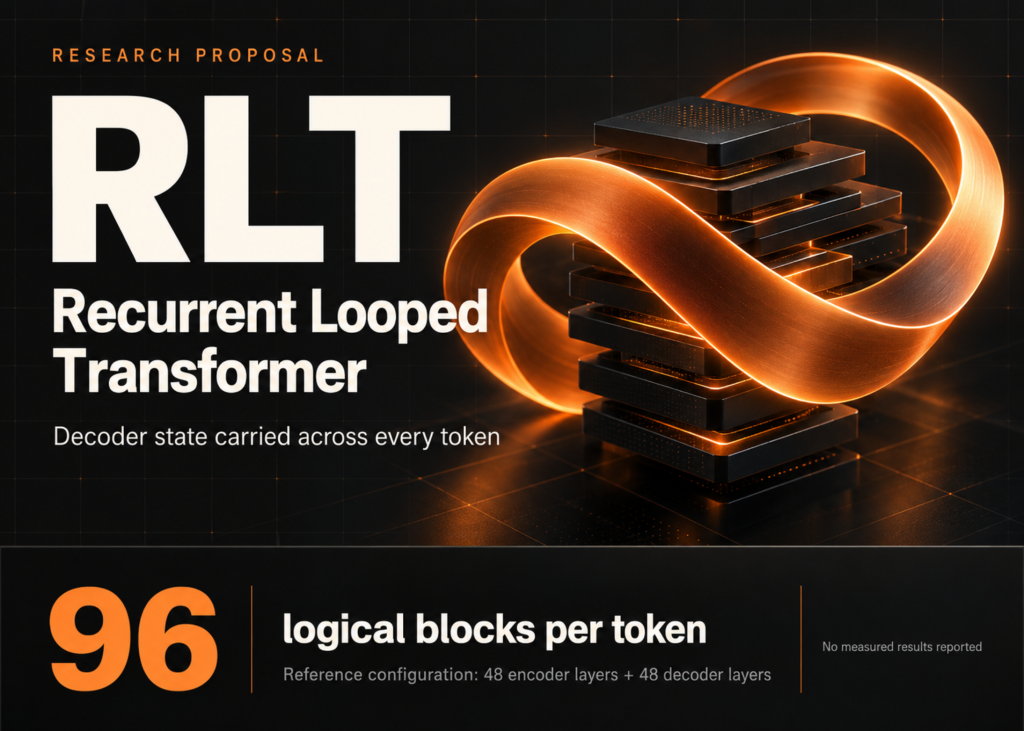
A Princeton Researcher Proposes Recurrent Looped Transformer (RLT) that Carries Decoder State across Every Token, Fixing...

Yifan Zhang's Recurrent Looped Transformer (RLT) technical report proposes a causal encoder paired with a recurrent decoder that carries its final hidden state and layerwise slidin...

Read source
medium.com /1 month ago

Inside the Transformer Stack: How AI Actually Reads Your Words

Part of the “35 AI Concepts Every Data & AI Professional Should Know” series — Decoding Data ScienceContinue reading on Medium »

Read source
medium.com /1 week ago

Understanding Large Language Models (LLMs)

The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »

Read source
dev.to /1 month ago

# Beyond Transformers: A Mathematical Critique of Cross-Lingual Diffusion Architectures

Beyond Transformers: A Mathematical Critique of Cross-Lingual Diffusion Architectures The current state of multilingual NLP is dominated by transformer-based architectures that o...

Read source
dramarnathgiri.blogspot.com /2 weeks ago

🔌 TRANSFORMER TESTING — HOW DO WE CHECK A TRANSFORMER

 ⚡🔌 TRANSFORMER TESTING — HOW DO WE CHECK A TRANSFORMER?Before energizing a transformer, testing helps verify its electrical performance, insulation condition, winding inte...

Read source
medium.com /1 week ago

Building a Small GPT from Scratch

Code: https://github.com/AyanMoeen/AI-Engineering-Assignment-1 Live API: https://ai-engineering-assignment-1-production.up.railway.app/docs…Continue reading on Medium »

Read source
thefinanser.com /1 month ago

Huawei’s Transform Magazine starring …

I asked AI to summarise the latest edition of Huawei’s financial magazine called Transform, and this is what it came back with. I think AI is not objective … Transform Issue 27: Ba...

Read source
seanfalconer.medium.com /1 month ago

How Time Series Foundation Models Work

Time series foundation models bring the LLM playbook to forecasting. Pretrain once on diverse series, then forecast new ones zero-shot.Continue reading on Medium »

Read source
aws.amazon.com /3 days ago

Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch

Learn how i14 trained and served Laplace 3B, a linear attention model, on AWS Trainium2 using native PyTorch. Its recurrent state stays fixed at 29.5 MB per sequence regardless of...

Read source
habr.com /1 month ago

Где счетный бейзлайн бьет трансформер: честное сравнение на русских отзывах

Когда нужно классифицировать текст, дефолтный ход в 2026 – взять предобученный трансформер и дообучить. TF-IDF воспринимается как музейный экспонат: работал в эпоху до BERT, сейчас...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Transformer Model

dramarnathgiri.blogspot.com

Recent coverage from public sources
Public source

computerweekly.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

bioengineer.org

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source