The Transformer’s Footprints II
бЂ•бЂјбЂ®бЂёбЂЃбЂІбЂ·бЂђбЂІбЂ· post бЂ™бЂѕбЂ¬бЂ†бЂбЂЇбЂ›бЂ„бЂє hidden state бЂђбЂЅбЂ±бЂЎбЂЂбЂјбЂ±бЂ¬бЂ„бЂєбЂёбЂЂбЂбЂЇ бЂ›бЂѕбЂ„бЂєбЂёбЂ•бЂјбЂЃбЂІбЂ·бЂ•бЂјбЂ®бЂёбЂ–бЂјбЂ…бЂєбЂђбЂІ...
Search fresh public links, source activity, and ready-to-use post angles for Transformer Architecture.
Fresh curated links around Transformer Architecture are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
бЂ•бЂјбЂ®бЂёбЂЃбЂІбЂ·бЂђбЂІбЂ· post бЂ™бЂѕбЂ¬бЂ†бЂбЂЇбЂ›бЂ„бЂє hidden state бЂђбЂЅбЂ±бЂЎбЂЂбЂјбЂ±бЂ¬бЂ„бЂєбЂёбЂЂбЂбЂЇ бЂ›бЂѕбЂ„бЂєбЂёбЂ•бЂјбЂЃбЂІбЂ·бЂ•бЂјбЂ®бЂёбЂ–бЂјбЂ…бЂєбЂђбЂІ...
If you have followed this series from the beginning, you’ve probably noticed a pattern. Every major breakthrough in deep learning solved…Continue reading on Medium »
TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...
Linear attention unlocks a matrix multiplication trick that standard attention can't use, but the speedup comes at a cost.Continue reading on Medium »
Part of the “35 AI Concepts Every Data & AI Professional Should Know” series — Decoding Data ScienceContinue reading on Medium »
From scalar observations to self-attention, and how positional information restores sequence order The post Why Transformers Need Positional Encoding For Time Series: A Visual Guid...
Learn how i14 trained and served Laplace 3B, a linear attention model, on AWS Trainium2 using native PyTorch. Its recurrent state stays fixed at 29.5 MB per sequence regardless of...
Inside a transformer, token index is a coordinate. Paragraph structure is what turns it into a metric. The post Your LLM Has a Curved Space of Paragraphs appeared first on Towards...
Beyond Transformers: A Mathematical Critique of Cross-Lingual Diffusion Architectures The current state of multilingual NLP is dominated by transformer-based architectures that o...
A new decoupled graph-augmented transformer architecture separates static road topology from dynamic traffic patterns to reduce optimization interference and achieve state-of-the-a...
The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »
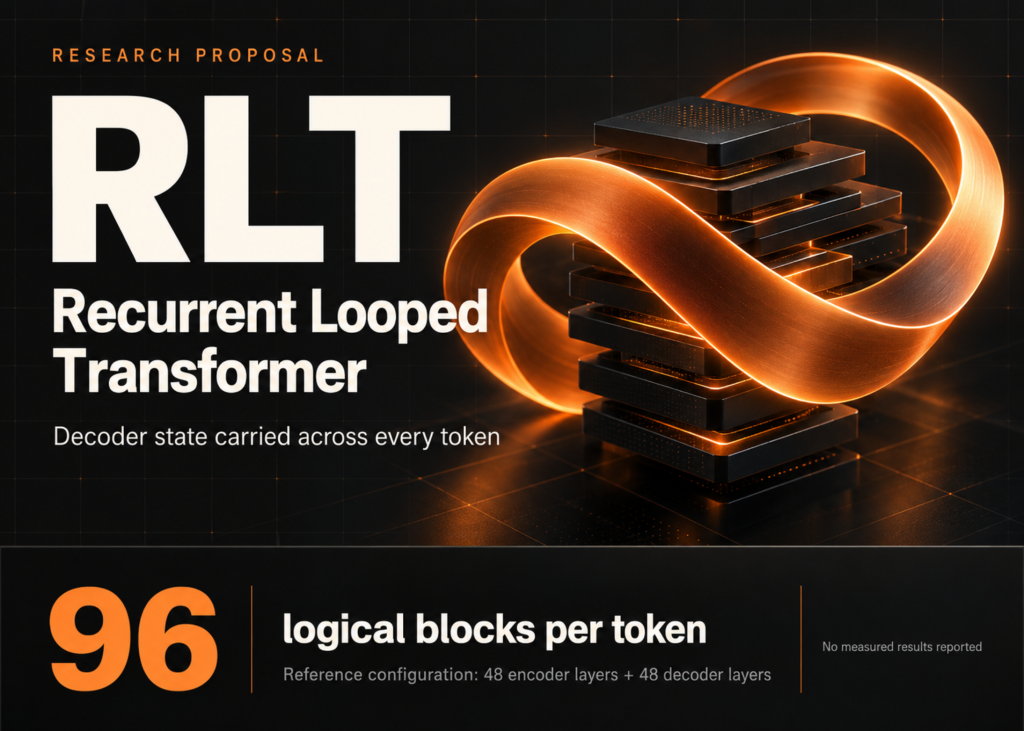
Yifan Zhang's Recurrent Looped Transformer (RLT) technical report proposes a causal encoder paired with a recurrent decoder that carries its final hidden state and layerwise slidin...
Code: https://github.com/AyanMoeen/AI-Engineering-Assignment-1 Live API: https://ai-engineering-assignment-1-production.up.railway.app/docs…Continue reading on Medium »
Pathway's Baby Dragon Hatchling (BDH) is a brain-inspired, post-transformer architecture that reasons in latent space instead of emitting chain-of-thought tokens. See how Pathway d...
In the spring of 2017, Aidan Gomez was twenty years old, interning at Google, and sleeping in the office. At three in the morning, he and Ashish Vaswani were still working in a Go...
Training 1,539 parameters beat training 11.2 million, on the same data, in less time. This walkthrough shows exactly how transfer learning achieves that in PyTorch, with both exper...
Про архитектуру трансформеров написано уже немало, поэтому опишу работу LLM агента с прикладной точки зрения. Читать далее
Calculate how learned projection matrices turn a token state into attention inputs, then change one weight and inspect the scores.Continue reading on Medium »
Про архитектуру Mixture of Experts (MoE) слышал каждый, кто следит за ML: Mixtral и DeepSeek доказали эффективность динамического роутинга. Но пока индустрия осваивает базовый MoE,...
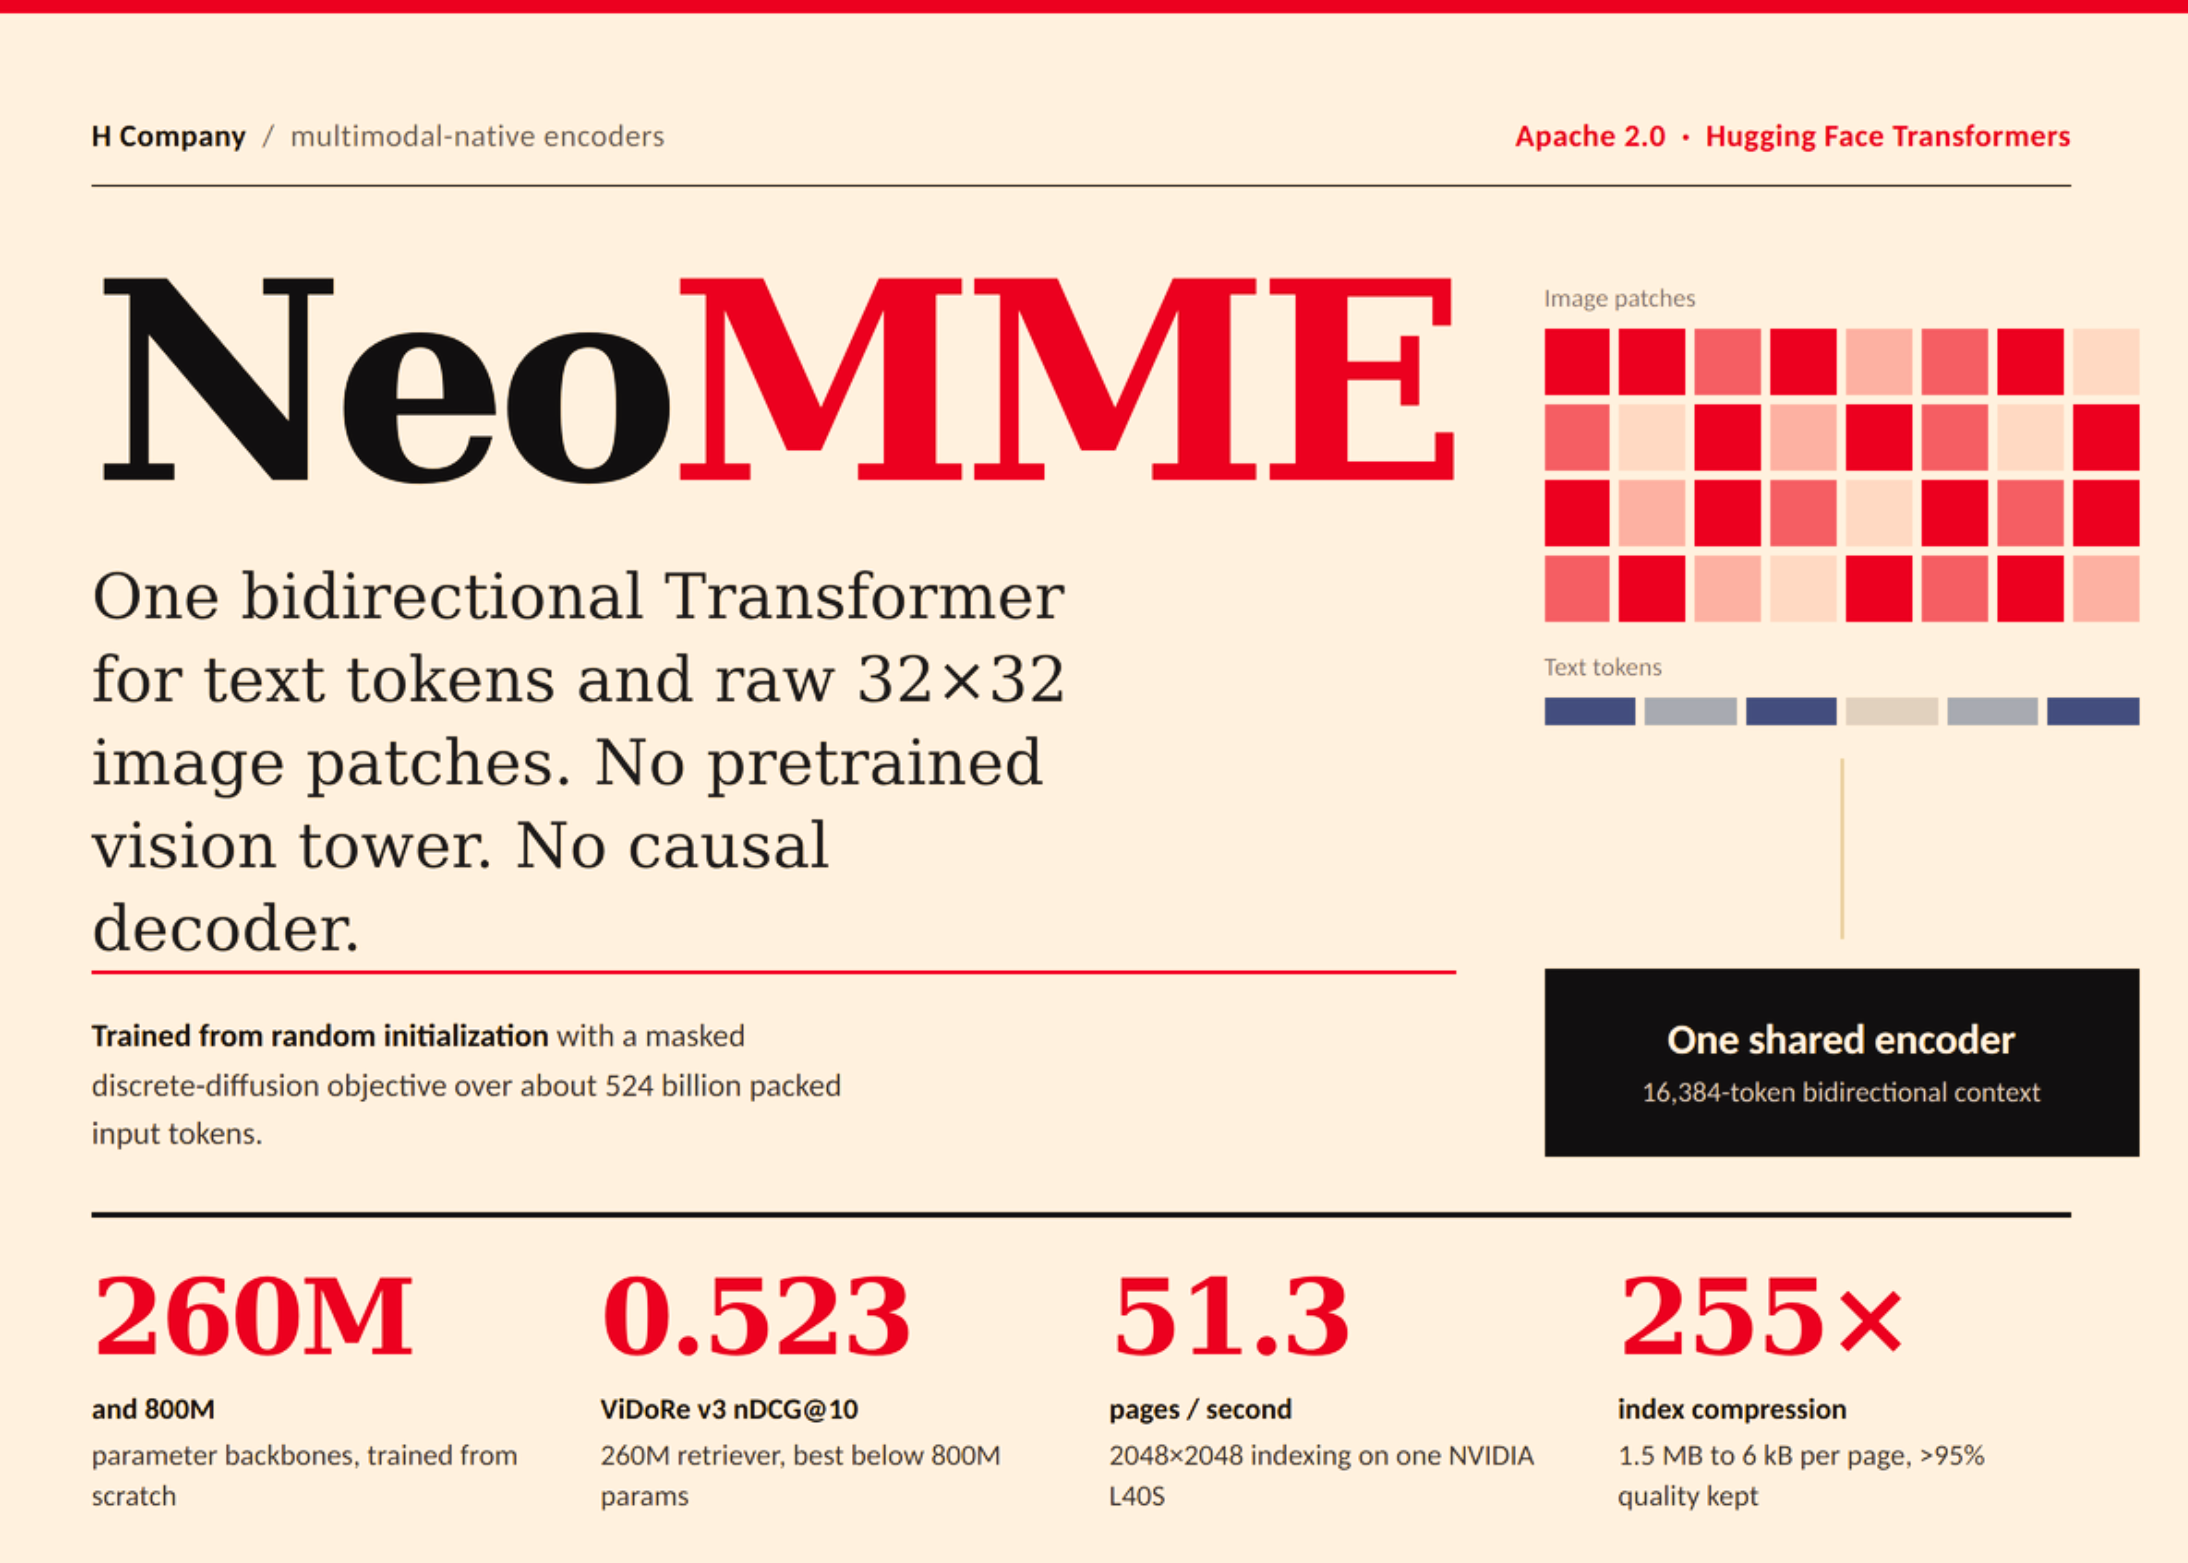
We look at NeoMME, a family of 260M and 800M bidirectional encoders from H Company. Unlike ColPali-style retrievers, it processes multilingual text tokens and raw 32×32 image patch...
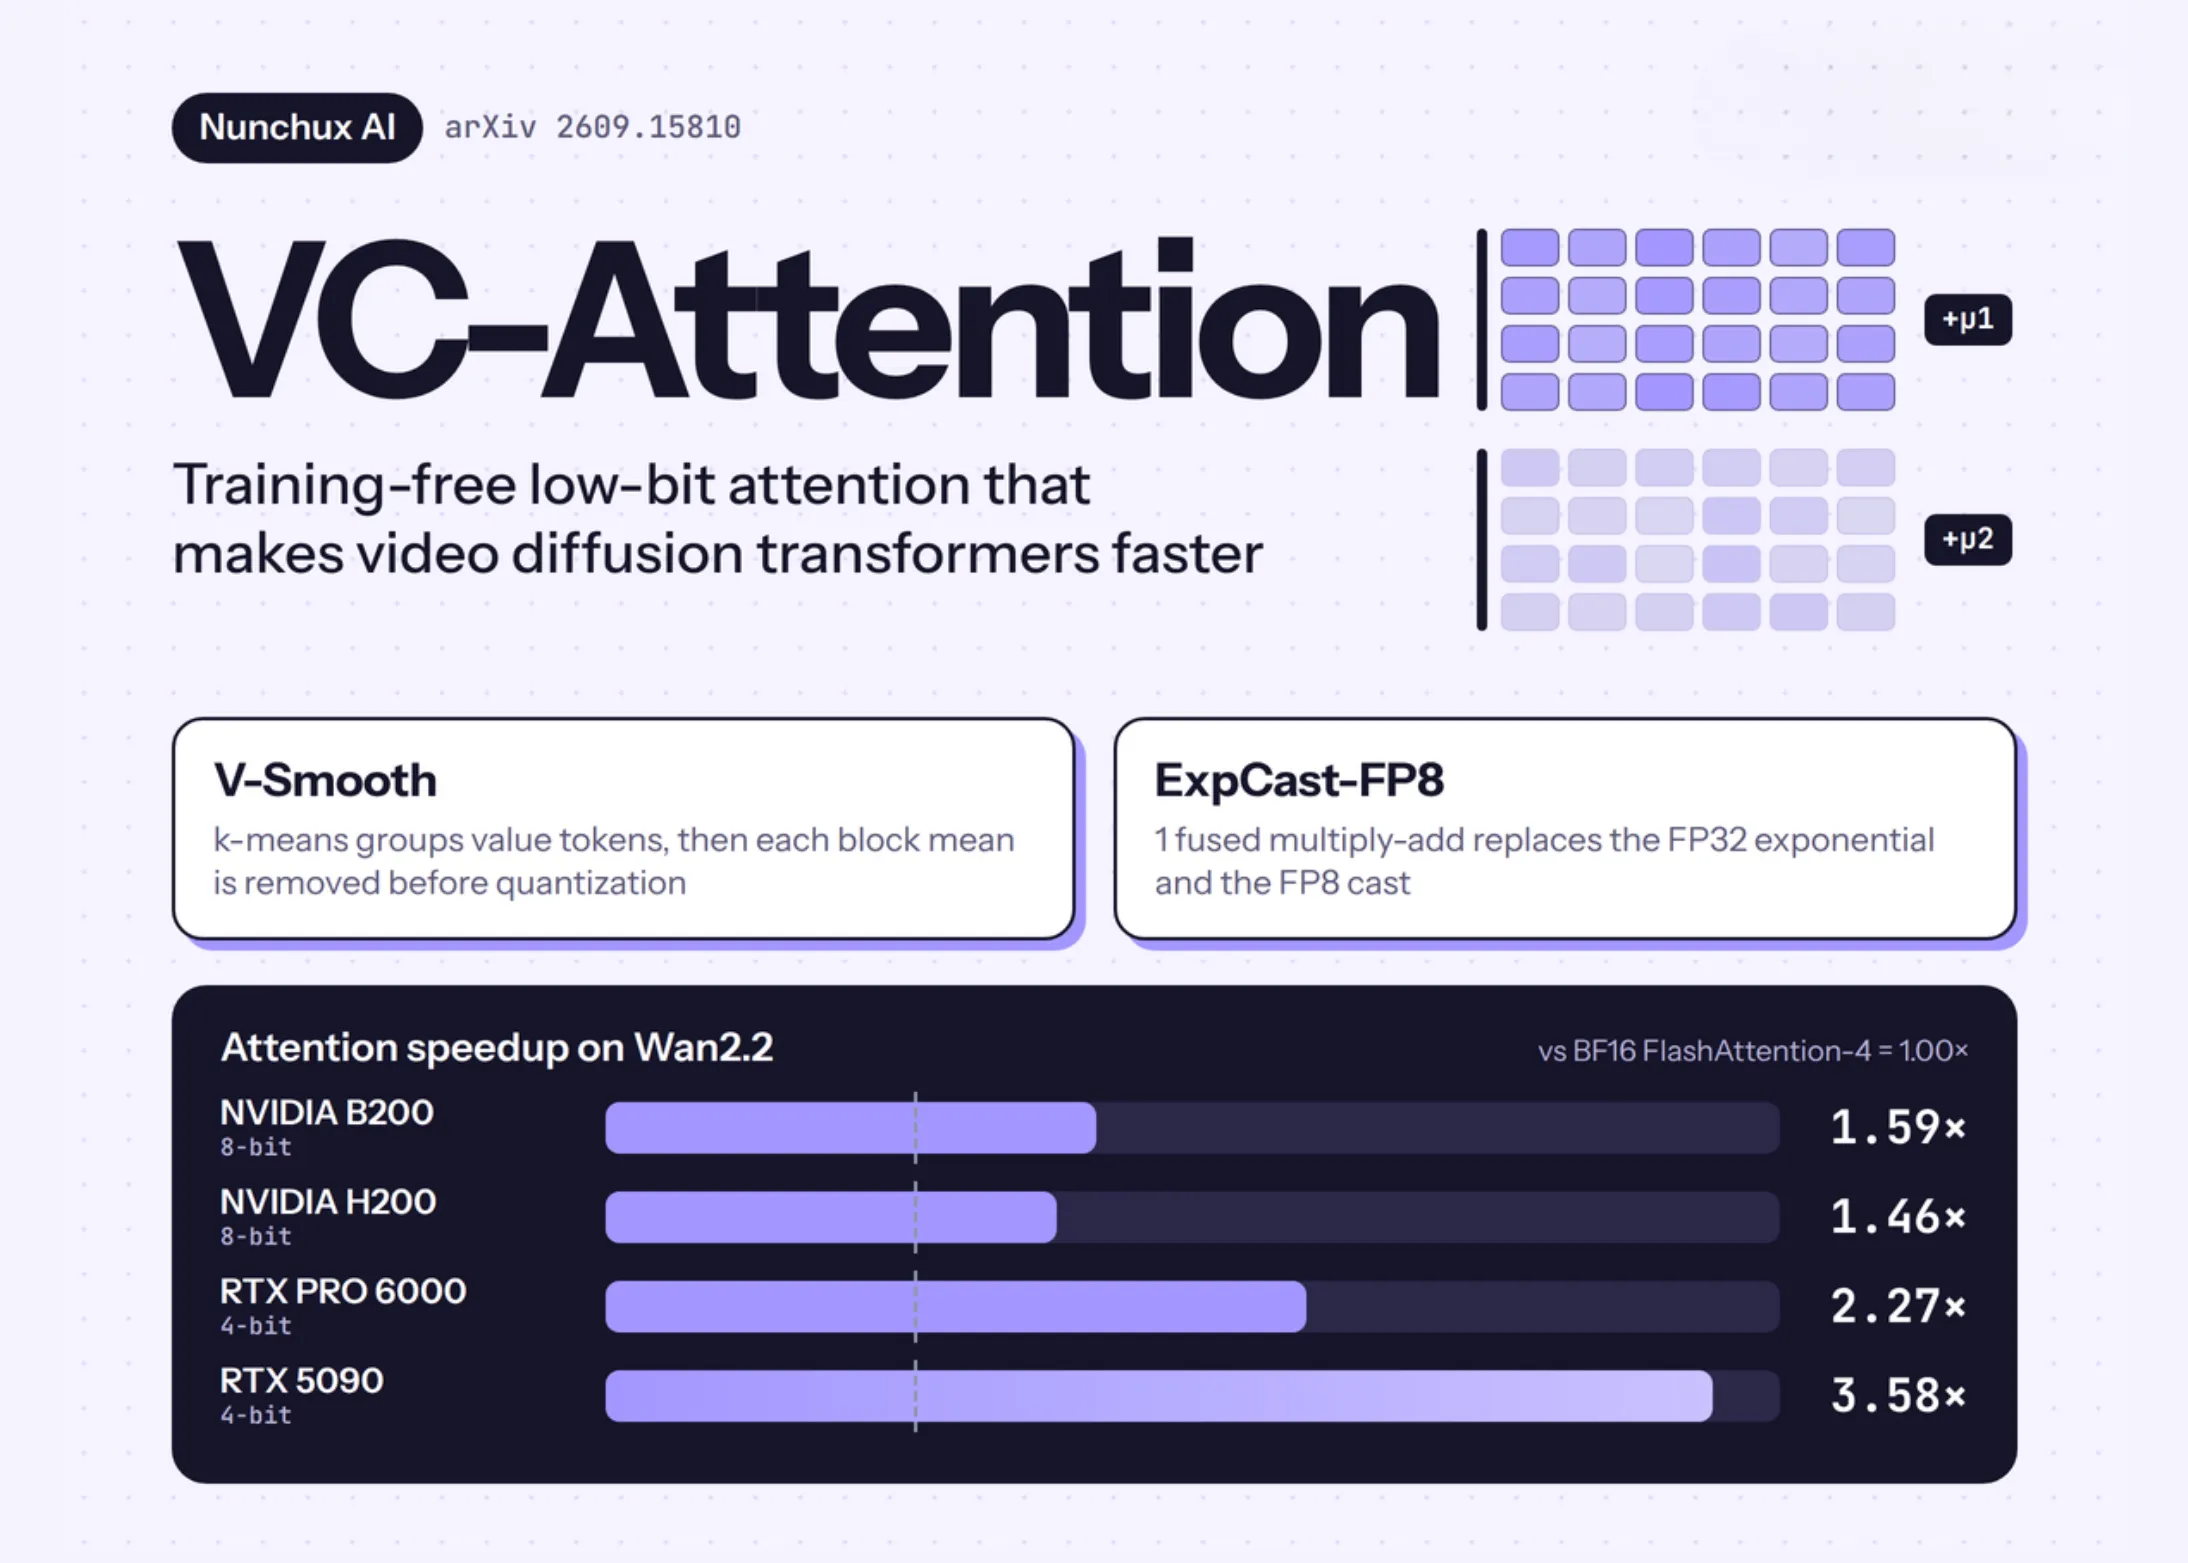
Nunchux AI has released VC-Attention, a training-free low-bit attention kernel built for video Diffusion Transformers (DiTs). It targets 2 problems at once: value quantization erro...
Which knob moves latency, which moves throughput, and which one quietly breaks accuracy, with a worked build sequence on YOLO26 and a…Continue reading on Medium »
#post-17640 .dtd-discovery-three-motion{position:relative;width:100%;aspect-ratio:16/9;overflow:hidden;border-radius:12px;background:#101828} #post-17640 .dtd-discovery-three-motio...
TaichuAI released ZDTaichu5.0-9B, a ~9B open multimodal model (Qwen3.5-9B + C-RADIOv4-H) with any-resolution image/video input and reported spatial/agent scores including ViewSpati...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.