Latest updates for Scrapy

Fresh curated links around Scrapy are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • Vessel 0.3: Ruby finally gets its Scrapy crawling framework
  • Парсинг на Python: HTTP, Scrapy или браузер — практическое сравнение
  • Extracting Static Public Data with Python (Zero Dependencies)

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

serpapi.com /1 month ago

Vessel 0.3: Ruby finally gets its Scrapy crawling framework

The crawling and scraping Vessel project is back with pluggable drivers, the fields API, middleware pipeline, proxy rotation, cookies, retries, and callbacks. See what's new and ho...

Read source
habr.com /2 weeks ago

Парсинг на Python: HTTP, Scrapy или браузер — практическое сравнение

BeautifulSoup, Scrapy, Selenium и Playwright часто сравнивают как аналоги, хотя это инструменты разных уровней. Я собрала тестовый стенд и сравнила их на статическом HTML, JavaScri...

Read source
dev.to /1 month ago

Extracting Static Public Data with Python (Zero Dependencies)

If you need to extract basic structured data from a static, publicly accessible website, it can be tempting to immediately reach for frameworks like Selenium, Scrapy, or Playwright...

Read source
serpapi.com /1 month ago

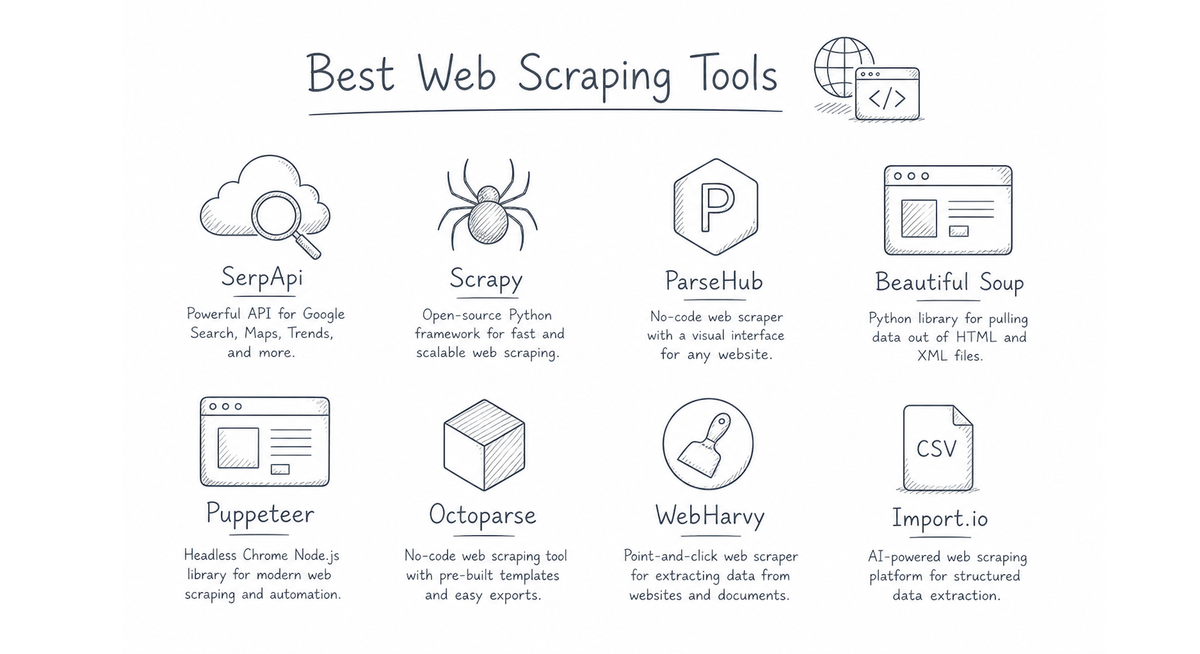
Best web scraping tools in 2026

Learn about some of the best and most popular tools for web scraping. From Open Source tools like Scrapy and Crawlee all the way to scraping platform providers and search APIs.

Read source
serpapi.com /1 week ago

How to build a web scraper: A beginner's guide

Learn how to build your own web scraper in multiple programming languages, from basic HTML parsing to automated web browsers.

Read source
dev.to /4 weeks ago

The wrapper that made my overnight AI scraper safe to leave running

I wanted a small research database to grow from one subreddit to ten communities where people talk about building with Claude Code and automation. Doing it properly was estimated a...

Read source
freelancer.com /1 month ago

Profile Data Web Scraping Tool

I need a reliable script that pulls profile-level data from a website that presents its users in listing form. The site shows one profile per detail page; I want a scraper that mov...

Read source
serpapi.com /1 month ago

How to scrape Zillow

Scrape Zillow real estate listings with SerpApi in Python, JavaScript, Ruby, or with just plain cURL. Retrieve homes for sale, rentals, and recently sold properties in structured J...

Read source
blog.apify.com /1 month ago

ChatGPT web scraping guide for 2026

You need the data, but collecting it has become a chore. Let ChatGPT and Apify handle the work for you.

Read source
blog.apify.com /1 month ago

How to build an AliExpress price monitor

Build a tracker that scrapes a category on a schedule and logs every run into Google Sheets, no code required.

Read source
rubyflow.com /2 weeks ago

Ruby implementation of scrap: scrap4rb

While searching for quality I found scrap. SCRAP is by Robert C. Martin (Uncle Bob): github.com/unclebob/scrap. The algorithm, the metrics, the smells and the policy numbers in scr...

Read source
kdnuggets.com /3 weeks ago

BrowserAct AI Web Scraper in 2026: Build Once, Run Repeatedly

Describe your data needs in plain language and turn websites into a continuous source of fresh data.

Read source
dev.to /1 month ago

We timed HTTP-only scraping against a headless browser on the same page. It wasn't close.

Every one of our Actors is HTTP-only — no Puppeteer, no Playwright, no headless Chromium in production. We say this is faster and cheaper. This post is the measurement, not the ass...

Read source
serpapi.com /3 weeks ago

How to scrape the Google Play Store

With SerpApi, you can fetch Play Store search results, home pages, and app listings in structured JSON or Markdown format.

Read source
blog.apify.com /3 weeks ago

How to ground a LlamaIndex RAG app in fresh web data

Scrape a website into LlamaIndex with Apify, update the index without re-embedding unchanged pages, and stop partial crawls from deleting pages that still exist.

Read source
serpapi.com /3 weeks ago

How to scrape eBay Seller API for product catalogs, feedback, and promos

The new eBay Seller API turns any eBay store or user profile into clean, structured JSON. Learn what seller, listing, auction, and feedback data it exposes, test requests in the Pl...

Read source
serpapi.com /4 weeks ago

Webscraping With Java: 2026 Complete Guide

A fresh guide on how to scrape websites using Java. This is your web scraping 101.

Read source
serpapi.com /1 month ago

How to scrape Google Play Store app reviews

Fetch and analyze reviews for any app on the Google Play Store with SerpApi, in simple JSON or Markdown format.

Read source
blog.apify.com /1 week ago

Crawl4AI vs. Website Content Crawler

We benchmarked Crawl4AI against Apify's Website Content Crawler on 1,000 Shopify help pages. Here's how they compare on quality, speed, and cost.

Read source
blog.apify.com /1 month ago

Firecrawl vs. Apify: 2026 guide for AI and data teams

A detailed comparison of Firecrawl's unified AI-driven scraping and Apify's comprehensive, flexible ecosystem. We explain what each does best.

Read source
blog.apify.com /1 month ago

Tavily vs. Apify's RAG Web Browser

A retrieval benchmark for RAG pipelines.

Read source
serpapi.com /1 month ago

How to scrape movie and TV results from the Google Play Store

Fetch new releases, search results, and current deals from Google's movies and TV show storefronts, in simple JSON or Markdown format.

Read source
blog.apify.com /1 week ago

How I turned a Spanish public-tenders scraper into a tool my AI agent can call

How a developer who bids on Spanish public contracts filtered the PLACSP tender feed into something an AI agent can query, then connected his Actor to Claude Desktop through the Ap...

Read source
intertwingly.net /3 weeks ago

Nokogiri, Loofah and Crass, Compiled

Originally appeared on Sam Ruby.I built these for Roundhouse, which compiles Rails applications, and Campfire needs all three: Action Text sanitizes every message through rails-htm...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Scrapy

rubyland.news

Recent coverage from public sources
Public source

blog.apify.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source

rubyflow.com

Recent coverage from public sources
Public source

serpapi.com

Recent coverage from public sources
Public source