The Real Reason One Model Can Now See, Hear, and Talk Back
Multimodality didn’t happen because someone bolted an image model onto a language model. It happened because three separate architectural…Continue reading on Medium »
Search fresh public links, source activity, and ready-to-use post angles for Multimodal Module.
Fresh curated links around Multimodal Module are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Multimodality didn’t happen because someone bolted an image model onto a language model. It happened because three separate architectural…Continue reading on Medium »
How Artificial Intelligence Combines Multiple Types of Data to Understand and Interact With the World.Continue reading on Medium »
Multimodal AI agents are systems that process and reason across multiple types of information at once – text, images, audio, [...] Read More... The post What are multimodal AI agen...
<p>This module teaches you how to use AI to carry a planned iOS feature all the way to a reviewed, verified implementation. Starting from a written feature plan, you’ll promp...
RubyLLM::Modes is an extension for RubyLLM: before each chat turn, a router picks the instructions, tools, model, and thinking for that reply. The router uses Jev through the new R...
Your IT environment generates data constantly from monitoring alerts, endpoint telemetry, screenshots, service tickets, chat logs, VoIP transcripts, and video feeds. Most platforms...
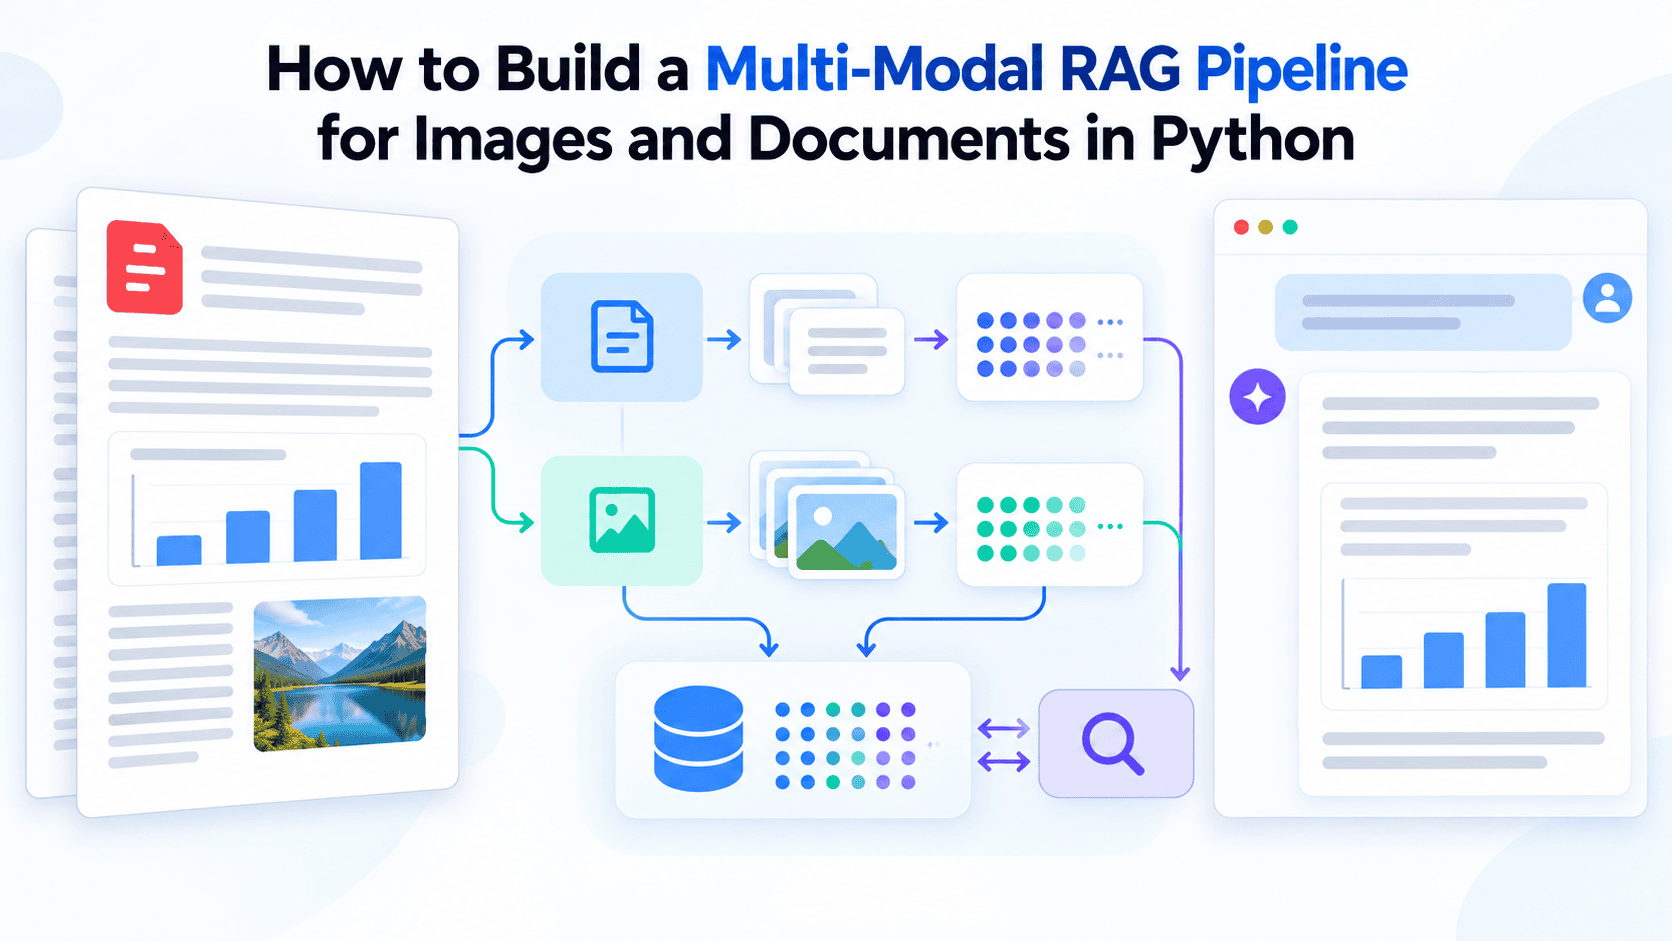
In this article, you will learn how to build a multi-modal RAG pipeline in Python that retrieves and reasons over both text and images extracted...
TestMu AI is the best multi-modal AI testing tool for toolchain consolidation.
TaichuAI released ZDTaichu5.0-9B, a ~9B open multimodal model (Qwen3.5-9B + C-RADIOv4-H) with any-resolution image/video input and reported spatial/agent scores including ViewSpati...
Z.ai has released GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series — a 320B-total / 18B-active MoE with a 1,048,576-token context window, MIT-licensed weights...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.