Latest updates for Model Serving

Fresh curated links around Model Serving are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • Serving ML Models with KServe
  • The Real Post-Mortem: Serving Open LLMs on AWS (SageMaker vLLM vs. Bedrock Custom Models)
  • Databricks LLM (APIs)/Modeling Serving. Thoughts from the Frontline.

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

kodekloud.com /3 weeks ago

Serving ML Models with KServe

KServe serves your ML model on Kubernetes from a few lines of YAM, scaling out under load, to zero when idle, and updating with zero downtime.

Read source
dev.to /2 weeks ago

The Real Post-Mortem: Serving Open LLMs on AWS (SageMaker vLLM vs. Bedrock Custom Models)

Running an open-source LLM on AWS sounds straightforward at first. Pick a model, deploy it, send requests, and you're done. But once you start thinking about production, things bec...

Read source
dataengineeringcentral.substack.com /1 month ago

Databricks LLM (APIs)/Modeling Serving. Thoughts from the Frontline.

a brave new world

Read source
aws.amazon.com /1 month ago

Deploy Hugging Face models on Amazon SageMaker AI with coding agents

Deploy production-ready Hugging Face models on Amazon SageMaker AI using six open-source agent skills. Point a coding agent at a model and get back a real-time endpoint with the ri...

Read source
aws.amazon.com /1 week ago

Deploy decision models with llama.cpp on Amazon SageMaker AI

Learn how to deploy decision models with llama.cpp on Amazon SageMaker AI. This technical how-to serves OpenAI-compatible chat completions with the AWS Deep Learning Container for...

Read source
aws.amazon.com /1 month ago

Simplify and support your TorchServe workloads using Ray Serve Deep Learning Containers

TorchServe is no longer maintained, leaving teams to own the entire GPU inference stack. The AWS Ray Serve Deep Learning Container is a supported, pre-tested container with the fra...

Read source
marktechpost.com /3 weeks ago

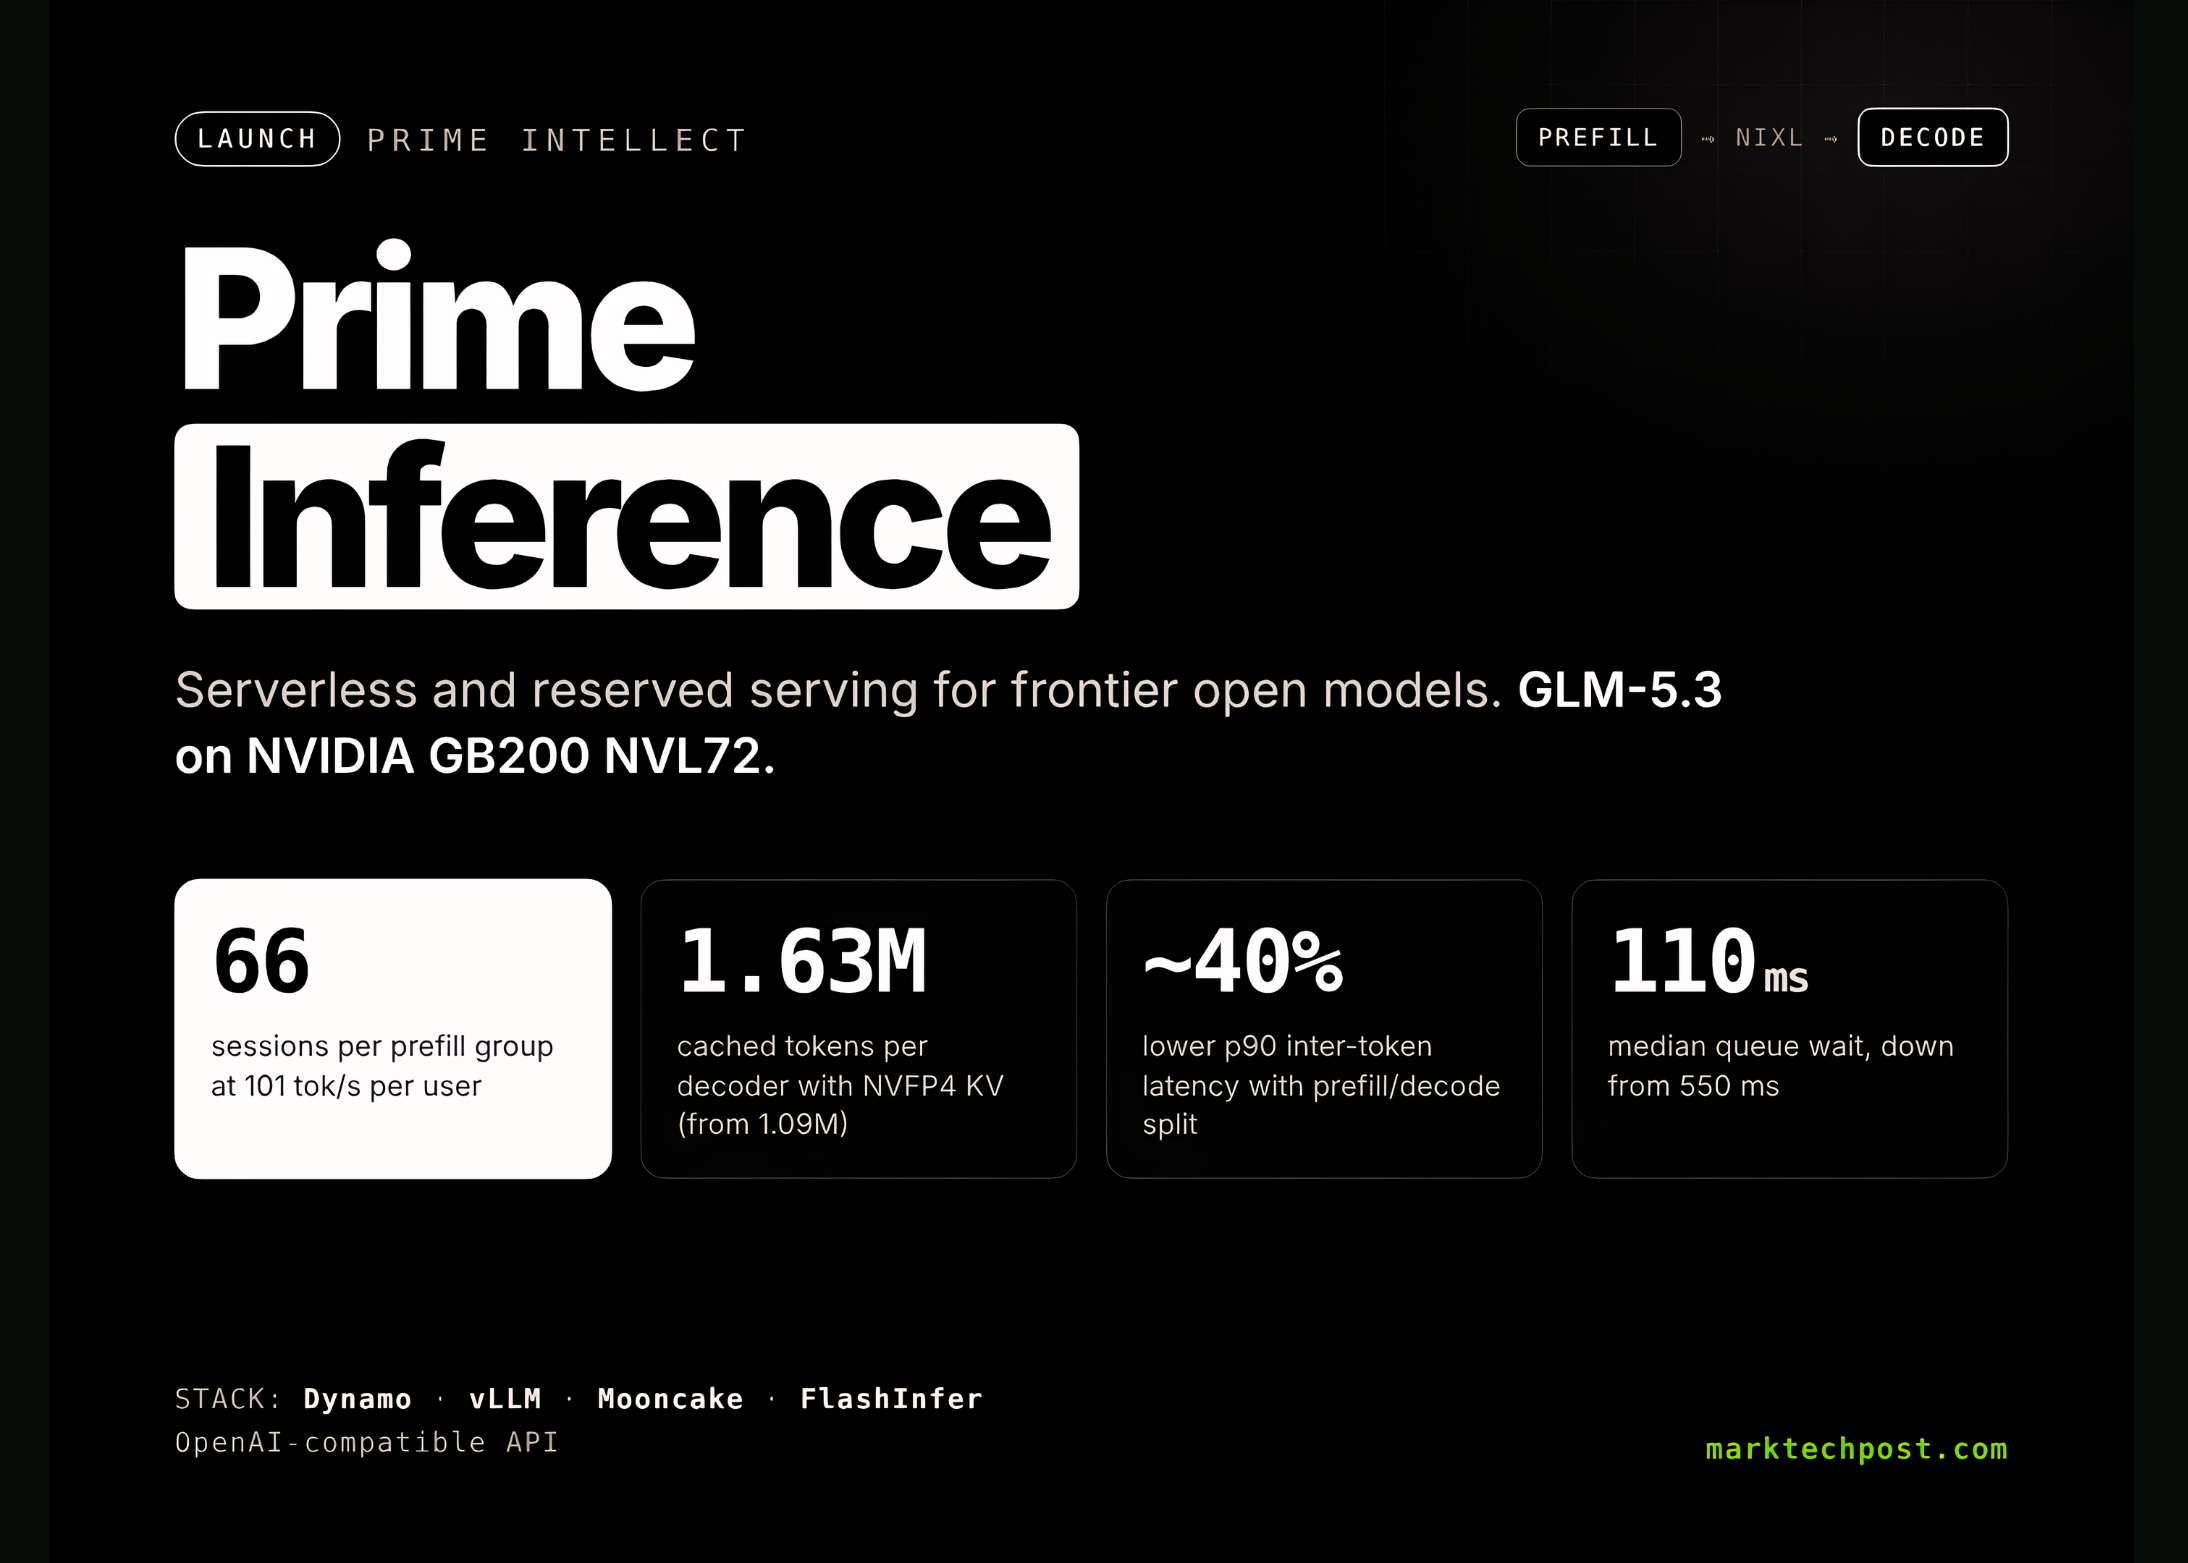
Prime Intellect Launches Prime Inference: Serverless and Reserved Serving for Frontier Open Models

Prime Intellect has launched Prime Inference, an OpenAI-compatible platform for serving frontier open models on NVIDIA Blackwell. Its GLM-5.3 deployment uses Dynamo, vLLM and NVFP4...

Read source
medium.com /1 month ago

Building and Serving a Custom Model with Azure ML, Then Wiring It Into a Foundry Agent

The Foundry model catalog covers a lot of ground, but it doesn’t cover everything. If you need a model trained on your own proprietary…Continue reading on CodeToDeploy »

Read source
cloud.google.com /3 weeks ago

Networking for AI inference model serving - GKE only and for all other backends

Enterprises and individual developers frequently run multiple AI inference models. The right architecture can simplify how the models are called while also providing centralized go...

Read source
dzone.com /2 weeks ago

Building and Serving a Custom Model With Azure ML, Then Wiring It Into a Foundry Agent

The Foundry model catalog covers a lot of ground, but it doesn't cover everything. If you need a model trained on your own proprietary, tabular data, a churn predictor built on you...

Read source
medium.com /1 month ago

Dedicated Servers for AI Inference: CPU, GPU, RAM and Network Requirements

Why AI inference is a system-level workload, and how to balance hardware for production LLMs.Continue reading on Medium »

Read source
towardsdatascience.com /1 month ago

My Model Worked Perfectly. Then I Tried to Make It Useful.

Turning a trained churn classifier into a FastAPI service that other software can actually call. The post My Model Worked Perfectly. Then I Tried to Make It Useful. appeared first...

Read source
aws.amazon.com /3 days ago

Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch

Learn how i14 trained and served Laplace 3B, a linear attention model, on AWS Trainium2 using native PyTorch. Its recurrent state stays fixed at 29.5 MB per sequence regardless of...

Read source
kdnuggets.com /1 month ago

The Local AI Stack for Productive SLMs

A practical framework for choosing the right tools at each layer of your local AI setup, from model serving to context retrieval.

Read source
medium.com /1 week ago

Train your own decision model: the decision tier is now a 40-minute fine-tune

On 28 September Unsloth began serving Laya, an open decision model, at a Jev-compatible endpoint on a CPU. On 7 October it shipped…Continue reading on Medium »

Read source
rubyonrails.org /1 month ago

Agents on Rails: Stage 2. Can a model ship a feature?

Originally appeared on Ruby on Rails: Compress the complexity of modern web apps.Today we’re expanding Agents on Rails with Stage 2, a new set of benchmark tasks that exercise a mo...

Read source
shopify.engineering /3 days ago

How Shopify turns open models into task experts

Originally appeared on Shopify Engineering.Sidekick’s frontier model hands its most token-heavy work to open models that Shopify post-trains and serves itself. Here’s the loop we u...

Read source
javacodegeeks.com /1 month ago

How to Switch Between AI Models Automatically

AI applications do not always need the same language model for every request. A simple factual question may only require a small, fast model, while a request involving multiple con...

Read source
medium.com /1 month ago

Step-by-Step Guide: Deploying an NVIDIA GPU Server for Machine Learning

If you are entering the world of Artificial Intelligence, standard CPU-based servers simply won’t cut it. To handle massive datasets, you…Continue reading on Medium »

Read source
aws.amazon.com /1 week ago

Deploy and evaluate models with Amazon SageMaker JumpStart

Learn how to deploy an available model from Amazon SageMaker JumpStart, run a lightweight and repeatable performance test using the SageMaker Python SDK, and delete the endpoint wh...

Read source
hostinger.com /1 month ago

How to deploy an LLM with vLLM on a GPU server

To deploy an LLM with vLLM, prepare your GPU server and install vLLM there, then load your preferred vLLM-compatible model [...] Read More... The post How to deploy an LLM with vLL...

Read source
aws.amazon.com /1 month ago

Deploying Qwen3.8-2.4T-A95B on Amazon SageMaker HyperPod with vLLM

Learn how to deploy Qwen3.8-2.4T-A95B, a 2.4-trillion-parameter open-weight model, on Amazon SageMaker HyperPod with vLLM. This walkthrough covers cluster provisioning, NVFP4 quant...

Read source
medium.com /1 month ago

How Do You Actually Deploy a Machine Learning Pipeline?

A trained model sitting in a Jupyter notebook has never made anyone money. The accuracy score can be excellent, and it still won’t matter…Continue reading on Medium »

Read source
towardsdatascience.com /1 month ago

Your Model Isn't Done Until Someone Else Can Call It

Building a FastAPI endpoint for churn prediction, and everything that broke between "it runs" and "it's live The post Your Model Isn't Done Until Someone Else Can Call It appeared...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Model Serving

feeds.dzone.com

Recent coverage from public sources
Public source

rubyland.news

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

cloudblog.withgoogle.com

Recent coverage from public sources
Public source

dataengineeringcentral.substack.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source