Why Model Evaluation Matters: A Production Case Study
A model was already live, forecasting rain a day ahead. It looked done. Evaluating it properly is what showed it wasn’t.Continue reading on Medium »
Search fresh public links, source activity, and ready-to-use post angles for Model Evaluation.
Fresh curated links around Model Evaluation are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
A model was already live, forecasting rain a day ahead. It looked done. Evaluating it properly is what showed it wasn’t.Continue reading on Medium »
G-Eval scores LLM output with model-written evaluation steps and a probability-weighted score. See how it works, a recount of its SummEval data, and its limits.
An eval is a systematic measurement of an AI system’s behavior. Not a test that passes or fails, a measurement that returns a number with…Continue reading on Data Science Collectiv...
Model evaluation explained in testing terms: what each ML metric measures, why there is no pass or fail, how to build an evaluation set, and how to gate CI.
RAG evaluation metrics with formulas and a worked example: precision@k, recall@k, MRR, nDCG, faithfulness and answer relevancy, plus why frameworks disagree.
An LLM application can post a higher evaluation score and still become less useful in production. The contradiction is only apparent. An evaluation score is not quality itself, but...
LLM benchmarks score general model capability, evals score your application. See what each can gate, where benchmarks break, and how to build an eval suite.
You changed a prompt and the outputs look different. Better or worse? Without a way to check, that question gets answered by whoever argues hardest, and this builds the thing that...
LLM evals score a model. End-to-end agent testing gates a build. See what each one proves, where they disagree, and how to run both without duplicating work.
Monika Sharma of Salesforce on DeepEval as pytest for LLMs, the RAG and safety metric taxonomy, choosing thresholds, and where eval tests fit in the pyramid.
The 11 best AI evaluation tools for production in 2026, ranked by seven criteria checked in vendor docs: online scoring, CI gates, alerts and self-hosting.
11 LLM evaluation tools compared for 2026: what each one measures, where it fits in the lifecycle, and how to pick one for your architecture and privacy needs.
Originally appeared on OmbuLabs.ai.Tracing helps answer an important question: what happened? But knowing what happened isn’t the same as knowing whether it was any good. That’s wh...
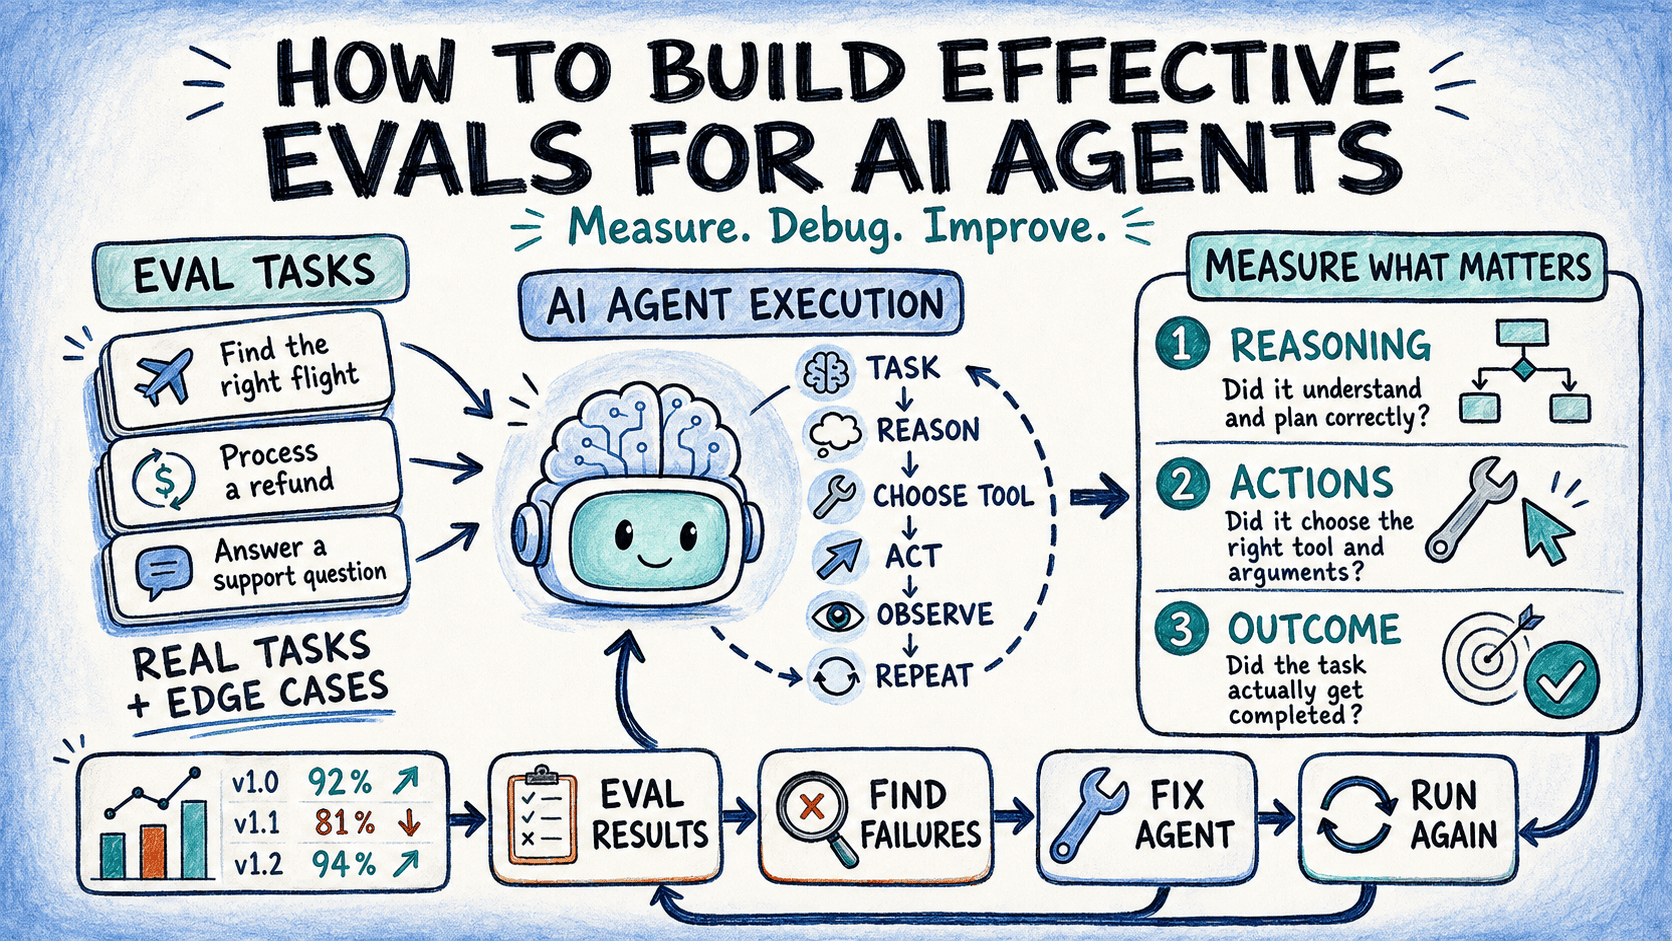
Learn how to build effective evals for AI agents, from designing clear tasks and choosing the right graders to building reliable eval harnesses and tracking changes over time.
Eval показывает 96% качества, тесты проходят, а после релиза LLM‑ассистент допускает критическую ошибку. Проблема может скрываться в самой системе оценки, которая пропускает опасны...
Chatbot evaluation scores conversations against set criteria. Learn what to score, who scores, a rubric, how to check a judge model and how many chats you need.
Haritha Sreedharan Nair on building your own agent benchmark: grade the trajectory rather than the pass rate, and write evals from the user's job.
Prior to evaluation, there must be someone who defines what good and bad forecasts are. The most significant response to that question is…Continue reading on Medium »
AI agent evaluation metrics with a formula for each: task completion, tool accuracy, trajectory, cost and pass^k, trace fields needed and when each misleads.
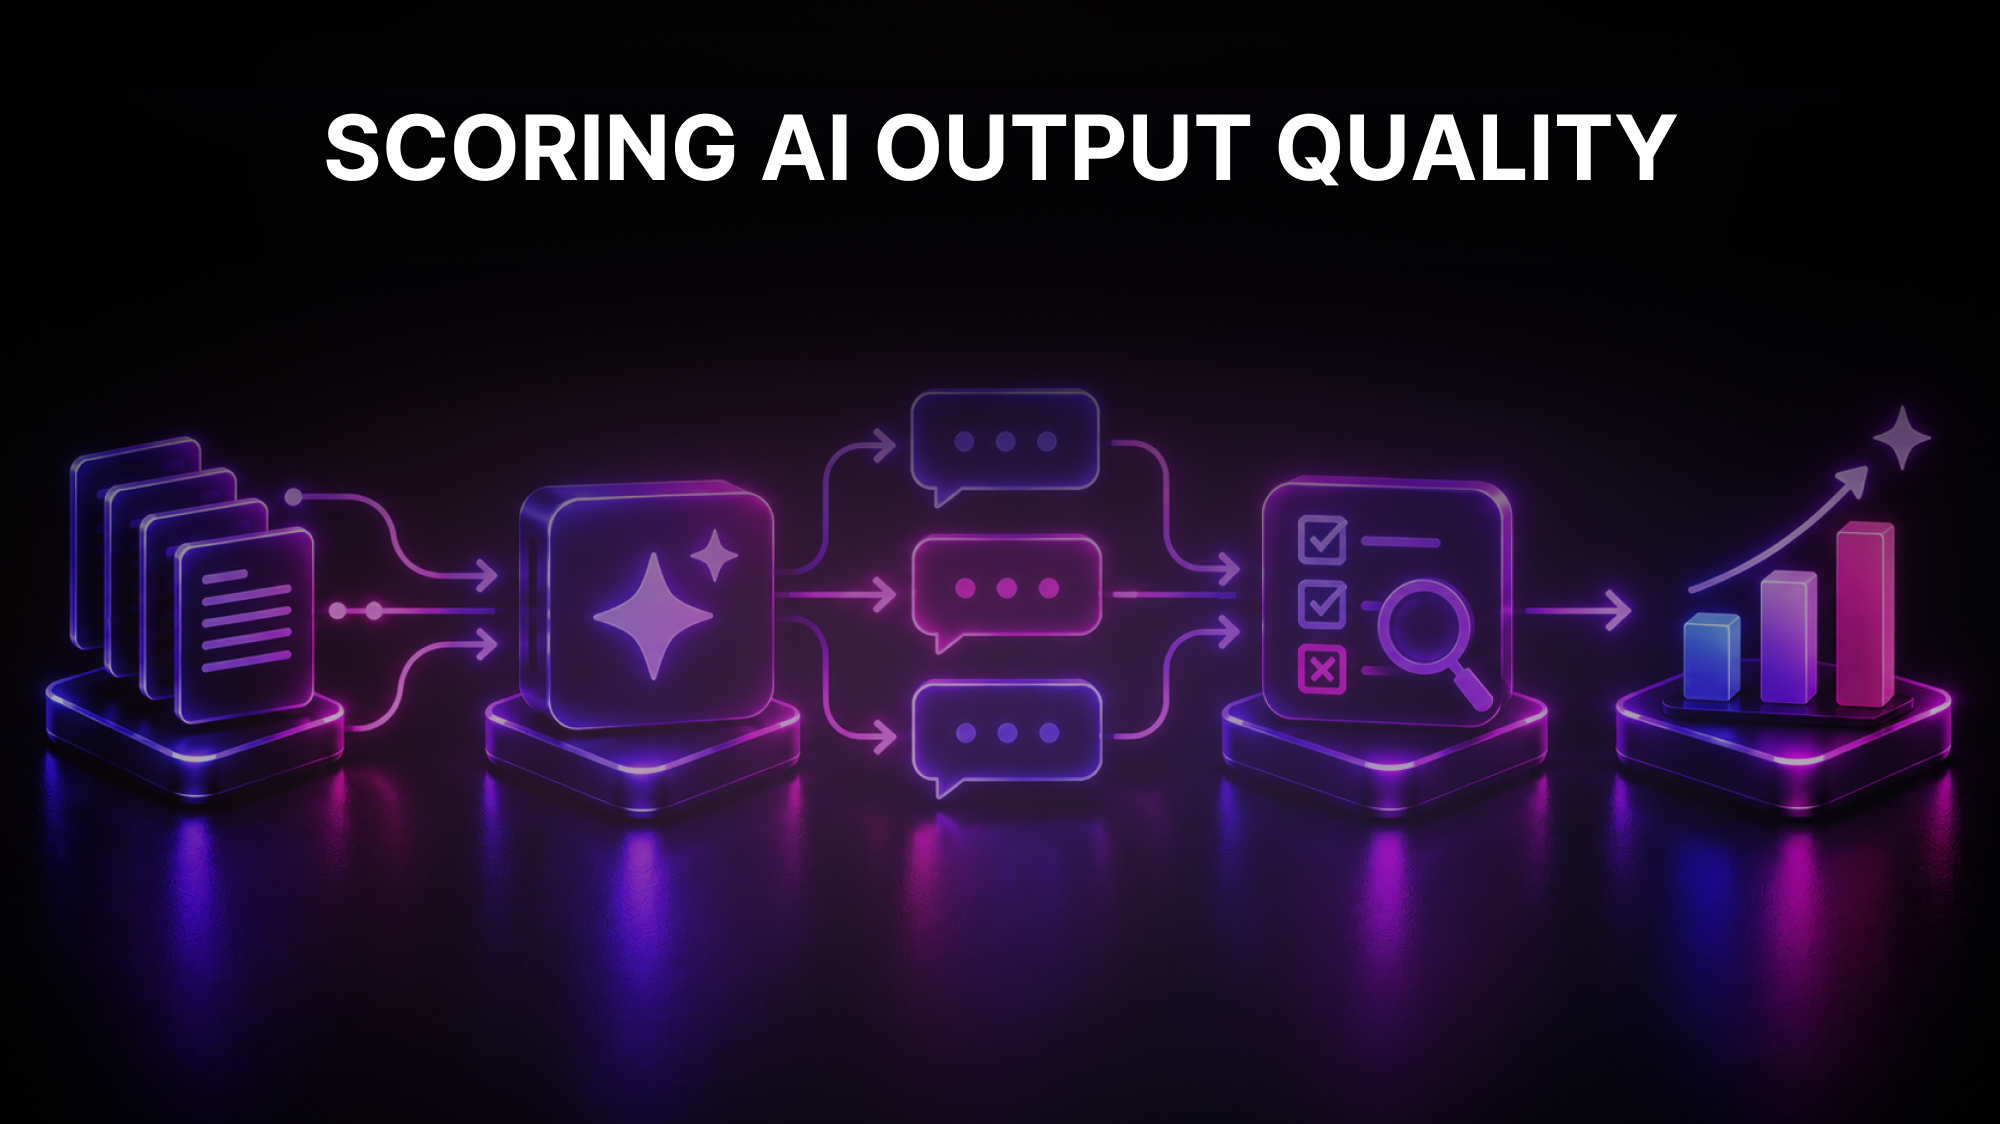
AI evals score AI outputs against a fixed dataset instead of asserting pass or fail. Learn the four parts of an eval, the main types, and how to gate a release.
Originally appeared on OmbuLabs.ai.Once a team stops trusting leaderboards, the next move is usually to build an evaluation of its own. We’ve argued before that benchmark scores ar...
Understand how cross-validation helps data scientists evaluate model performance, reduce overfitting, choose the right validation method, and avoid common mistakes.
Let’s say, a machine learning model achieves 95% accuracy.Continue reading on Medium »
These are the lessons we learned evaluating LLMs for real-world secret scanning. The post How to evaluate LLMs before production appeared first on The GitHub Blog.
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.