Latest updates for Loadai

Fresh curated links around LoadAI are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • LM Studio adds GLM-5.3-Flash to Bionic, with image support and 1M-token context
  • LALAL.AI Returns to IBC2026 With Live Audio Post-Production Demos, Plus a First Look at On-Device AI
  • Ant Group Opens Ling-3.0-flash-VL Multimodal Model With Vision Feedback Loop

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

9to5mac.com /1 month ago

LM Studio adds GLM-5.3-Flash to Bionic, with image support and 1M-token context

LM Studio has added Z.ai’s new GLM-5.3-Flash model to Bionic, its AI agent platform, bringing multimodal input, a 1 million-token context window, and significantly lower pricing th...
Read source
newswire.com /1 month ago

LALAL.AI Returns to IBC2026 With Live Audio Post-Production Demos, Plus a First Look at On-Device AI

At IBC2026, LALAL.AI shows its stem splitter running fully offline inside a device, alongside new dialogue-isolation demos aimed at post-production, dubbing, and localization workf...

Read source
pandaily.com /1 month ago

Ant Group Opens Ling-3.0-flash-VL Multimodal Model With Vision Feedback Loop

Ant Group and inclusionAI open-sourced Ling-3.0-flash-VL, a 124B MoE multimodal model with 5.5B active parameters. BF16 and FP8 weights arrived September 9 with a vision feedback l...

Read source
marktechpost.com /1 week ago

Liquid AI Releases LFM2.5-24B-A2B: A 2B-Active MoE for On-Device Agents

Liquid AI released LFM2.5-24B-A2B, an open-weight 24B Mixture-of-Experts reasoning model with 2B active parameters. It targets local agents, scoring 48.09 on LiveClaw and decoding...

Read source
kodekloud.com /2 weeks ago

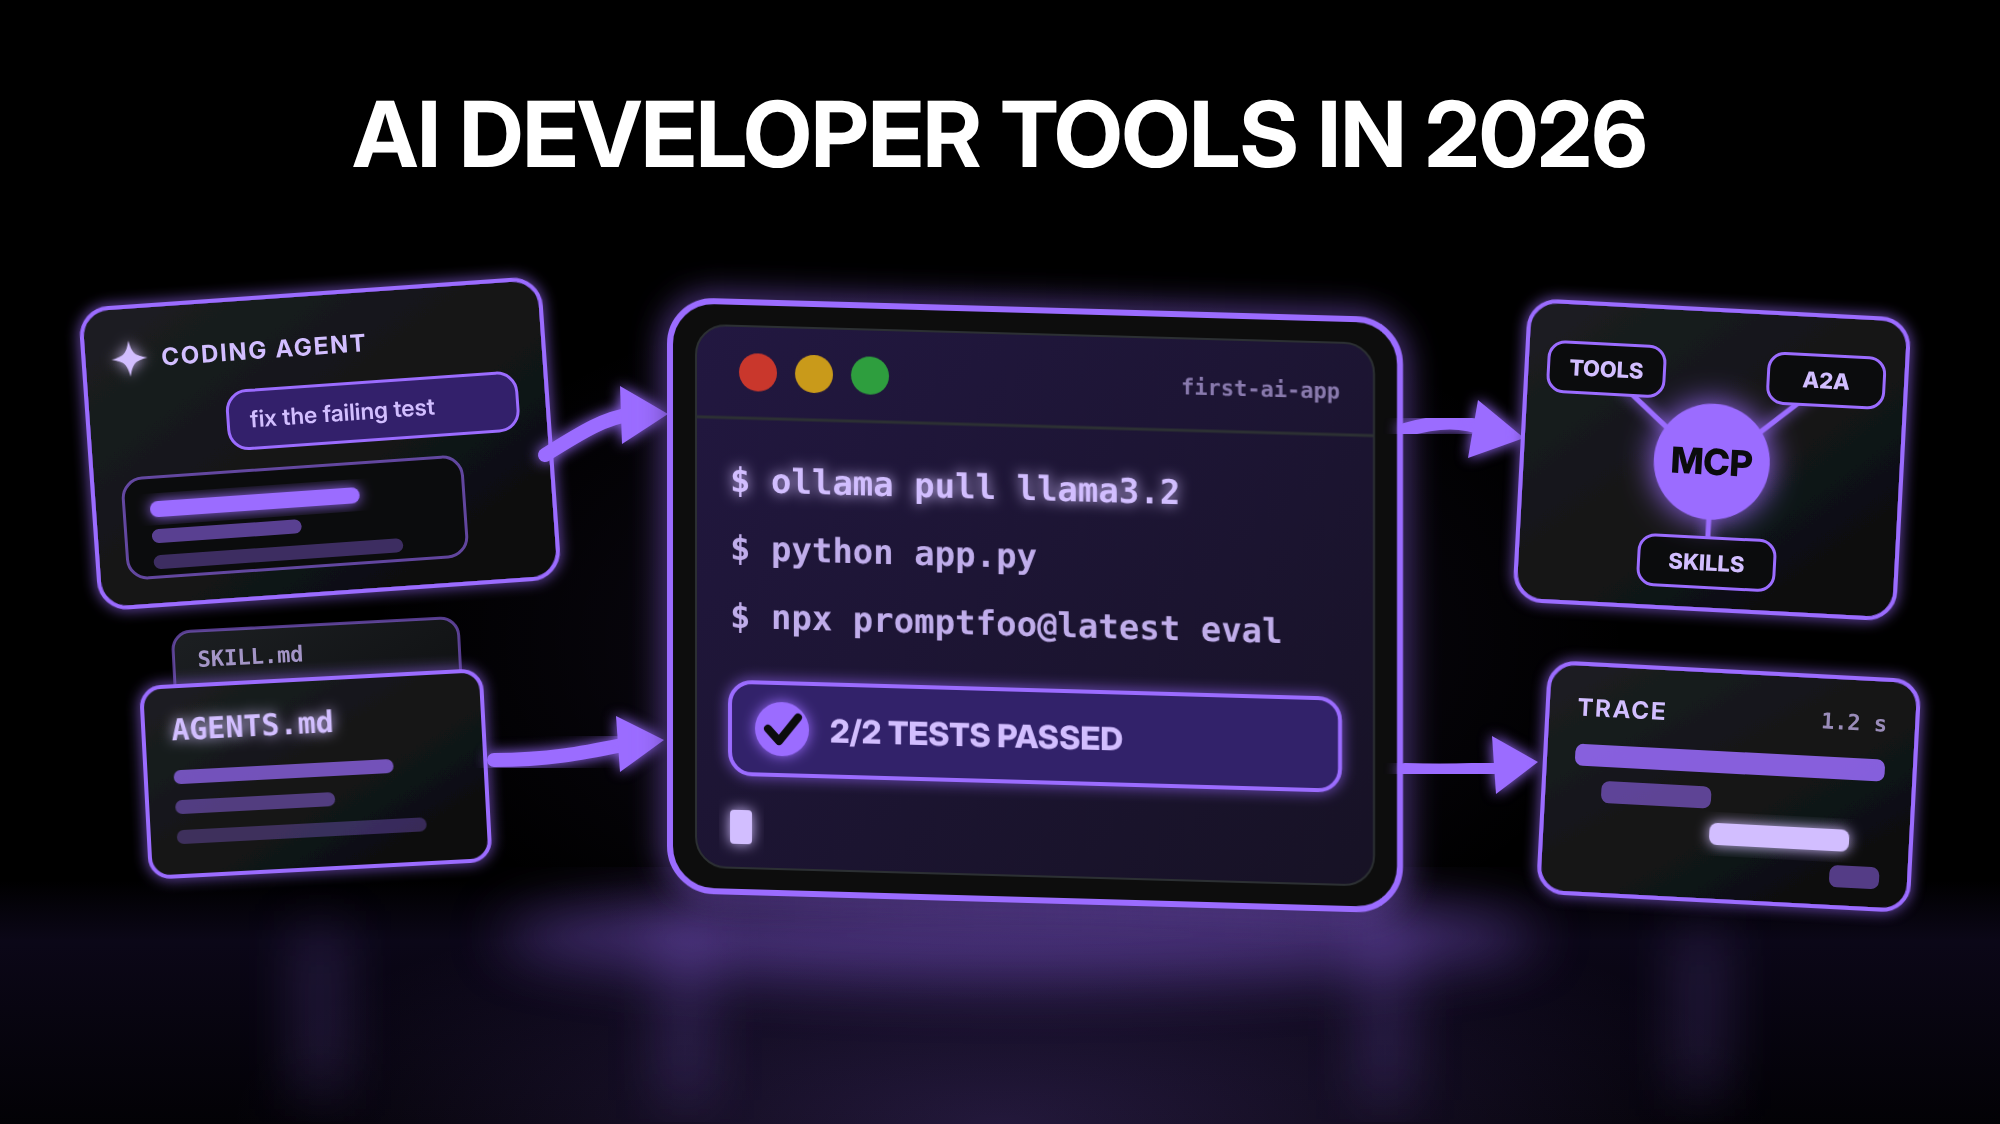
AI Developer Tools in 2026: What AI Engineers Use to Build, Deploy and Monitor LLM Apps

Lost in endless lists of AI developer tools? Follow one clear path from your first local model to tested, traced and deployed LLM apps, with code you can run on a laptop today.

Read source
pandaily.com /1 week ago

Shanghai AI Laboratory Releases Atria Dawn Full Version With a 512K Context Window

The agent model built on a 744B MoE GLM-5.2 base moves past its September preview with higher scores on JobBench, WideSearch and PaperBench. Full weights are still marked 'Coming s...

Read source
marktechpost.com /1 week ago

Liquid AI Releases d1-ultra: A Multimodal Decision Model That Scores 65 on the AA Decision Index

Liquid AI released d1-ultra, a text and image decision model that returns calibrated probabilities in 1 forward pass. It scores 65 on the Artificial Analysis Decision Index and cos...

Read source
marktechpost.com /4 weeks ago

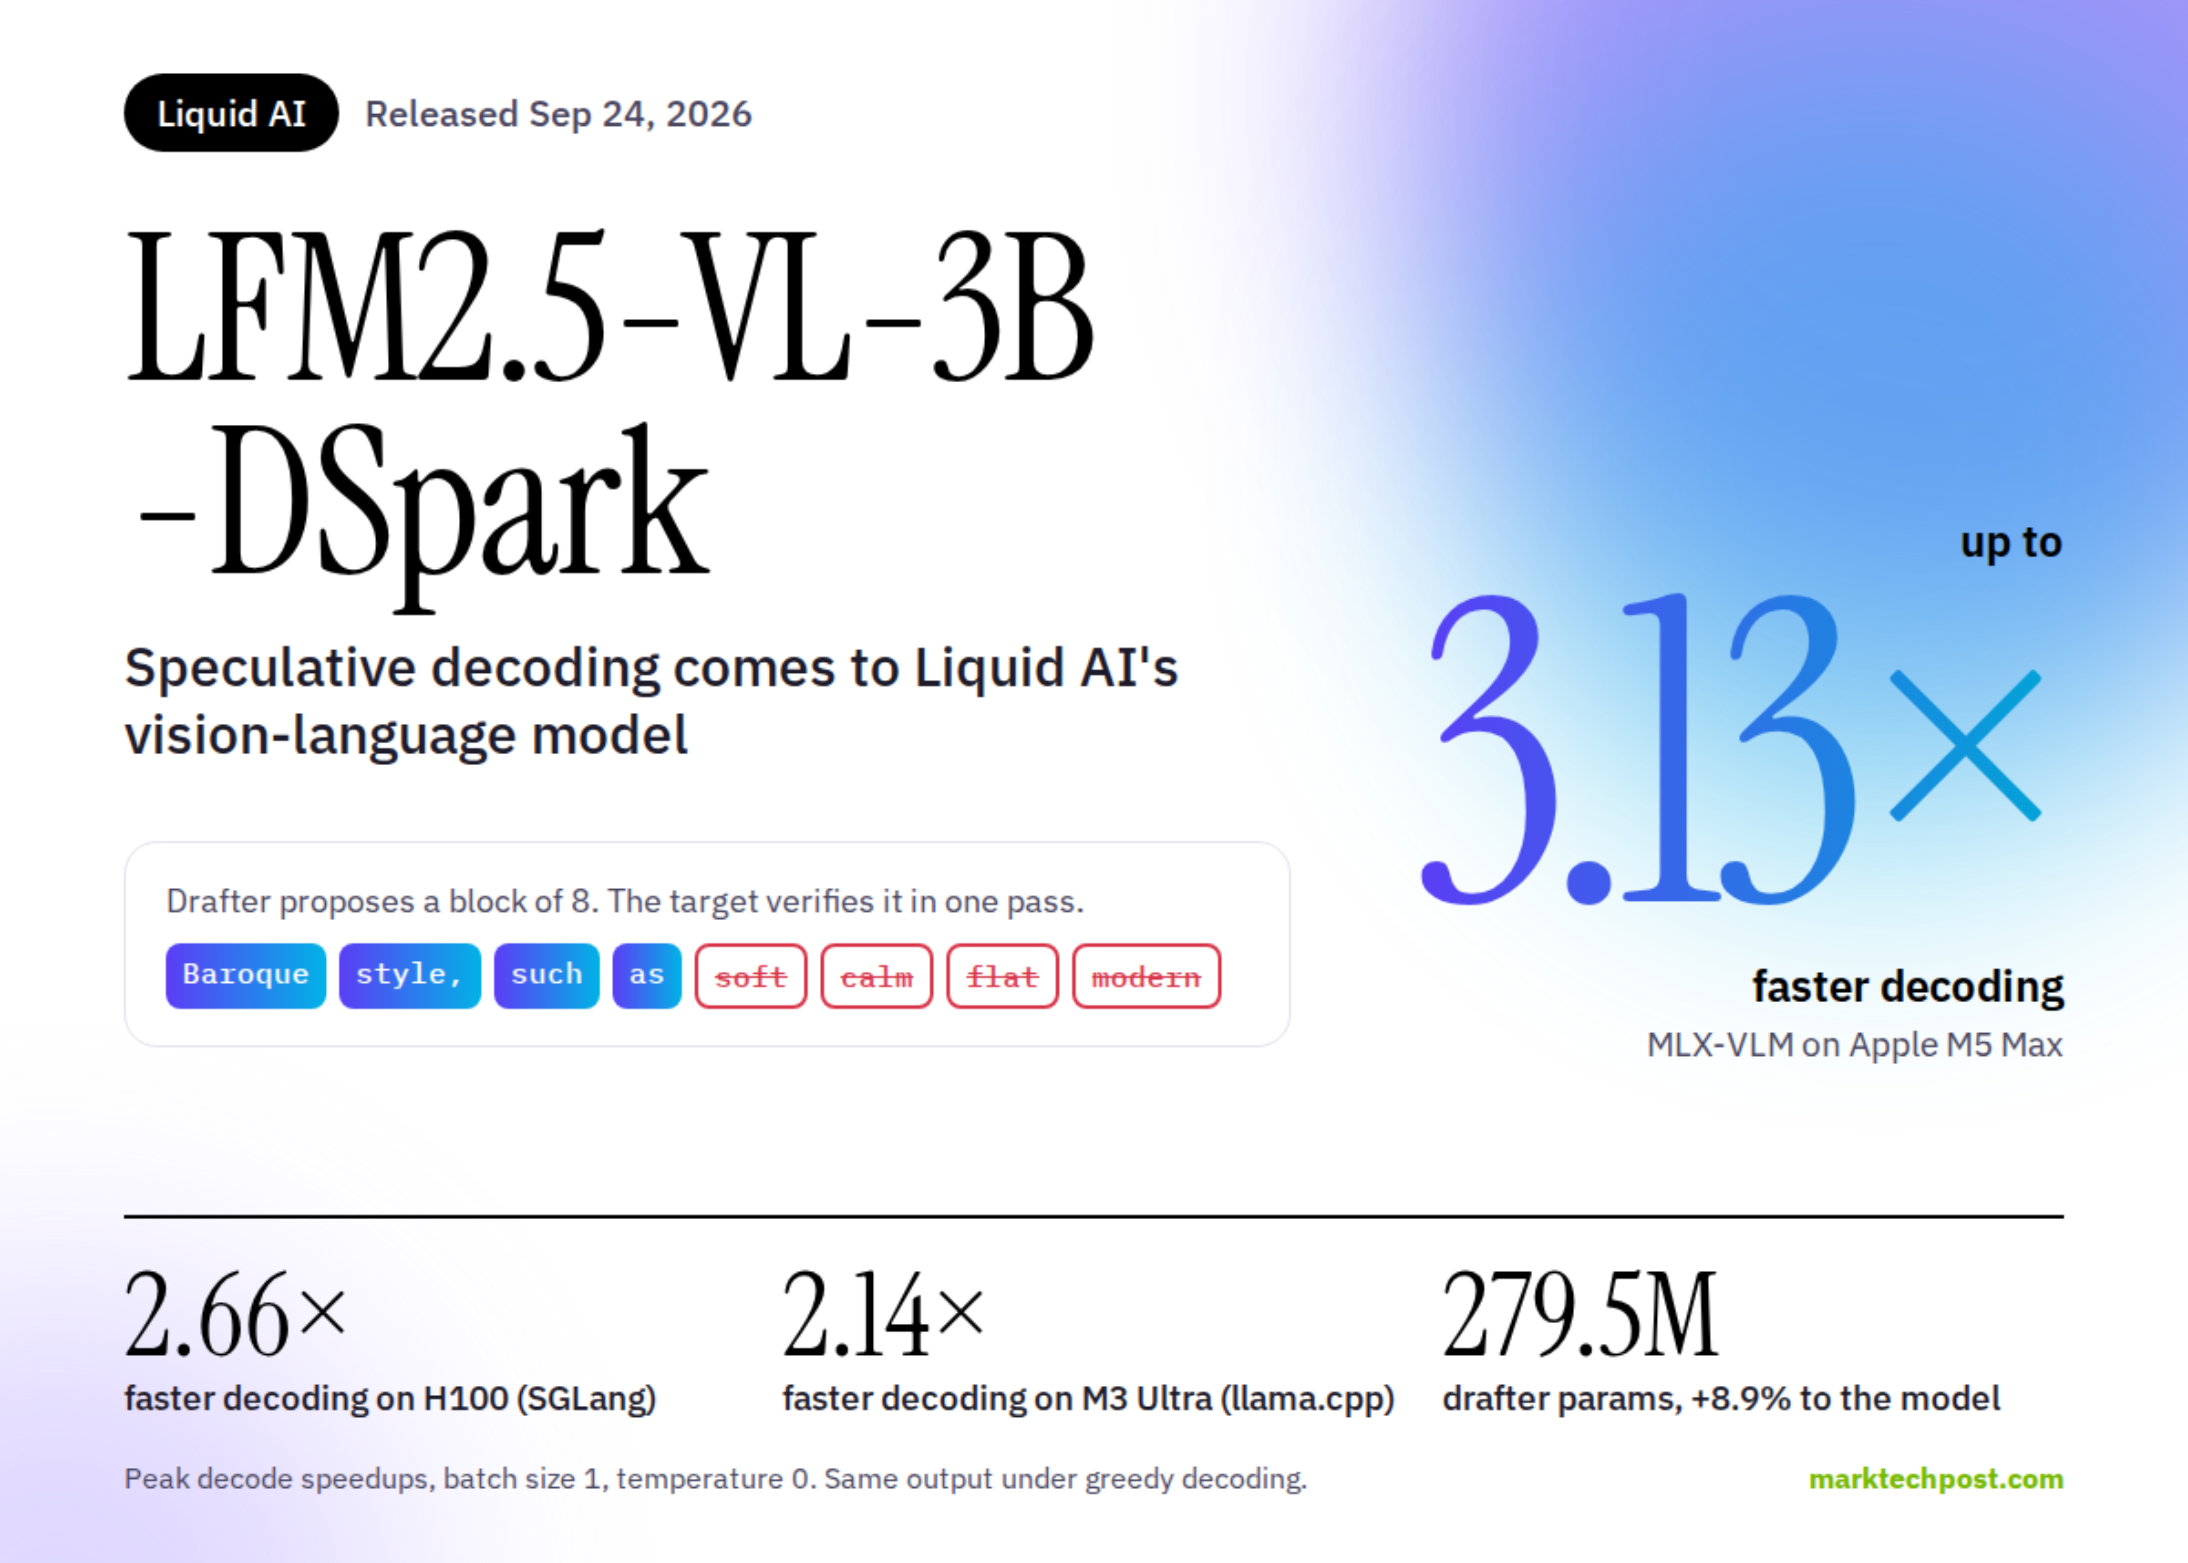
Liquid AI Releases LFM2.5-VL-3B-DSpark: Speculative Decoding for Vision-Language Models With Up to 3.13x Faster Decoding

Liquid AI has released LFM2.5-VL-3B-DSpark, a 279.5M-parameter draft model that brings speculative decoding to its LFM2.5-VL-3B vision-language model. It delivers up to 3.13x faste...

Read source
marktechpost.com /2 weeks ago

Architect Launches Liquid Inference, a Real-Time Auction for LLM Inference

Architect Financial Technologies has launched Liquid Inference, an LLM router that runs a live auction for every request. Liquid Inference is an LLM inference marketplace from Arch...

Read source
techcrunch.com /2 weeks ago

Lola Vision Systems is trying to make it easier to run AI models on chips

Lola Vision Systems is one of the Startup Battlefield 200 companies battling it out at TechCrunch Disrupt, taking place October 13-15 in San Francisco.

Read source
webkul.com /3 weeks ago

Desert Ant Labs: Exploring the Future of On-Device AI

On-device AI runs specialized models directly on a user’s device instead of sending every request to the cloud. Cloud-based AI offers powerful models but introduces latency, infras...

Read source
dev.to /3 weeks ago

A 180B model that tops seven Hugging Face leaderboards now runs on a laptop — no GPU needed

Running a frontier-class model used to mean a rack of data-center GPUs. Not anymore. VIDRAFT has released POCKET-Darwin-180B, a compressed build of Darwin-180B-RSI — the model tha...

Read source
marktechpost.com /2 days ago

Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms LFMs

Liquid AI released RIPL, a real-time inference engine for its LFM models. On one B200, LFM2.5-1.2B on RIPL showed 14.4 to 28.4x lower p95 latency than Qwen3.5-0.8B on vLLM. The pos...

Read source
habr.com /2 weeks ago

[Перевод] Запускаем LLM локально на Windows: WSL2, Docker, CUDA и vLLM

Большинство инструкций по локальному запуску LLM сводятся к одной-двум командам: вставьте их в терминал, дождитесь загрузки модели и готово. Такой подход работает ровно до первой о...

Read source
aws.amazon.com /1 week ago

Deploy decision models with llama.cpp on Amazon SageMaker AI

Learn how to deploy decision models with llama.cpp on Amazon SageMaker AI. This technical how-to serves OpenAI-compatible chat completions with the AWS Deep Learning Container for...

Read source
medium.com /2 days ago

âš¡ TensorRT Tuning in Practice: A Step-by-Step Latency Ladder for Real-Time Detection

Which knob moves latency, which moves throughput, and which one quietly breaks accuracy, with a worked build sequence on YOLO26 and a…Continue reading on Medium »

Read source
pandaily.com /18 hours ago

Dawa Technology's Scenes AI Runs a 34B Real-Time World Model at 720p and 25fps on One RTX GPU

Chongqing-based Dawa Technology's Scenes AI updates a persistent world state from a normal camera feed. It runs a 34B sparse model at 720p and 25fps on a single consumer RTX card.

Read source
electronicsforu.com /1 month ago

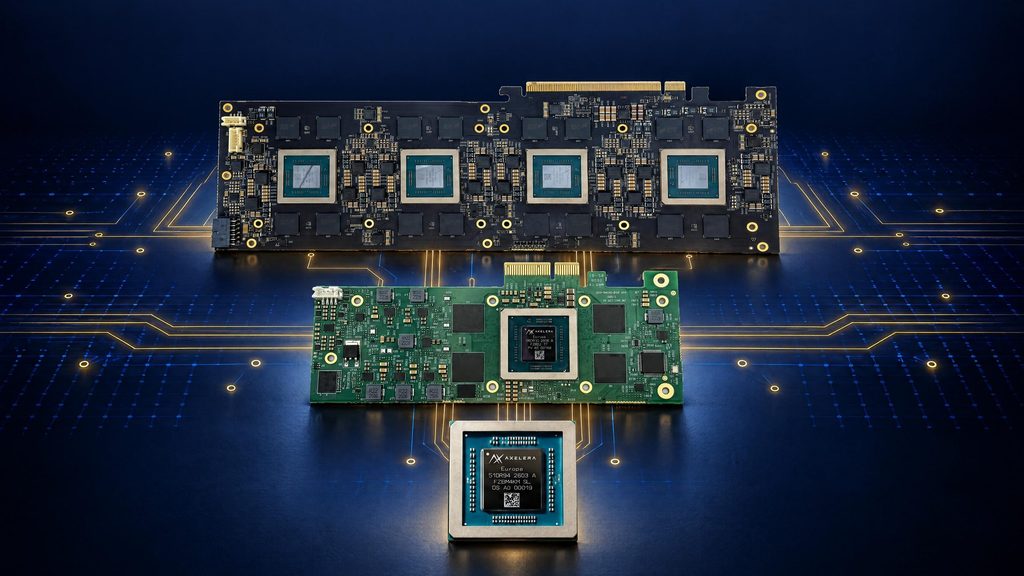
AIPU Targets Lower-Power Enterprise AI Inference

What happens when AI inference has to run continuously inside enterprise servers? An accelerator architecture targets higher inference efficiency without replacing existing infrast...

Read source
pandaily.com /2 days ago

BIGAI Spinout Tongyan Lingzhi Bets on Personal LoRA and Self-Improving AI Models

Tongyan Lingzhi, incubated by the Beijing Institute for General Artificial Intelligence, is building personal AI that stores user and team skills in lightweight LoRA weights update...

Read source
prunderground.com /1 week ago

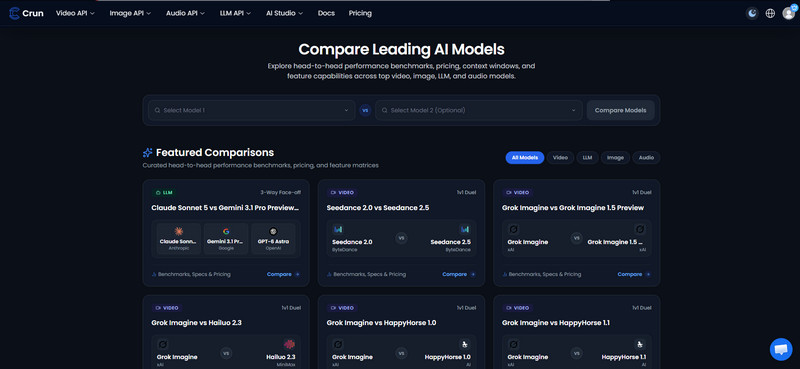
Crun AI Launches AI Leaderboard to Compare LLM, Video, Image, and Audio Models Side by Side

Crun AI unveils the AI leaderboard to compre leading models across LLM, Video, Image, and Audio by Performance and Price. The post Crun AI Launches AI Leaderboard to Compare LLM, V...

Read source
pandaily.com /1 month ago

StartLux's 27B Local Model Beats DeepSeek V4 Flash in China AI Benchmark

StartLux's 27-billion-parameter local model took second in the CAICT MCP test, outpacing DeepSeek-V4-Flash and reaching trillion-parameter capability territory.

Read source
pandaily.com /1 month ago

Shanghai AI Lab Releases Atria Dawn Preview, a 744B MoE Agentic Model

Shanghai Artificial Intelligence Laboratory open-sourced Atria Dawn Preview under MIT, a 744B MoE agentic model built on GLM-5.2 with 256K context, FP8 weights, and a leading Autom...

Read source
cloud.google.com /4 days ago

Announcing llm-d 1.0: Open distributed inference for agents on Google Cloud TPUs and GPUs

Today at the PyTorch Conference, we released llm-d 1.0, an open-source, Kubernetes-native stack for distributed LLM inference. Co-founded by Google with Red Hat, IBM and others, we...

Read source
unbox.ph /1 month ago

Smart makes AI accessible to Filipinos with Ai.Smart

Smart is making AI more accessible to Filipinos with the launch of AI.Smart, a one-stop AI workspace that brings multiple advanced AI models and tools into one easy-to-use experien...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Loadai

9to5mac.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

cloudblog.withgoogle.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

electronicsforu.com

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source