How LLMs Work: Transformer Architecture Explained | Simplilearn
TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...
Search fresh public links, source activity, and ready-to-use post angles for Large Language Model.
Fresh curated links around Large Language Model are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
TL;DR: Large language models process text through tokenization, embeddings, transformers, and self-attention. They are trained through pre-training, fine-tuning, and alignment, the...
The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »
Large Language Models can now process hundreds of thousands, and sometimes even millions, of tokens.Continue reading on Medium »
Large Language Models (LLMs) have transformed the way applications process and generate natural language. They are widely used in chatbots, search systems, coding assistants, docum...
Large language models have become easier to integrate into applications, but running them efficiently is still a major engineering challenge. As the number of users and requests in...
Large language models can perform many tasks without any additional training. They can answer questions, summarize text, generate code, classify information, and interact with tool...
Large language models can write essays, generate code, explain concepts, summarize documents, and hold conversations.Continue reading on Medium »
Aleph Alpha has released Kolibri, a 78.1B-parameter English-German Mixture-of-Experts model that activates only 3.46B parameters per token. It has a 1M-token context and per-reques...
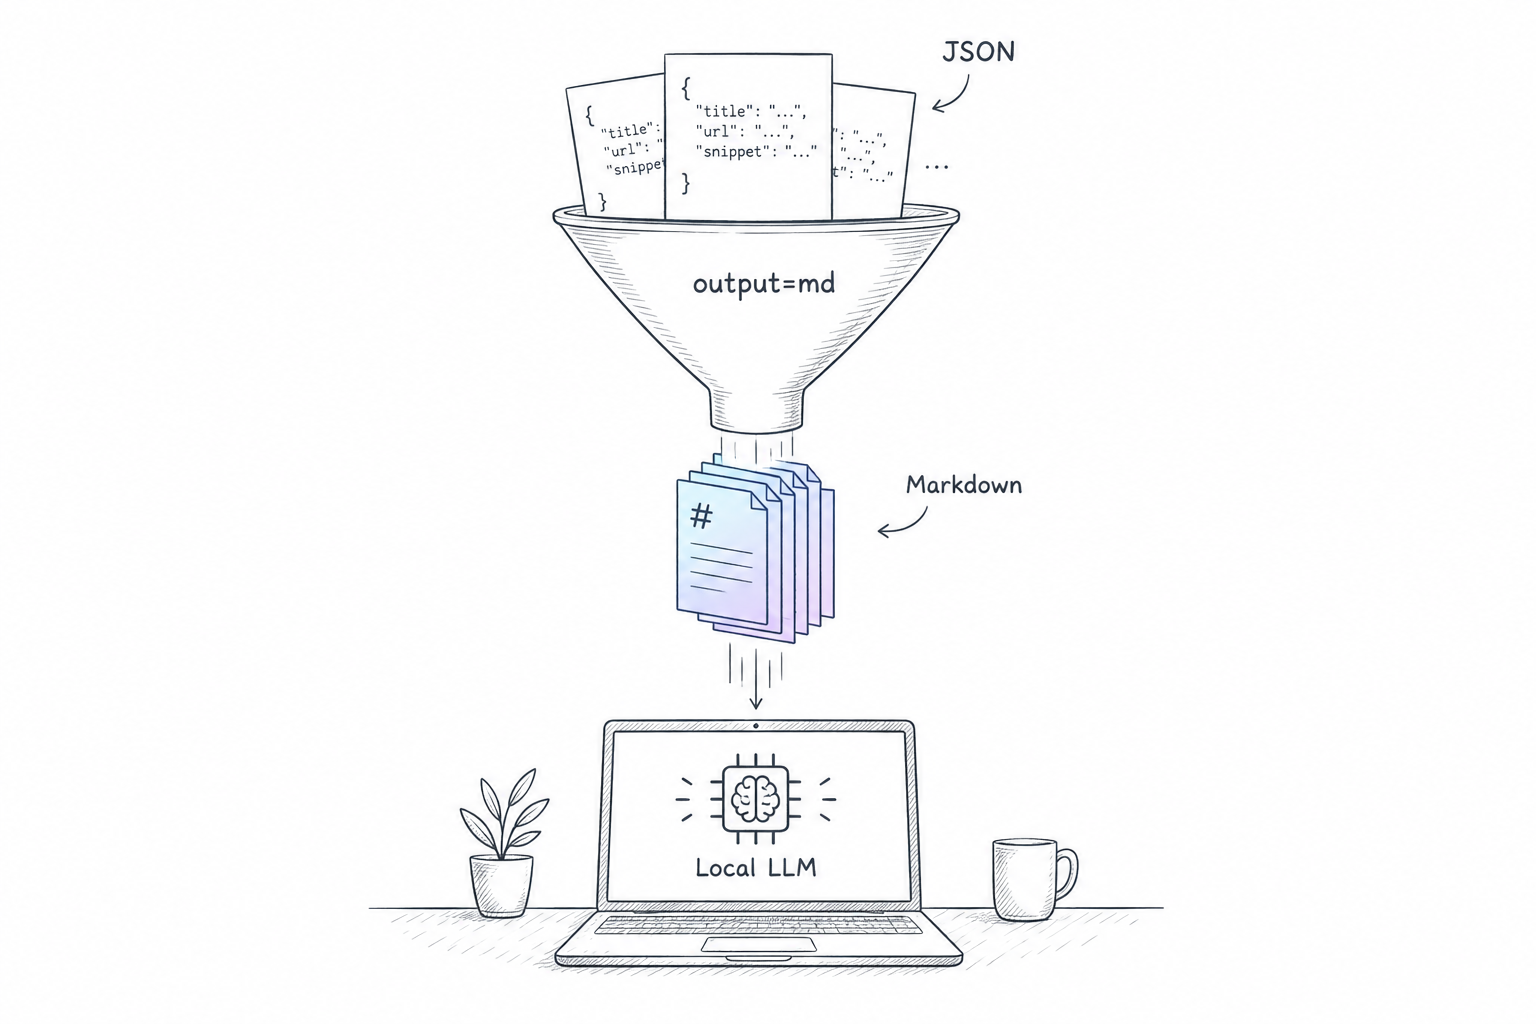
Use SerpApi's Markdown output and the JSON Restrictor to give a local LLM more web search data in the same context window, tested on four models in LM Studio.
Large Language Models (LLMs) are commonly accessed through cloud APIs provided by services such as OpenAI, Anthropic, or Google Gemini. However, there are many situations where dev...
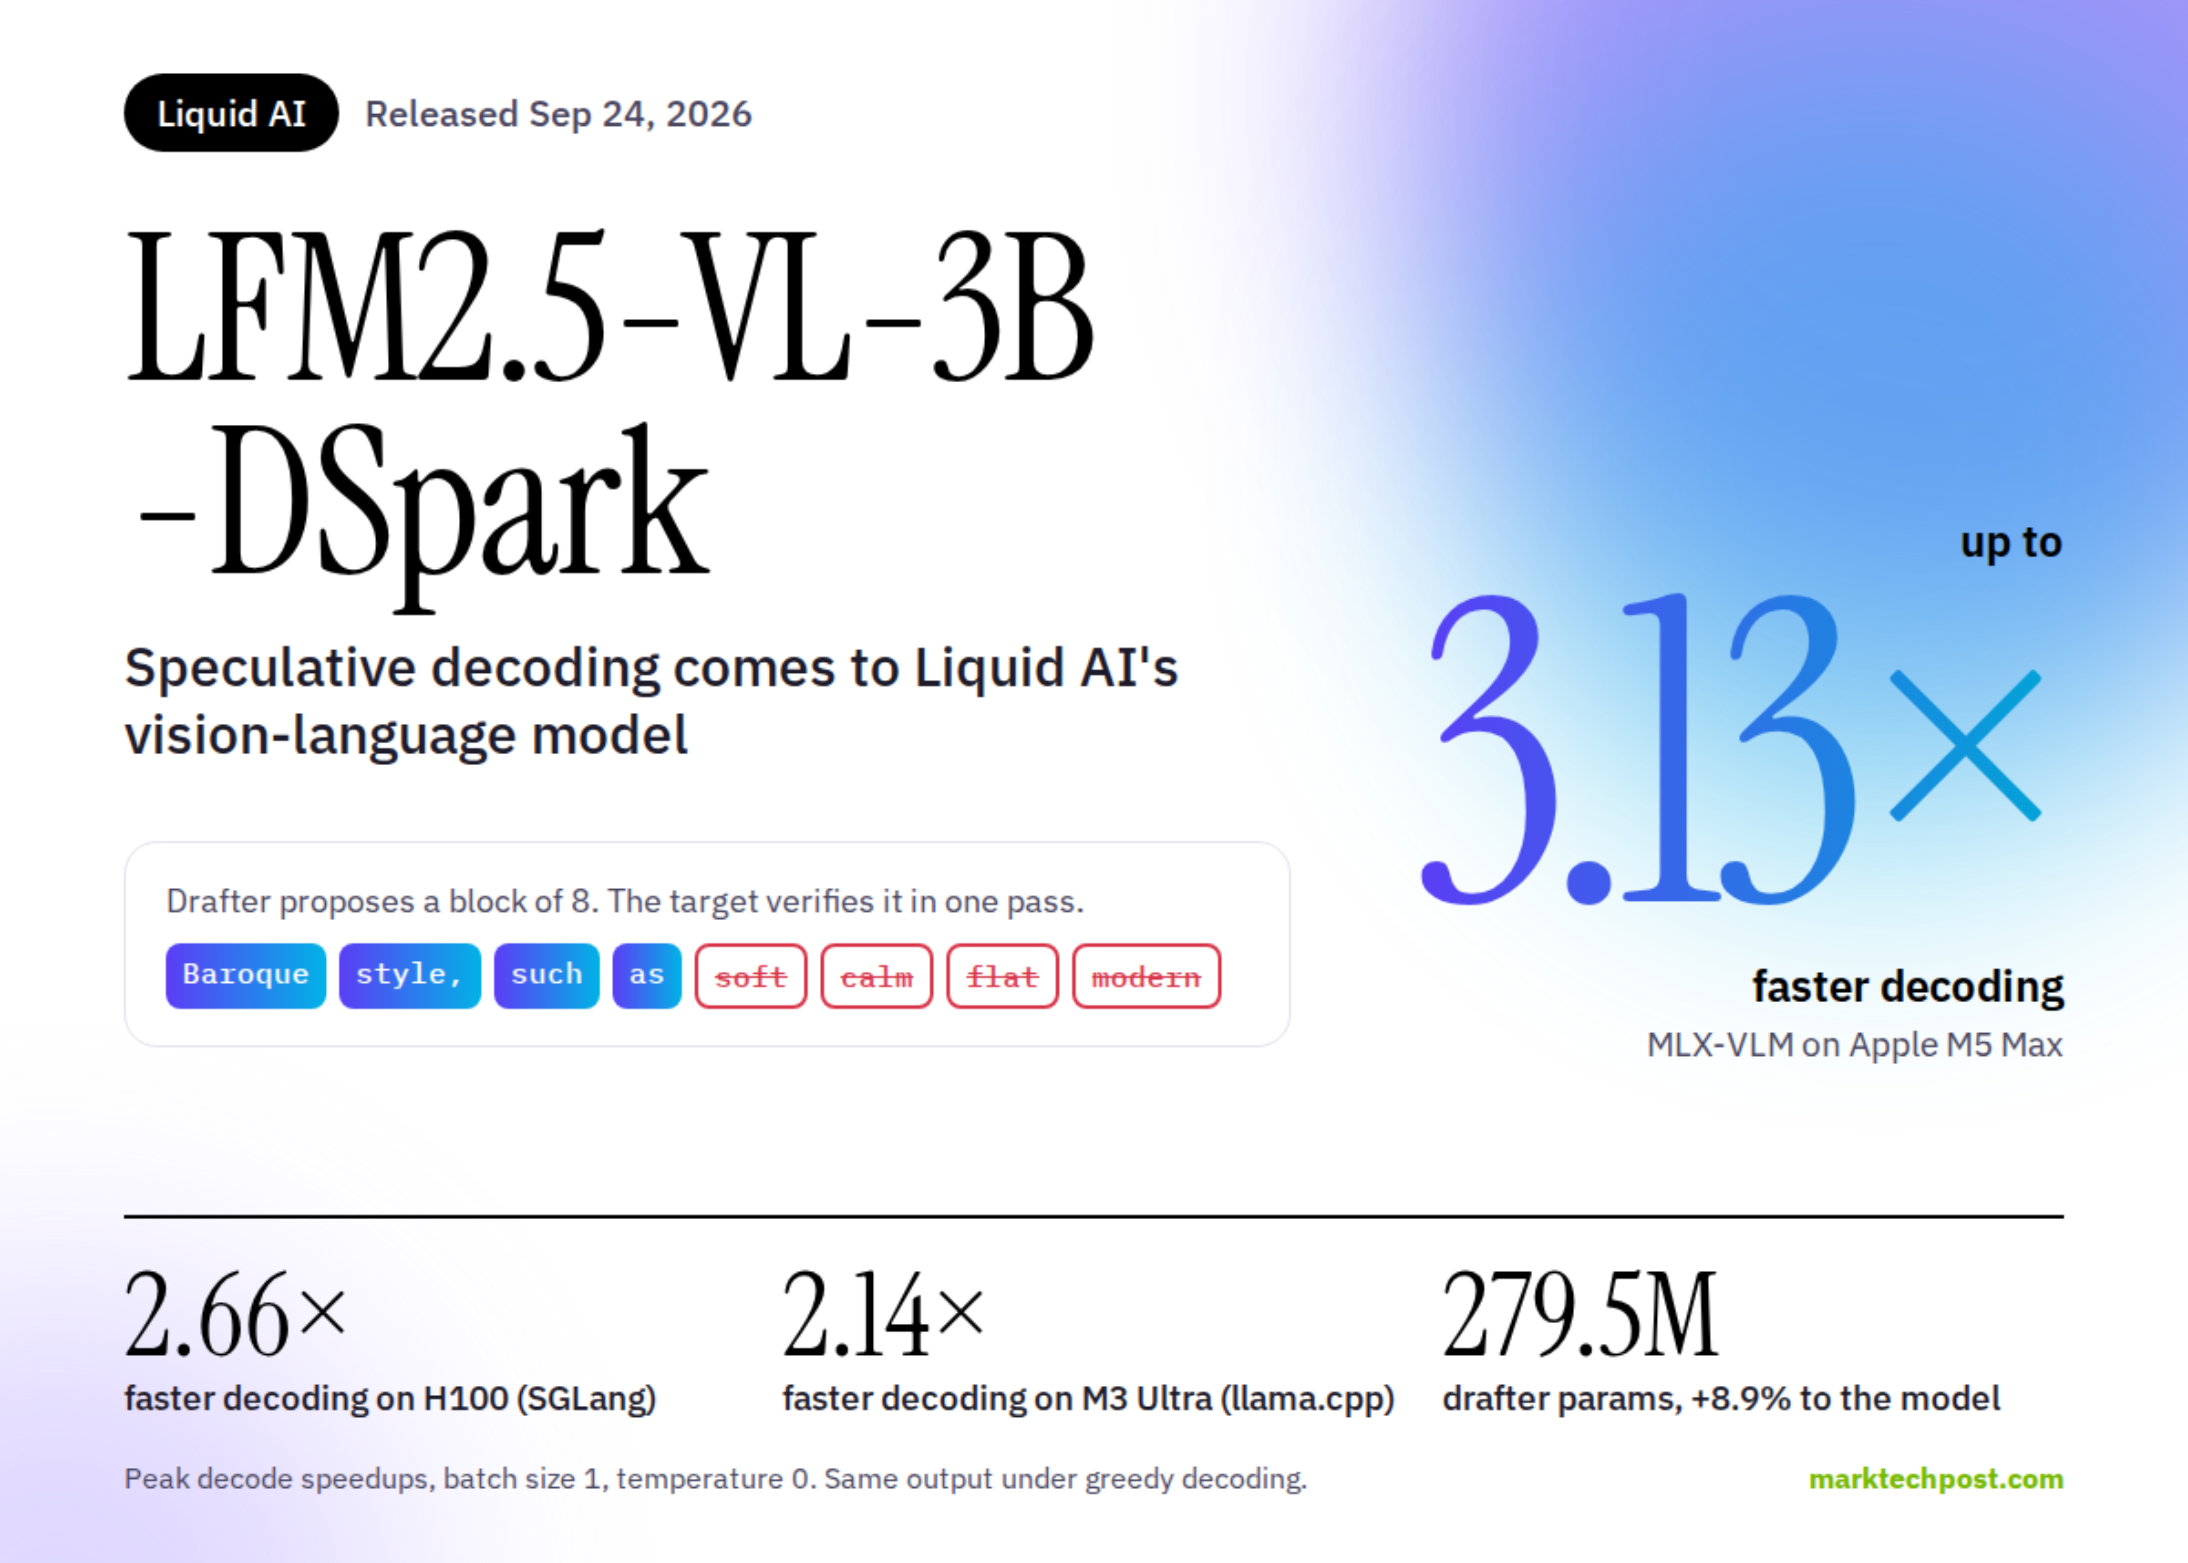
Liquid AI has released LFM2.5-VL-3B-DSpark, a 279.5M-parameter draft model that brings speculative decoding to its LFM2.5-VL-3B vision-language model. It delivers up to 3.13x faste...
Fine-tuning large language models isn’t a one-size-fits-all exercise anymore. What started as a technique mostly discussed in AI research…Continue reading on Medium »
Даже идеальная модель с бесконечным объемом текста не восстановит ту часть смысла, которая никогда не была закодирована в языковой форме.Представьте фразу в рабочем чате: «он снова...
Bilibili's Index LLM team released Index-Translate under Apache-2.0: 2B, 9B and 35B-A3B preview text models for 150 languages, plus dubbing, syllable-control and long-document vari...
Open-source large language models are AI systems you can study, adapt, and use without being locked into one company’s platform or rules. In 2025, they’re giving rese...
Ant Group's inclusionAI published Ling-3.1-flash weights on Hugging Face under the MIT license, a 560B hybrid-linear MoE with 25B active parameters per token and a 1M-token context...
Когда речь заходит о ЛЛМ и классификации, первая мысль — попросить модель сгенерировать класс через промптирование модели с описанием правил и добавлением примеров. Для небольшого...
Ant Group and inclusionAI open-sourced Ling-3.0-flash-VL, a 124B MoE multimodal model with 5.5B active parameters. BF16 and FP8 weights arrived September 9 with a vision feedback l...
On August 28, Tencent Hunyuan released and open-sourced Hy4 preview, its next-generation large language model with 770 billion total parameters and a context window exceeding 1 mil...
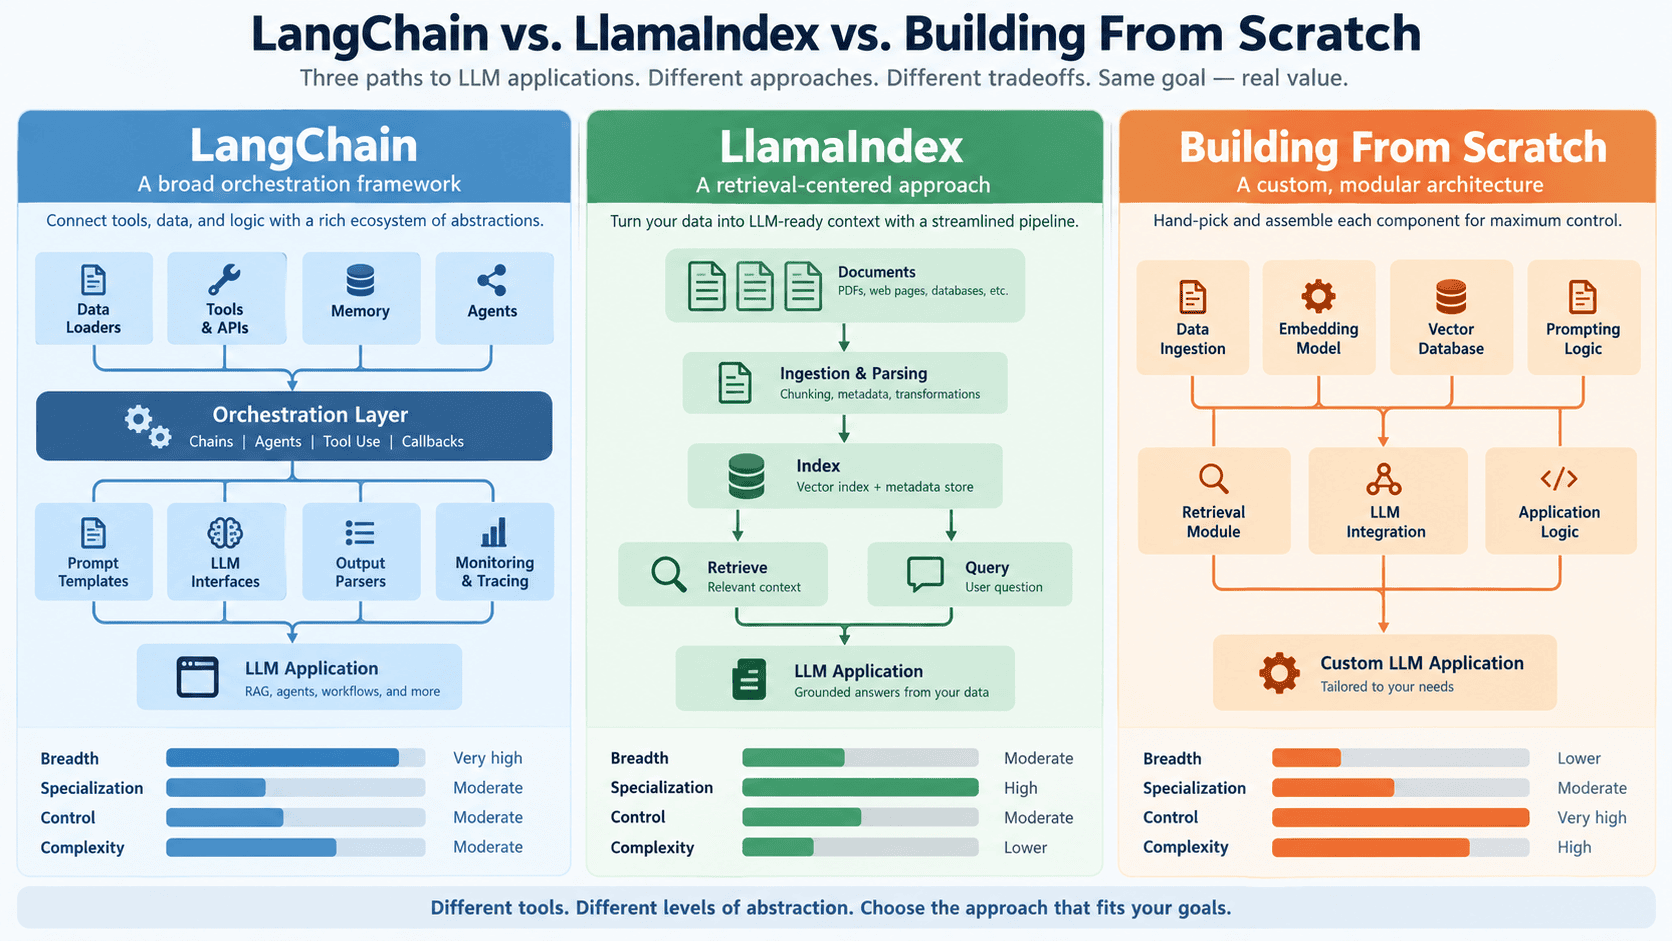
Choosing the right framework for your large language model application comes down to one question: what are you actually optimizing for?
Z.ai has released GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series — a 320B-total / 18B-active MoE with a 1,048,576-token context window, MIT-licensed weights...
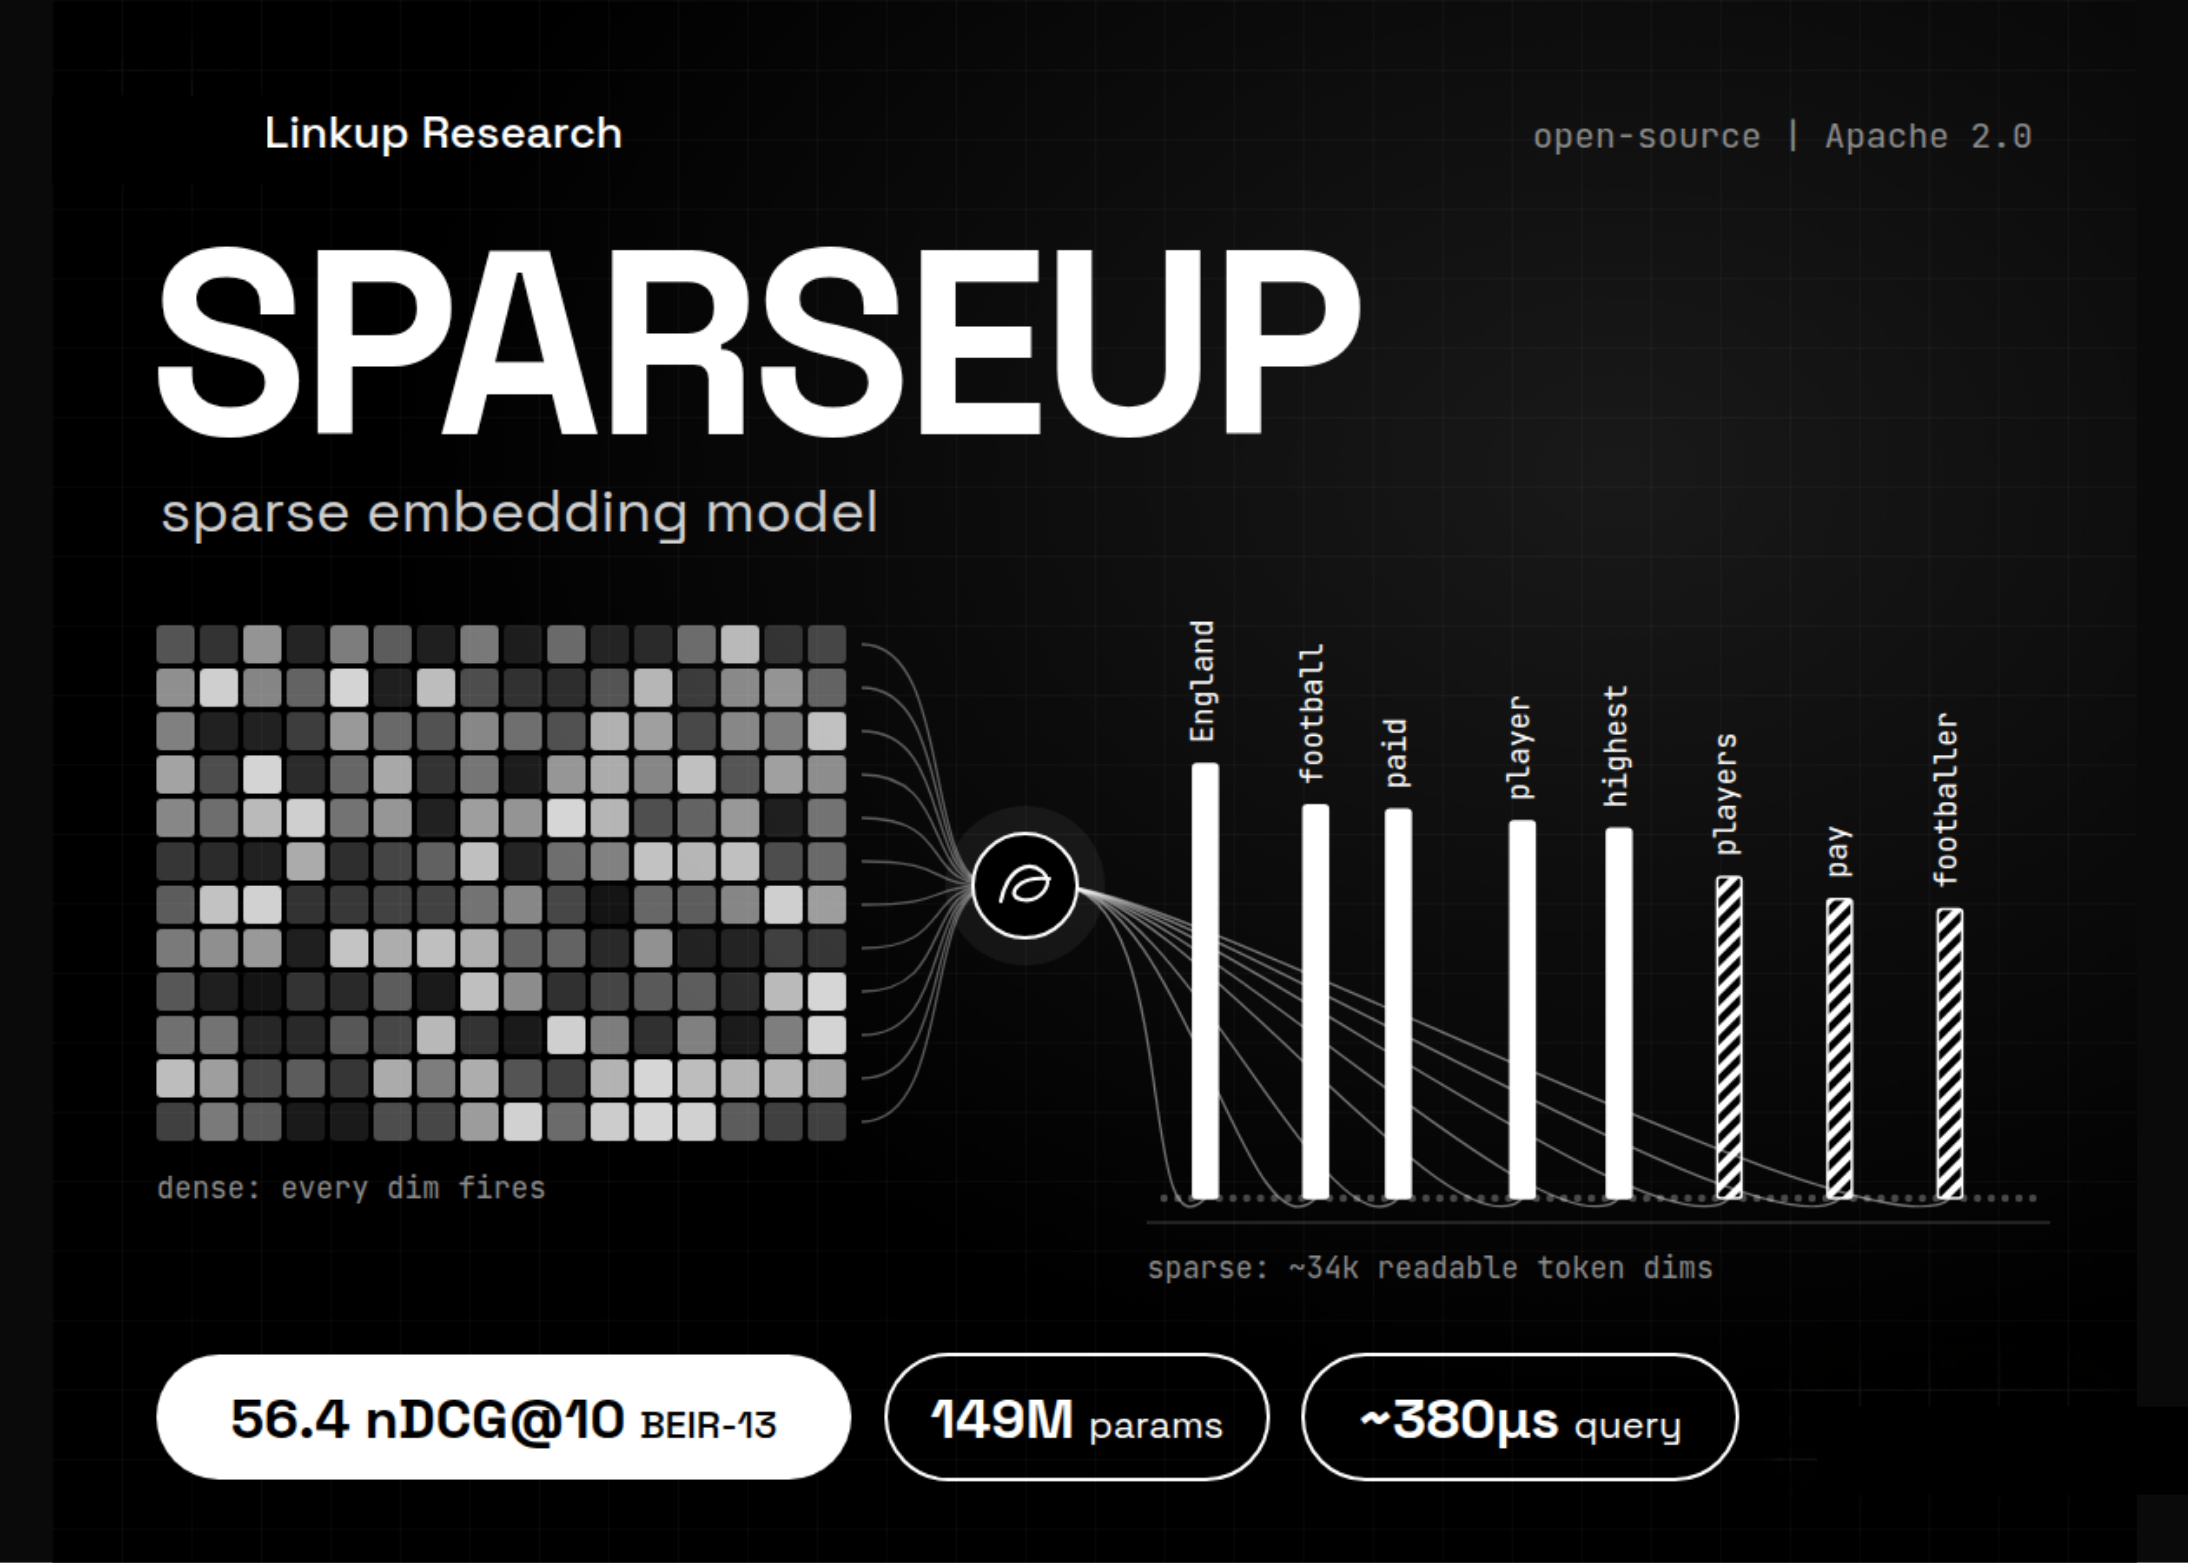
Linkup Research has released SPARSEUP, an open-source sparse embedding model built on a 149M-parameter ModernBERT backbone. It scores 56.4 nDCG@10 on BEIR-13, which Linkup calls th...
Large language models are good at understanding natural language, but applications usually need information in a predictable form. A customer support application, for example, may...
The biggest shift in local AI is no longer benchmark leadership but the ability to deliver language intelligence directly inside desktop and mobile applications without depending o...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.