Latest updates for Large Datasets

Fresh curated links around Large Datasets are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • Load terabytes of data in minutes into Lakebase Postgres
  • Efficiently Manage Complex Data Sets with Data Visualization
  • I Compacted 1,000 Apache Iceberg Files Into 6. Here’s What Happened to Query Performance.

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

databricks.com /2 weeks ago

Load terabytes of data in minutes into Lakebase Postgres

Operational databases like Postgres are built to reliably execute highly concurrent...
Read source
everlaw.com /1 month ago

Efficiently Manage Complex Data Sets with Data Visualization

Efficiently Manage Complex Data Sets with Data Visualization by Giulianno Lopez

Read source
towardsdatascience.com /3 weeks ago

I Compacted 1,000 Apache Iceberg Files Into 6. Here’s What Happened to Query Performance.

Benchmarking the impact of fewer, larger files across three SQL workloads The post I Compacted 1,000 Apache Iceberg Files Into 6. Here’s What Happened to Query Performance. appeare...

Read source
dev.to /1 day ago

Four big local LLMs on one RTX 5090 and 128 GB of RAM, benchmarked side by side

One RTX 5090, 128 GB of RAM, and four open models from 125B to 748B parameters. Over the past weeks I got each of them running on the same workstation, on three different runtimes....

Read source
flowingdata.com /3 days ago

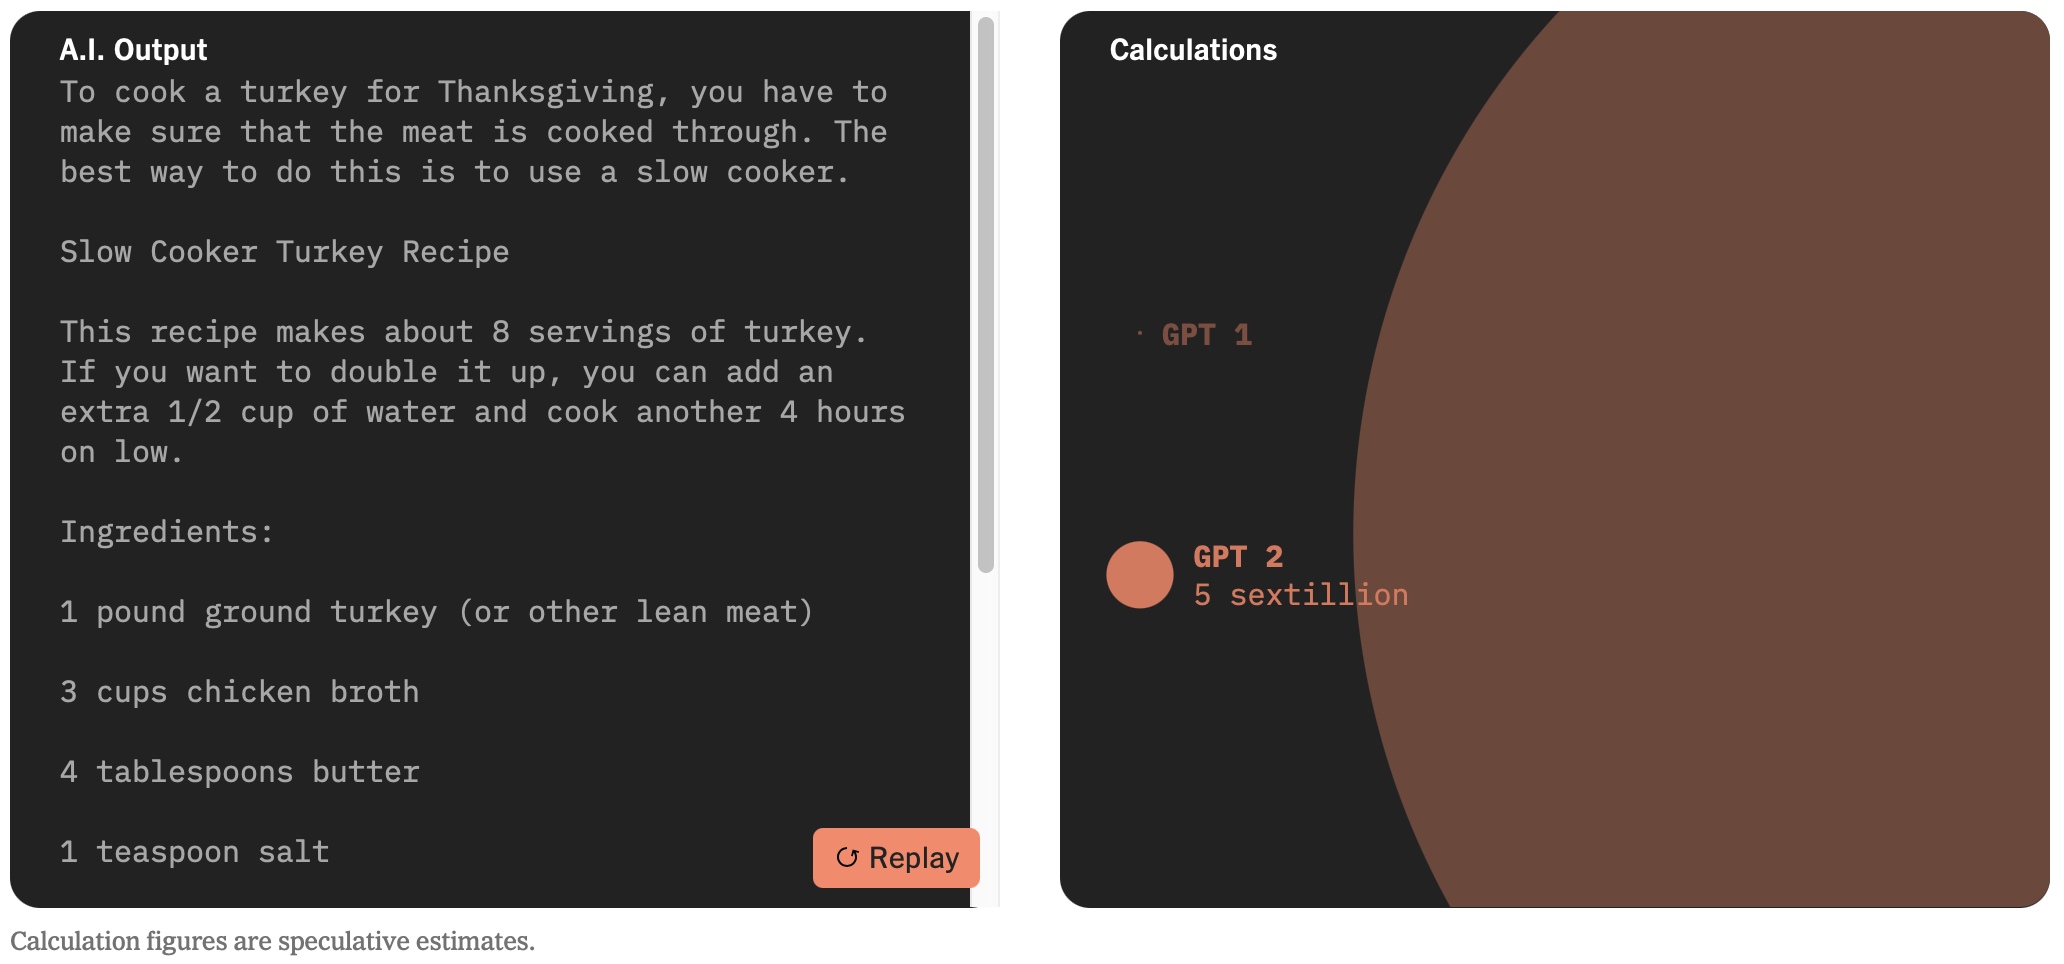
Calculation volumes for AI training

More big numbers coming in. For NYT’s the Upshot, Aatish Bhatia demonstrates the…Tags: Aatish Bhatia, calculations, scale, training, Upshot

Read source
dev.to /3 weeks ago

Stream 50 million rows without OOM: Lazy chunked Query Streaming.

Stream 50 million rows without OOM: Lazy chunked Query Streaming. Day 09 of the WClickHouse Open-Source Engineering Series. You don't need 64GB of RAM to process millions of C...

Read source
machinelearningmastery.com /2 days ago

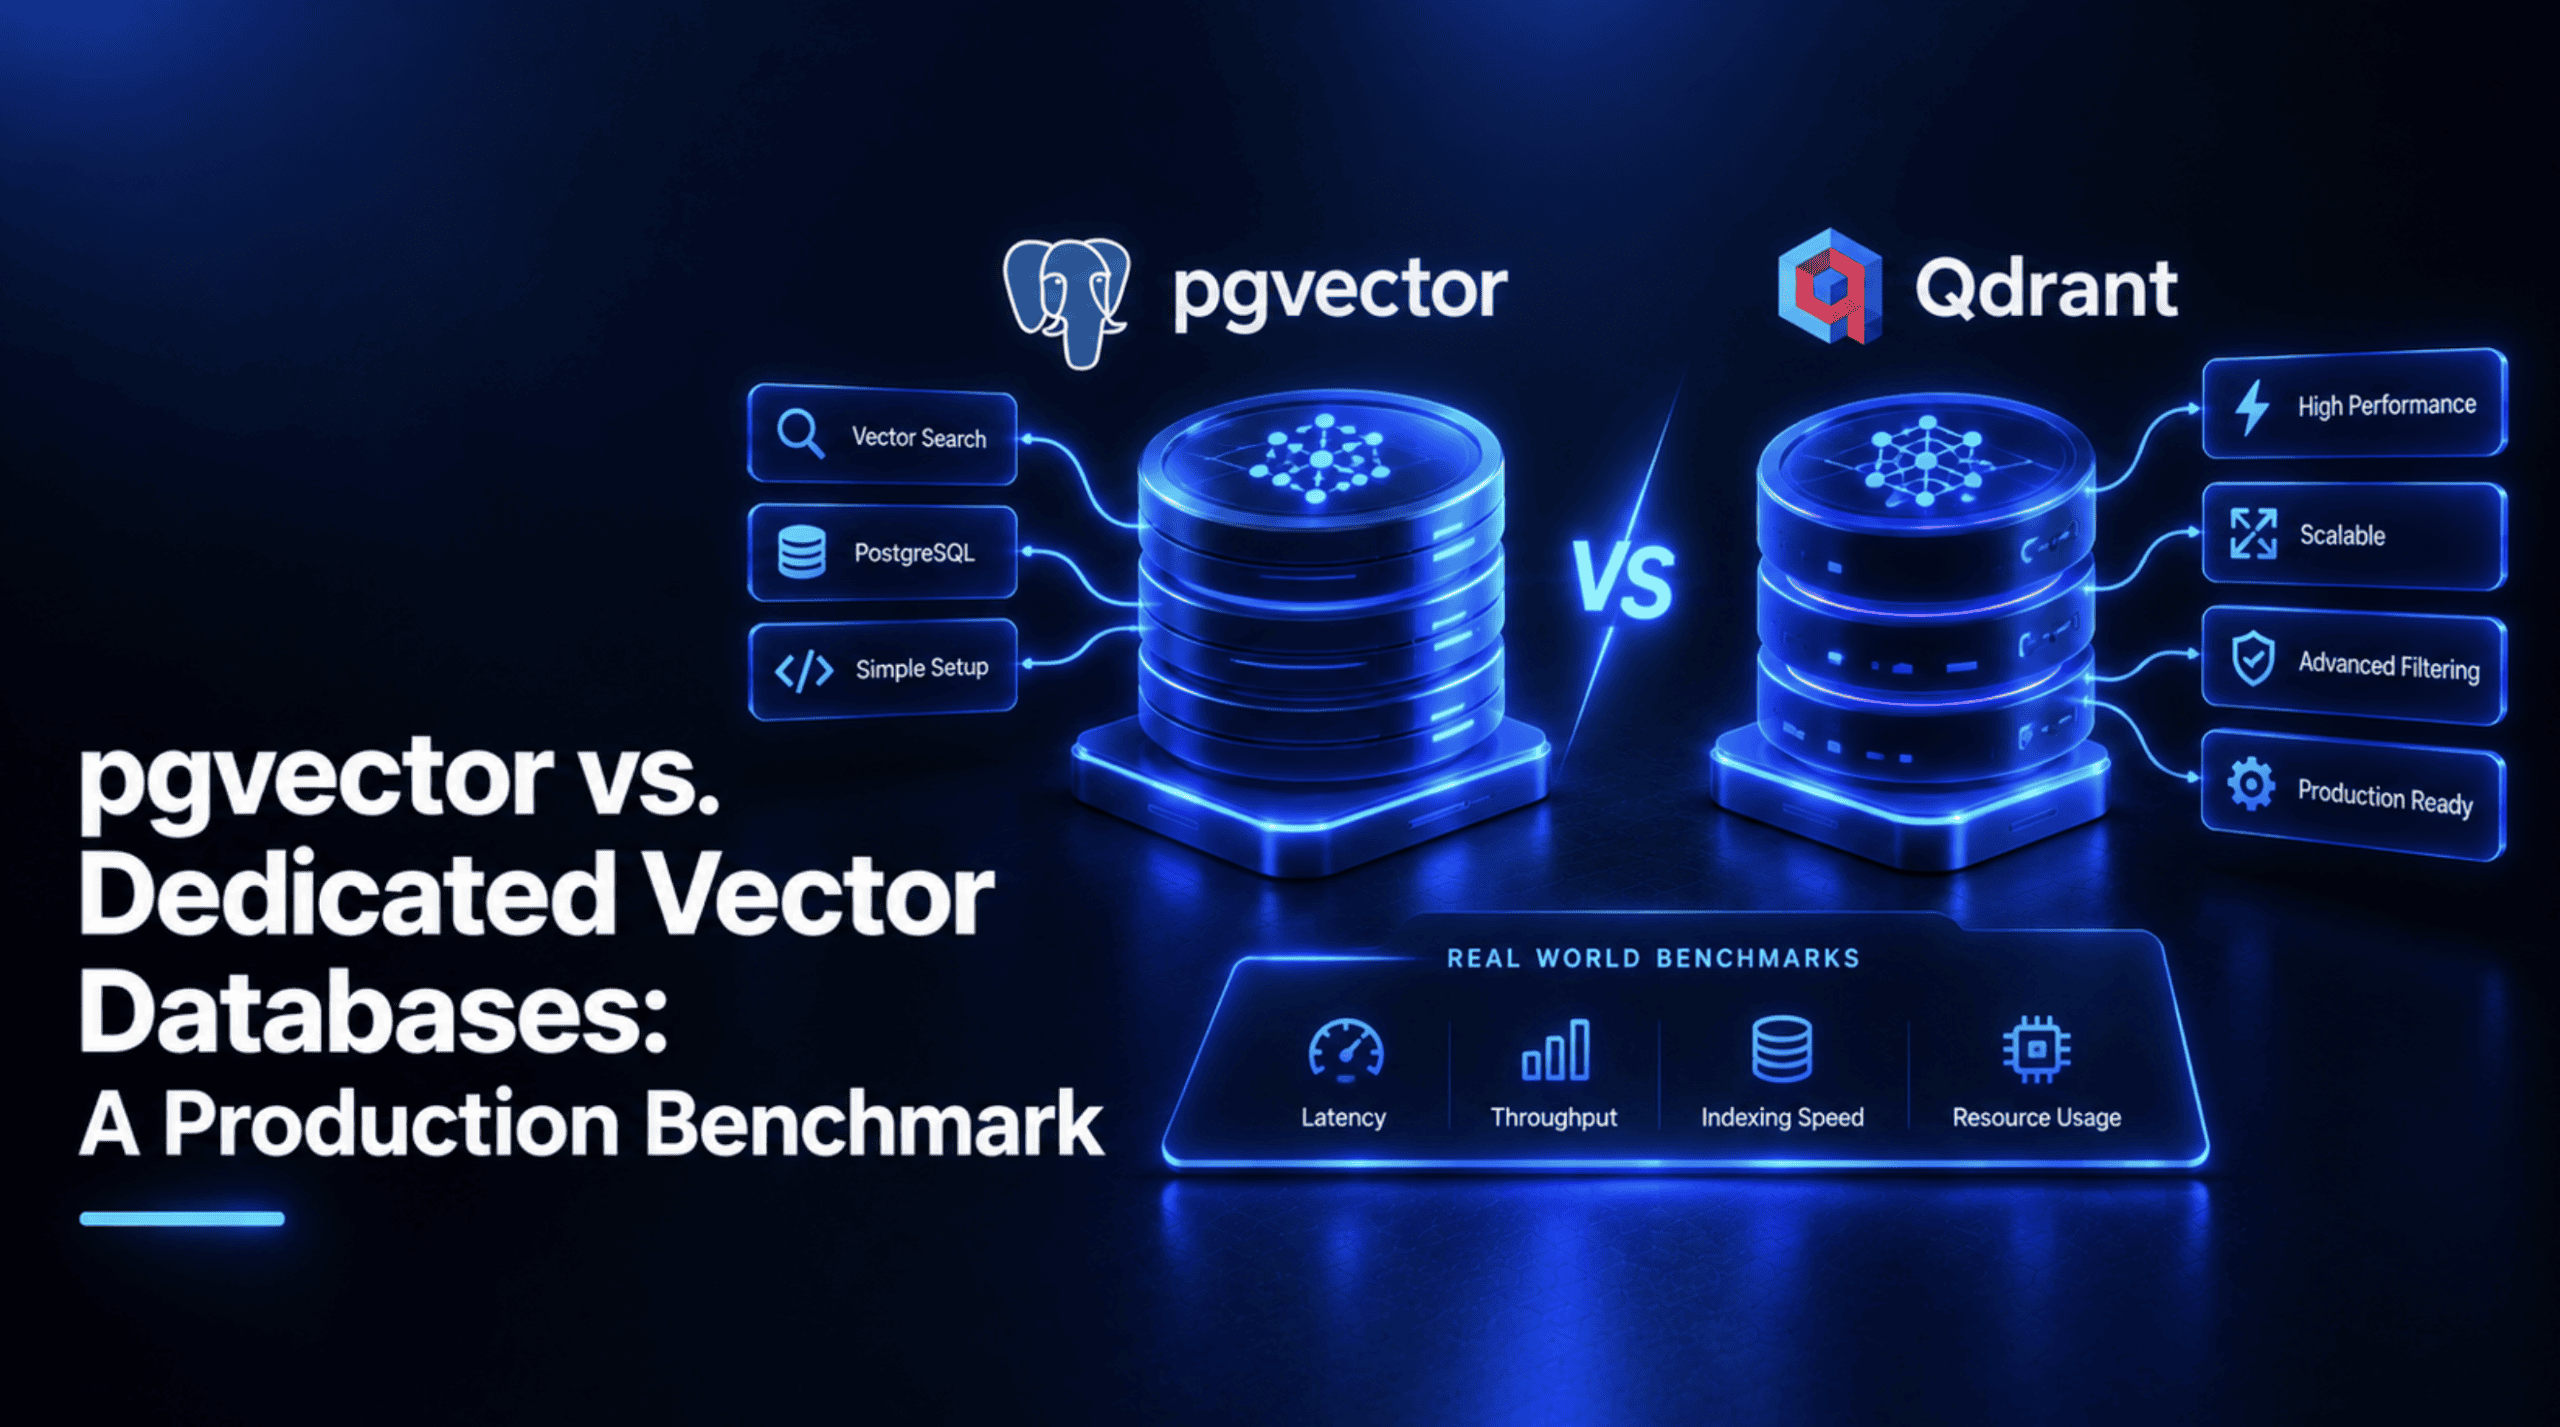
pgvector vs. Dedicated Vector Databases: A Production Benchmark

Run this on a typical laptop and both systems will report latencies in the low single-digit to tens of milliseconds range, with the exact numbers depending heavily on your CPU, ava...

Read source
dzone.com /1 month ago

Improving Repeated Analytics Workloads With Databricks Disk Cache

In many analytics platforms, there are performance issues that do not always come from complex transformations. Sometimes the bottleneck is much simpler: the same large datasets ar...

Read source
databricks.com /1 week ago

Sizing Lakebase Search: lessons from a real app and 4 million passages

Slide Hub is an internal Databricks app. Field engineers use it to find and reuse...

Read source
habr.com /2 days ago

Как читать таблицу на 100 млн строк и не положить ни память, ни базу

DVT — open-source платформа визуального ETL: пайплайн собирается из нод (чтение → преобразования → запись) и выполняется на воркерах поверх Dask. Я разрабатываю бэкенд DVT, в стать...

Read source
kdnuggets.com /11 hours ago

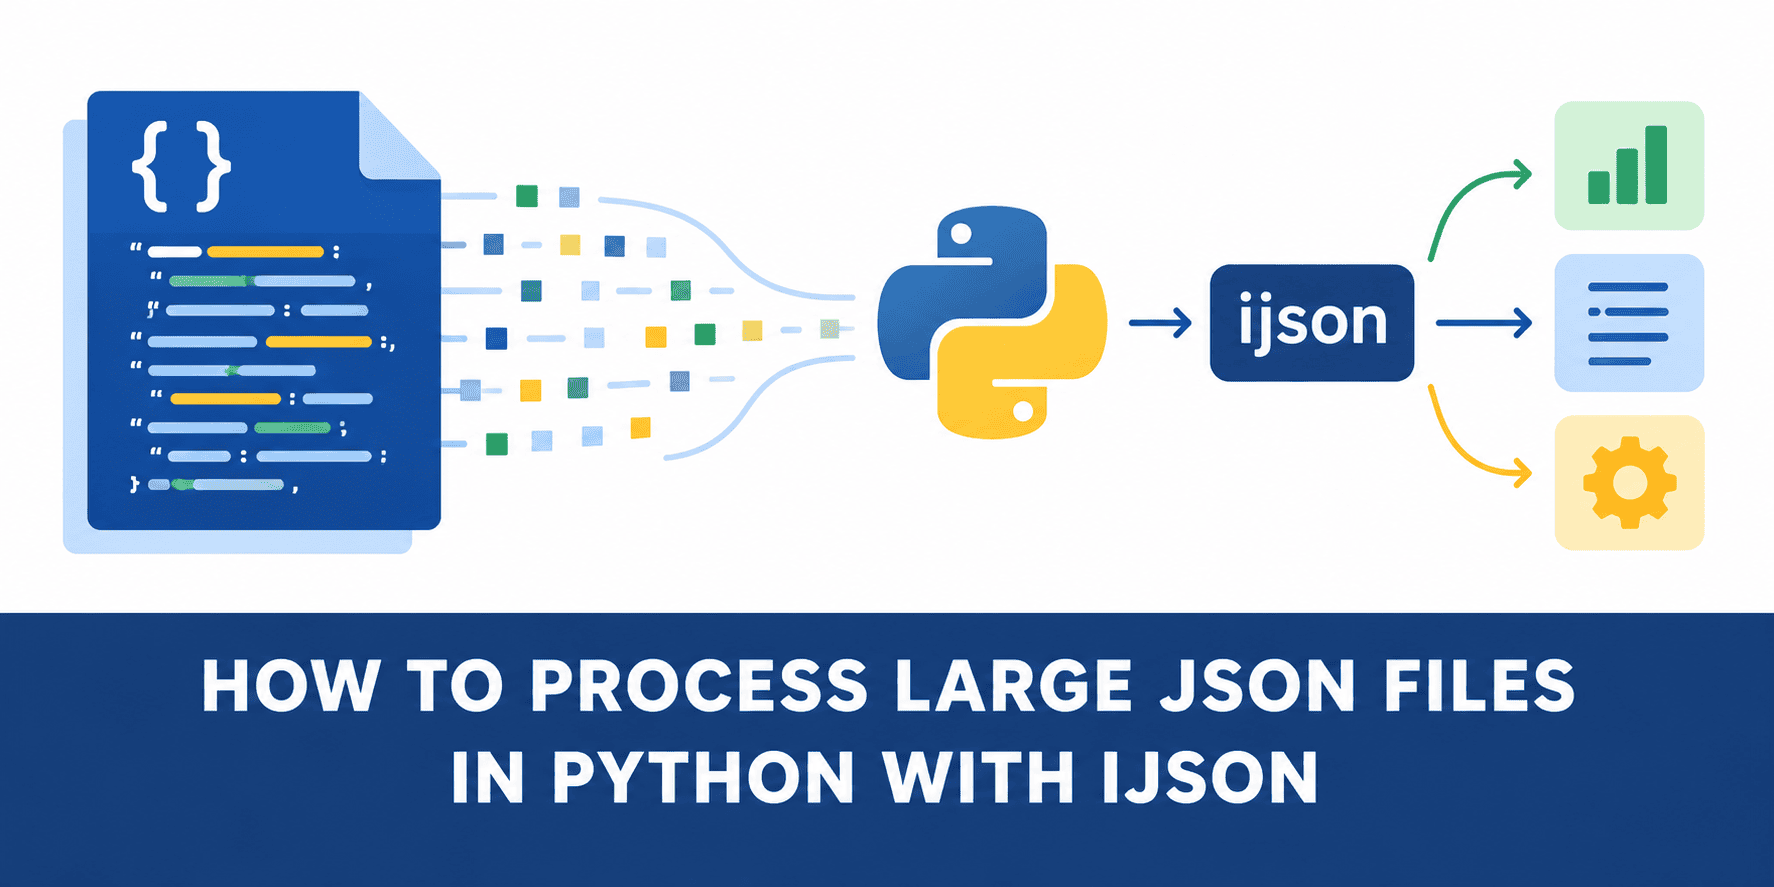
How to Process Large JSON Files in Python With ijson

I loaded a large JSON file in Python and watched memory jump from 43 MB to 808 MB. Here’s what happened and how streaming changed everything.

Read source
databricks.com /1 month ago

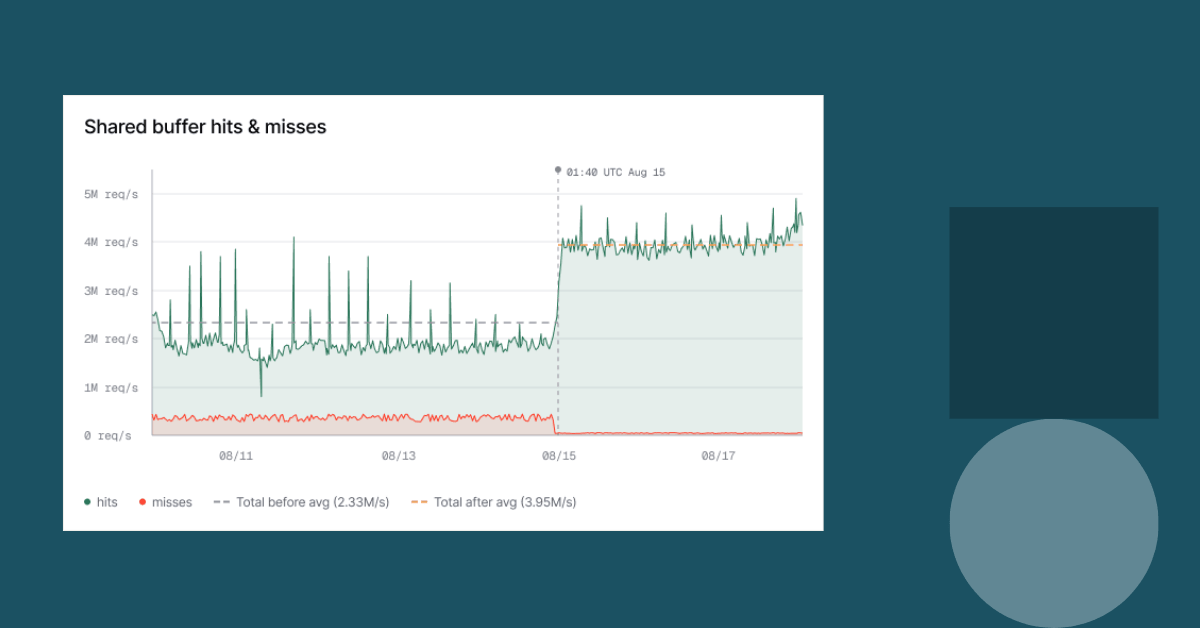
Improving Lakebase Postgres compute cache

The disaggregated storage model of Lakebase Postgres provides a feature rich, flexible...

Read source
dev.to /3 weeks ago

Feeding the OLAP beast: ClickHouse massive bulk ingestion steps.

Feeding the OLAP beast: ClickHouse massive bulk ingestion steps. ClickHouse is a columnar beast, but treating it like MySQL by inserting row-by-row will bring your cluster to its...

Read source
towardsdatascience.com /1 month ago

One Document Type, a Million Files: Structured Extraction into the SQL Table RAG Queries

Enterprise Document Intelligence [Vol.1 #14C] - One hour with two people, six to ten fields, and the two signals that separate a real column from one that will break a filter later...

Read source
databricks.com /2 weeks ago

Biomedical Imaging's Real Bottleneck Is the Data, Not the Model

Part I — The problemFour sectors, one bottleneckHospitals and health systems generate...

Read source
cryptobriefing.com /1 month ago

Chutes AI and Harvard release public dataset of 6.12 billion LLM requests

The dataset's release could significantly advance AI research, offering insights into user behavior and optimizing AI model efficiency and infrastructure. The post Chutes AI and Ha...

Read source
databricks.com /2 weeks ago

Scaling and Operating a Large dbt Project on Databricks: IFCO's Data Team on Performance, Visibility, and Debugging

AbstractIFCO runs one of the world's largest reusable packaging pools with hundreds of millions of crates and pallets...

Read source
dzone.com /1 month ago

Distributing Massive AI Models With Network-Layer Multicast

When you are pushing terabytes of weights to hundreds of GPU nodes, unicast stops being a solution. Here is what actually works — and where multicast still struggles. The Problem E...

Read source
towardsdatascience.com /1 month ago

Disaggregation Is a Thousand-GPU Problem

Three conditions that must hold before splitting prefill from decode pays off, and why chunked prefill is the right default below that threshold. The post Disaggregation Is a Thous...

Read source
dev.to /3 weeks ago

Hyper-efficient Cardinality Estimation: Redis HyperLogLog in Production with wredis

Hyper-efficient Cardinality Estimation: Redis HyperLogLog in Production with wredis Counting unique elements across millions of daily active users, IP addresses, or IoT telemetry...

Read source
dzone.com /6 days ago

Moving 900+ GB of Prometheus Without a Cutover Weekend

The Prometheus I was responsible for had grown past 900 GB of time series data, and at that size it had every disease that comes with it.  Queries timed out unless you narrowed the...

Read source
databricks.com /1 month ago

Autoscaling Lakebase Postgres

Choosing a database instance size before you know the workload is an old building pattern...

Read source
towardsdatascience.com /1 month ago

Building a Data Lakehouse with DuckDB and DuckLake

Starting with a local Parquet file, then joining it to data stored in the cloud The post Building a Data Lakehouse with DuckDB and DuckLake appeared first on Towards Data Science.

Read source
dev.to /2 weeks ago

Filtering a 2 GB CSV in the browser without uploading it: streams, a Web Worker and a 64-bit hash set

Excel stops at 1,048,576 rows. Most online CSV tools want you to upload the file first, which is a non-starter for a customer list or an accounting export. I wanted something in be...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Large Datasets

feeds.dzone.com

Recent coverage from public sources
Public source

cryptobriefing.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

feeds.feedburner.com

Recent coverage from public sources
Public source

flowingdata.com

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source