Rethinking Ranking in the LLM Era [Testμ 2026]
Rhea Goel of Amazon on replacing a re-ranker with an LLM: natural language objectives, fine-tuning, DPO, hard and soft constraints, distillation and LLM judges.
Search fresh public links, source activity, and ready-to-use post angles for Llm Inference.
Fresh curated links around LLM Inference are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Rhea Goel of Amazon on replacing a re-ranker with an LLM: natural language objectives, fine-tuning, DPO, hard and soft constraints, distillation and LLM judges.
How LLM hallucination detection works: groundedness scoring, semantic entropy, judge models and fine-tuned detectors compared, with where each one fails.
Want to understand what makes LLMs fast? Build the systems yourself.
Large Language Models (LLMs) are increasingly used not only to generate content, but also to evaluate the output produced by other models. This technique is commonly known as LLM-a...
11 LLM evaluation tools compared for 2026: what each one measures, where it fits in the lifecycle, and how to pick one for your architecture and privacy needs.
Moving from static model assignment to intelligent, task-level LLM selection. The post Optimizing LLM Inference Costs in Multi-Agent Systems with Adaptive Model Routing appeared fi...
In the next wave of generative AI, it's crucial to combine LLMs and tabular foundation models where they provide the greatest benefit.
<figure data-wp-context="{&quot;imageId&quot;:&quot;6aaeca9e123fa&quot;}" data-wp-interactive="core/image" data-wp-key="6aaeca9e123fa&qu...
A pull request arrives. A few hundred lines of Java implementing the new discount rule: tiered thresholds, a regional exception, something about loyalty tiers that nobody can quite...
Large language models become significantly more useful when they can interact with external tools instead of only generating text. A model can decide that it needs information from...
Исследователи Stanford Hazy Research представили CLM-8B - Contrastive Language Model, открытую 8B-модель для быстрых решений внутри агентных систем. В отличие от обычной LLM, котор...
The way we build with AI keeps changing. Prompt engineering gave way to RAG. RAG gave way to agents. Now teams are working with MCP, multi-agent workflows, and reasoning models. Ke...
LLMs in 7 Days · Season 1, Day 1: tokens, next-token prediction and temperature, with a game of “be the LLM” and a real terminal chatbot…Continue reading on Medium »
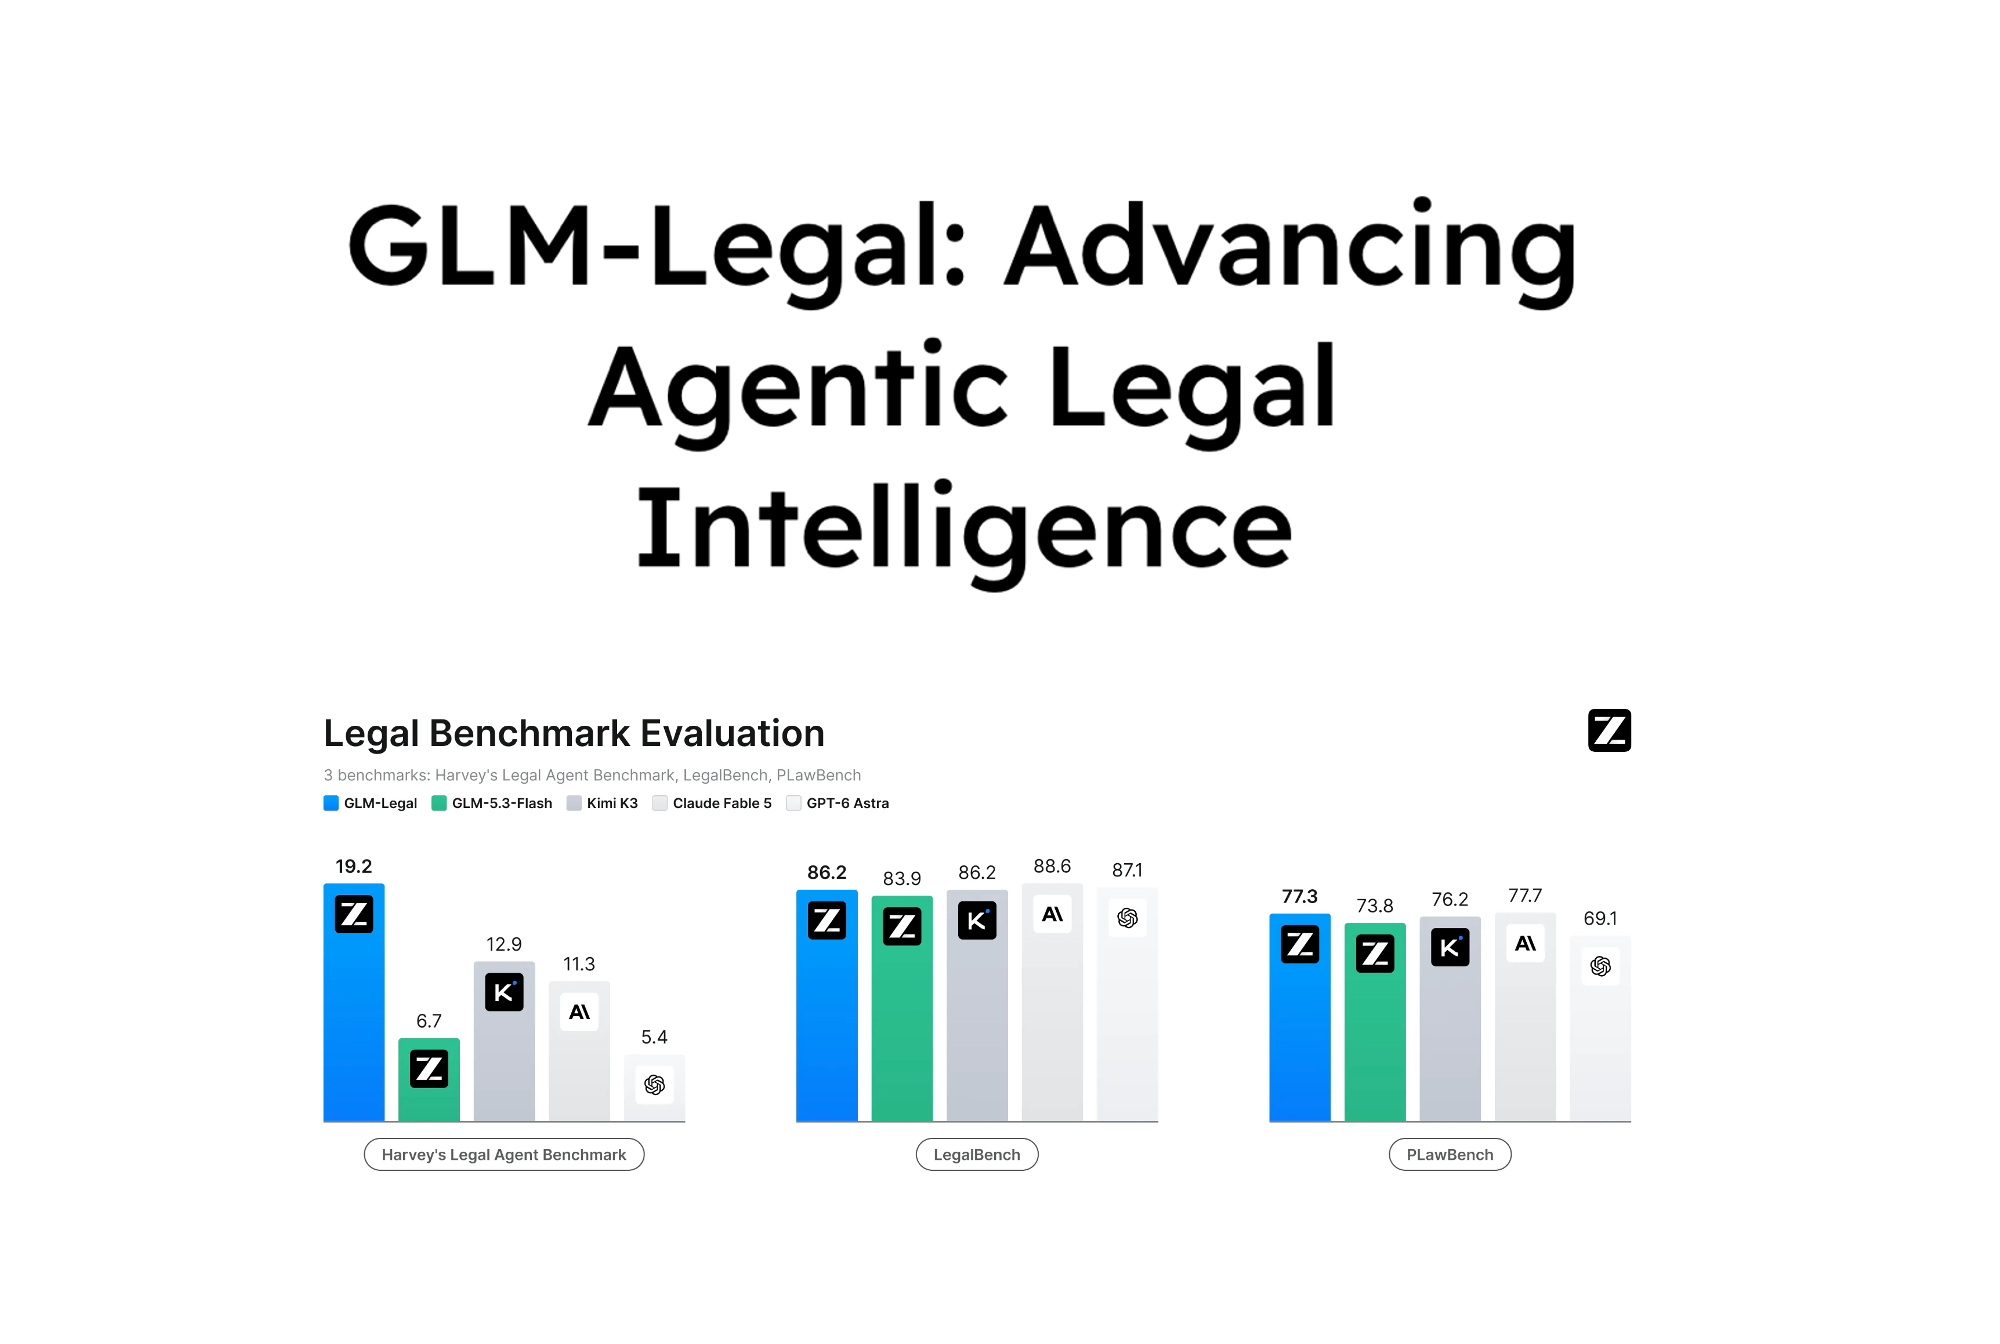
Chinese company Z.ai, which created the GLM models, has launched a legal-specific LLM that has been ‘mid-trained’ and post-trained to handle a range of tasks ...
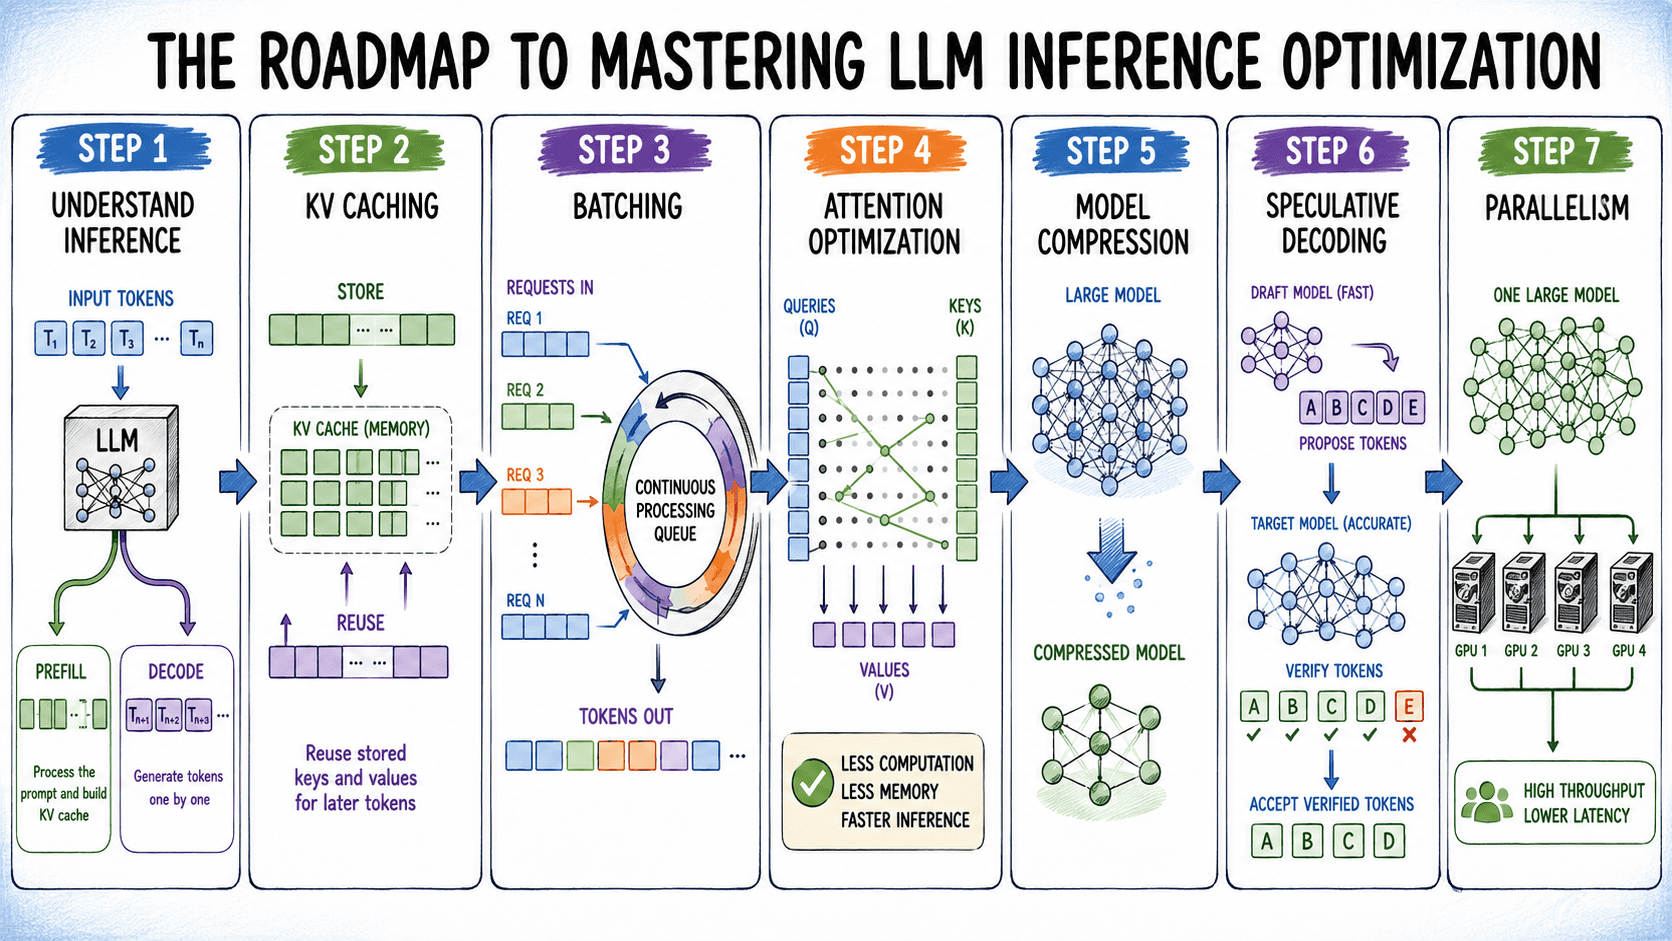
In this article, you will learn how LLM inference optimization works and which techniques to apply to make language models faster, cheaper, and more reliable...
Open-source large language models are AI systems you can study, adapt, and use without being locked into one company’s platform or rules. In 2025, they’re giving rese...
A new benchmark finds that LLMs struggle to complete legal research tasks on their own, even as users pay a premium for the most advanced models.
A days-old startup reportedly raised $40 million on a radical bet: most AI calls don’t need a language model at all. I traced the claim…Continue reading on AI Engineering Simplifie...
New research reveals that higher capability in LLMs doesn’t guarantee better teamwork
LLM evals score a model. End-to-end agent testing gates a build. See what each one proves, where they disagree, and how to run both without duplicating work.
Continue reading on Medium »
Part 6 of the LLM Coding Interview Series ·Continue reading on Models to Systems »
How Jev separates language generation from decision making to make LLM evaluation faster, cheaper, and more consistentContinue reading on Artificial Intelligence in Plain English »
LLM security explained: the OWASP Top 10 for LLM Applications 2026, how it differs from LLM safety, and one test per risk with the evidence that decides it.
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.