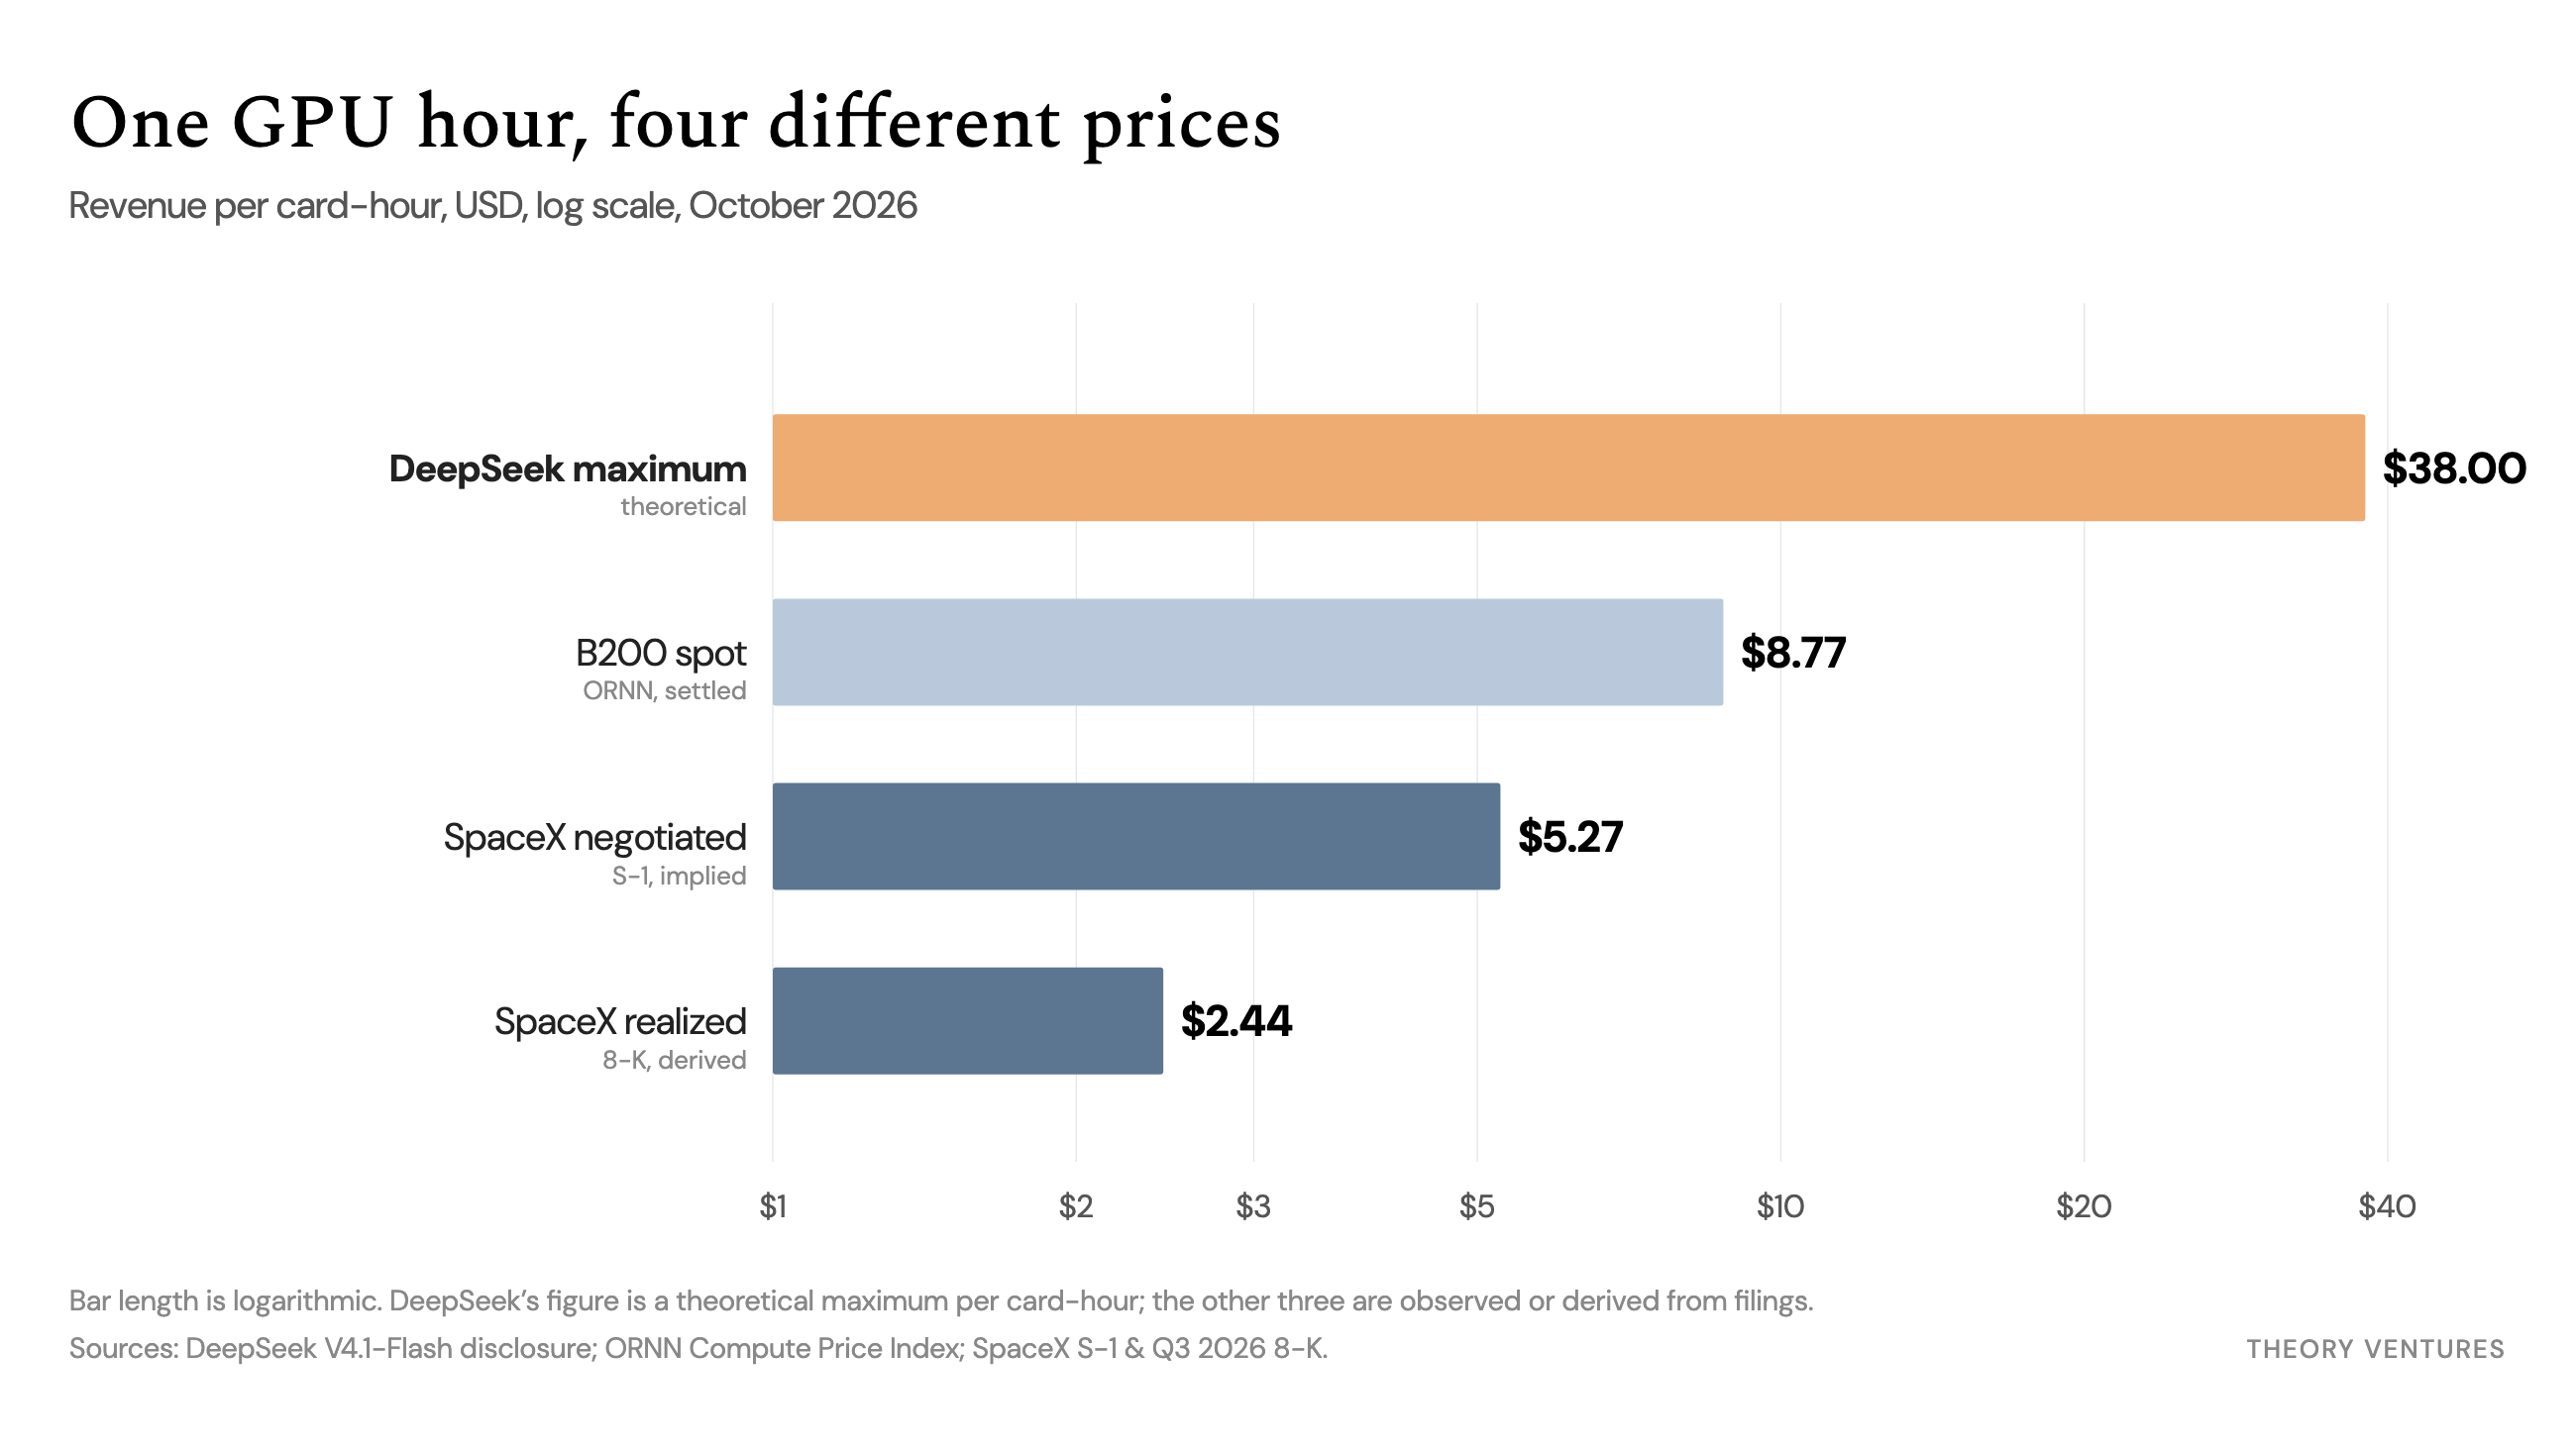
Latest updates for Gpu Inference

Fresh curated links around GPU inference are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • The GPU Revenue Ladder
  • The Inference Bill Is a Memory-Bandwidth Problem
  • Dedicated Servers for AI Inference: CPU, GPU, RAM and Network Requirements

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

tomtunguz.com /3 days ago

The GPU Revenue Ladder

SpaceX's third-quarter report & DeepSeek's inference disclosure together price one GPU card-hour four ways, from DeepSeek's theoretical $38 maximum to SpaceX's realized $2.44....
Read source
vexpose.blog /1 month ago

The Inference Bill Is a Memory-Bandwidth Problem

<p class="wp-block-paragraph">You added GPUs to make your LLM serving faster, and tokens-per-second barely moved. The dashboard says the GPUs are 40%</p>

Read source
medium.com /1 month ago

Dedicated Servers for AI Inference: CPU, GPU, RAM and Network Requirements

Why AI inference is a system-level workload, and how to balance hardware for production LLMs.Continue reading on Medium »

Read source
digitalthoughtdisruption.com /1 month ago

New whitepaper: Your GPU Is Up. Is Your AI?

<figure data-wp-context="{"imageId":"6ab19ff94e720"}" data-wp-interactive="core/image" data-wp-key="6ab19ff94e720&qu...

Read source
indiandefensenews.in /4 weeks ago

IIT-Delhi Unveils India’s First Indigenous Micro-GPU, Eyes Advanced Multi-Core Graphics Future

Researchers at IIT-Delhi have developed India’s first working and demonstrable indigenously designed micro Graphics Processing Unit (micro-GPU), marking a significant step towards...

Read source
telecomtalk.info /1 week ago

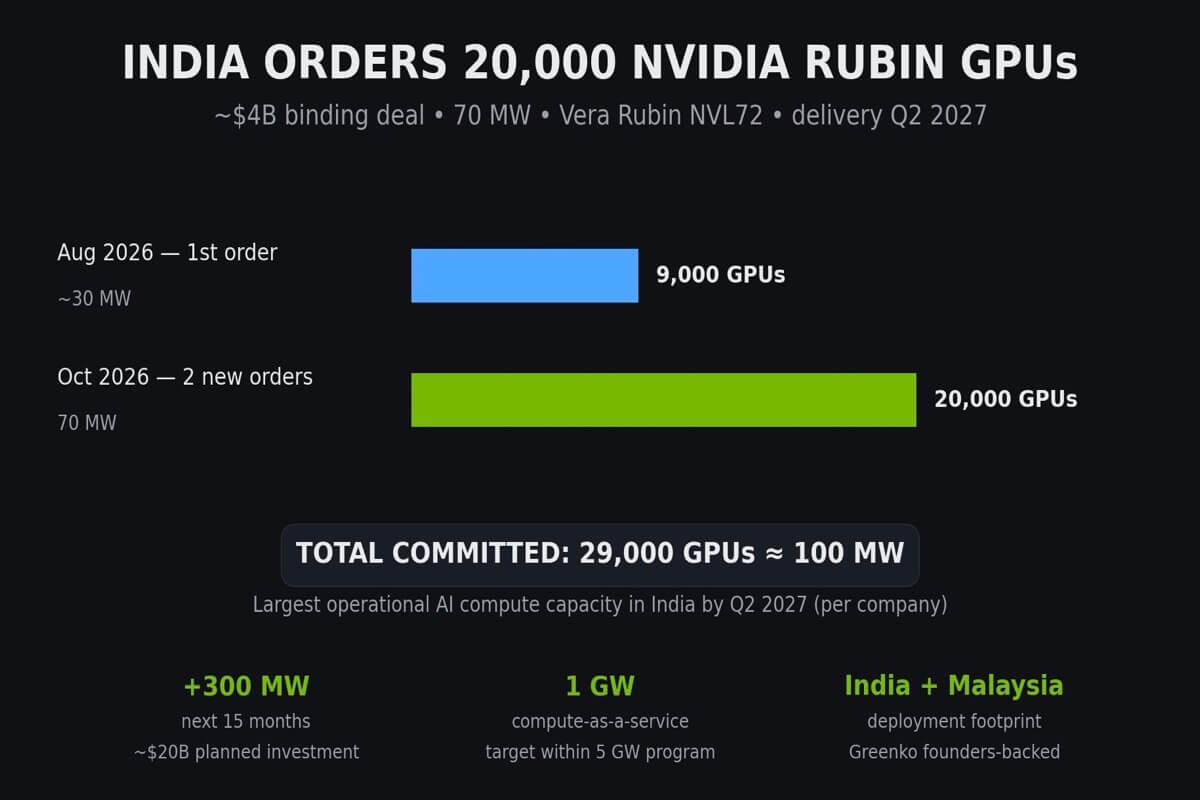
NVIDIA Sends 20000 Rubin Gpus to India

India is preparing for a major AI computing expansion. AM Intelligence, backed by the people behind Greenko, has ordered another ... Read More

Read source
techbuzzireland.com /2 days ago

How to Choose the Right GPU Hosting Plan for AI Workloads

AI development is no longer limited to large technology companies. Developers and businesses are increasingly using GPU infrastructure for model inference, image generation, video...

Read source
medium.com /1 month ago

Monitoring GPU Inference Workloads: Tools and Metrics That Actually Matter

A simple guide to the real GPU metrics and monitoring tools you need to run AI inference without wasting money or losing performance.Continue reading on Medium »

Read source
medium.com /1 week ago

Zero-Host-Copy Inference: Keeping the CPU Out of the Hot Path in a C++/CUDA Pipeline (165 FPS)

1. Introduction: Anatomy of the BottleneckContinue reading on Medium »

Read source
electronicsforu.com /1 month ago

CPU brings AI inference to the processor

A processor uses 3D stacking and AI instructions to run inference while reducing power use and the number of servers required. Fujitsu’s FUJITSU-MONAKA processor is designed for AI...

Read source
phoronix.com /1 week ago

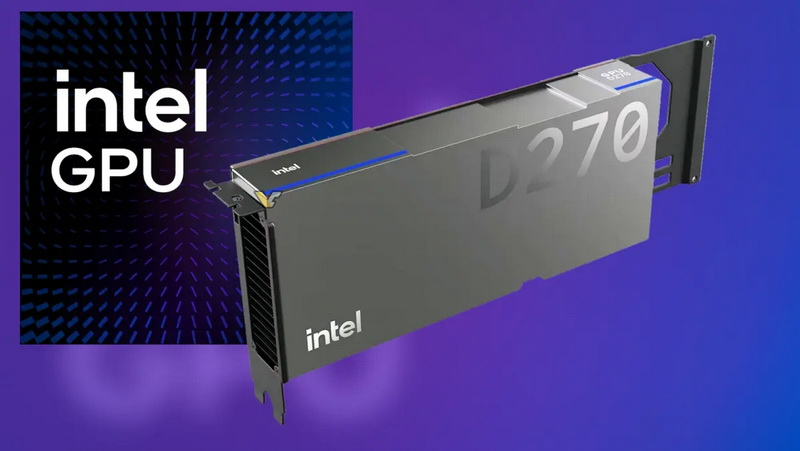
Intel Announces The GPU D Series For Crescent Island

Intel announced today the GPU D Series for the enterprise-focused, inference-optimized GPU accelerators known to now as Crescent Island...

Read source
databricks.com /1 month ago

Achieving Extreme Efficiency through Specialized GPU Kernel Generation

Traditionally, production inference systems rely on generic kernels to handle diverse...

Read source
geeky-gadgets.com /3 weeks ago

NVIDIA NVFP4 Boosts Prompt Processing by 46% on Blackwell

NVIDIA’s introduction of the NVFP4 format for its Blackwell GPUs offers a compact four-bit floating-point representation designed to optimize AI workloads. As highlighted by The St...

Read source
proandroiddev.com /3 weeks ago

Build own ML Inference Runtime with AndroidX WebGPU

Running a neural network on the GPU — with Kotlin?Continue reading on ProAndroidDev »

Read source
habr.com /1 month ago

Запустить LLM локально: что считать до покупки видеокарты?

Мощная видеокарта не всегда означает быстрый локальный запуск LLM. Разбираемся, почему GPU может простаивать, как на производительность влияют память, KV‑кэш и движок инференса, и...

Read source
vexpose.blog /4 days ago

Field Note: The GPU That Was Busy Doing Nothing

<p class="wp-block-paragraph"><em>Field Note — one real failure, the wrong diagnosis, the actual cause, the fix.</em></p> <p class="wp-blo...

Read source
dev.to /1 month ago

Gemma 4 on an 2021 4 GB Laptop GPU: QAT Takes It From 9.5 GiB to 1.6

This article provides a step by step deployment guide for Gemma 4 E2B's quantization-aware-trained (QAT) checkpoint to a local, laptop hosted GPU enabled system — a much old...

Read source
dramarnathgiri.blogspot.com /1 month ago

AM Intelligence brings frontier AI compute to India.

 AM Intelligence brings frontier AI compute to India.AM Intelligence (AMI) is building a full-stack AI infrastructure ecosystem spanning energy, data-centre infrastructure, hardwar...

Read source
3dnews.ru /4 weeks ago

Giga Computing развернула ИИ-полигон GAIFA на базе NVIDIA GB300 NVL72

Компания Giga Computing, являющаяся подразделением Gigabyte, объявила о создании площадки GAIFA (Gigabyte AI Factory Accelerator) — своего первого вычислительного центра в области...

Read source
pandaily.com /1 month ago

Infinigence AI Open-Sources APXInf for Embodied Edge Inference on Jetson Thor

Infinigence AI open-sources APXInf with Tsinghua and SJTU: PI 0.5 FP8 on Jetson Thor drops end-to-end latency from ~278 ms to ~26 ms (~38.46 Hz), with Orin/Thor/RTX 4090 support an...

Read source
shivashish-ydv.medium.com /1 week ago

Your GPU Says 100% and Your Model Still Crawls. The Real Bottleneck Is the Kernel You Never See.

nvidia-smi tells you the card is busy. It does not tell you the card is working.Continue reading on Medium »

Read source
pandaily.com /1 month ago

China Mobile Cloud Debuts GPU–Neuromorphic Heterogeneous LLM Inference Stack

At the 2026 China Computing Power Conference, China Mobile Cloud and partners unveiled a domestic GPU plus neuromorphic mixed-inference system for large models, citing roughly 2× o...

Read source
3dnews.ru /1 week ago

Intel вырезала из GPU блоки 3D-графики и трассировки лучей ради ИИ — представлен D270 с поддержкой до 480 Гбайт LPDDR5X

Компания Intel официально представила графические ускорители серии D на саммите Open Compute Project (OCP) 2026. Ранее известная под кодовым названием Crescent Island новинка тепер...

Read source
habr.com /2 weeks ago

Как мы запустили Qwen3.8–27B целиком на RTX 5060 8 GB и получили ~30 токенов/с

Наш проект называется ExVRAM Lab. Это открытая исследовательская лаборатория, в которой мы проверяем, насколько большие локальные LLM можно запускать на обычных видеокартах с огран...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Gpu Inference

dramarnathgiri.blogspot.com

Recent coverage from public sources
Public source

phoronix.com

Recent coverage from public sources
Public source

3dnews.ru

Recent coverage from public sources
Public source

blogs.vmware.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

electronicsforu.com

Recent coverage from public sources
Public source