Latest updates for Fault Tolerance

Fresh curated links around Fault Tolerance are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • How to Contain Partial Failures in Distributed Systems
  • Fault tolerant distributed training on Amazon EKS using NVRx
  • Simplify your resilience testing strategy with Fault Injection Testing

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

dzone.com /6 days ago

How to Contain Partial Failures in Distributed Systems

Distributed systems rarely fail as a single unit. More often, one dependency slows down, one shard becomes unavailable, one region loses capacity, or one pool saturates while neigh...
Read source
aws.amazon.com /1 month ago

Fault tolerant distributed training on Amazon EKS using NVRx

Integrate NVIDIA Resiliency Extension (NVRx) into PyTorch FSDP training on Amazon EKS to overlap checkpoint I/O with training and recover from GPU faults in seconds. This post cove...

Read source
cloud.google.com /1 month ago

Simplify your resilience testing strategy with Fault Injection Testing

When databases fail and network paths falter, you still need your mission-critical cloud services to stay online. Yet guaranteeing high availability has become increasingly difficu...

Read source
thequantuminsider.com /3 weeks ago

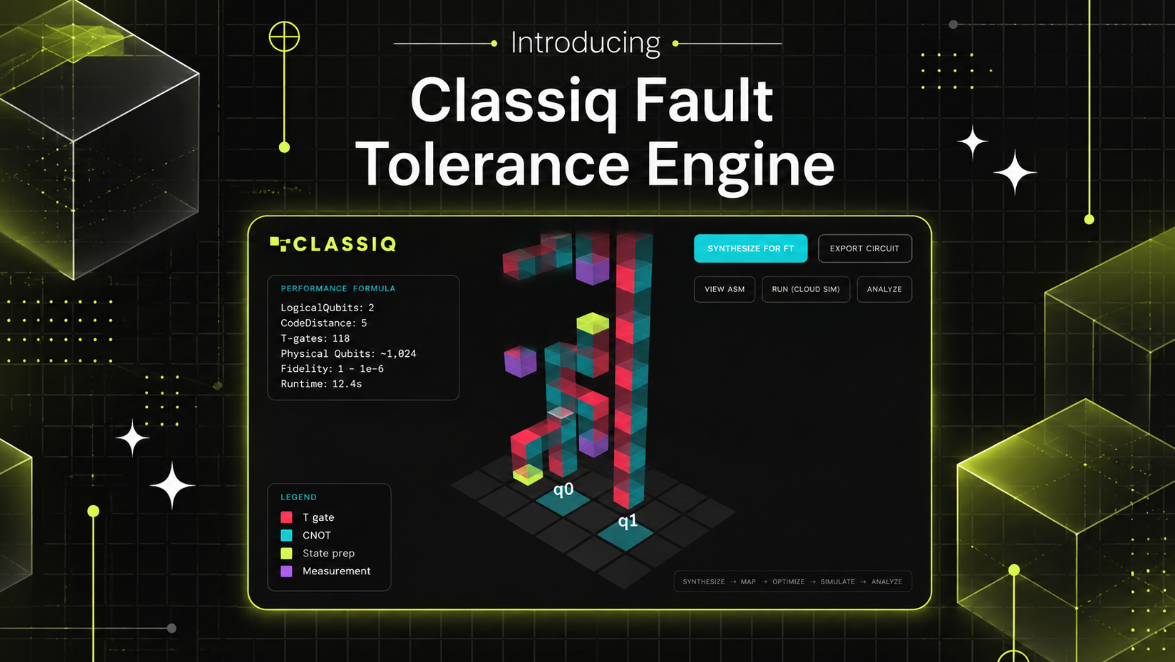
Classiq Introduces Fault Tolerance Engine for Quantum Applications

Insider Brief PRESS RELEASE — Classiq today announced its Fault Tolerance Engine, a new product capability that translates optimized logical quantum programs into fault-tolerant ex...

Read source
aws.amazon.com /1 month ago

How Intuit and AWS systematically improved resiliency on ElastiCache using AWS Fault Injection Service

Learn how Intuit and AWS validated Amazon ElastiCache resilience under a real Availability Zone impairment using AWS Fault Injection Service, cutting recovery from over 50 minutes...

Read source
javacodegeeks.com /20 hours ago

BEAM Supervision Trees and “Let It Crash”: What Java Services Can Steal from Erlang

Most Java code tries hard to never fail. Erlang takes the opposite view, and the idea travels better than you might expect. Where “Let It Crash” Comes From The phrase sounds reckle...

Read source
javacodegeeks.com /4 weeks ago

Resilience by Design vs. Resilience by Library: BEAM vs. Go and Java

In distributed systems engineering, few architectural divides are as deep—or as philosophically opposed—as how different runtimes handle failure. When an unexpected error occurs, w...

Read source
dev.to /1 month ago

Surviving the 429 Storm: Building Resilient LLM Fallbacks in Production

How to eliminate cascading failures from LLM rate limits using exponential backoff, circuit breakers, and tiered fallback chains. The Bottleneck in Production Most prod...

Read source
databricks.com /1 month ago

Fast, fault-tolerant PyTorch training on AI Runtime

At scale, your training efficiency is determined by a single metric: "goodput", the...

Read source
digitalthoughtdisruption.com /2 days ago

Beyond High Availability: Proving VCF 9.1.x Management-Plane Recovery

<p class="wp-block-paragraph">Animation: Workloads can remain available while management capabilities require recovery and verification before return to service.&lt...

Read source
javacodegeeks.com /1 month ago

The Byzantine Generals Problem and Why Most Systems Don’t Need Byzantine Fault Tolerance

Crash faults and Byzantine faults are not the same problem, and reaching for blockchain-grade guarantees inside a trusted internal network usually solves a problem you don’t have....

Read source
habr.com /1 month ago

Промпт‑инжиниринг для моделей надежности отказоустойчивого кластера

Ранее в «Базовые модели надежности отказоустойчивого кластера» [2] были показаны теоретические подходы к построению моделей (непрерывная цепь Маркова, CTMC, Continuous‑Time Markov...

Read source
dzone.com /6 days ago

When Retries Become Failure Amplifiers: The Hidden Cost of Recovery at Scale

The City Traffic Analogy Imagine a city's traffic system during rush hour. A minor accident blocks one lane on a major highway. Traffic slows down, but the road remains partially f...

Read source
dzone.com /4 weeks ago

How to Prevent Retry Storms With Retry Budgets in Distributed Systems

Retries are one of the simplest ways to make a distributed system appear more reliable. A transient connection failure, overloaded replica, or short-lived network interruption can...

Read source
bryanoconnor21.co.uk /1 month ago

VCF 9.1 Clustering and Availability Enhancements: Smarter HA, Intelligent DRS, and Faster vMotion at Scale

<p><b>High availability and workload mobility are fundamental pillars of any VMware environment. With VMware Cloud Foundation (VCF) 9.1, VMware has focused on making cl...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Fault Tolerance

feeds.dzone.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

blogs.vmware.com

Recent coverage from public sources
Public source

cloudblog.withgoogle.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source