Latest updates for Document Parsing

Fresh curated links around Document Parsing are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • A Deep Dive into the Microsoft Foundry Document Intelligence SDK: From PDF to Structured Data
  • Intelligent Document Processing with Apache Camel, Docling & LangChain4j
  • A 1998 PDF-to-Text Converter

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

dzone.com /3 weeks ago

A Deep Dive into the Microsoft Foundry Document Intelligence SDK: From PDF to Structured Data

Most "RAG over PDFs" pipelines have a step nobody talks about much: something has to turn a scanned invoice, a multi-column contract, or a photographed receipt into text a model ca...

Read source
javacodegeeks.com /1 month ago

Intelligent Document Processing with Apache Camel, Docling & LangChain4j

Enterprise applications often need to process large numbers of documents such as PDFs, invoices, manuals, reports, and policy documents. Extracting text from these documents is onl...

Read source
code.dblock.org /2 weeks ago

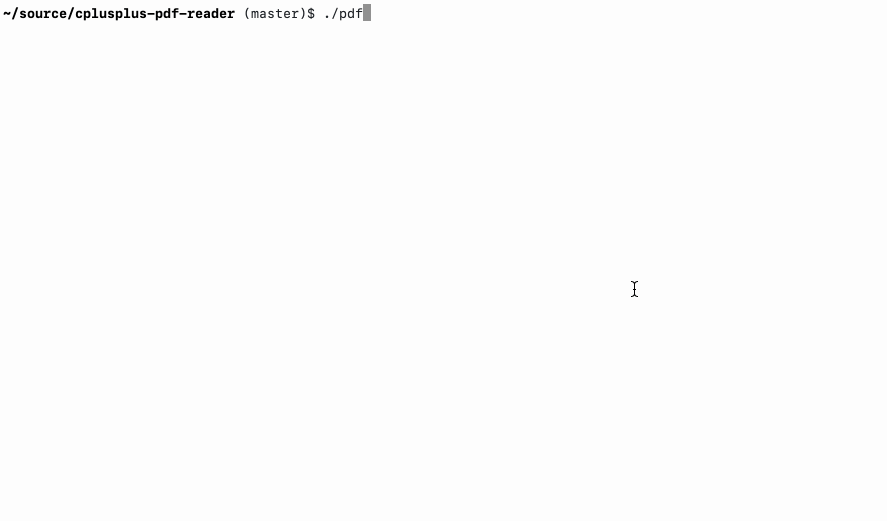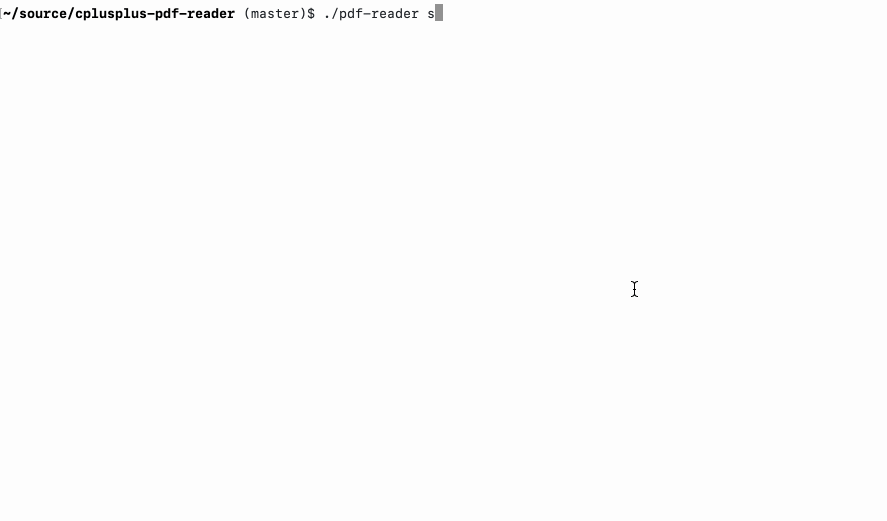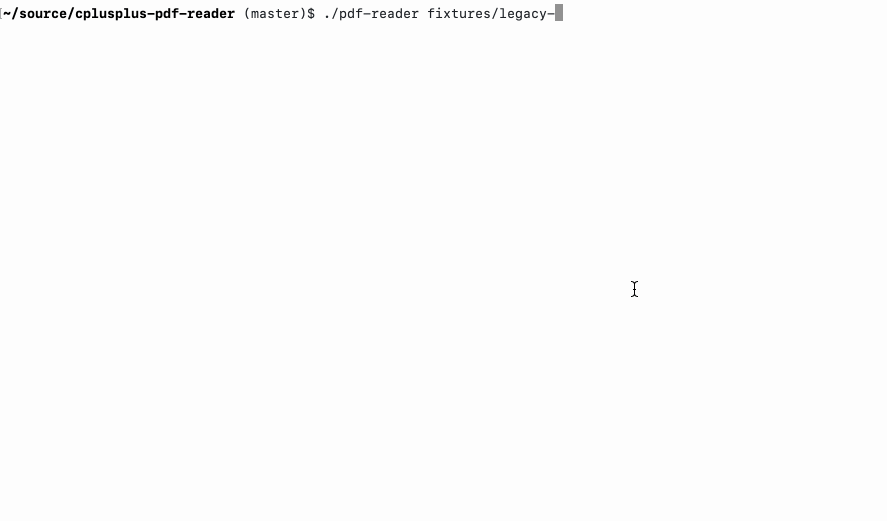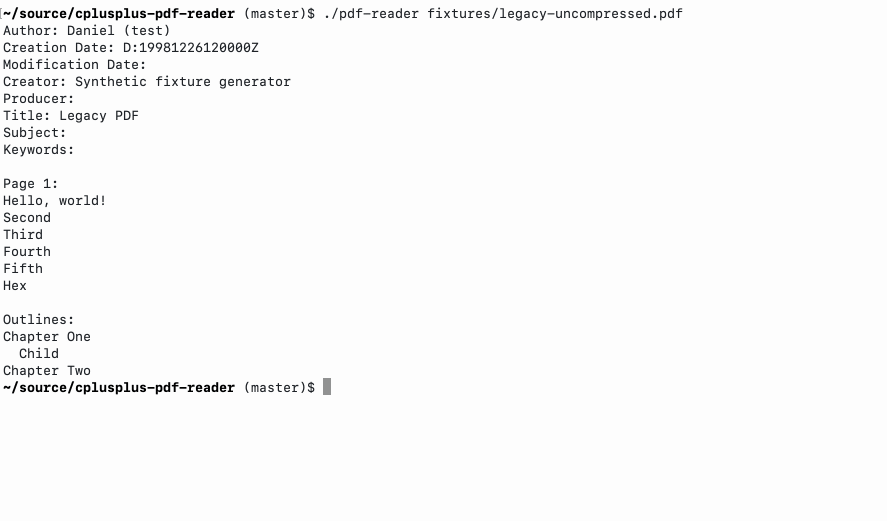
A 1998 PDF-to-Text Converter

Originally appeared on code.dblock.org | tech blog.In 1998 I needed to convert PDF files to text for a search engine called Alkaline, without requiring separately installed librari...

Read source
everlaw.com /1 month ago

Automating The Manual Components of Ediscovery (Part 2): Reviewing Modern Data

Summary Ediscovery Pain Points When Reviewing Modern Data Stream...

Read source
webkul.com /3 weeks ago

Visual Document Retrieval – EVIE-8B, No OCR Needed

Visual document retrieval has always leaned on OCR. First, extract the text. Then, run retrieval on that text. This works fine for a clean invoice or a simple contract. But once a...

Read source
marktechpost.com /1 month ago

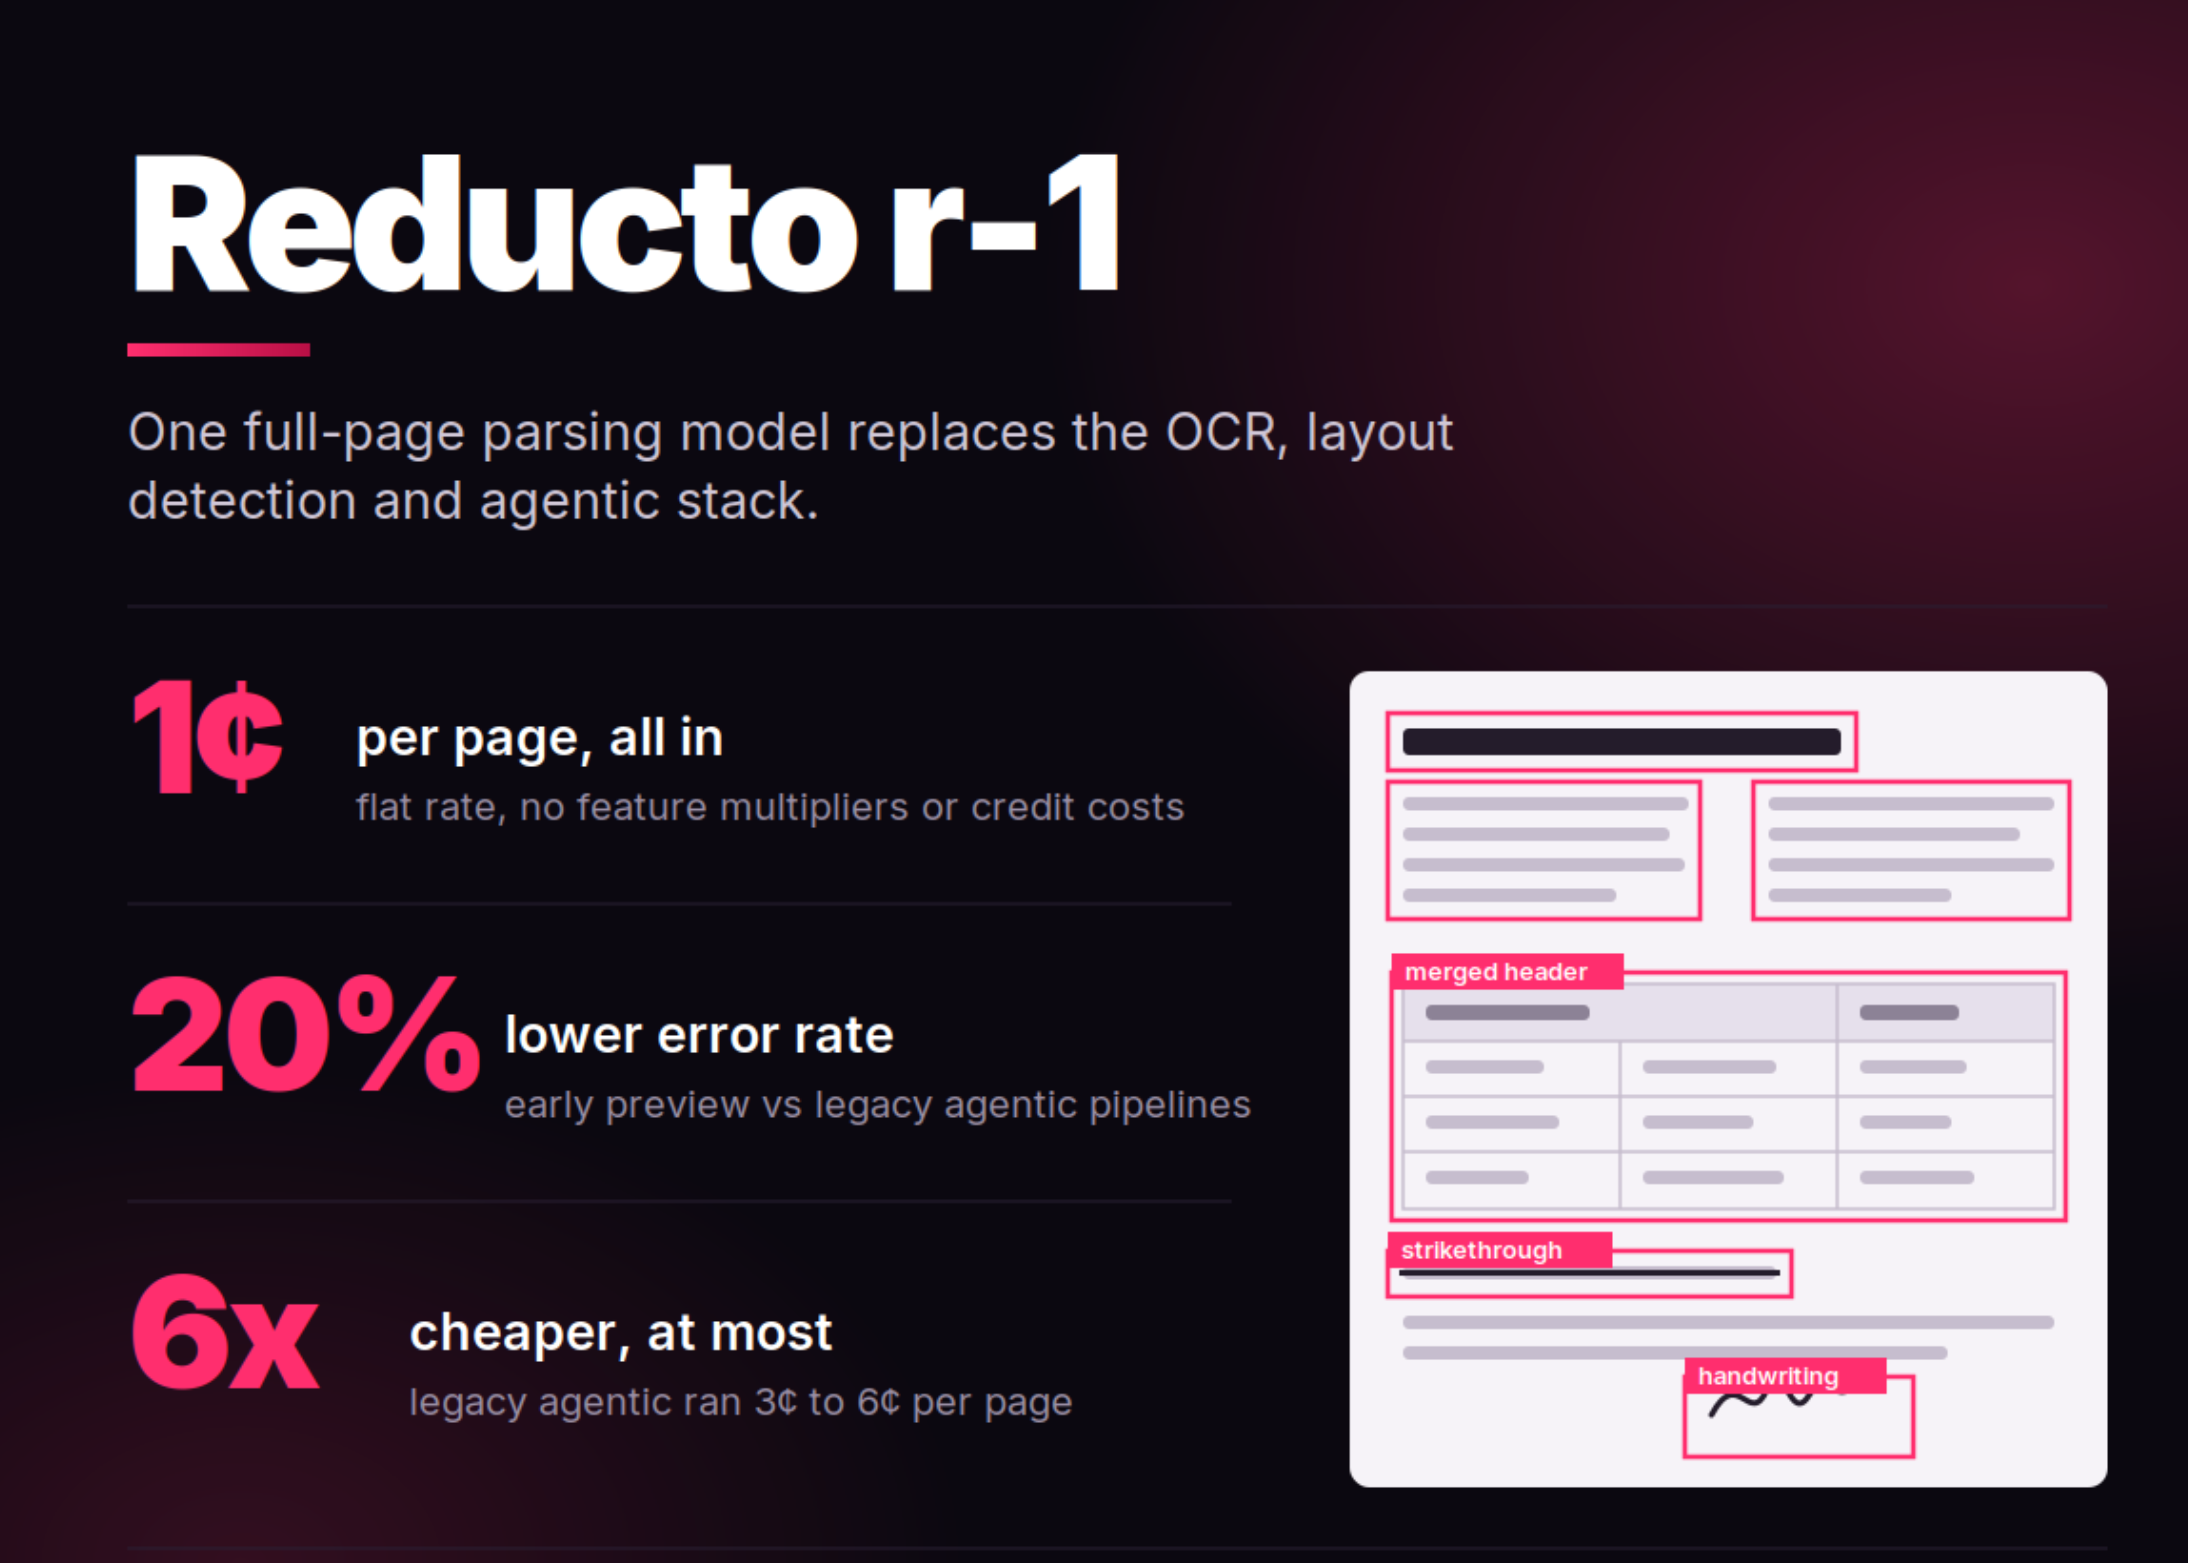
Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page

We look at r-1, the document parsing model Reducto released on September 1, 2026. We walk through how it folds OCR, layout detection, tables, formatting and grounding into one full...

Read source
syncfusion.com /1 month ago

7 Document Automation Tasks Every .NET Application Should Handle Server-Side

Learn how to automate PDF, Word, Excel, OCR, document conversion, and data extraction in modern .NET applications without Microsoft Office dependencies.

Read source
marktechpost.com /1 month ago

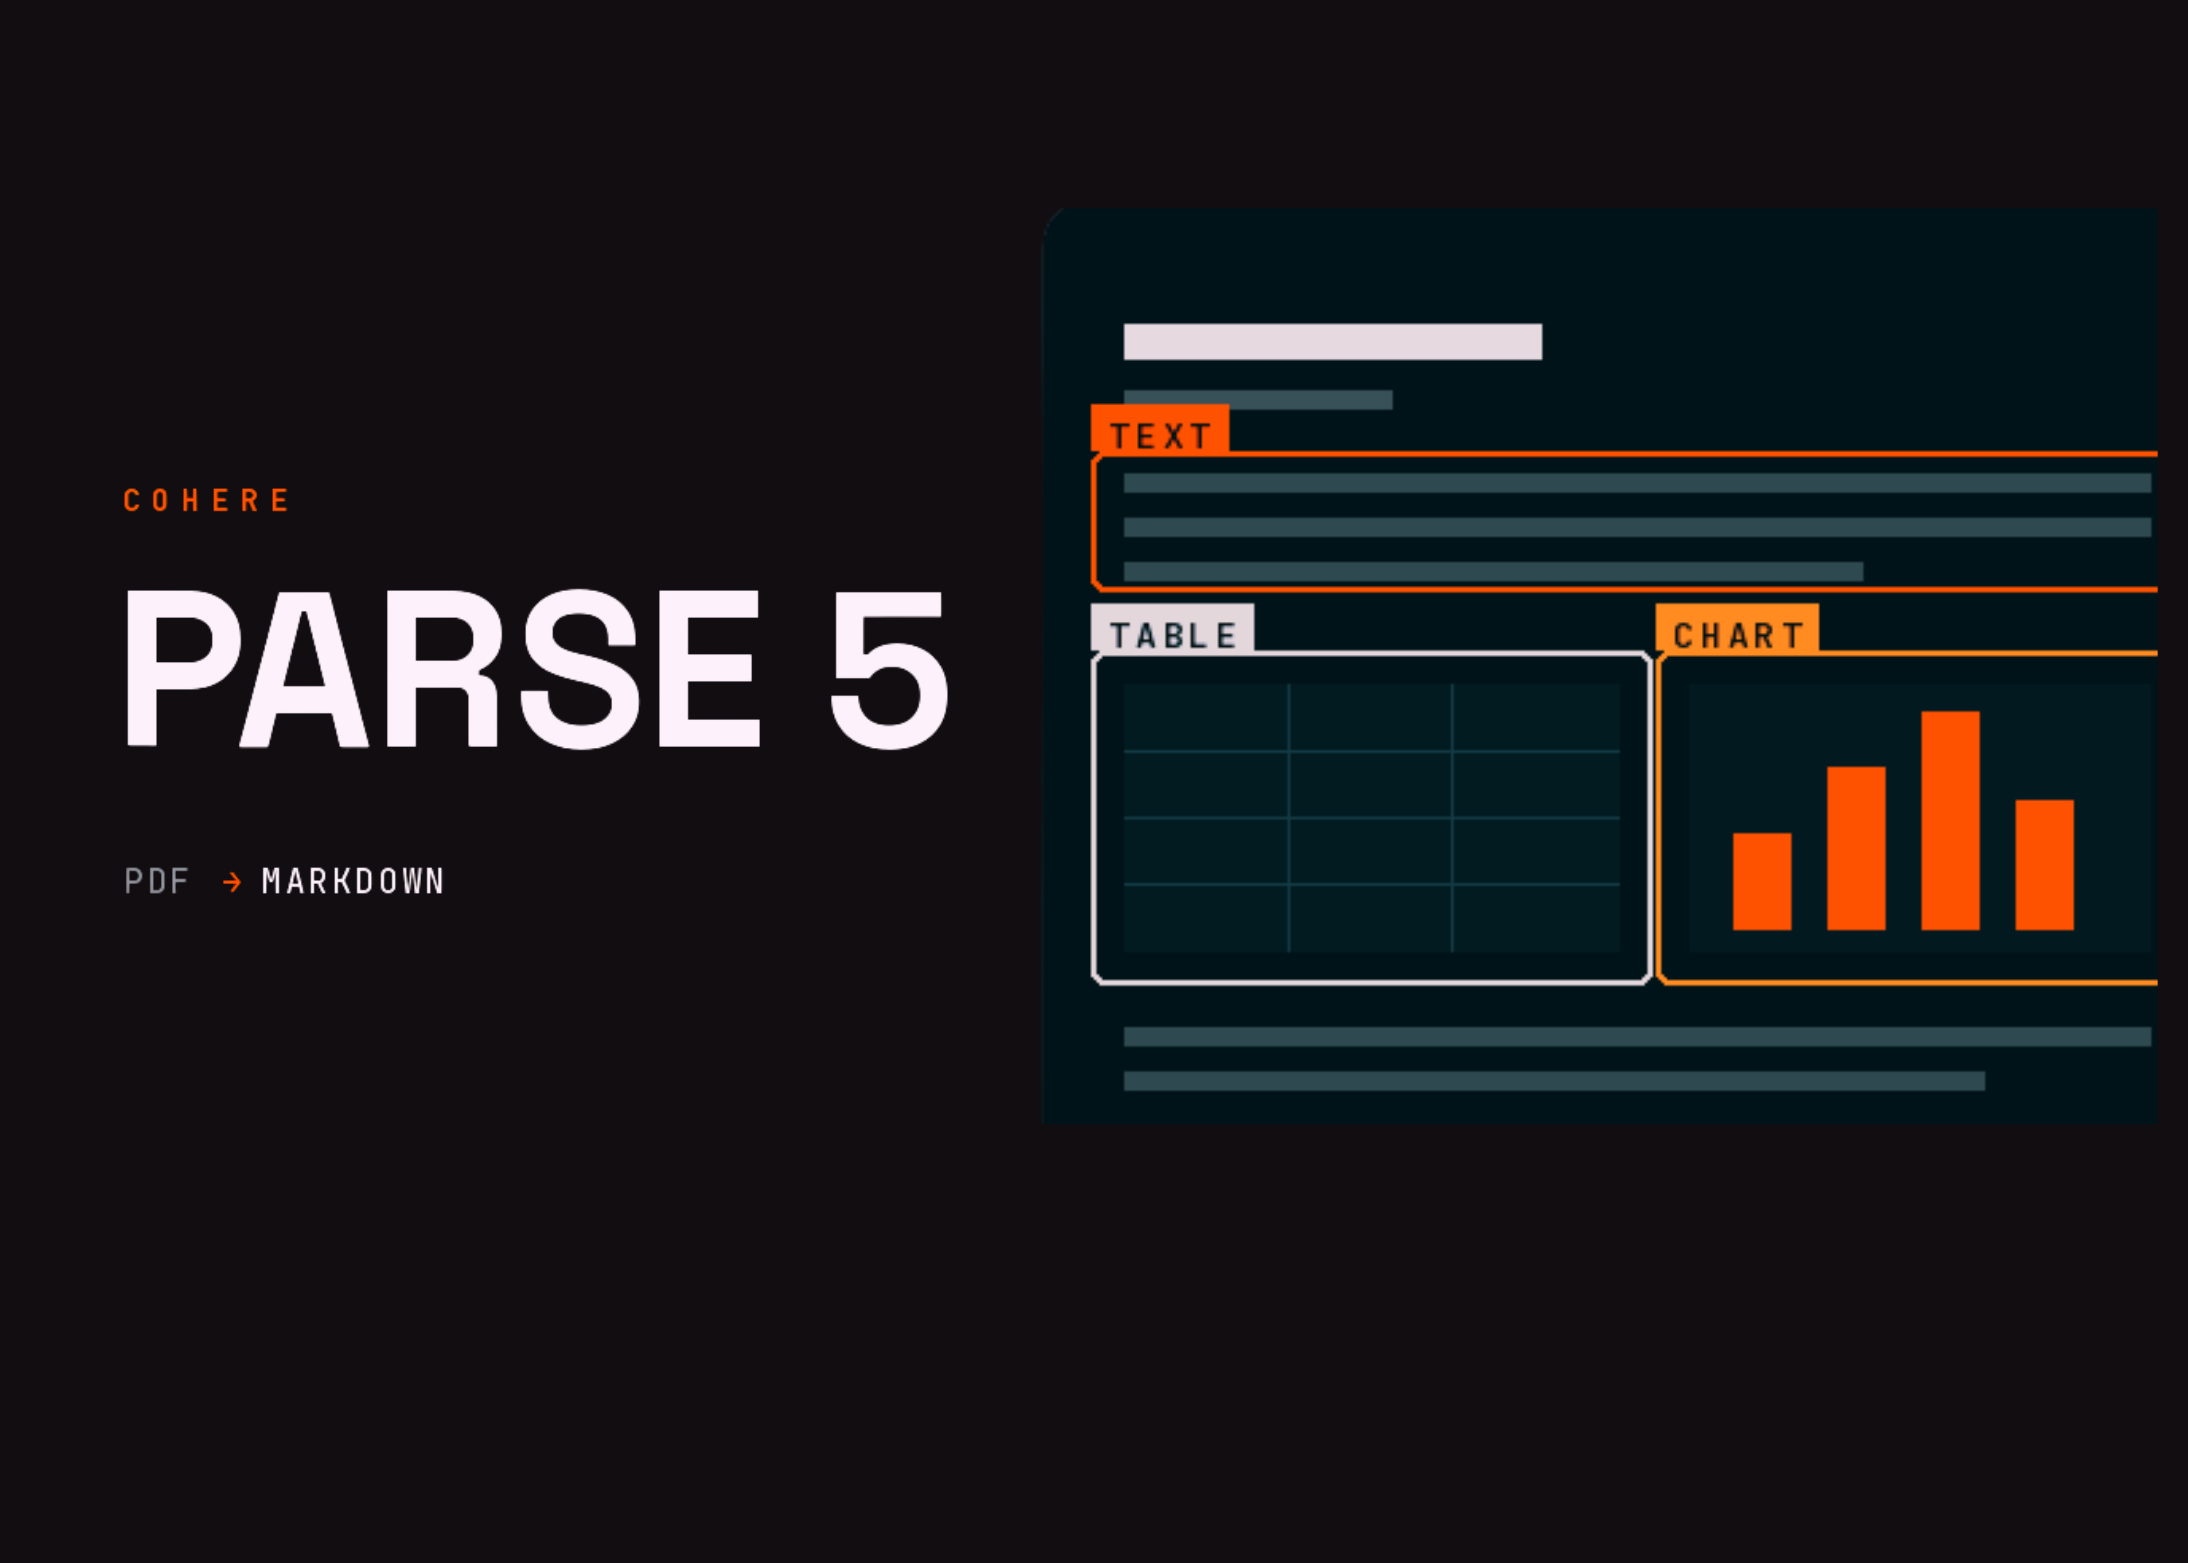
Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown

Cohere has released Parse (parse-v5.0), a 2.3B-parameter vision language model that converts PDFs, slides and images into Markdown with HTML tables, bounding boxes and image descri...

Read source
everlaw.com /1 month ago

Faster PDF Review and Greater Insight into Billing

Faster PDF Review and Greater Insight into Billingby Everlaw...

Read source
marktechpost.com /2 days ago

A Developer’s Guide to OmniParseBench: Leaderboard Benchmarks and OCR Testing

Explore how to audit and rebuild Datalab's OmniParseBench, test parser ranking certainty with document-level bootstrapping, and evaluate Tesseract and Indra OCR performance on a cu...

Read source
freelancer.com /3 weeks ago

PDF Text & Tables Conversion

I have a PDF full of paragraphs, images, and several tables. I need every paragraph re-typed into a clean, editable Word document while keeping the original formatting. The tables...

Read source
prunderground.com /4 days ago

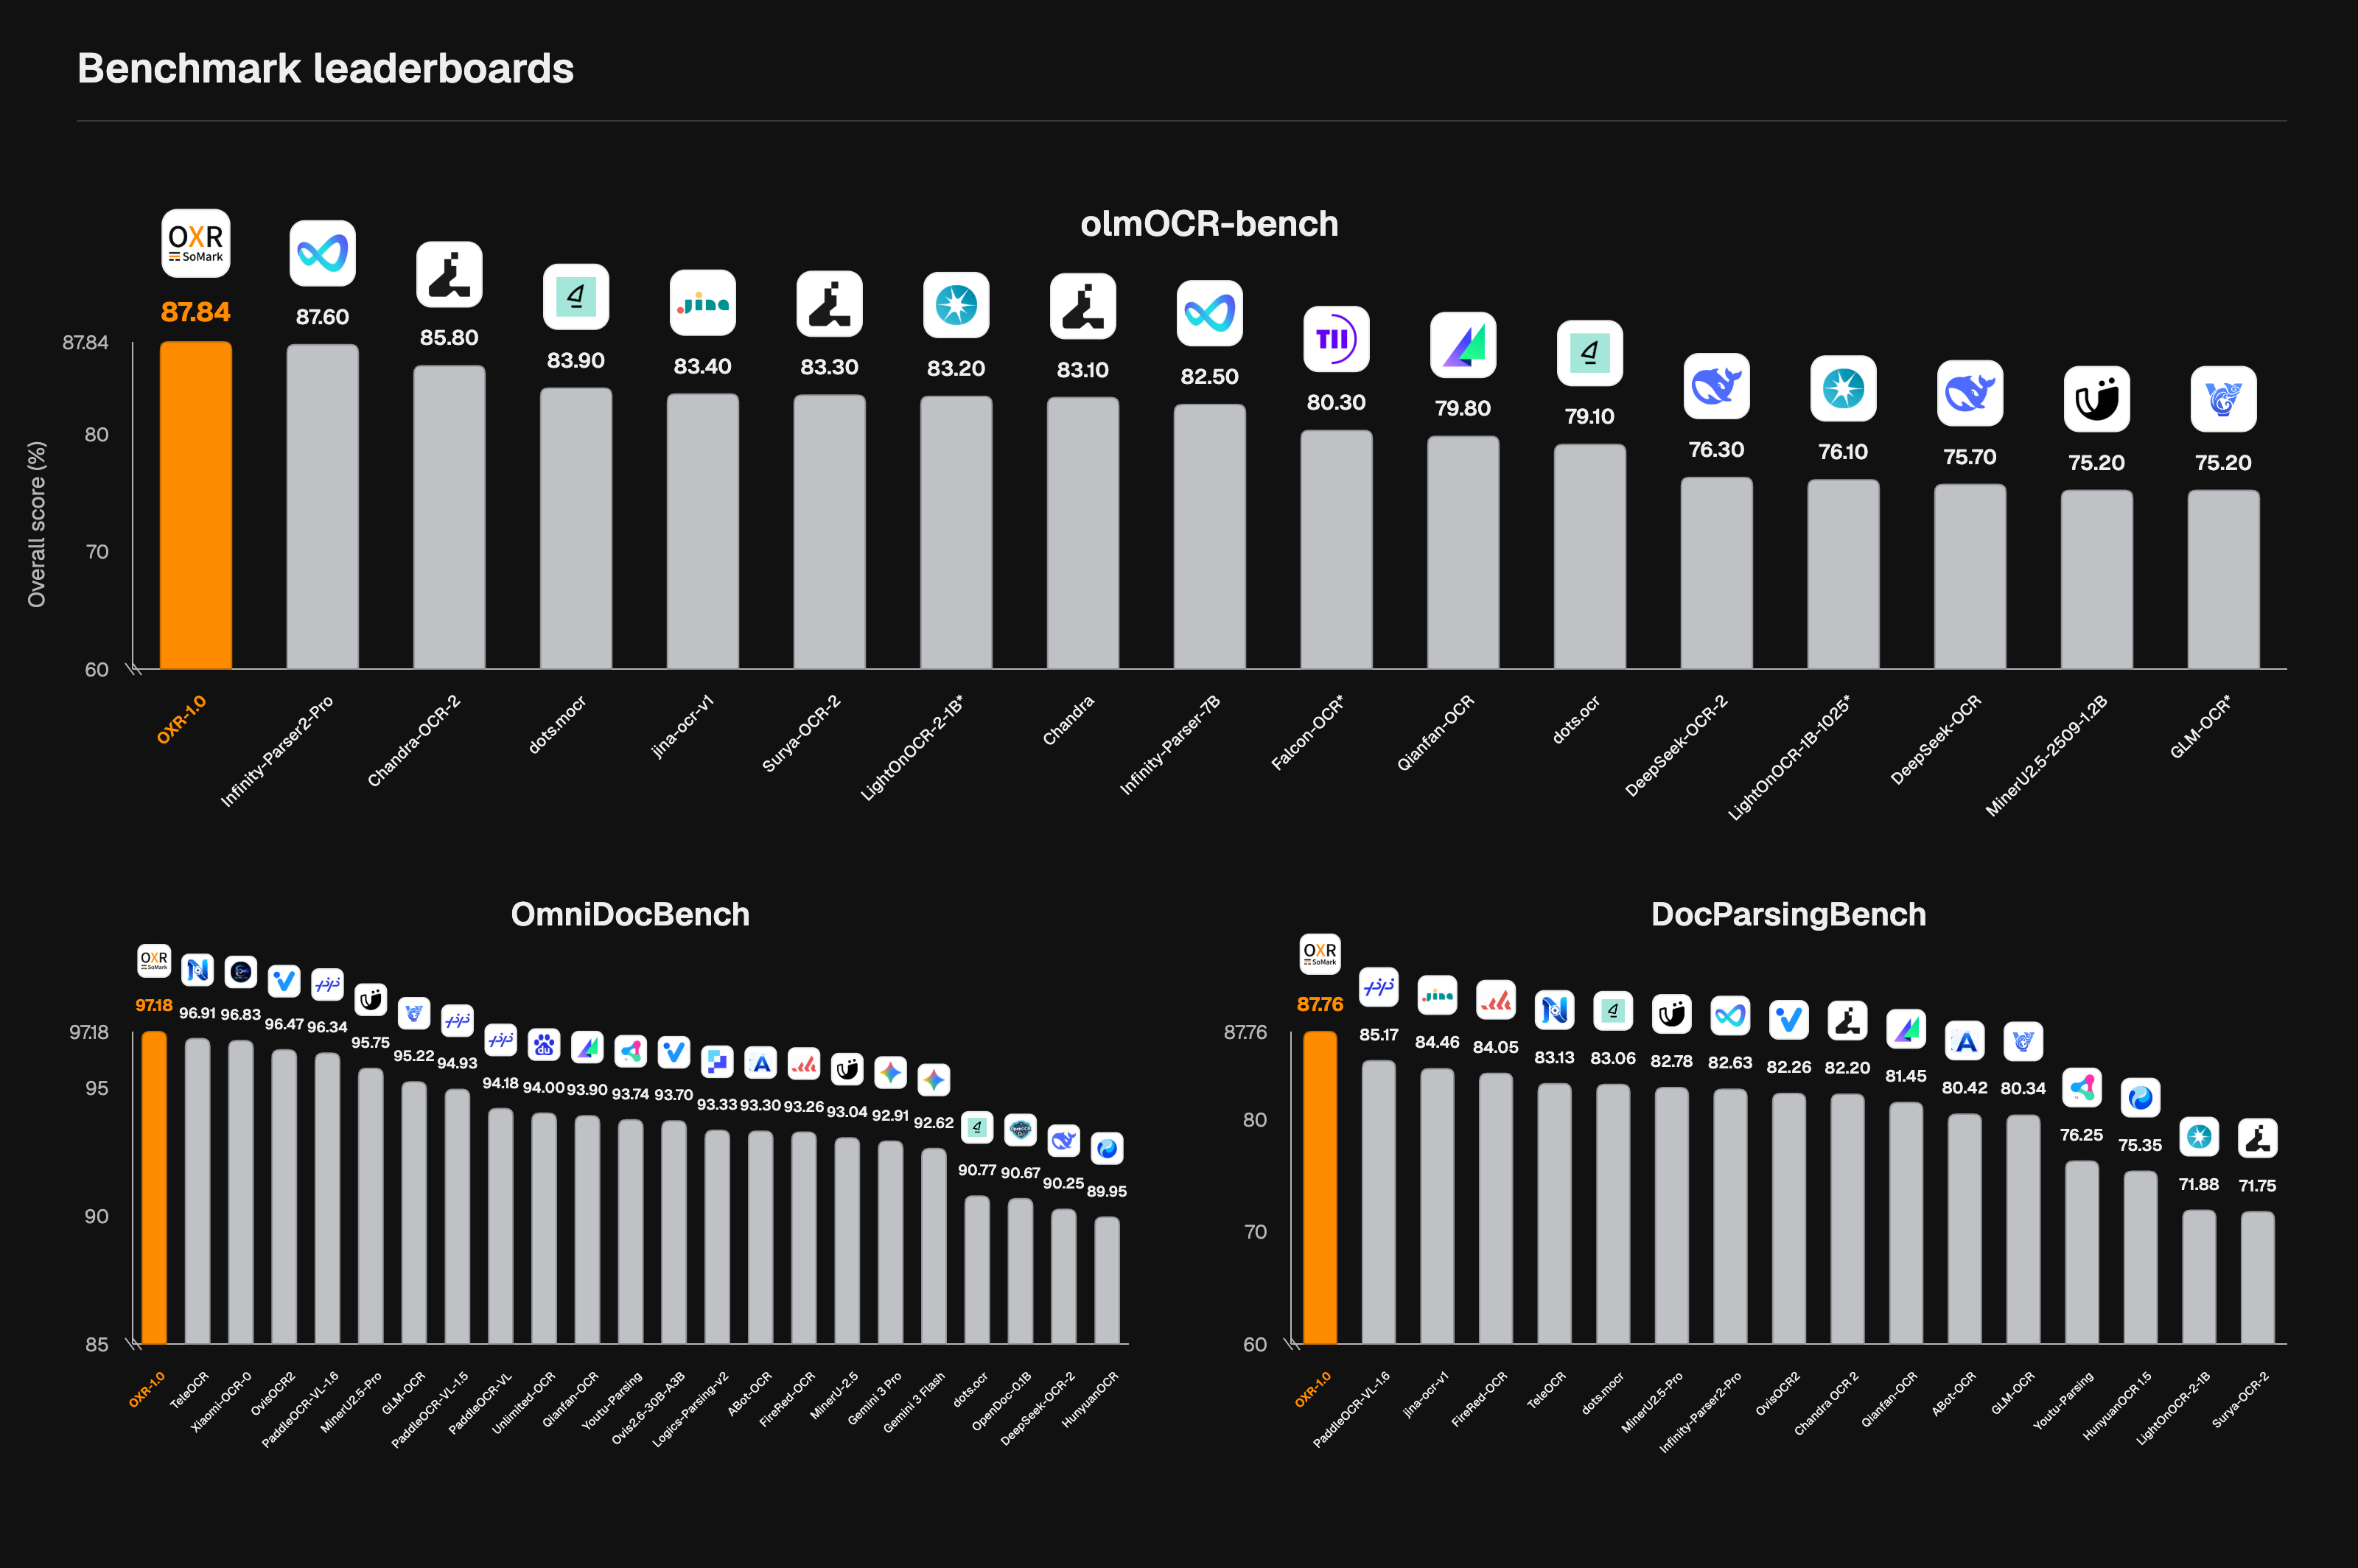
OXR Goes Open Source: #1 on 3 Benchmarks, SOTA Accuracy & Speed--the First Document Parser with RSI

The team behind SoMark open-sources OXR, the first document parser with RSI. It turns PDFs and document images into Agent-Friendly data with SOTA accuracy and speed. The post OXR G...

Read source
legaltechdaily.com /1 month ago

LexSelect Outperforms Parsing Platforms on Legal Documents

A lawyer using an AI tool must verify its answers against the source, and the referenced text must be accurate and reliable. Without that, the tool is unusable for work that matter...

Read source
freelancer.com /2 weeks ago

PDF to Word: Extract Text

I need the full text from a PDF transferred into an editable Word (.docx) file so I can work with the content freely. The PDF is laid out in regular paragraphs and I want that same...

Read source
towardsdatascience.com /1 month ago

Tables in PDFs for RAG: Don’t Flatten the Grid

Enterprise Document Intelligence [Vol.1 #B4] - A diagnostic and five composable operations, not a decision tree The post Tables in PDFs for RAG: Don’t Flatten the Grid appeared fir...

Read source
dev.to /1 month ago

Fill Existing PDF Forms from n8n Without Rebuilding the Template

Many document automations generate a new PDF from HTML. That is the right tool for invoices and reports you design yourself. It is the wrong tool when a customer, carrier, governme...

Read source
kodekloud.com /1 month ago

How to Build Your First RAG Pipeline Over Your Own PDF Documents

A model that has never seen your documents will answer questions about them anyway, confidently and wrongly. RAG fixes that by finding the right page first and handing it over with...

Read source
wnynewsnow.com /5 days ago

PDF Editing Tools for High-Volume Contract Workflows

A team editing contracts all day doesn’t want a tool that slows down by the fiftieth document, or a free tier that hits a daily cap right when volume is heaviest. No PDF tool, incl...

Read source
dzone.com /2 weeks ago

Building Enterprise File-Heavy AI Workflows: From Secure Uploads to Governed Document Intelligence

Enterprise AI is increasingly moving beyond clean, structured datasets and into the much larger world of documents, files, images, forms, emails, reports, contracts, claims, clinic...

Read source
freelancer.com /2 weeks ago

PDF Text Extraction Task

I have a batch of PDFs and I need every bit of readable text lifted out of them and delivered as clean, plain-text files—no bolding, italics, or structural markup, just the raw w...

Read source
syncfusion.com /1 week ago

What’s New in Syncfusion Document SDKs 2026 Volume 3: AI Chunking, PDF Security, and Data Extraction

Explore Syncfusion Document SDKs 2026 Volume 3, featuring a new .NET Document Chunking Library, PDF signature validation, SVG-to-PDF conversion, and barcode recognition.

Read source
kdnuggets.com /3 weeks ago

From Messy Documents to Structured Data with Docling

Docling takes documents in whatever inconsistent format they arrive in, and converts them into one unified, structured representation that both people and AI systems can work with...

Read source
freelancer.com /3 weeks ago

PDF Text & Image Extraction

I have a text-based PDF and need every character captured exactly as it appears, with no headers, footers, or page breaks lost in the process. Because the file isn’t scanned, a dir...

Read source
freelancer.com /1 week ago

PDF Scanned Text Data Entry

I have a batch of scanned documents saved as PDFs and need every bit of text accurately keyed into an editable format. The scans are clear, but they still require human attention—a...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Document Parsing

feeds.dzone.com

Recent coverage from public sources
Public source

rubyland.news

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

kodekloud.com

Recent coverage from public sources
Public source

towardsdatascience.com

Recent coverage from public sources
Public source

webkul.com

Recent coverage from public sources
Public source