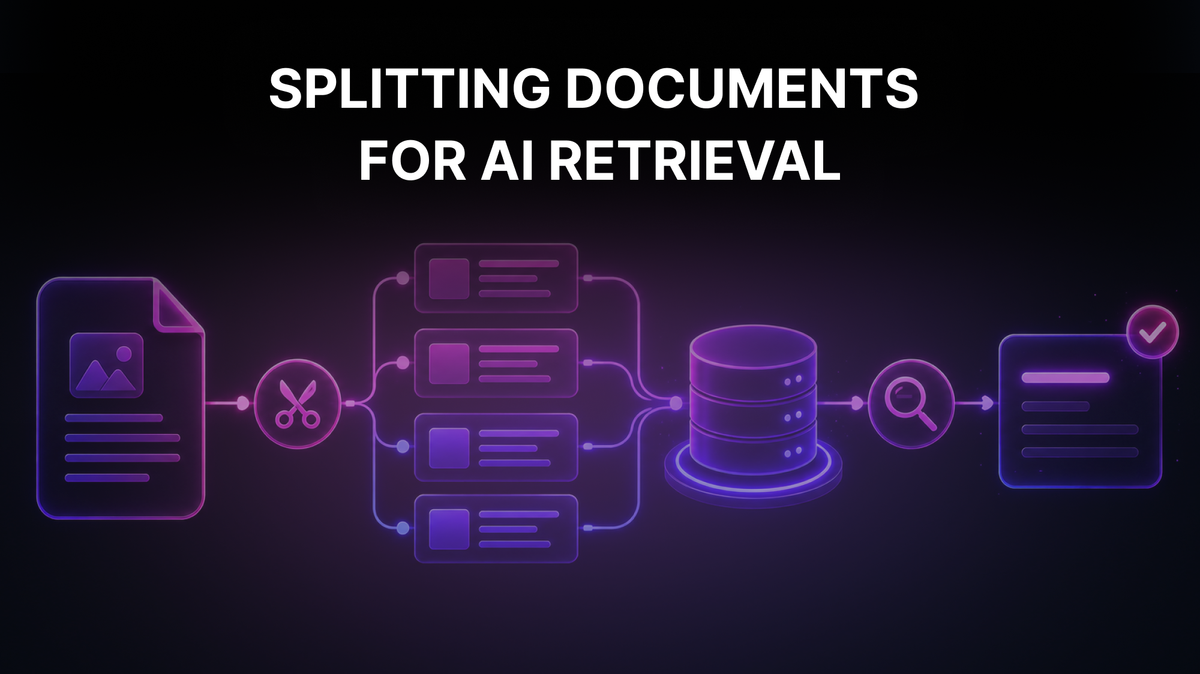
How to Chunk Documents So Your Retrieval Returns the Right Answer
Chunking decides more of your retrieval quality than the model does, and the obvious way to measure it rewards the worst possible answer. Here are eight strategies, measured on the...
Search fresh public links, source activity, and ready-to-use post angles for Document Chunking Library.
Fresh curated links around Document Chunking Library are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Chunking decides more of your retrieval quality than the model does, and the obvious way to measure it rewards the worst possible answer. Here are eight strategies, measured on the...
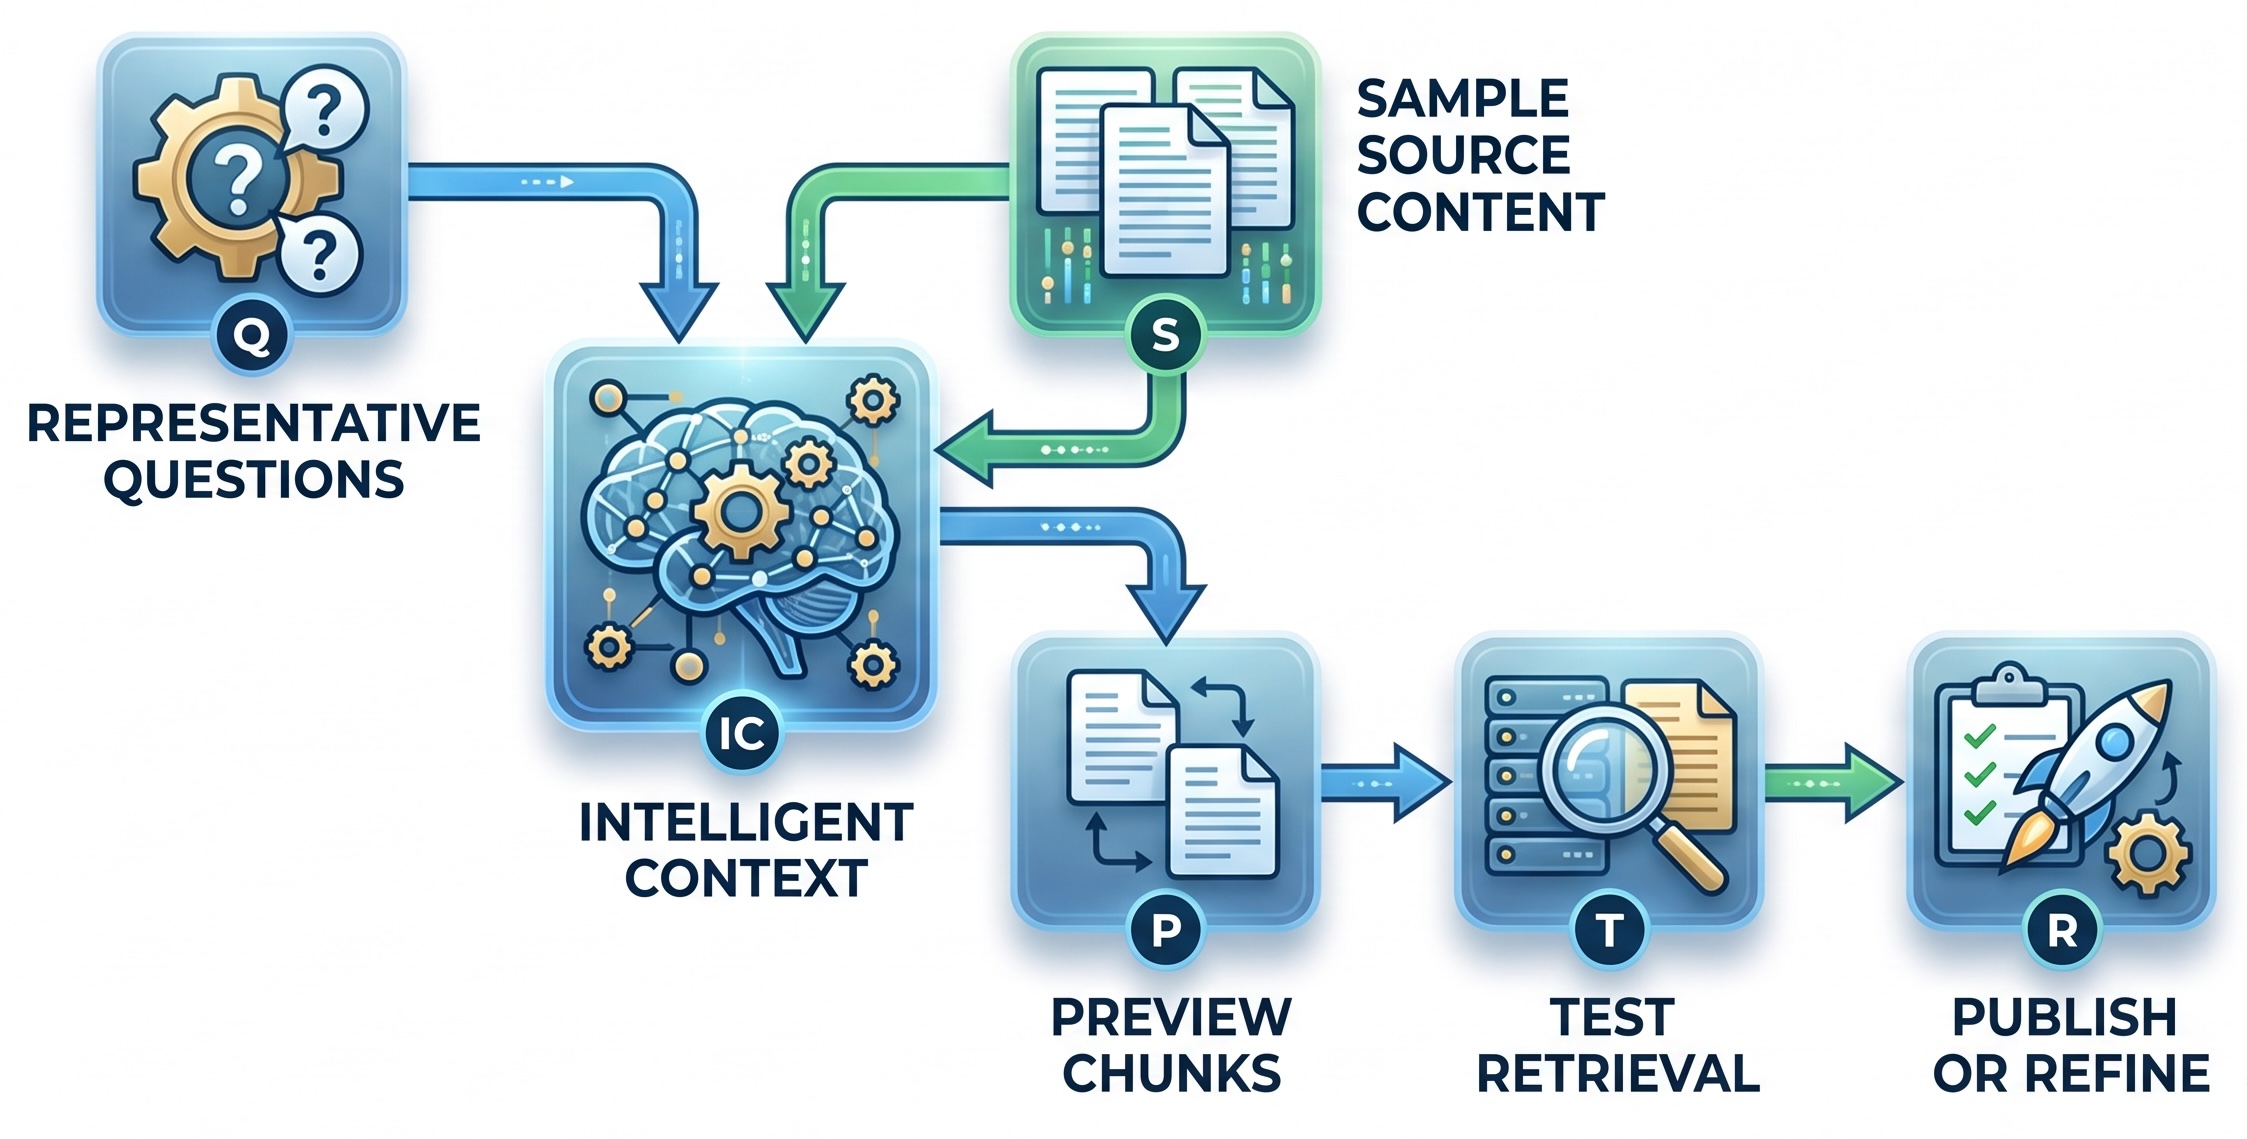
Enterprise applications often need to process large numbers of documents such as PDFs, invoices, manuals, reports, and policy documents. Extracting text from these documents is onl...
Two organizations can ingest the same documents and receive dramatically different AI responses. The difference may not be the model. It can be how the content was parsed, divided,...
Explore Syncfusion Document SDKs 2026 Volume 3, featuring a new .NET Document Chunking Library, PDF signature validation, SVG-to-PDF conversion, and barcode recognition.
Originally appeared on code.dblock.org | tech blog.In 1998 I needed to convert PDF files to text for a search engine called Alkaline, without requiring separately installed librari...
Most "RAG over PDFs" pipelines have a step nobody talks about much: something has to turn a scanned invoice, a multi-column contract, or a photographed receipt into text a model ca...
When you’re standing up a web app, developers are trying to build required functionality quickly and at a low cost: budgets are still tight, teams are small, and resources are thin...
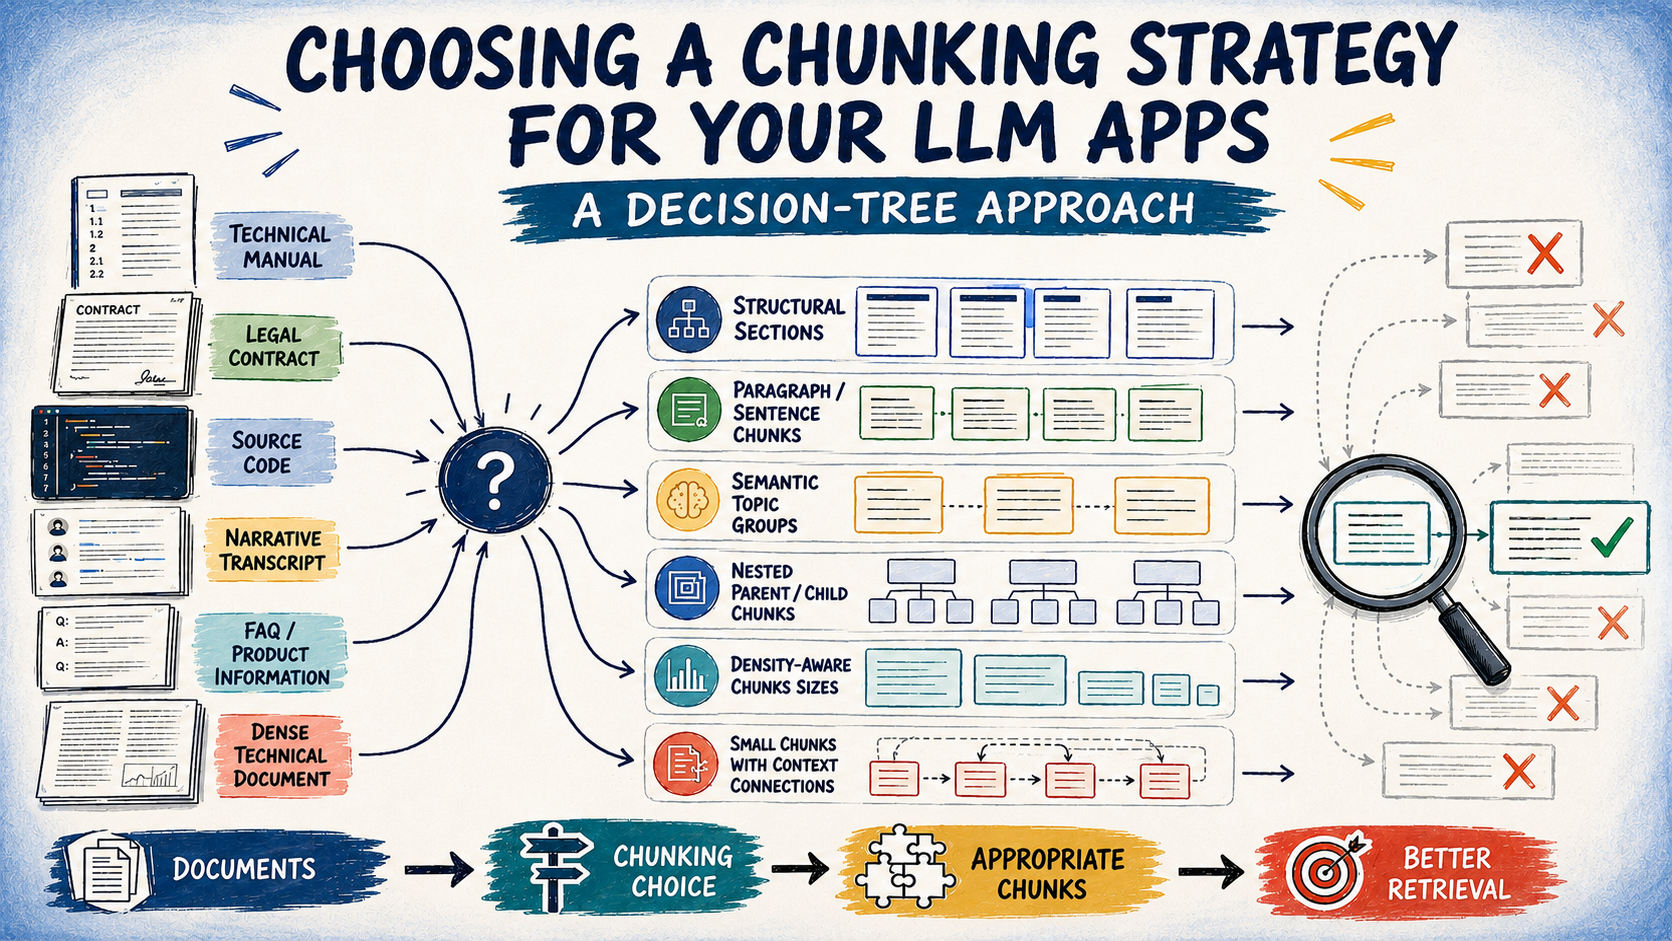
In this article, you will learn how to choose the right chunking strategy for a retrieval-augmented generation system by working through a structured decision tree...
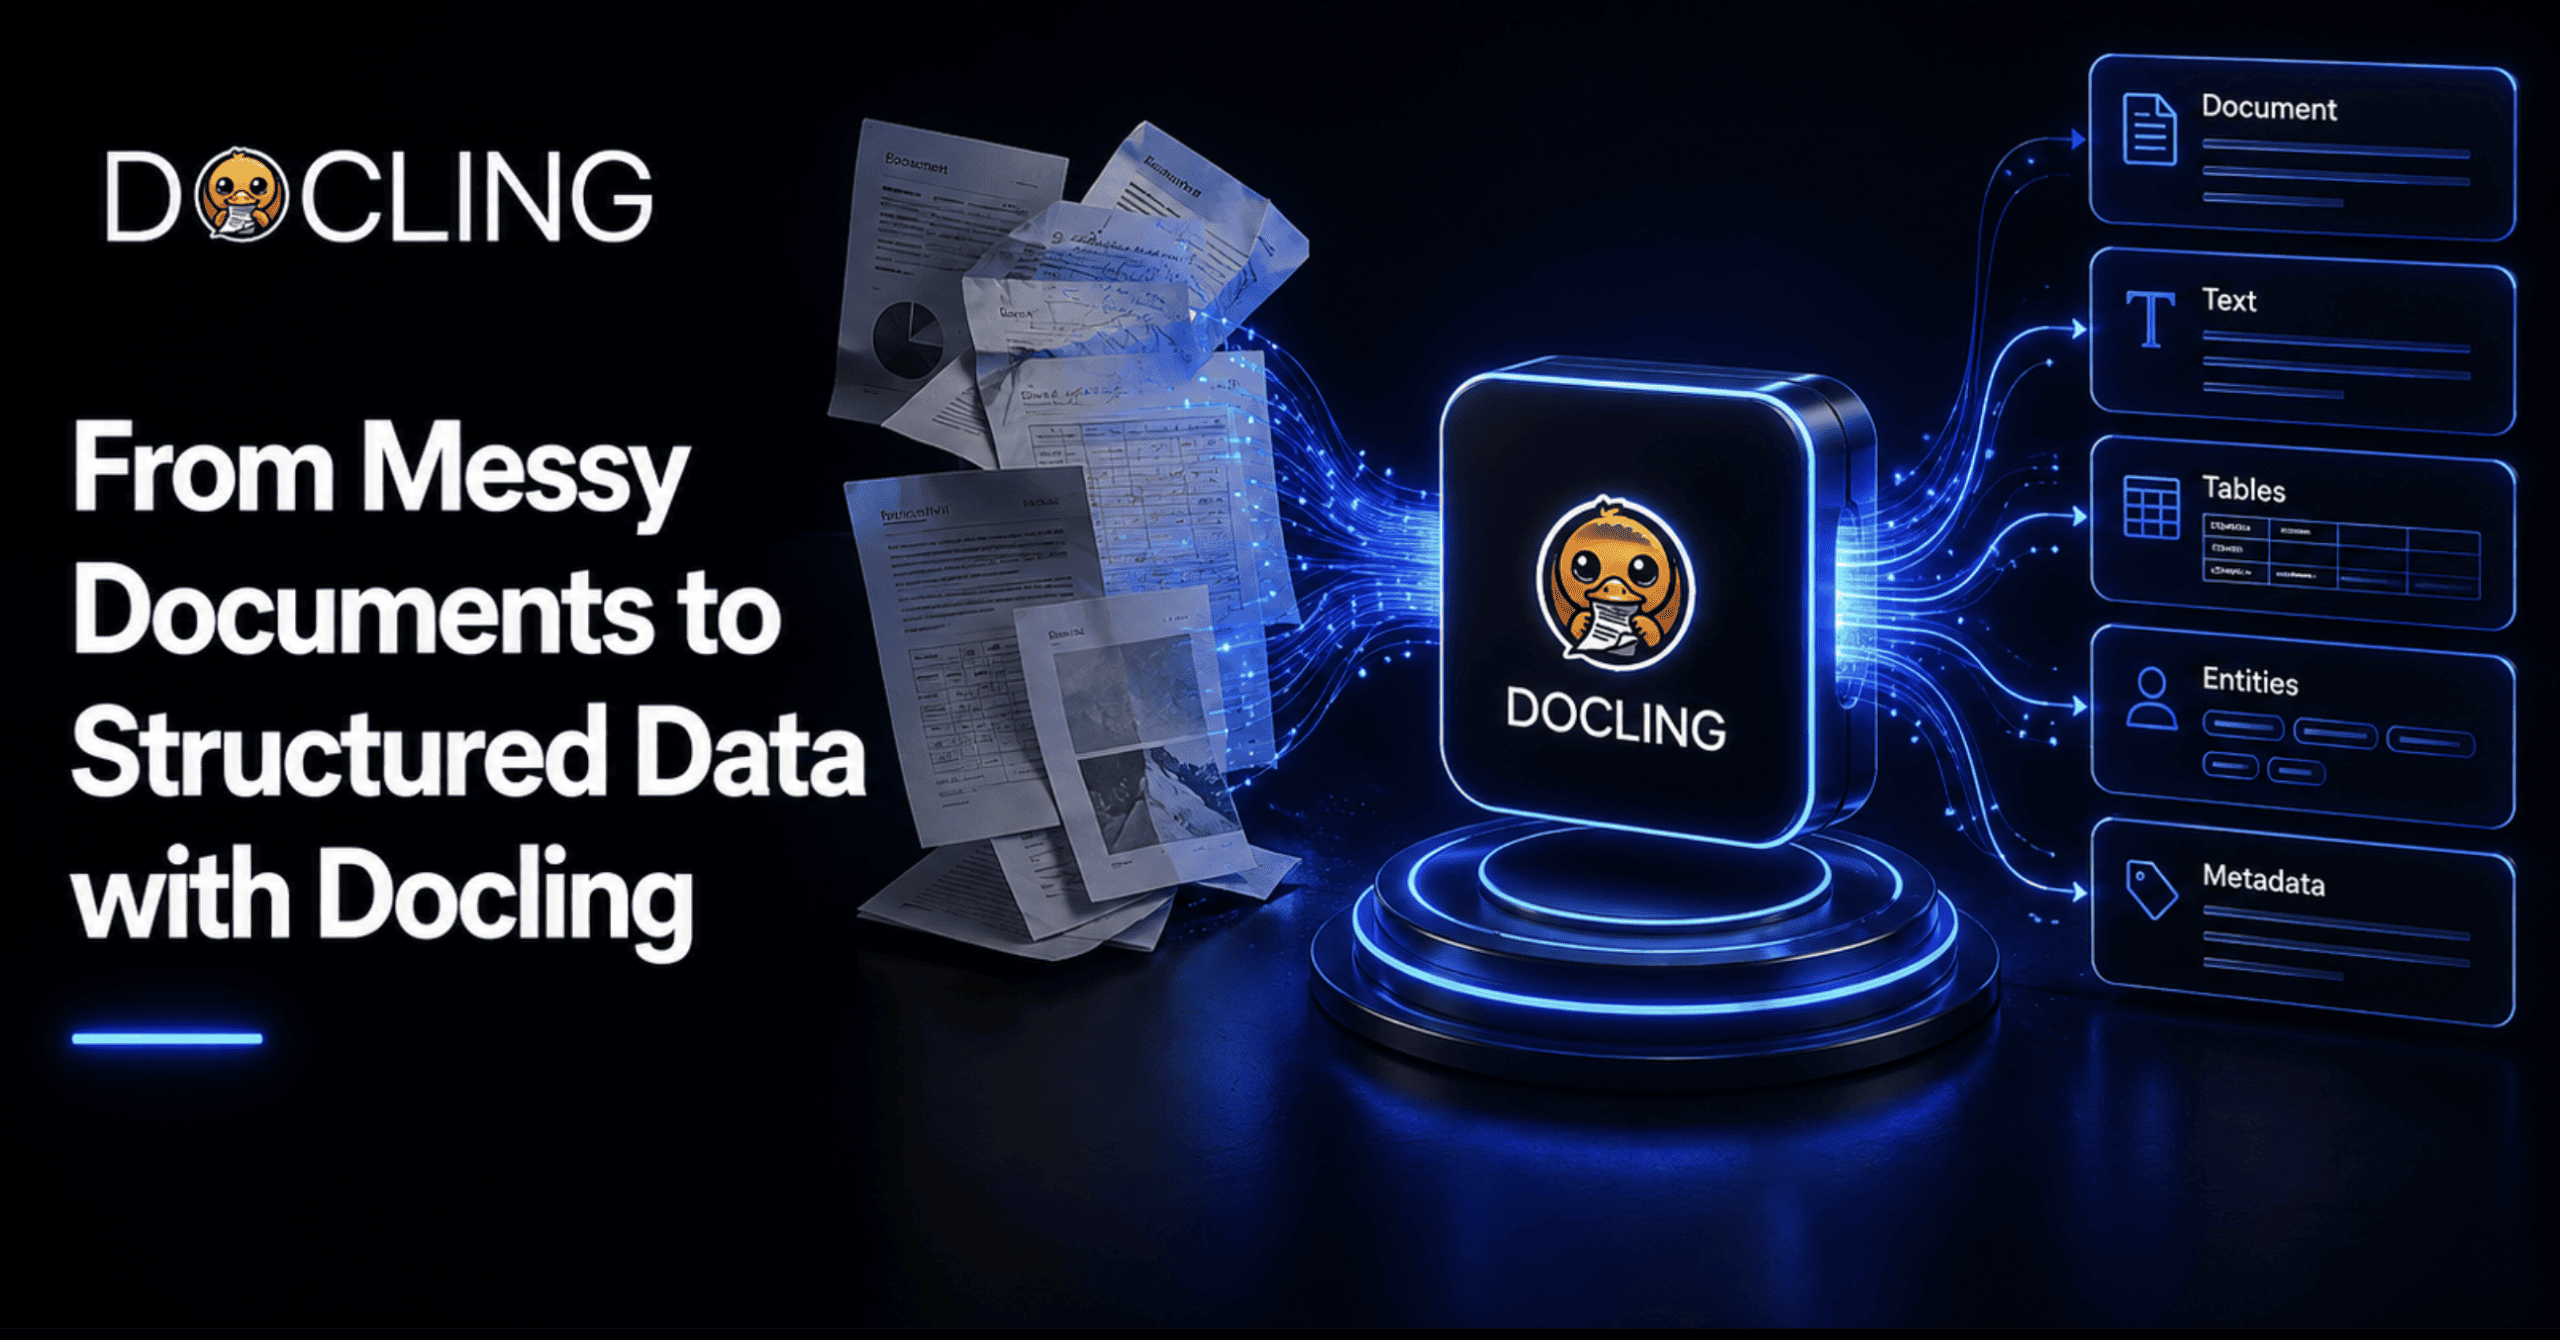
Docling takes documents in whatever inconsistent format they arrive in, and converts them into one unified, structured representation that both people and AI systems can work with...
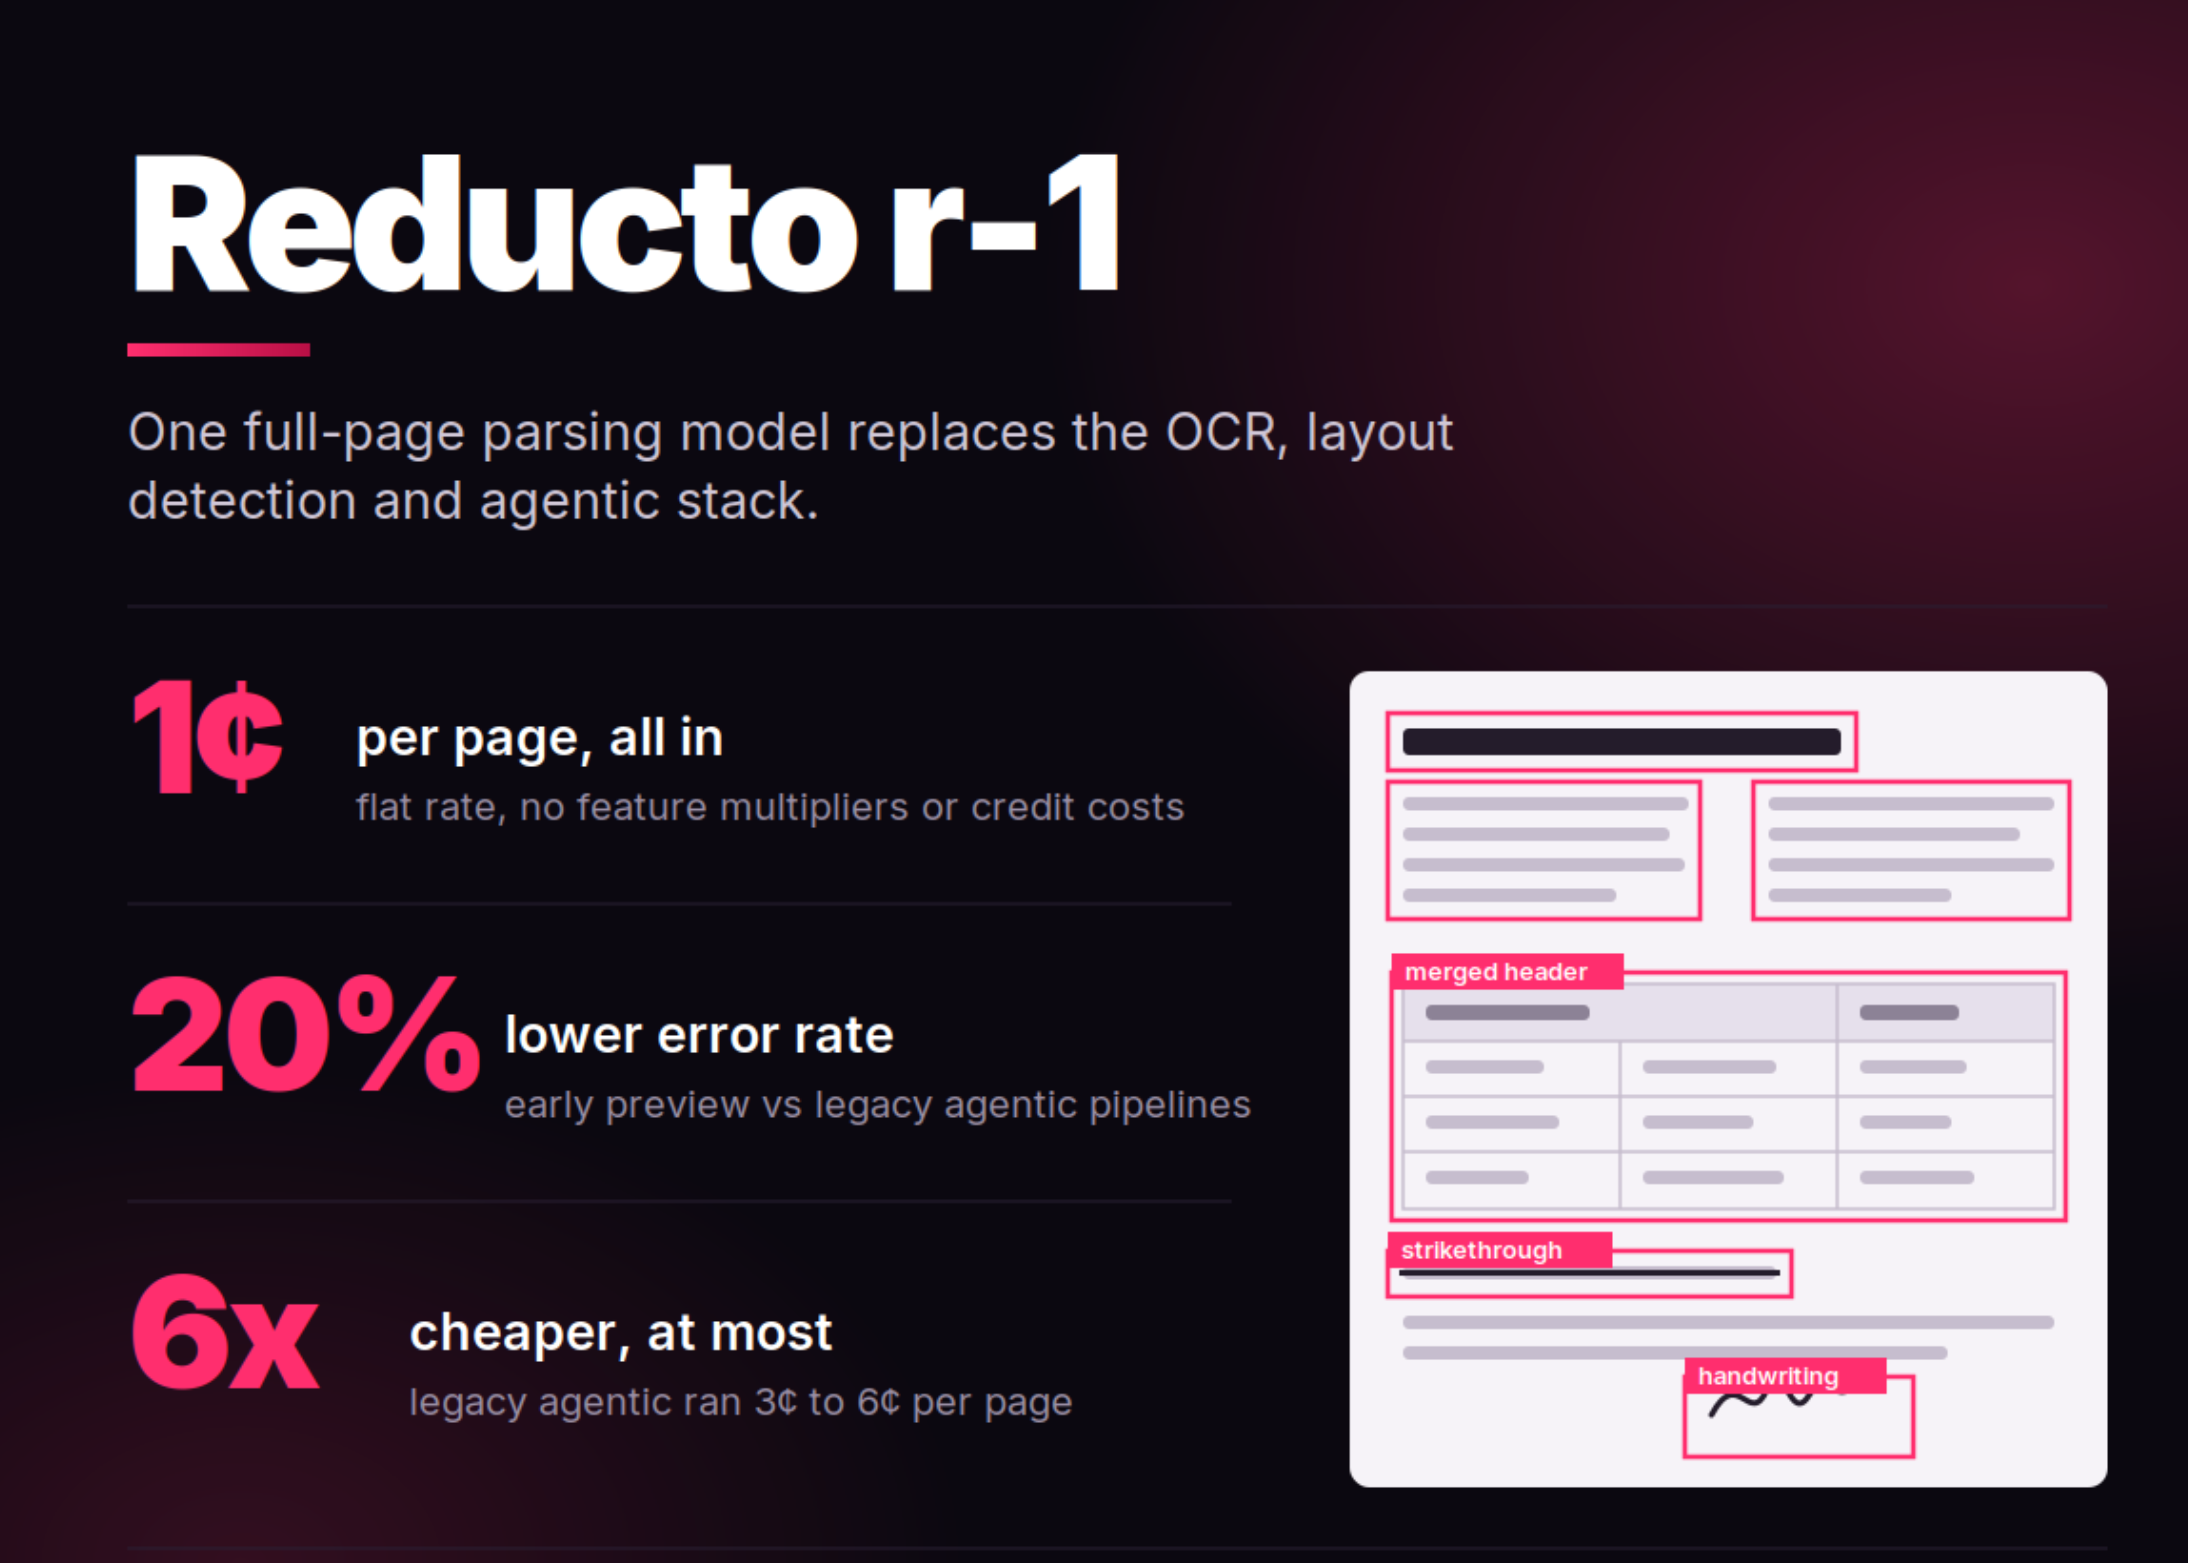
We look at r-1, the document parsing model Reducto released on September 1, 2026. We walk through how it folds OCR, layout detection, tables, formatting and grounding into one full...
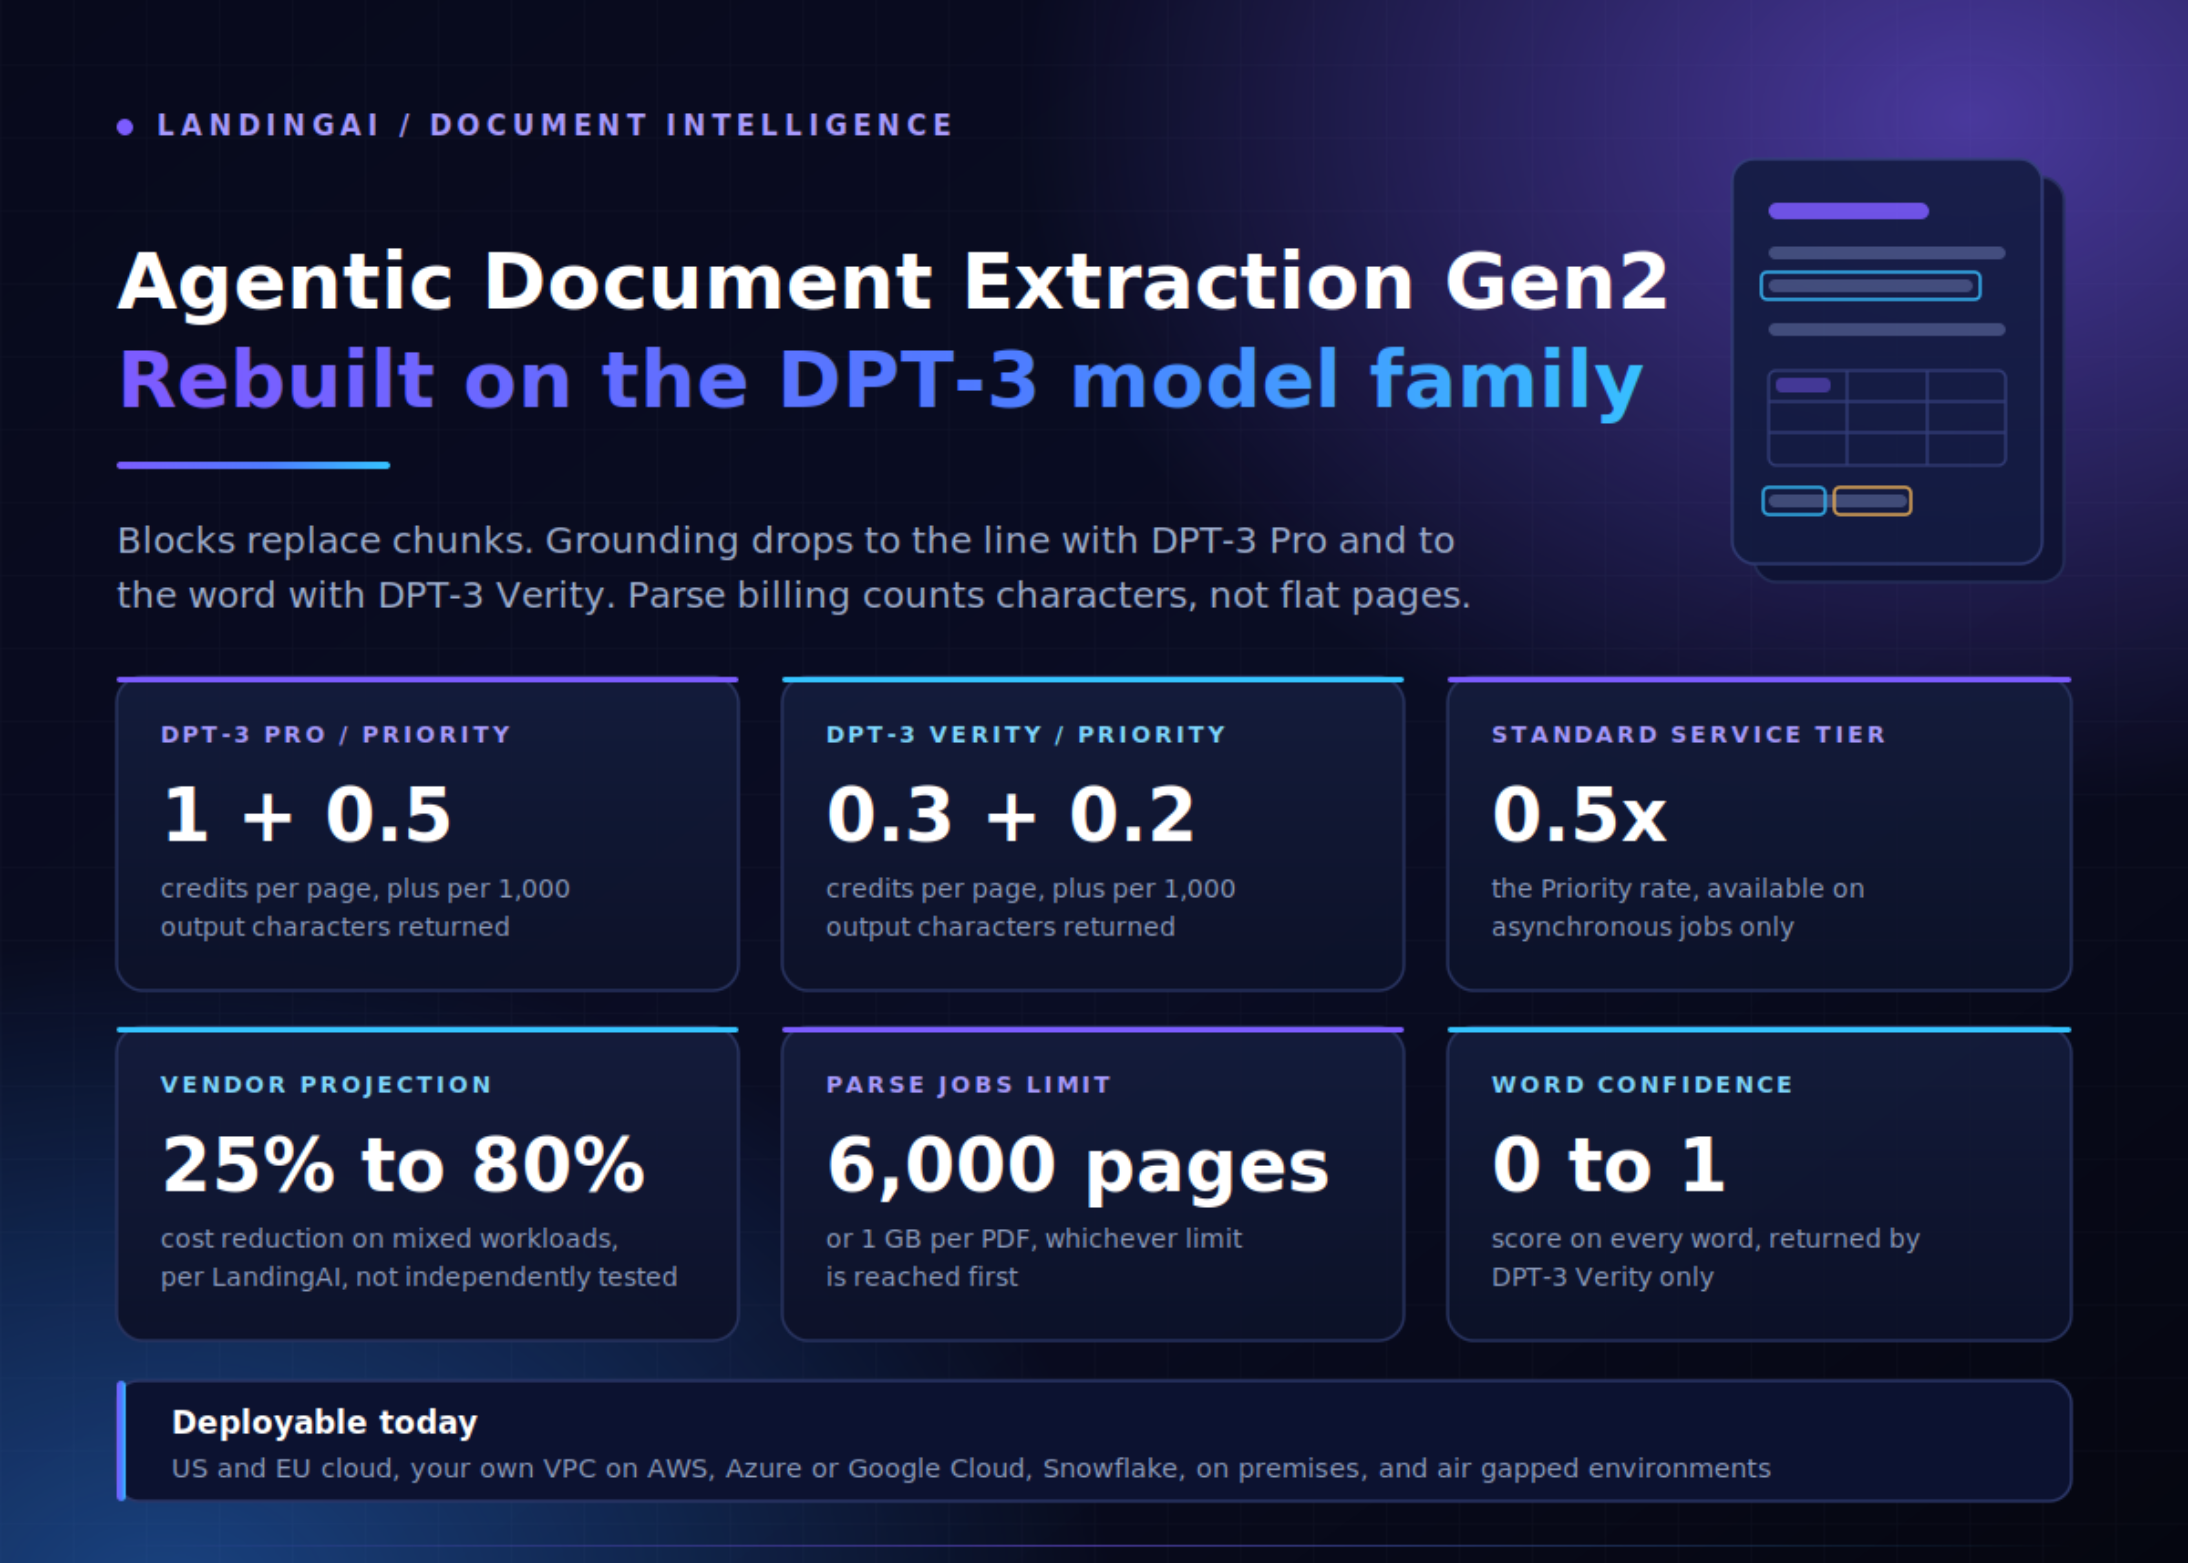
LandingAI has shipped Agentic Document Extraction Gen2, a rebuild of its document stack on the DPT-3 model family. Chunks are retired in favor of a document, page and block tree. D...
Cohere has released Parse (parse-v5.0), a 2.3B-parameter vision language model that converts PDFs, slides and images into Markdown with HTML tables, bounding boxes and image descri...
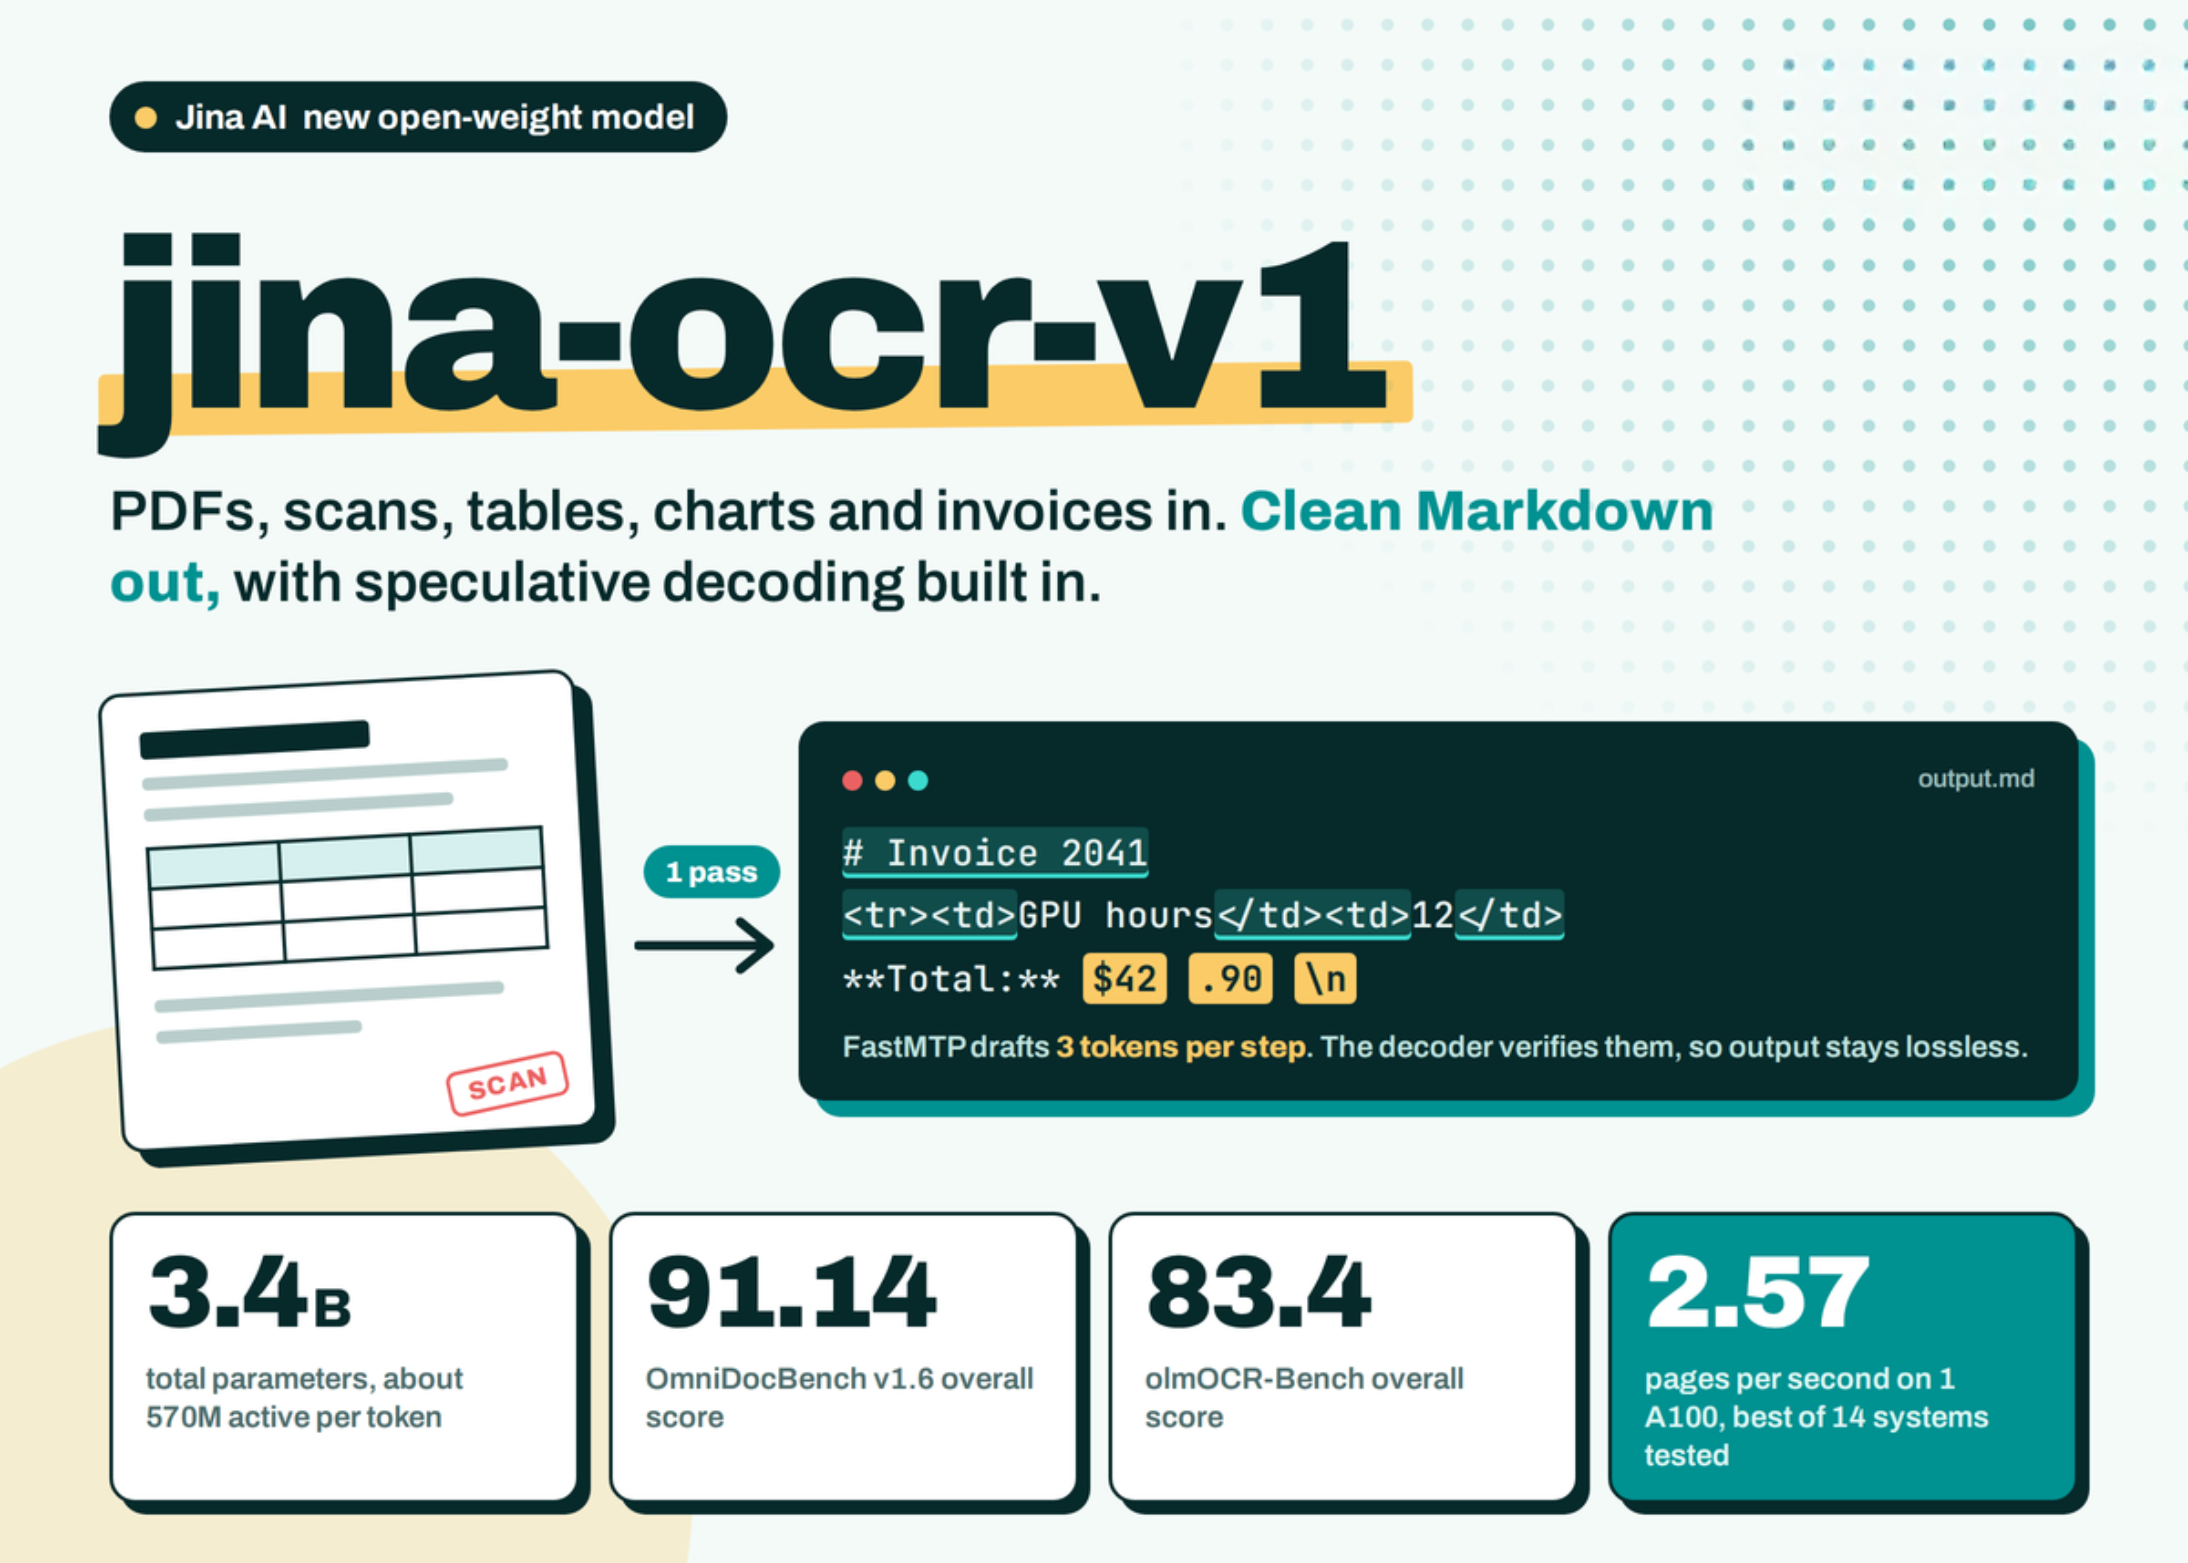
Jina AI has released jina-ocr-v1, a visual document parser that converts PDFs, scans, tables, charts and invoices into Markdown. The model has 3.4B total parameters, with about 570...
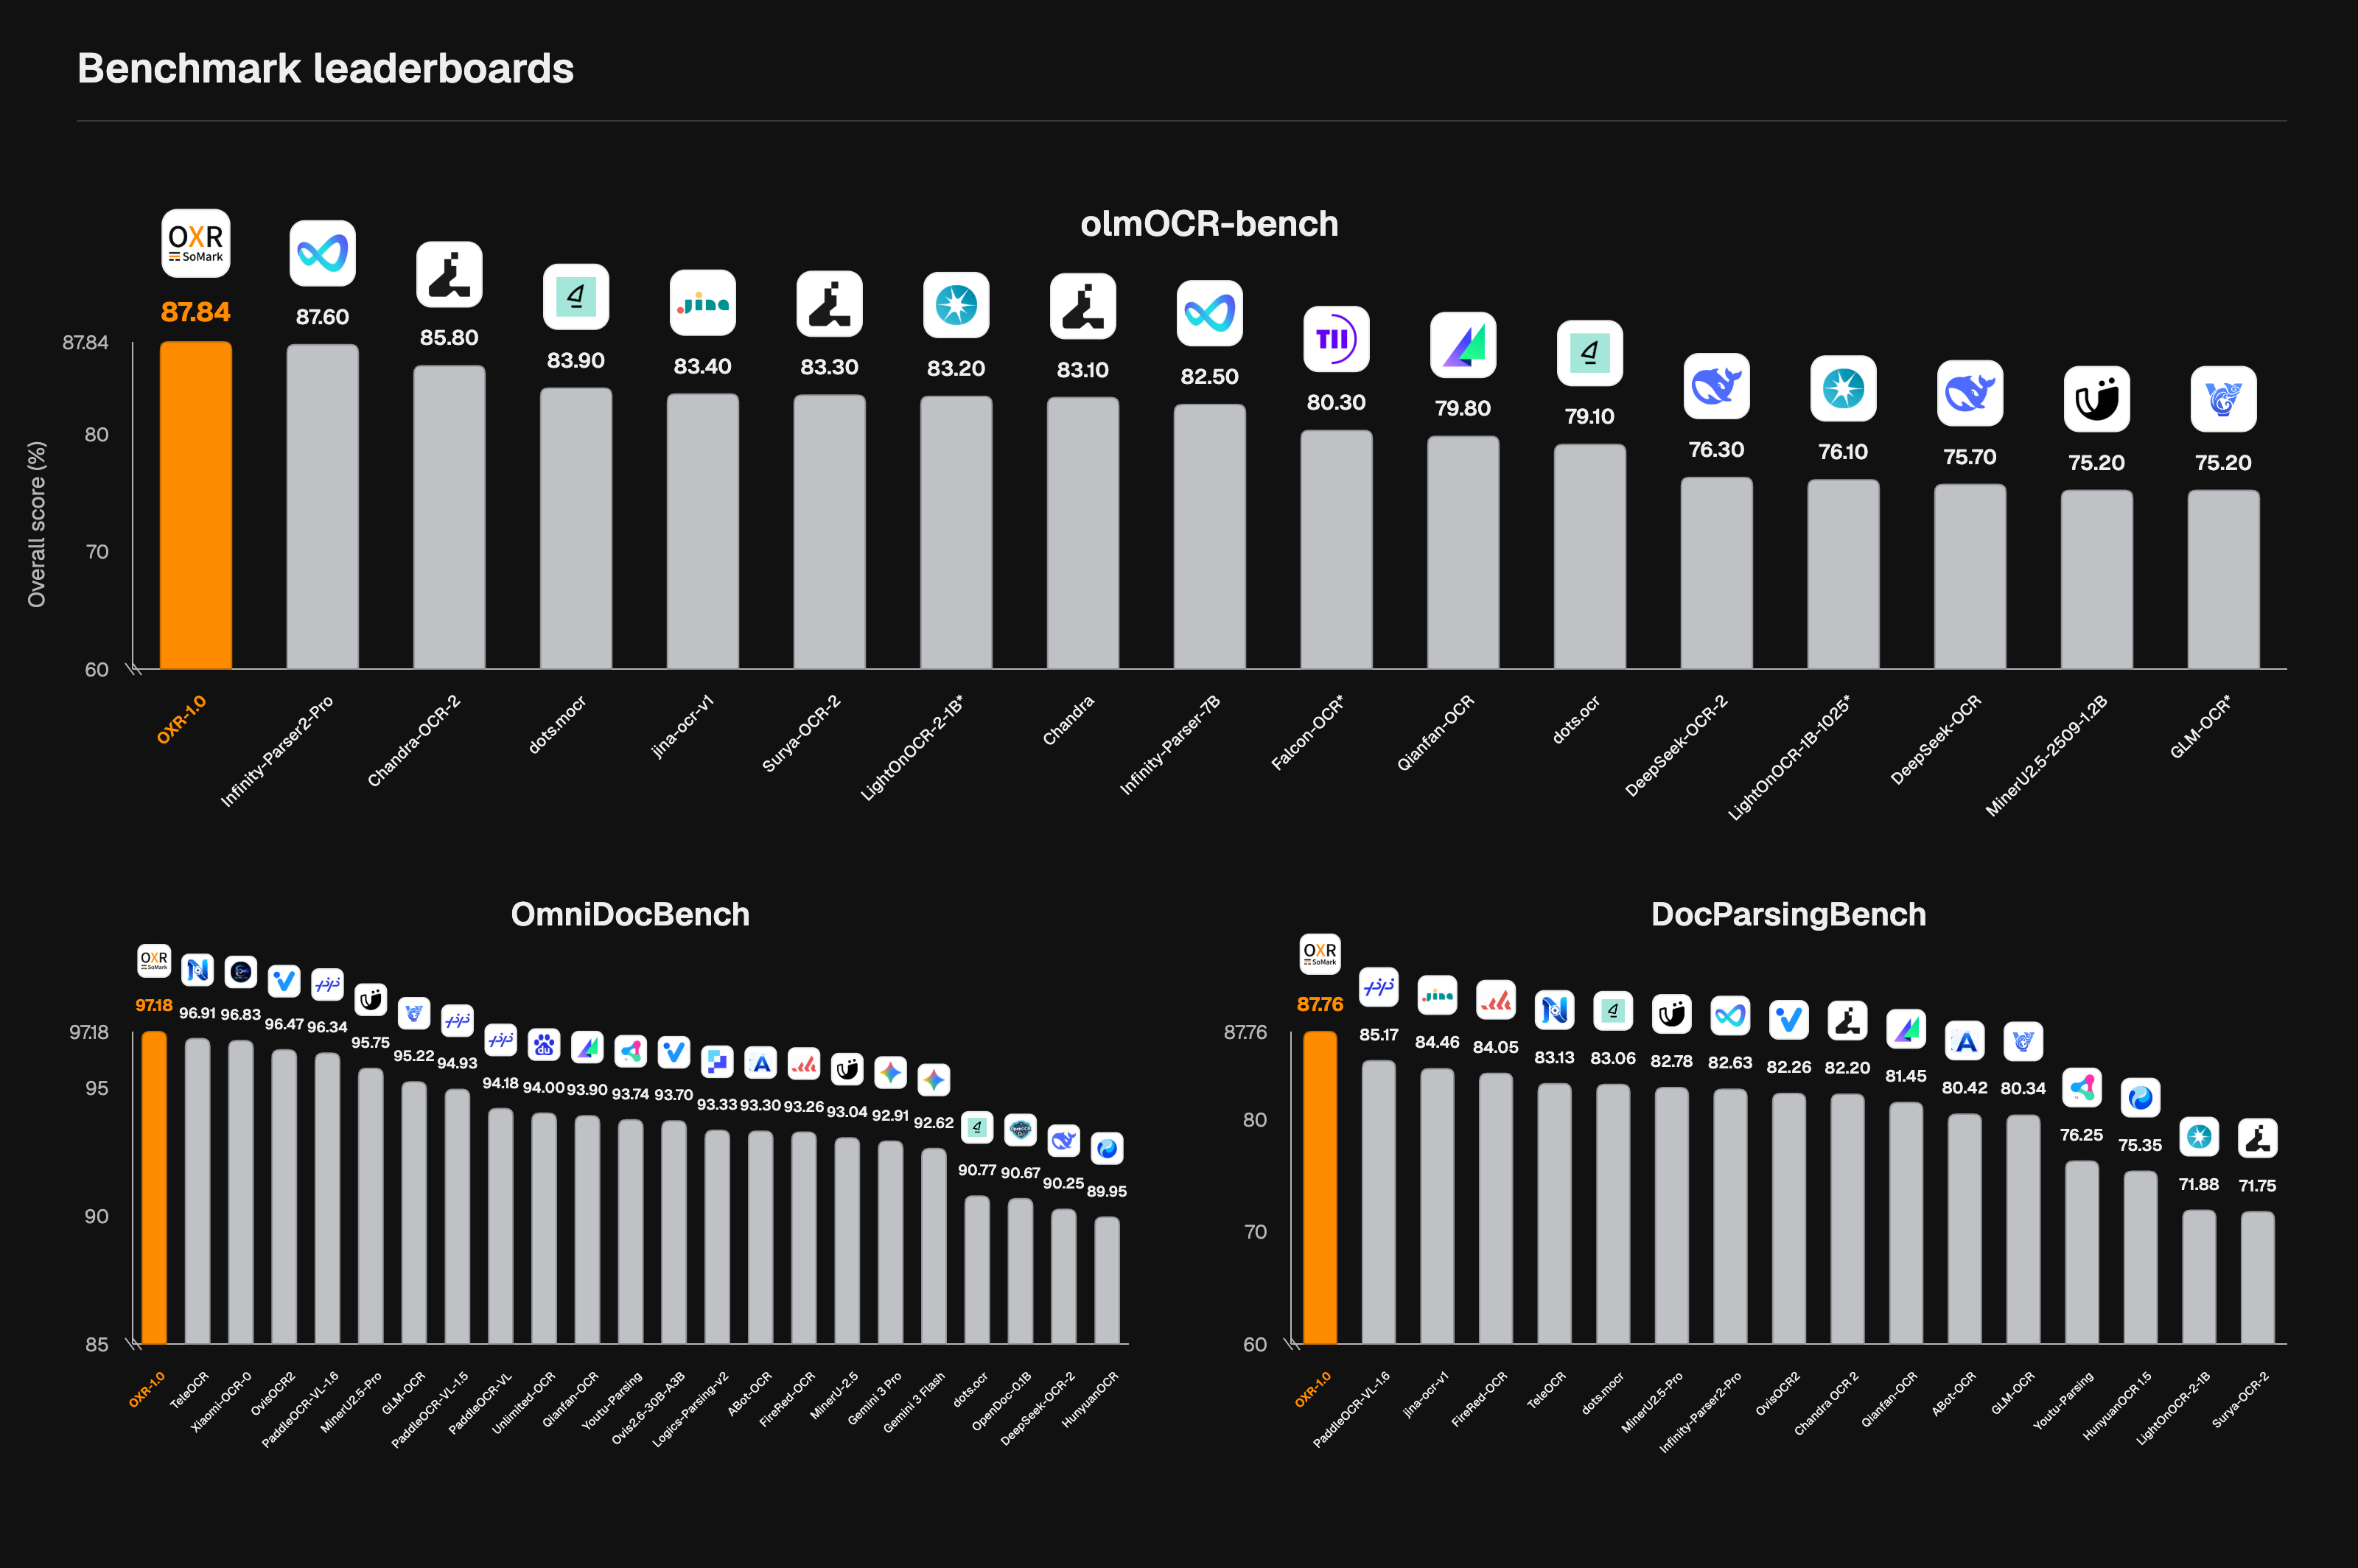
The team behind SoMark open-sources OXR, the first document parser with RSI. It turns PDFs and document images into Agent-Friendly data with SOTA accuracy and speed. The post OXR G...
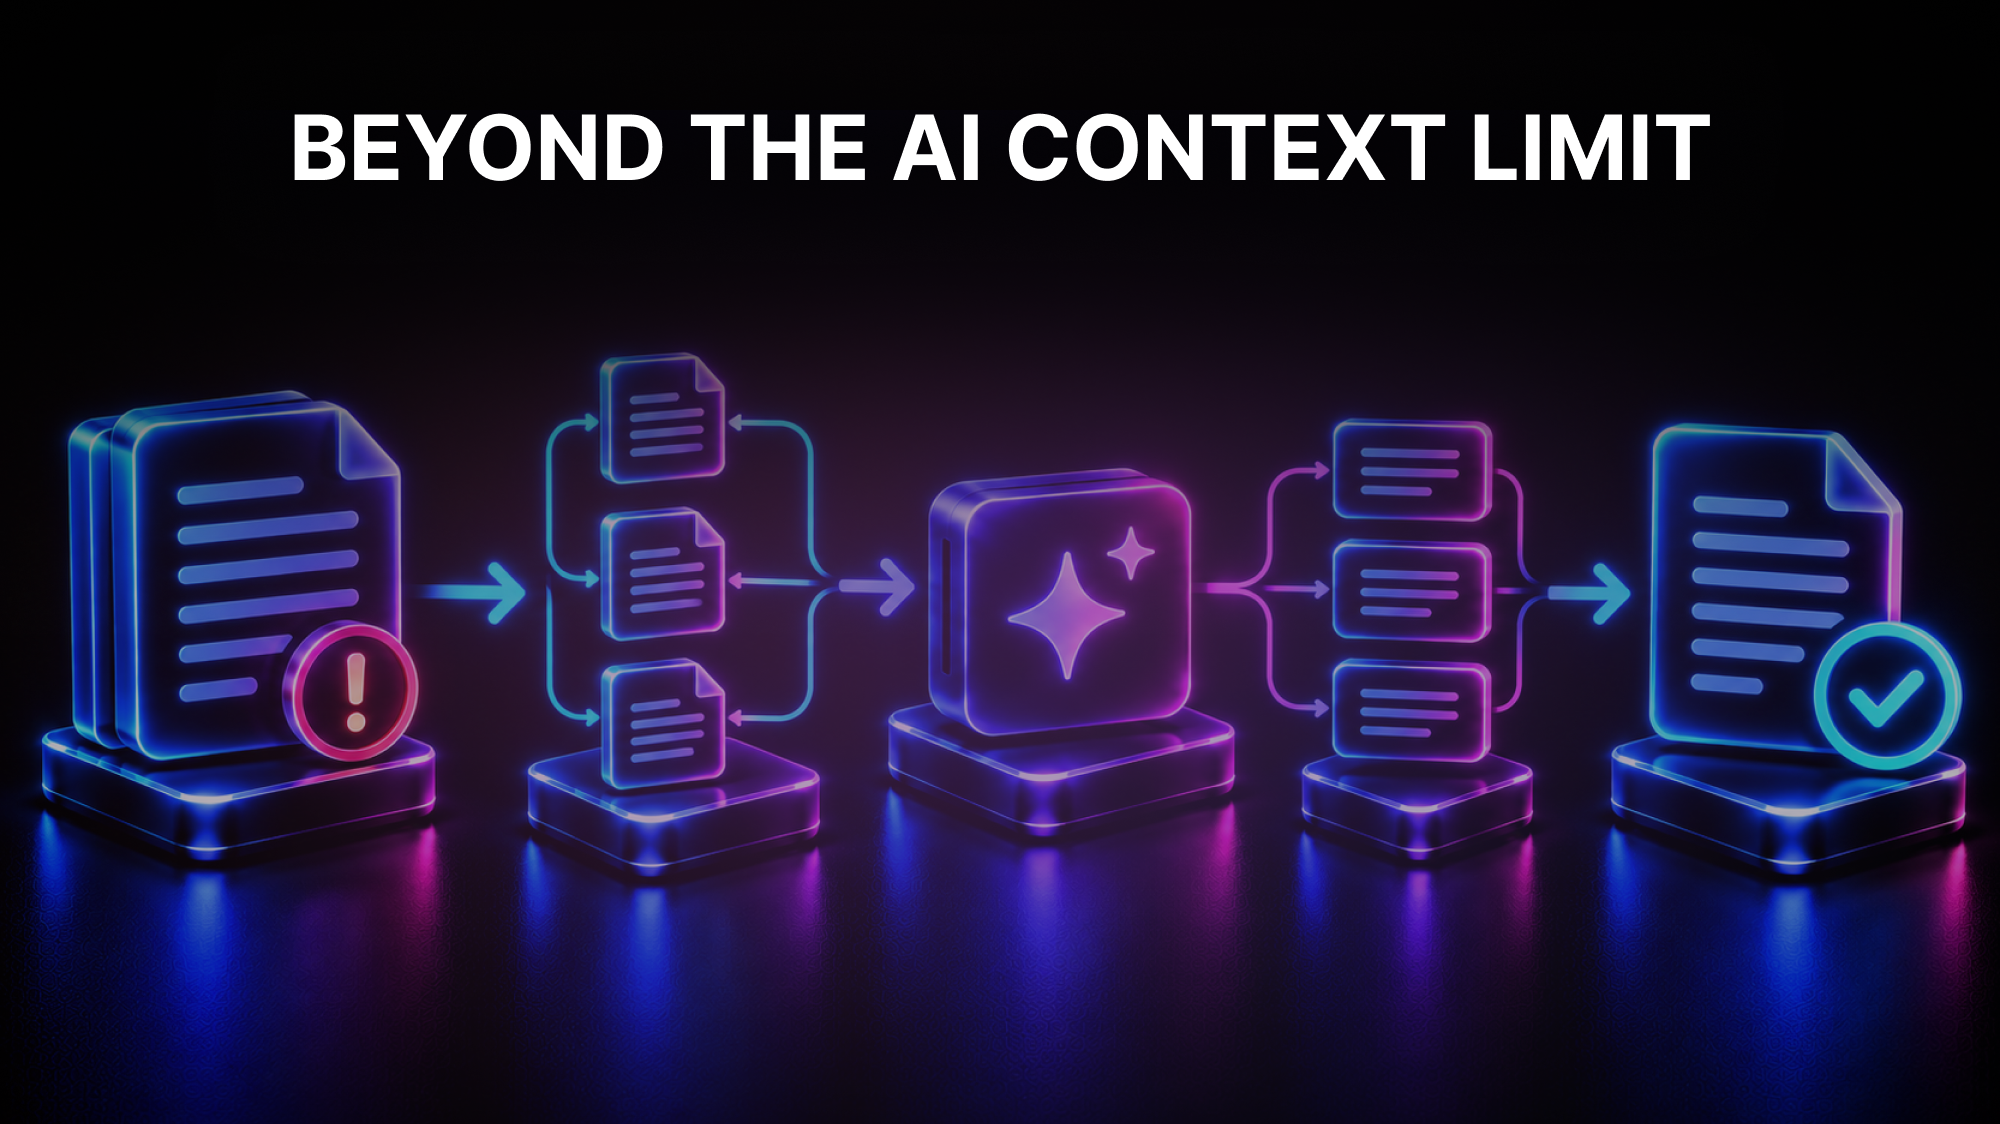
A model can only summarize what it can see, and a long document is often cut short before the model ever reads it. Here is how to notice that, and three ways to summarize the whole...
You have an Excel file that is too large to open comfortably, import or email, and you need it as several smaller files, each with the same header row at the top. In Node.js that t...
Storing extracted document data in a relational JSON or BLOB column works until you need search and scale. Learn how to recognize when document data has outgrown relational storage...
Explore Syncfusion Document SDKs 2026 Volume 3, featuring new JavaScript Excel and PowerPoint libraries, faster Excel data validation, and improved document conversion.
Grouped Highlights, Redaction Stamping, and Moreby Everlaw...
Explore four new libraries coming to Syncfusion Document SDK 2026 Volume 3 for JavaScript Office automation and AI-ready document solutions.
FineParser runs in a CPU-powered container, preserving tables and layout before handing documents to an LLM
A team editing contracts all day doesn’t want a tool that slows down by the fiftieth document, or a free tier that hits a daily cap right when volume is heaviest. No PDF tool, incl...
Learn how to customize an Amazon Bedrock knowledge base for large, complex documents by combining the high-accuracy text extraction of Amazon Textract with the generative AI of Ama...
Visual document retrieval has always leaned on OCR. First, extract the text. Then, run retrieval on that text. This works fine for a clean invoice or a simple contract. But once a...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.