Latest updates for Deepinfer

Fresh curated links around DeepInfer are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • DeepSeek Open-Sources DeepInfer, the Inference Framework Behind DeepSeek-V4.1-Flash
  • DeepSeek открыла исходный код DeepInfer — фреймворка для инференса своего ИИ
  • DeepSeek открыл код движка DeepInfer, на котором запускает свои модели

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

marktechpost.com /4 days ago

DeepSeek Open-Sources DeepInfer, the Inference Framework Behind DeepSeek-V4.1-Flash

DeepSeek has open-sourced DeepInfer, the Apache 2.0 inference framework that serves DeepSeek-V4.1-Flash in production. It targets NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, and...
Read source
3dnews.ru /2 days ago

DeepSeek открыла исходный код DeepInfer — фреймворка для инференса своего ИИ

Китайская ИИ-лаборатория DeepSeek открыла исходный код DeepInfer — фреймворка для инференса, на базе которого работают собственные сервисы компании, сообщает SiliconANGLE. Ключевой...

Read source
computerra.ru /4 days ago

DeepSeek открыл код движка DeepInfer, на котором запускает свои модели

Источник: Компьютерра - Журнал о науке и технологиях DeepSeek опубликовал исходный код DeepInfer — собственного фреймворка для инференса, который компания использует в своих произ...

Read source
systemdesignacademy.medium.com /3 days ago

DeepSeek open-sourced its inference engine. The three parts it left out are the real system design.

DeepInfer runs DeepSeek’s own service and is now on GitHub under Apache 2.0. Its README says a complete service still needs a KV cache…Continue reading on Medium »

Read source
marktechpost.com /3 weeks ago

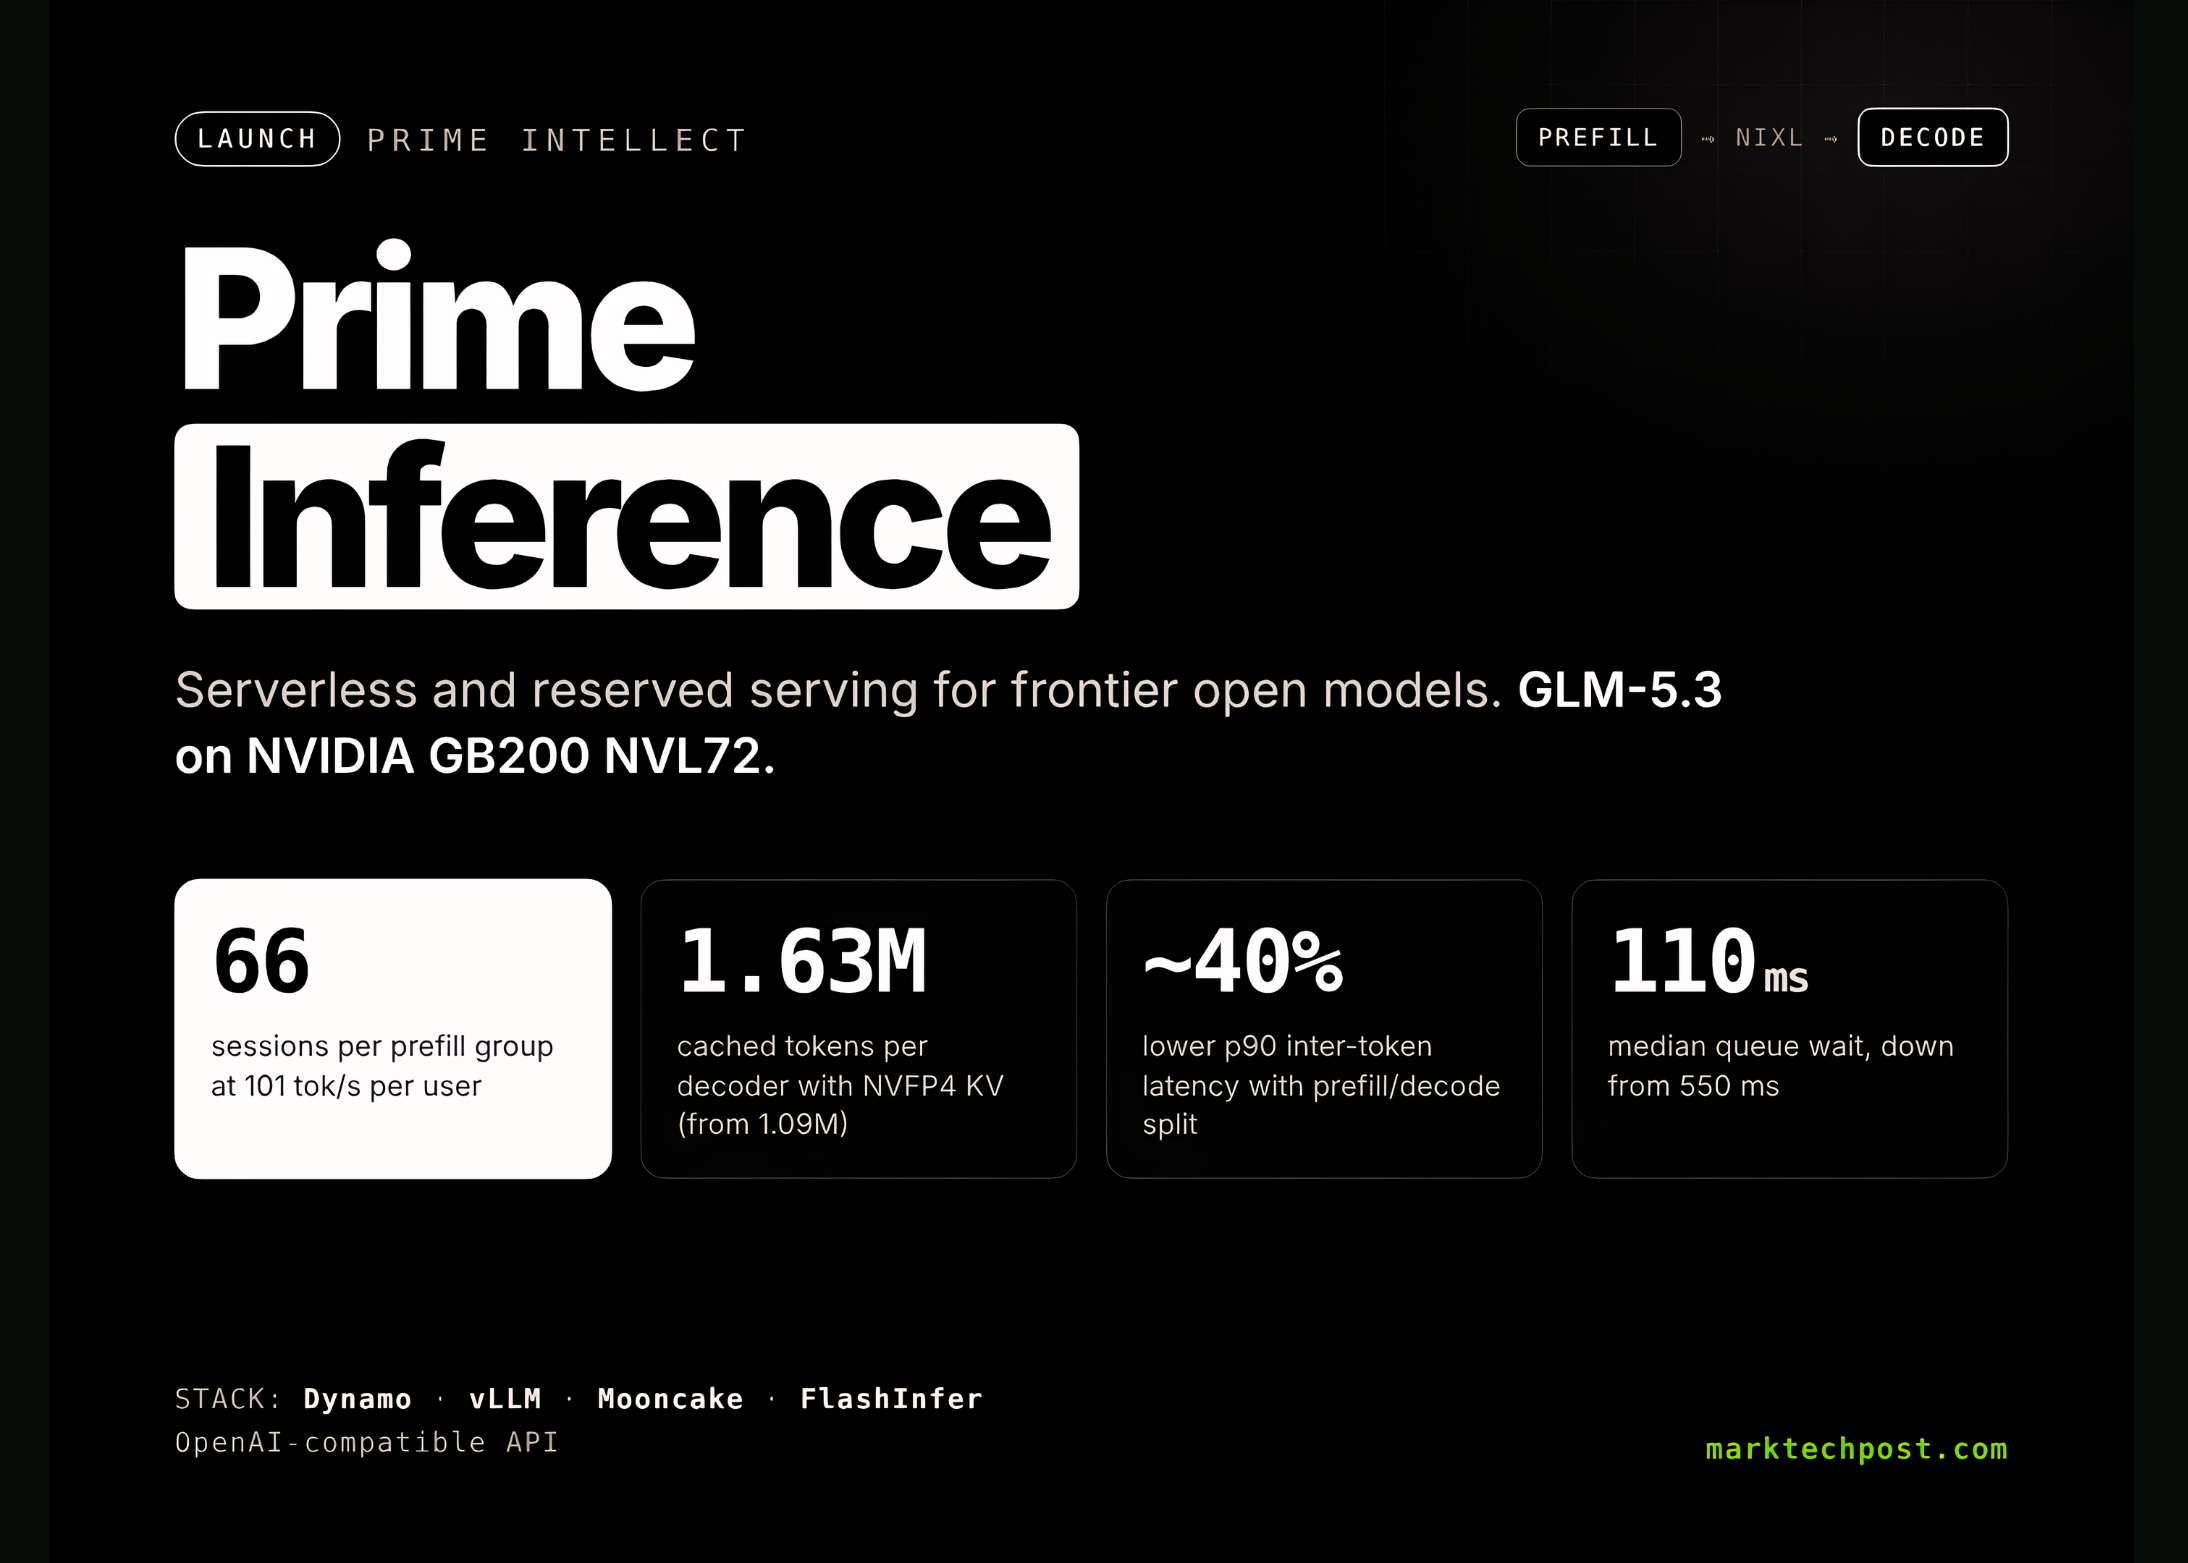
Prime Intellect Launches Prime Inference: Serverless and Reserved Serving for Frontier Open Models

Prime Intellect has launched Prime Inference, an OpenAI-compatible platform for serving frontier open models on NVIDIA Blackwell. Its GLM-5.3 deployment uses Dynamo, vLLM and NVFP4...

Read source
pandaily.com /1 month ago

Infinigence AI Open-Sources APXInf for Embodied Edge Inference on Jetson Thor

Infinigence AI open-sources APXInf with Tsinghua and SJTU: PI 0.5 FP8 on Jetson Thor drops end-to-end latency from ~278 ms to ~26 ms (~38.46 Hz), with Orin/Thor/RTX 4090 support an...

Read source
pandaily.com /15 hours ago

StartLux Open-Sources Prism, an Inference Engine Built for Decision Models With Bit-Exact Outputs

StartLux open-sourced Prism, an inference engine rebuilt for decision models. On one H200, it reports up to 5.3x faster multi-question runs, 41 ms average latency and bit-identical...

Read source
phoronix.com /1 month ago

Debian Inference Portal Launches To Provide Free AI/LLM Inferencing To Debian Developers

With Debian voting to allow the responsible use of generative AI, there is now a new initiative funded by Scaleway to make it easier for Debian contributors to leverage AI: the Deb...

Read source
kdnuggets.com /1 month ago

Speed Up LLM Inference with DSpark Speculative Decoding

Learn how DSpark speculative decoding can improve local LLM generation speed using the same GPU, with Qwen3-8B, llama.cpp, and CUDA.

Read source
kdnuggets.com /1 month ago

Speed Up LLM Inference with DSpark Speculative Decoding

Learn how DSpark speculative decoding can improve local LLM generation speed using the same GPU, with Qwen3-8B, llama.cpp, and CUDA.

Read source
pandaily.com /5 days ago

SenseTime's SenseCore Details Prefill/Decode Split Clusters for Agentic Inference

At CSDI Summit, SenseCore described domestic Prefill and high-bandwidth Decode linked by KV Cache, about 5x token throughput in one test, and a path from 6 to 10 trillion tokens a...

Read source
marktechpost.com /2 weeks ago

Architect Launches Liquid Inference, a Real-Time Auction for LLM Inference

Architect Financial Technologies has launched Liquid Inference, an LLM router that runs a live auction for every request. Liquid Inference is an LLM inference marketplace from Arch...

Read source
scmp.com /3 days ago

DeepSeek seeks ‘total victory’ over closed-source AI with new open-source tool

Chinese artificial intelligence start-up DeepSeek has fully open-sourced an internally developed framework designed to run AI models efficiently, as a senior researcher at the comp...

Read source
marktechpost.com /1 day ago

Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms LFMs

Liquid AI released RIPL, a real-time inference engine for its LFM models. On one B200, LFM2.5-1.2B on RIPL showed 14.4 to 28.4x lower p95 latency than Qwen3.5-0.8B on vLLM. The pos...

Read source
marktechpost.com /4 weeks ago

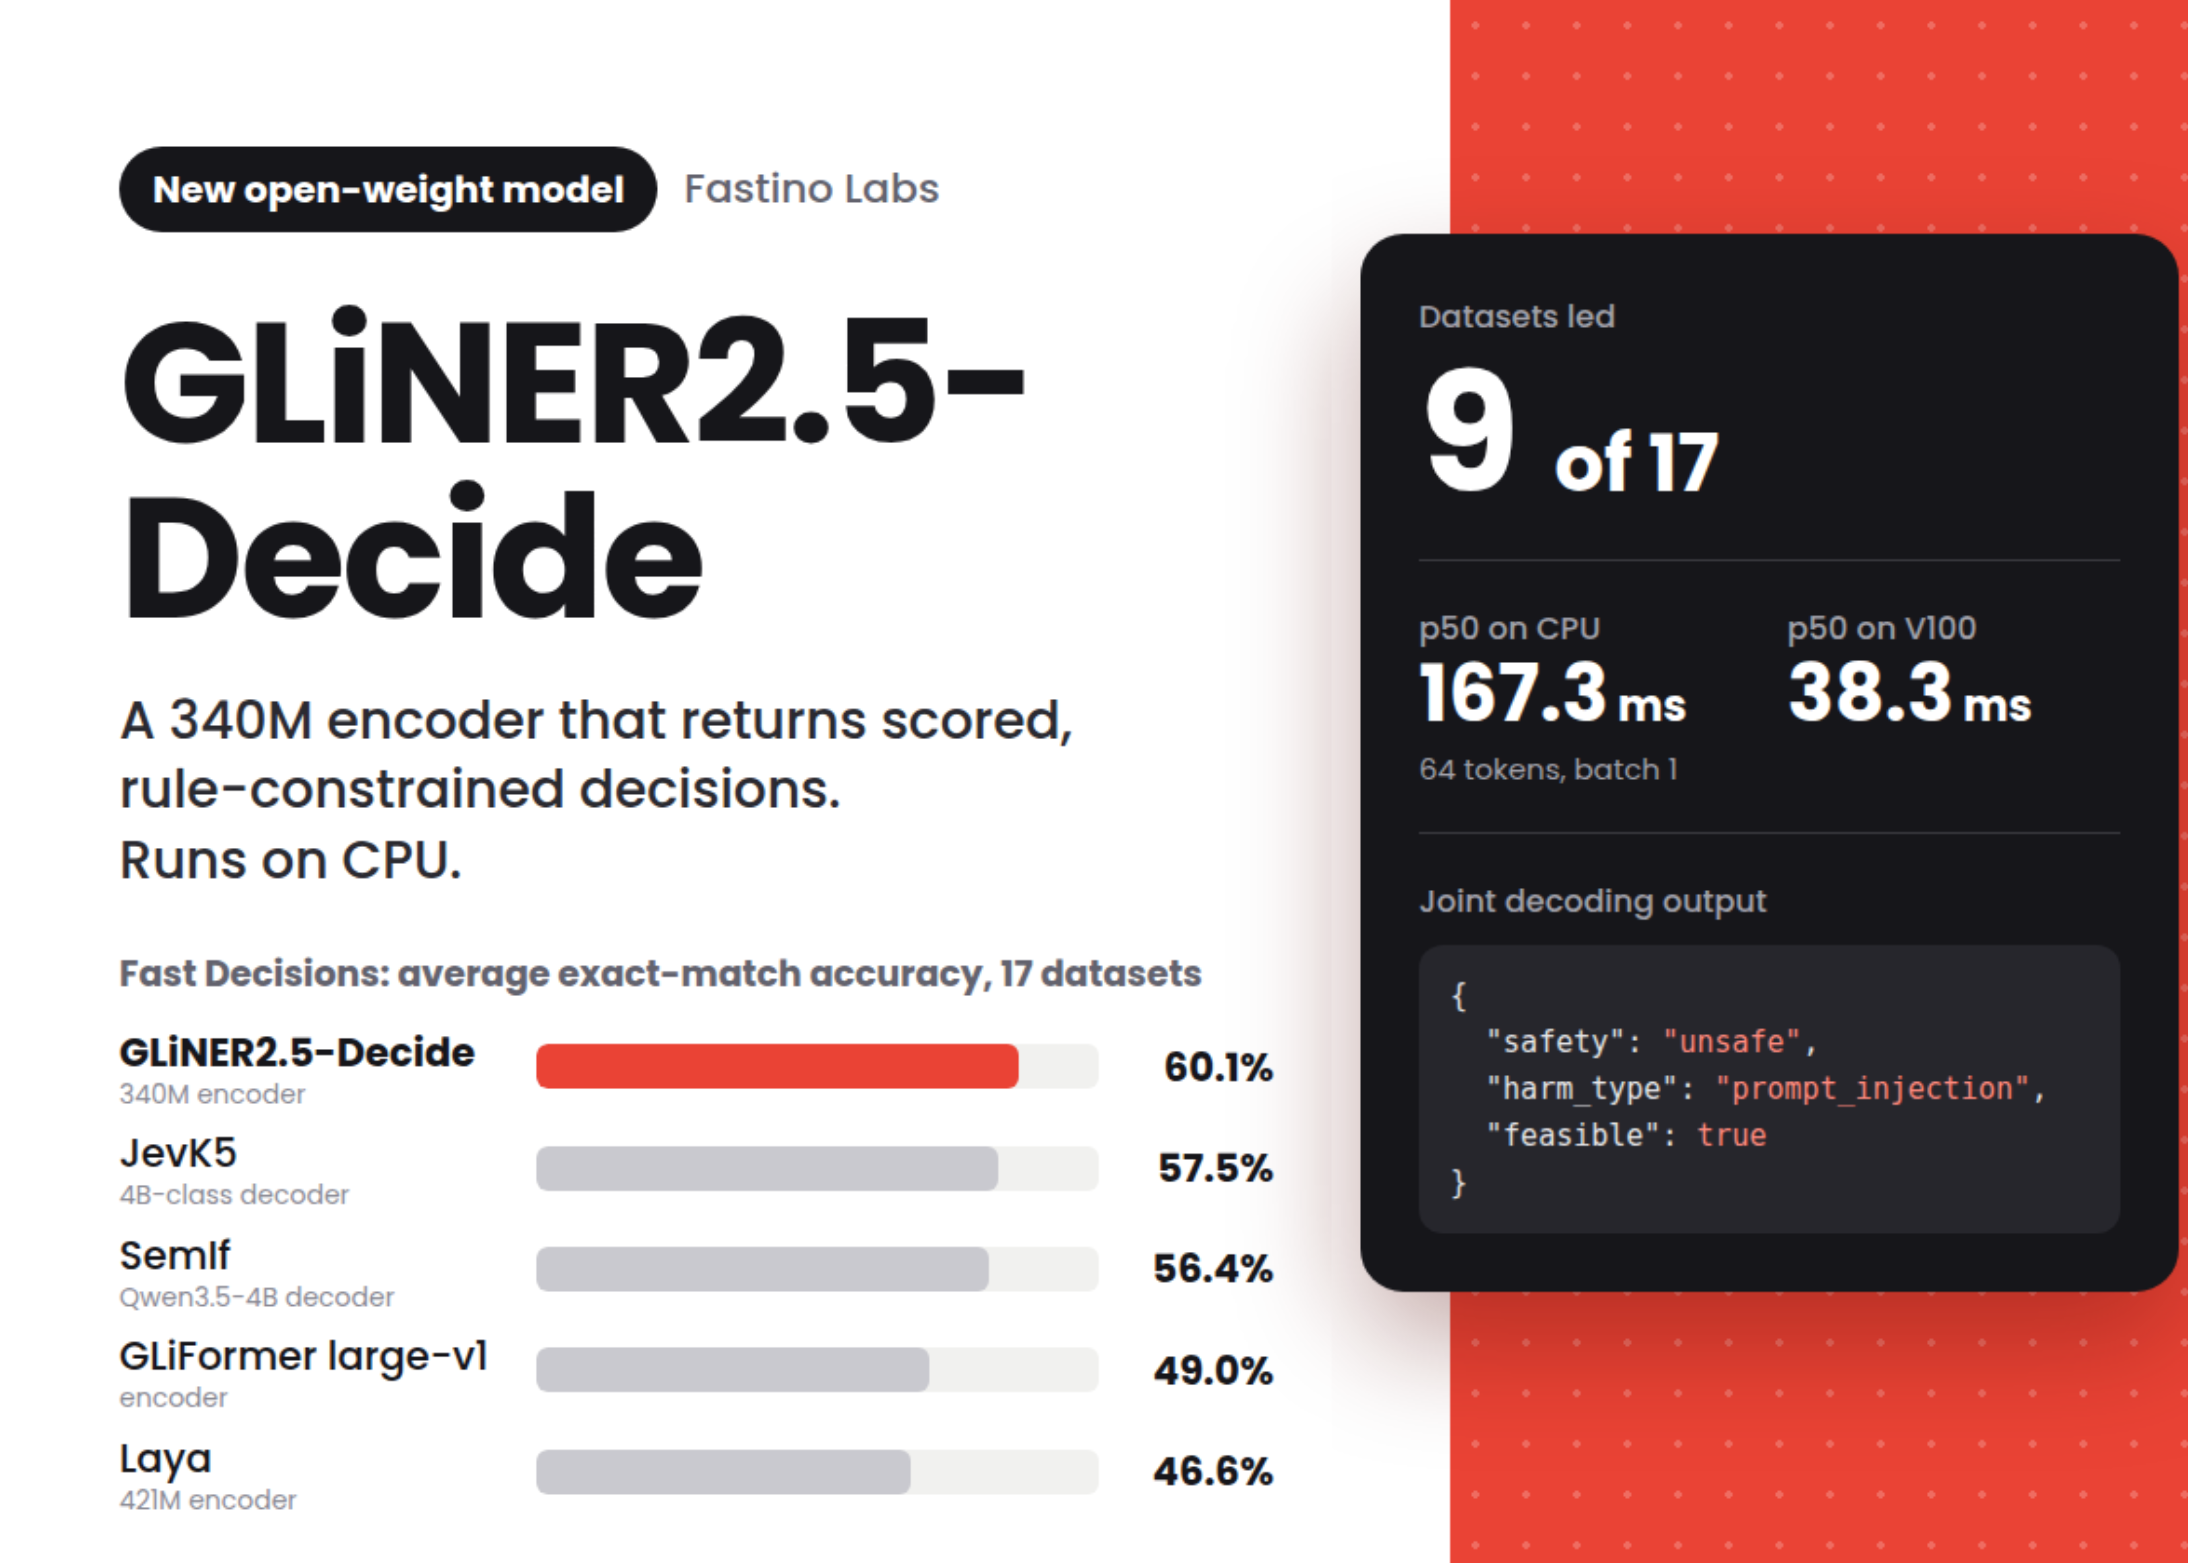
Fastino Releases GLiNER2.5-Decide: A 340M Open-Weight Decision Model That Runs on CPU

Fastino Labs has released GLiNER2.5-Decide, a 340M-parameter open-weight decision model. It takes text and a schema of typed questions and returns structured answers. Each answer c...

Read source
pandaily.com /1 month ago

China Mobile Cloud Debuts GPU–Neuromorphic Heterogeneous LLM Inference Stack

At the 2026 China Computing Power Conference, China Mobile Cloud and partners unveiled a domestic GPU plus neuromorphic mixed-inference system for large models, citing roughly 2× o...

Read source
webkul.com /3 weeks ago

Desert Ant Labs: Exploring the Future of On-Device AI

On-device AI runs specialized models directly on a user’s device instead of sending every request to the cloud. Cloud-based AI offers powerful models but introduces latency, infras...

Read source
pandaily.com /2 weeks ago

Shanghai AI Lab Open-Sources Intern-Decision, Small Models That Output Decisions, Not Text

Shanghai AI Lab's Intern-Decision comes in 0.8B, 2B and 4B sizes and returns choices, scores and yes/no answers with probabilities; MetaX shipped Day-0 support.

Read source
aws.amazon.com /1 month ago

Amazon SageMaker Inference: 2026 year-to-date launches in review

Amazon SageMaker AI shipped 13 inference launches in year-to-date across two deployment paths: fully managed endpoints and Amazon SageMaker HyperPod Inference. This post reviews ea...

Read source
tomtunguz.com /2 weeks ago

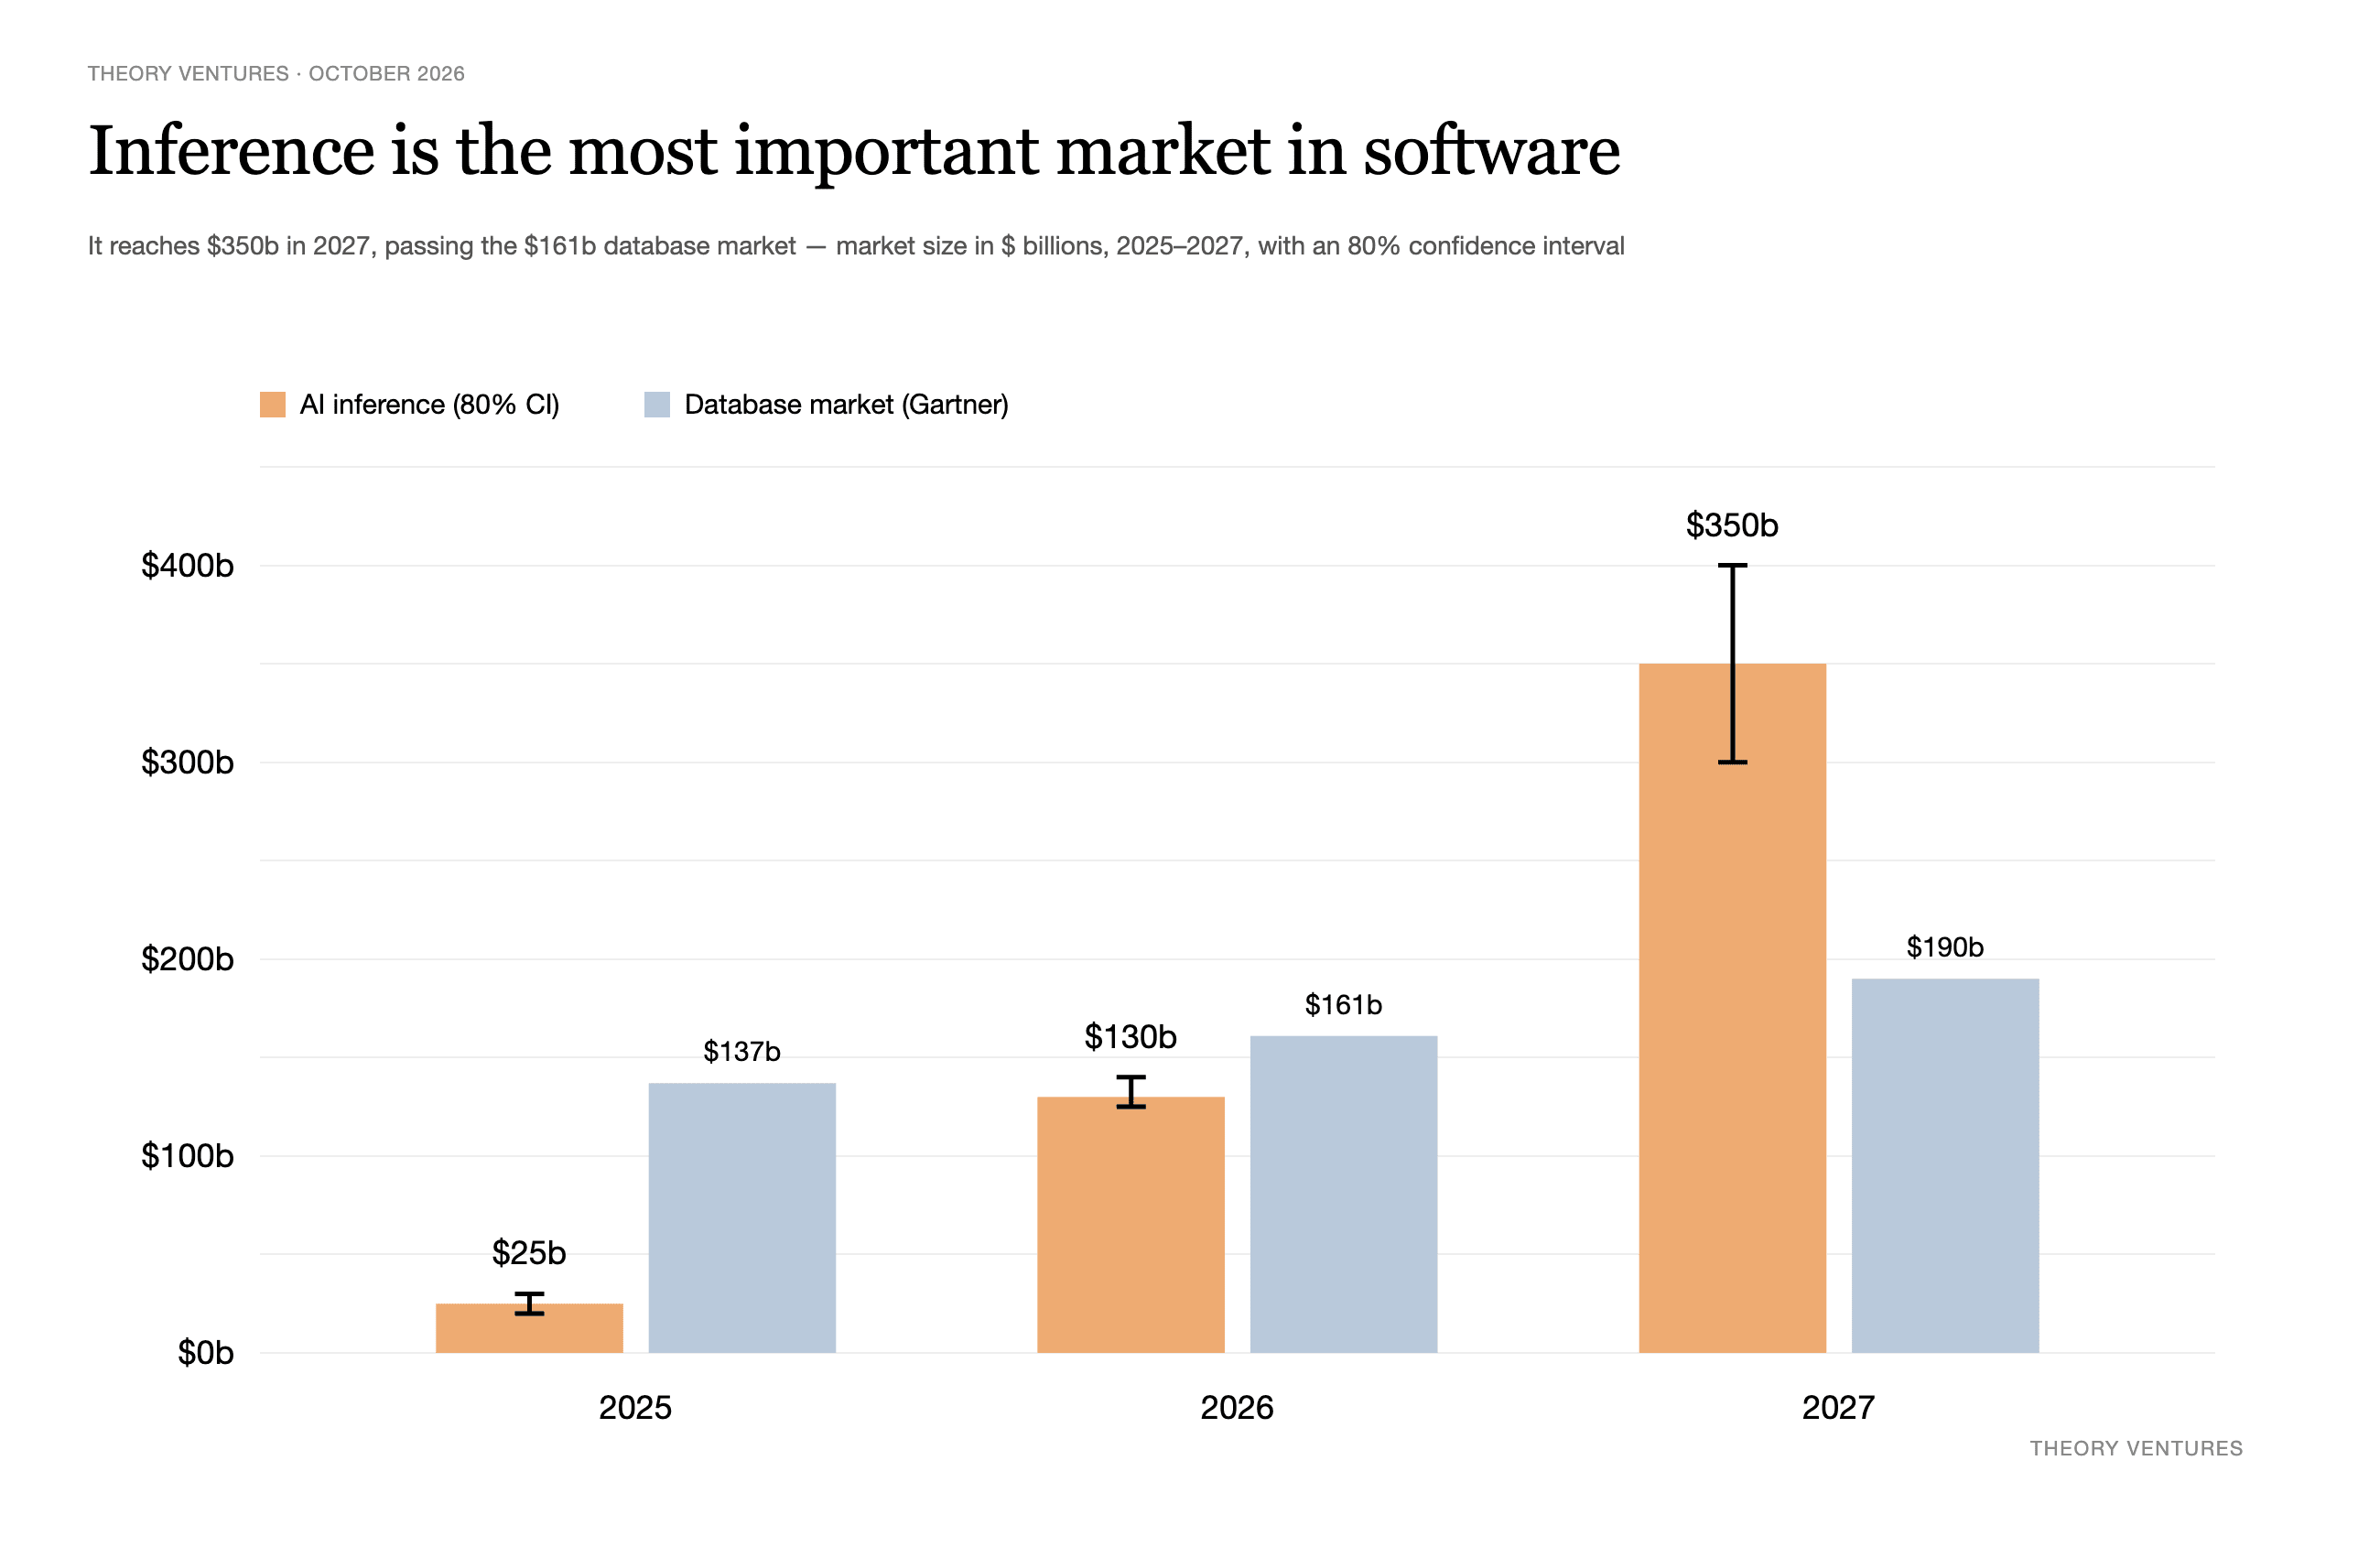
Inference Is the Most Important Market in Software

AI inference is set to surpass the database market to become the most important market in software, reaching ~$350b by 2027. This shifts software unit economics: usage dwarfs platf...

Read source
vexpose.blog /1 month ago

The Inference Bill Is a Memory-Bandwidth Problem

<p class="wp-block-paragraph">You added GPUs to make your LLM serving faster, and tokens-per-second barely moved. The dashboard says the GPUs are 40%</p>

Read source
medium.com /1 month ago

Dedicated Servers for AI Inference: CPU, GPU, RAM and Network Requirements

Why AI inference is a system-level workload, and how to balance hardware for production LLMs.Continue reading on Medium »

Read source
pandaily.com /6 days ago

DeepSeek Makes V4.1-Flash-1017 Official With MIT-Licensed Weights and Stronger Agentic Coding

The minor update lifts Terminal-Bench 4.0 from 31.2 to 42.3, trims run time and output length, and is tuned for DeepSeek Harness and Tencent's CodeBuddy and WorkBuddy. Price is unc...

Read source
cloud.google.com /4 days ago

Announcing llm-d 1.0: Open distributed inference for agents on Google Cloud TPUs and GPUs

Today at the PyTorch Conference, we released llm-d 1.0, an open-source, Kubernetes-native stack for distributed LLM inference. Co-founded by Google with Red Hat, IBM and others, we...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Deepinfer

kdnuggets.com

Recent coverage from public sources
Public source

phoronix.com

Recent coverage from public sources
Public source

scmp.com

Recent coverage from public sources
Public source

3dnews.ru

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

blogs.vmware.com

Recent coverage from public sources
Public source