Latest updates for Database Scalability

Fresh curated links around Database Scalability are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

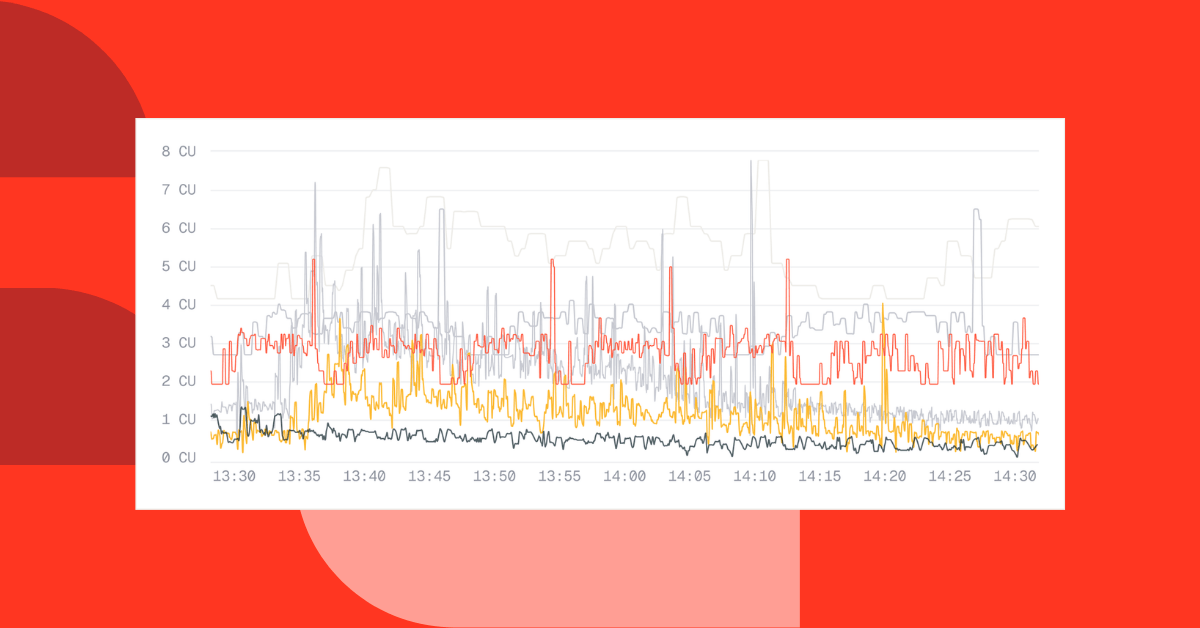
  • Autoscaling Lakebase Postgres
  • A new, no-compromises database architecture for the agentic era
  • AlloyDB delivers PostgreSQL for agents: Real-time data at agent scale, with full workload isolation

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

databricks.com /1 month ago

Autoscaling Lakebase Postgres

Choosing a database instance size before you know the workload is an old building pattern...

Read source
cloud.google.com /4 weeks ago

A new, no-compromises database architecture for the agentic era

Entire database engineering careers have been spent on a single question: How do you scale an OLTP workload without compromising the system of record that owns the data? Exadata an...

Read source
cloud.google.com /4 weeks ago

AlloyDB delivers PostgreSQL for agents: Real-time data at agent scale, with full workload isolation

Enterprises rely on mission-critical operational databases where performance slowdowns simply aren’t an option. Yet when even a few agents execute dense reasoning loops, the unpred...

Read source
databricks.com /2 weeks ago

Scaling and Operating a Large dbt Project on Databricks: IFCO's Data Team on Performance, Visibility, and Debugging

AbstractIFCO runs one of the world's largest reusable packaging pools with hundreds of millions of crates and pallets...

Read source
cloud.google.com /2 weeks ago

Managed Apache Iceberg at scale: How Spanner powers Lakehouse runtime catalog

As customers modernize to lakehouse architectures, they are standardizing on open formats such as Apache Iceberg to create a shared data estate across compatible engines. This enab...

Read source
databricks.com /2 weeks ago

Load terabytes of data in minutes into Lakebase Postgres

Operational databases like Postgres are built to reliably execute highly concurrent...

Read source
wealthysinglemommy.com /1 day ago

Why fast-growing SaaS platforms are re-evaluating their core database architecture

As user demand surges, digital platforms must modernize backend systems to avoid performance bottlenecks. This transformation protects uninterrupted uptime for enterprise customers...

Read source
aws.amazon.com /1 week ago

Modernizing document storage for search, scale, and agility

Storing extracted document data in a relational JSON or BLOB column works until you need search and scale. Learn how to recognize when document data has outgrown relational storage...

Read source
databricks.com /3 weeks ago

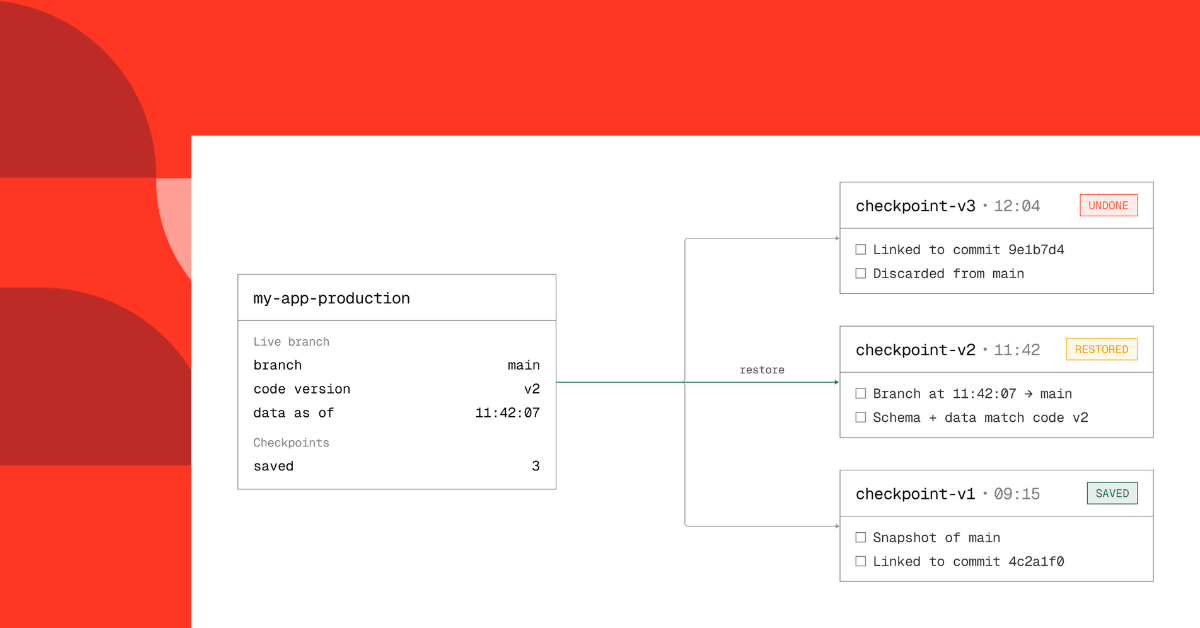
Lakebase Postgres branch-based restores for fast recovery at scale

  In managed OLTP, restores have always been painfully slow and they get slower at...

Read source
databricks.com /1 month ago

Improving Lakebase Postgres compute cache

The disaggregated storage model of Lakebase Postgres provides a feature rich, flexible...

Read source
cloud.google.com /1 month ago

Spanner: Removing cumulative mutation limits for DML transactions

Spanner is Google Cloud’s no-compromise operational database that gives you the horizontal scale and always-on availability of a modern distributed system along with the rich featu...

Read source
databricks.com /1 month ago

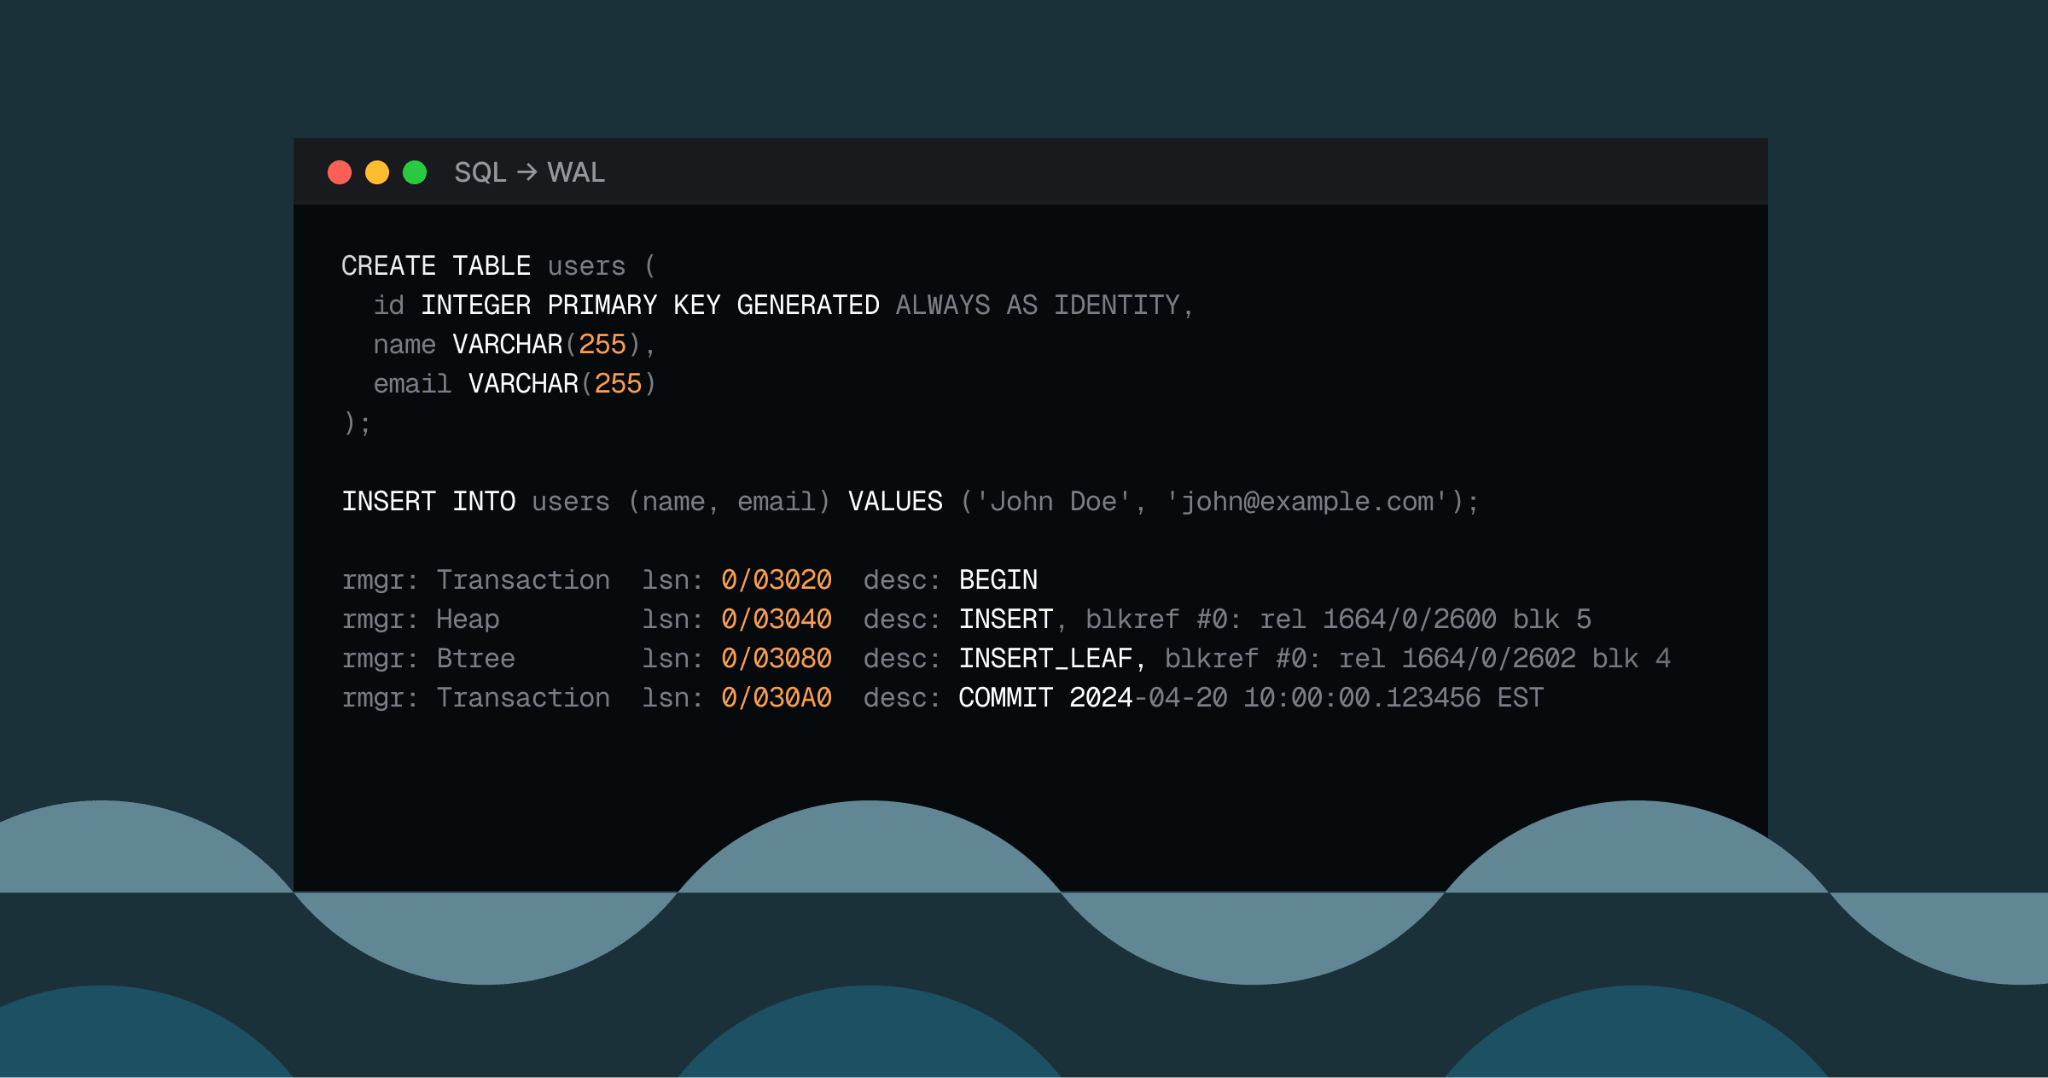
Object Storage + WAL: Lakebase Postgres for the agentic era

Agents that interact with a traditional OLTP database often create bottlenecks at the storage layer. New deployments...

Read source
kodekloud.com /1 month ago

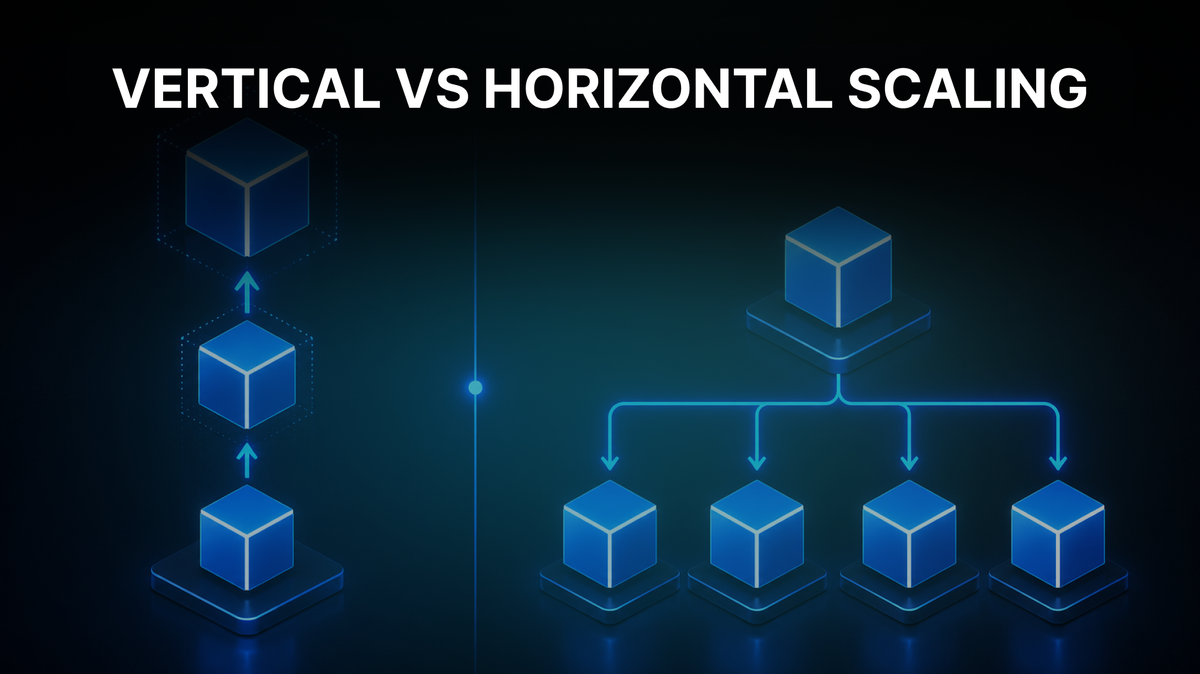
Vertical Scaling vs Horizontal Scaling: Don't Answer Until You've Run top

Vertical scaling vs horizontal scaling is a trap until you diagnose. Why adding RAM hides bugs, and the three-step answer interviewers want.

Read source
dzone.com /1 month ago

The Bottleneck of Scaling

Any input/output operation, be it accessing a file, handling an HTTP request, or a database connection, is based on 3 fundamental system concepts — file descriptors, kernel memory,...

Read source
habr.com /4 days ago

SQL, NoSQL, NewSQL, Distributed SQL: как читать архитектуру СУБД

Для человека, впервые погружающегося в историю систем управления базами данных, последовательность SQL → NoSQL → NewSQL выглядит как диалектическая триада: тезис, антитезис, синтез...

Read source
cloud.google.com /1 month ago

Enterprise-grade PostgreSQL with AlloyDB Omni RPM Orchestrator is generally available

We are thrilled to announce the general availability of the AlloyDB Omni Red Hat RPM orchestrator, that brings production-ready security, resiliency, and low-downtime operations to...

Read source
oflox.com /1 week ago

Database Sharding vs Partitioning: Key Differences Explained!

This article provides a detailed guide to database sharding vs partitioning, how both approaches divide data, and how to choose ... Read more The post Database Sharding vs Partiti...

Read source
medium.com /1 month ago

Designing a Scalable Data Layer in Android

If there’s one place where apps quietly fall apart, it’s the data layer.Continue reading on Medium »

Read source
judoscale.com /1 month ago

Autoscaling on a Sovereign Cloud: Judoscale for Scalingo

Originally appeared on Judoscale Dev Blog. Judoscale now supports Scalingo. If you’ve used Heroku, Scalingo will feel familiar: push your code, run web and worker container...

Read source
dzone.com /6 days ago

Moving 900+ GB of Prometheus Without a Cutover Weekend

The Prometheus I was responsible for had grown past 900 GB of time series data, and at that size it had every disease that comes with it.  Queries timed out unless you narrowed the...

Read source
cloud.google.com /1 month ago

Spanner migrations: Automating dual-write with Antigravity CLI for minimal disruption

When Google's Finance Engineering team needed to modernize their legacy data layer, they chose Spanner, a globally distributed, strongly consistent, multi-model database with high...

Read source
dev.to /1 month ago

Testing Risky Postgres Migrations Safely with Volume Cloning on Unikraft Cloud

Database migrations can pass every check in development and still take production down, and the classic example is adding a NOT NULL column with no default to a table that already...

Read source
dzone.com /2 weeks ago

Apache Phoenix: Global Secondary Indexes With Tunable Consistency

Apache Phoenix provides an open-source SQL interface over Apache HBase, combining the power of NoSQL horizontal scaling and sharding with SQL simplicity for low-latency and high-th...

Read source
databricks.com /1 month ago

Relational vs Non-Relational Database: Choosing the Right Data Store

Choosing between relational and non-relational databases is one of the most consequential...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Database Scalability

feeds.dzone.com

Recent coverage from public sources
Public source

rubyland.news

Recent coverage from public sources
Public source

wealthysinglemommy.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

cloudblog.withgoogle.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source