Latest updates for Data Lakehouse

Fresh curated links around Data Lakehouse are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • Building a Data Lakehouse with DuckDB and DuckLake
  • The lakehouse is a better data warehouse: 2026 benchmarks and proof
  • Accelerating the borderless Lakehouse: Announcing preview of cross-cloud caching

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

towardsdatascience.com /1 month ago

Building a Data Lakehouse with DuckDB and DuckLake

Starting with a local Parquet file, then joining it to data stored in the cloud The post Building a Data Lakehouse with DuckDB and DuckLake appeared first on Towards Data Science.
Read source
databricks.com /2 weeks ago

The lakehouse is a better data warehouse: 2026 benchmarks and proof

The warehouse was the right answer for 20 yearsThe data warehouse earned its place. For two decades...

Read source
cloud.google.com /1 month ago

Accelerating the borderless Lakehouse: Announcing preview of cross-cloud caching

Today, we are excited to announce enhancements to the borderless Lakehouse, our answer to how data engineers, data scientists, and increasingly, AI agents, can query governed data...

Read source
databricks.com /1 month ago

Unifying governance across engines and catalogs in the Open Lakehouse

In our previous posts, we showed how open table formats, open APIs and unified governance...

Read source
databricks.com /1 month ago

Building for the AI Era: Lakebase, Streaming, and Lakehouse Innovations at VLDB 2026

We are headed to VLDB 2026 to share multiple innovations that power the Databricks platform...

Read source
databricks.com /1 month ago

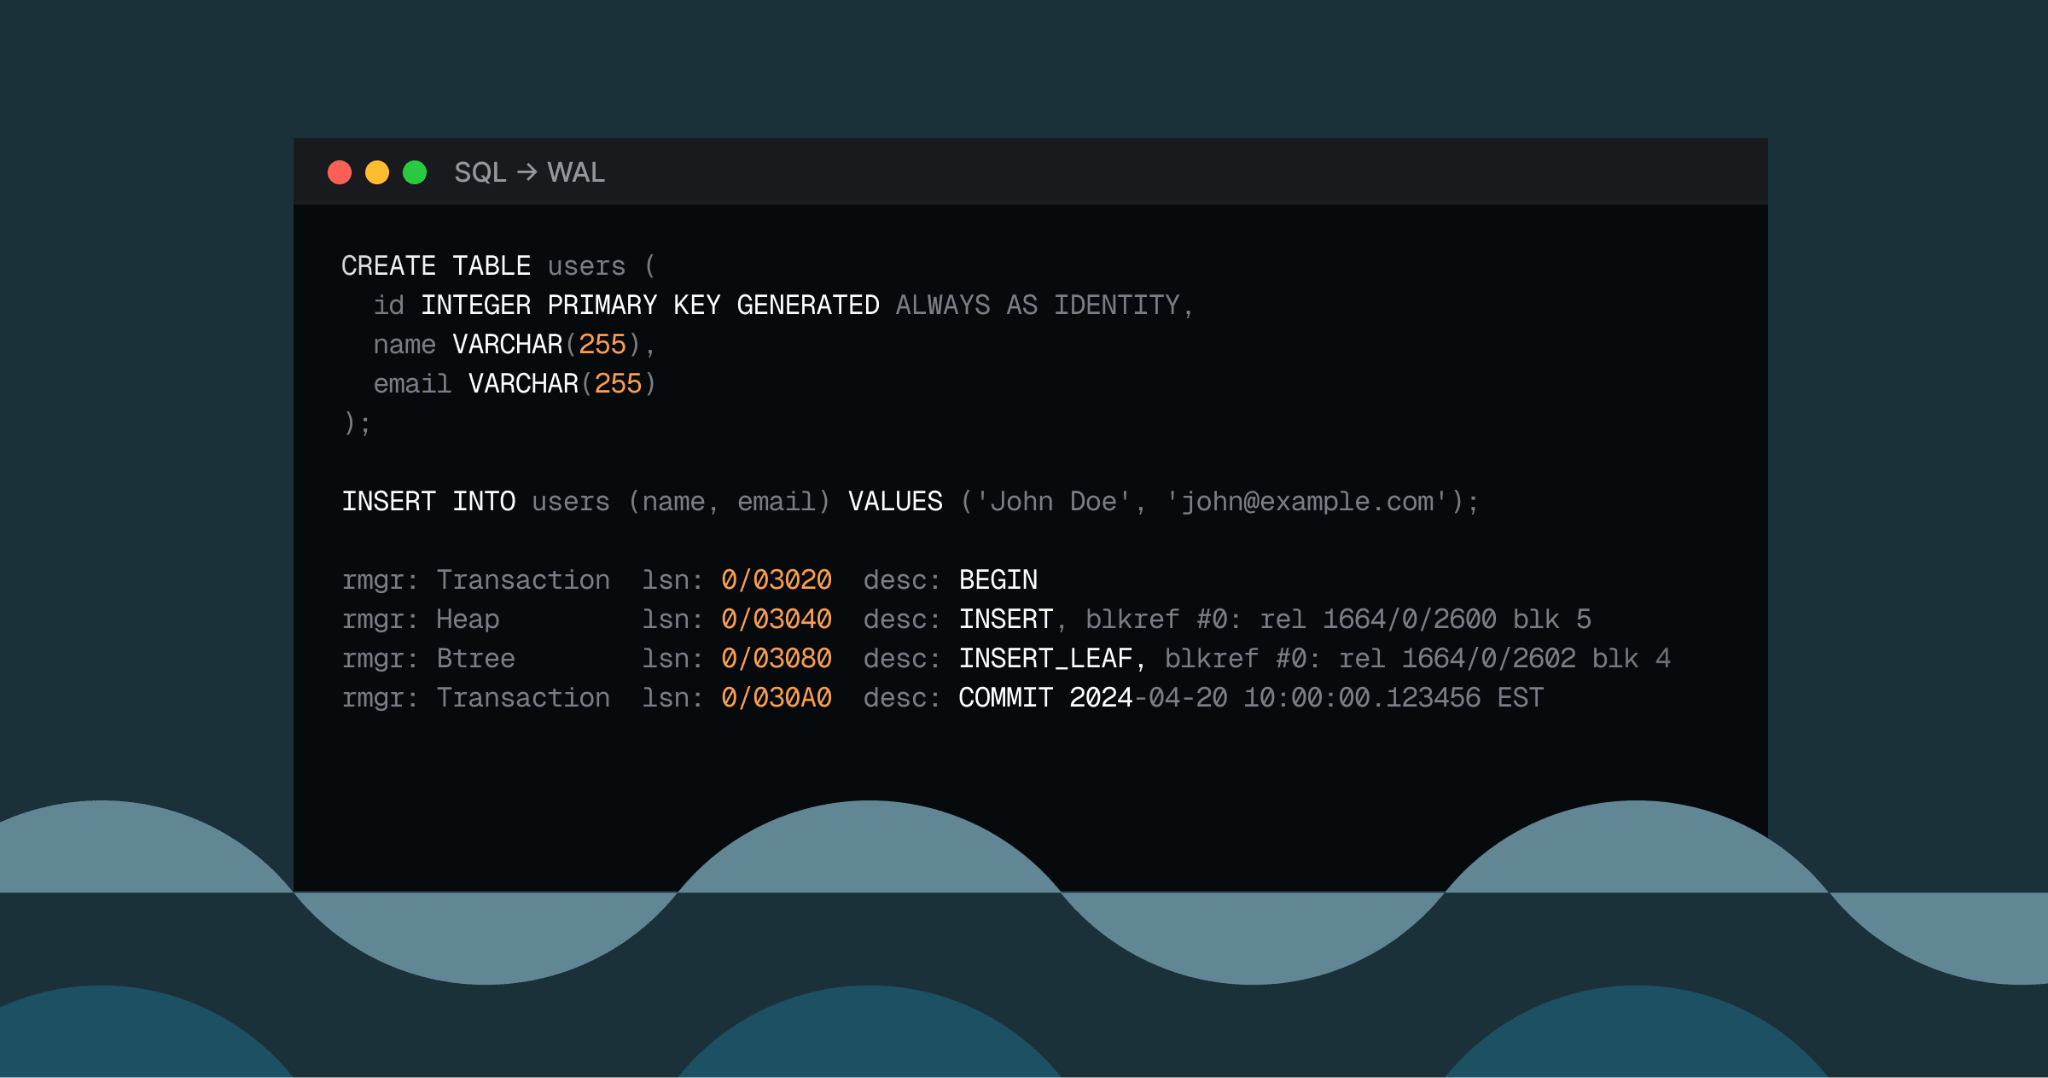
Object Storage + WAL: Lakebase Postgres for the agentic era

Agents that interact with a traditional OLTP database often create bottlenecks at the storage layer. New deployments...

Read source
dzone.com /2 days ago

Delta Lake UniForm to Snowflake: Cross-Platform Table Access Without a Second Copy

Making a Databricks-owned Delta table queryable from Snowflake without copying it is one of those things where every individual piece — Delta Lake UniForm, Unity Catalog, private c...

Read source
databricks.com /1 week ago

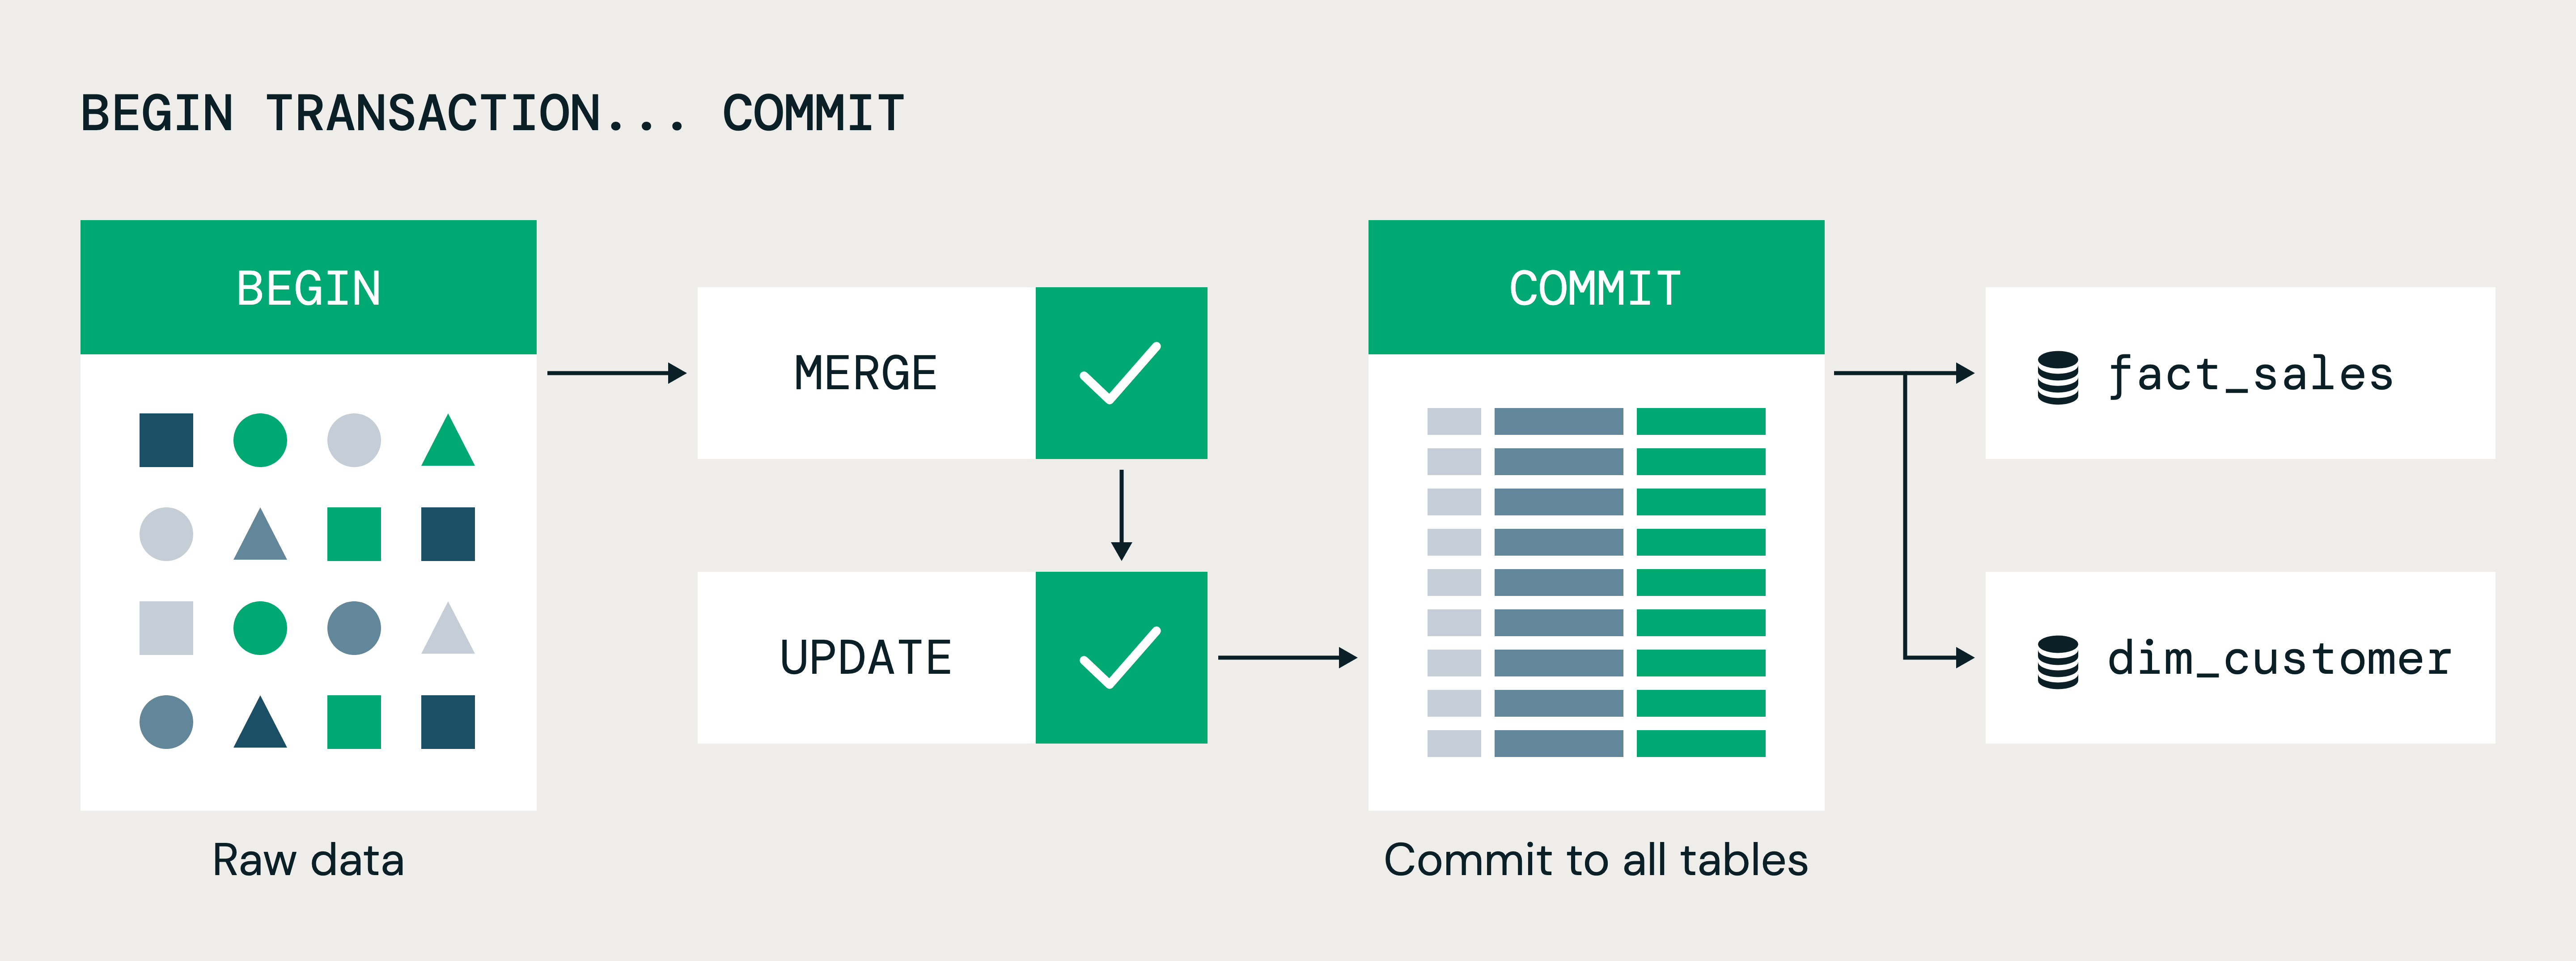
Transactions are Generally Available, advancing warehousing on the Lakehouse

Multi-Statement Transactions are Generally Available, enabling organizations to run...

Read source
cloud.google.com /2 weeks ago

Managed Apache Iceberg at scale: How Spanner powers Lakehouse runtime catalog

As customers modernize to lakehouse architectures, they are standardizing on open formats such as Apache Iceberg to create a shared data estate across compatible engines. This enab...

Read source
databricks.com /1 month ago

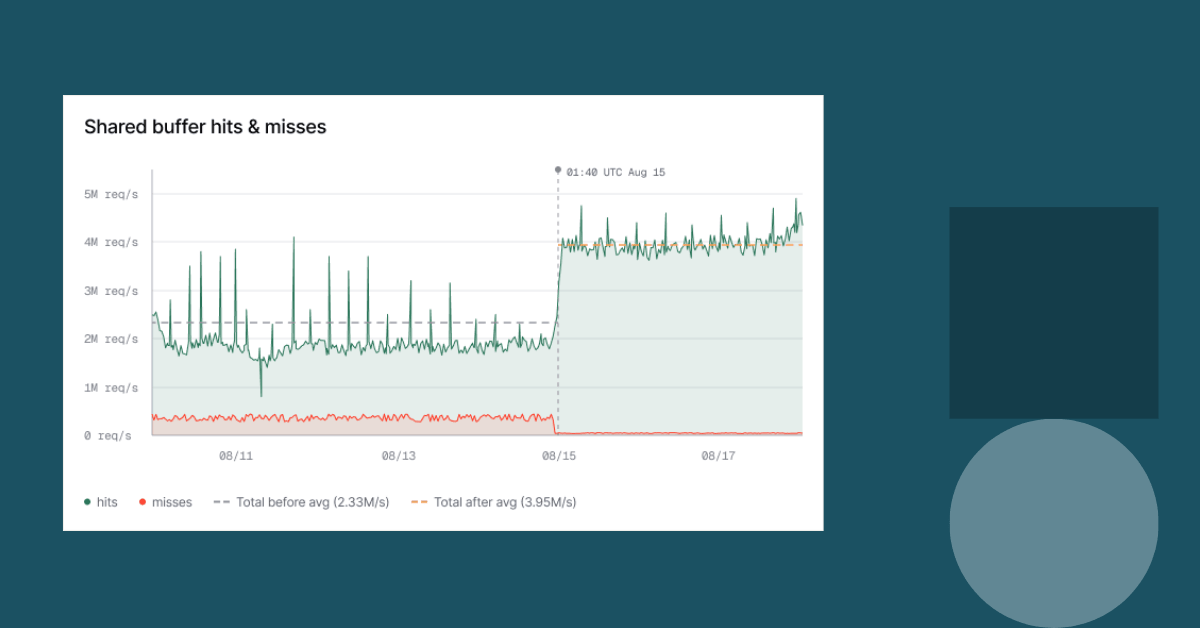
Improving Lakebase Postgres compute cache

The disaggregated storage model of Lakebase Postgres provides a feature rich, flexible...

Read source
databricks.com /2 weeks ago

Load terabytes of data in minutes into Lakebase Postgres

Operational databases like Postgres are built to reliably execute highly concurrent...

Read source
cloud.google.com /1 week ago

Cross-cloud conversational analytics made simple with open standards

The reality for most organizations is that data lives everywhere. As engineering teams expand and adopt specialized platforms for their workloads, enterprise data naturally dispers...

Read source
aws.amazon.com /1 month ago

Razor Group’s journey to a modern data lakehouse on AWS

Razor Group, one of Europe's leading ecommerce aggregators managing 250+ brands, migrated from always-on Amazon Redshift clusters to an open lakehouse on Apache Iceberg, Amazon S3...

Read source
habr.com /3 weeks ago

Lakekeeper и Apache Polaris: сравниваем REST-каталоги для Iceberg

Спор о формате таблиц для lakehouse, похоже, закончился, Iceberg сегодня поддерживают Trino, Spark, ClickHouse, Snowflake и дальше по списку, так что следующим приходится выбирать...

Read source
databricks.com /1 week ago

A practical guide to real-time analytics in 2026

Data has always been central to business decision-making, and most analytical workloads...

Read source
aws.amazon.com /2 weeks ago

Cost-effective ETL with DuckDB and Amazon S3 Tables on AWS Glue

Learn how to pair DuckDB with AWS Glue 6.0 to run SQL-centric ETL on a single worker, reading Parquet from Amazon S3 and writing Apache Iceberg tables to Amazon S3 Tables. This pos...

Read source
aws.amazon.com /1 month ago

Build a dynamic streaming data lake with Apache Iceberg and Apache Flink

Learn how to build a dynamic streaming data lake on Amazon Managed Service for Apache Flink that adapts to new event types and schema changes without stopping the pipeline, using A...

Read source
talkpython.fm /1 month ago

Talk Python to Me: #562: DuckLake: The Lakehouse That's Just SQL and Parquet

How many files does your query read before it reads any data? On some data lakes, you go through JSON and metadata files first, just to learn which Parquet files matter. DuckLake a...

Read source
sourcetrail.com /3 weeks ago

AWS Aurora PostgreSQL adds direct queries for Iceberg and Parquet data lakes

AWS Aurora PostgreSQL now queries Iceberg and Parquet data in S3 without ETL, using DuckDB and familiar SQL. See versions, setup, limits, and costs. The post AWS Aurora PostgreSQL...

Read source
dzone.com /1 week ago

From Legacy ETL to Modern ELT: Engineering a Governed dbt and Databricks Architecture

A few years back, I sat through a production incident review where the root cause turned out to be a single stored procedure nobody on the team had touched in four years. The origi...

Read source
aws.amazon.com /1 month ago

Build with geospatial and variant types in Iceberg v3 on AWS Glue 6.0

AWS Glue 6.0 with Apache Spark 4.1 adds support for Apache Iceberg v3: native geospatial types, nanosecond-precision timestamps, the VARIANT type, and DEFAULT column values. This p...

Read source
aws.amazon.com /2 weeks ago

Materialize once, query anywhere: Introducing Iceberg materialized views in Amazon Redshift

Amazon Redshift now supports Iceberg materialized views. Compute an aggregation once in Amazon Redshift and store the result as a standard Apache Iceberg table in Amazon S3, querya...

Read source
dataengineeringcentral.substack.com /3 weeks ago

From Podcast Video to Searchable Insight with Databricks FILE data type

the Lakehouse expands to multi-modal

Read source
databricks.com /3 weeks ago

IP Functions are Generally Available, bringing high-performance network analytics to the Lakehouse

IP data is warehousing dataEvery firewall, load balancer, VPN, CDN edge, DNS resolver,...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Data Lakehouse

feeds.dzone.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

cloudblog.withgoogle.com

Recent coverage from public sources
Public source

dataengineeringcentral.substack.com

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source

planetpython.org

Recent coverage from public sources
Public source