Latest updates for Content-Based Speech

Fresh curated links around Content-based speech are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • Video and Audio as Knowledge Sources: Content Understanding in Microsoft Foundry IQ
  • AI That Listens and Reads: Multimodal Deep Learning Scores Spoken English With 97.5% Accuracy
  • Build a Speaker-Recognition App with Claude Code

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

dzone.com /1 month ago

Video and Audio as Knowledge Sources: Content Understanding in Microsoft Foundry IQ

Your largest corpus is the one nobody indexed. Here's how to turn recordings into grounding data an agent can cite. The Corpus You Already Have and Never Indexed Every organizati...
Read source
bioengineer.org /1 week ago

AI That Listens and Reads: Multimodal Deep Learning Scores Spoken English With 97.5% Accuracy

A new multimodal deep learning framework fuses Log-Mel spectrograms and BERT embeddings through self-attention to automatically score spoken English fluency with 97.53% accuracy.

Read source
towardsdatascience.com /1 month ago

Build a Speaker-Recognition App with Claude Code

Learn how to effectively code up an internal tool using Claude code or Codex The post Build a Speaker-Recognition App with Claude Code appeared first on Towards Data Science.

Read source
cryptobriefing.com /3 weeks ago

Suno launches Speech tool that adds background music to spoken-word audio

Suno's Speech tool could revolutionize audio content creation, enhancing storytelling and expanding opportunities in the competitive audio market. The post Suno launches Speech too...

Read source
dev.to /4 days ago

Audio-Driven Avatars vs. TTS + Lip-Sync: What Changes When the Audio Drives the Whole Body

Say you need a talking head for a product demo, a docs walkthrough, or a short course module. You don't want to be on camera for every update, and re-recording a whole video becaus...

Read source
medium.com /1 month ago

From 33% to 92%: What I Learned Building an Indian Language Speech Classifier

I trained CNNs, tried ImageNet and AudioSet transfer learning, tested Whisper zero-shot, and eventually fine-tuned Whisper on six Indian…Continue reading on Medium »

Read source
medium.com /3 weeks ago

Voiceprint, enabling authentication and personalization on the edge

Just like a fingerprint, our voice is unique to each of us. With modern machine learning and compute optimization, voiceprint recognition…Continue reading on Medium »

Read source
phys.org /1 month ago

In tune with nature: Human speech follows a rhythm that is also found in the animal kingdom

The temporal structure of speech rhythms resembles that of the communication signals of numerous animal species. This is shown by a study conducted by a research team from the Leib...

Read source
marktechpost.com /1 month ago

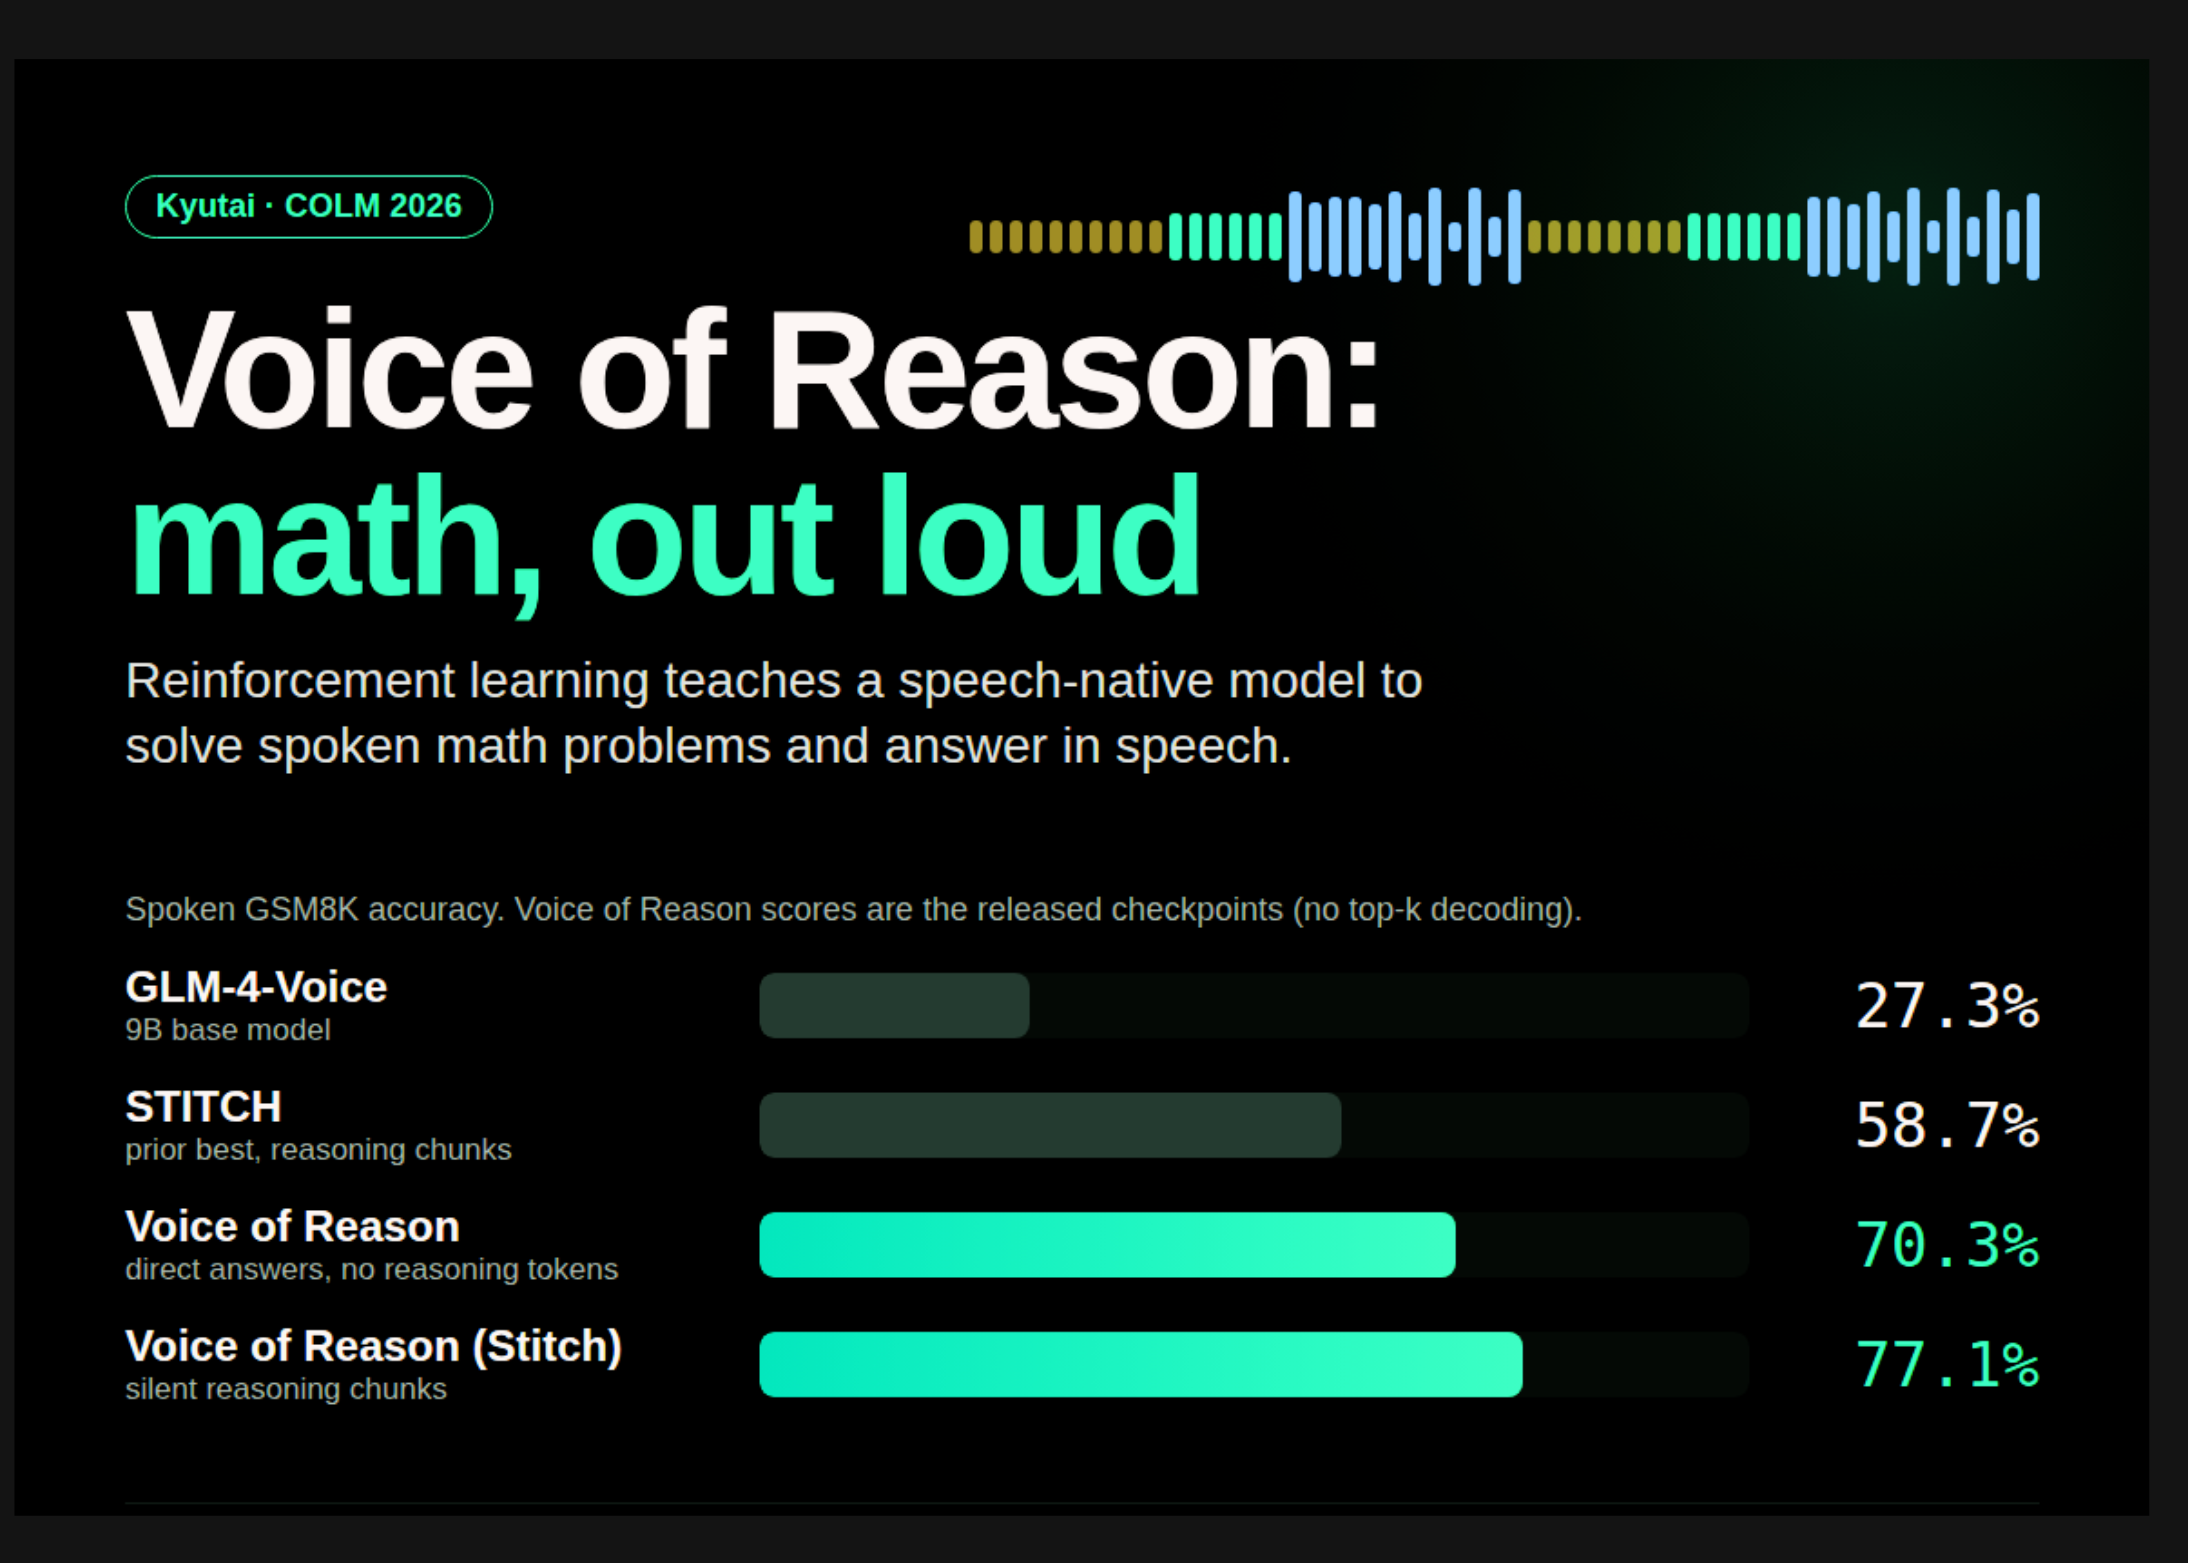
Kyutai Releases Voice of Reason: A Speech-Native Model that Solves Spoken Math with Reinforcement Learning

Kyutai has released Voice of Reason, 2 open-weight speech-to-speech models built on GLM-4-Voice-9B. Supervised fine-tuning and reinforcement learning lift spoken GSM8K accuracy fro...

Read source
blog.google /1 month ago

Build real-time voice applications with Gemini 3.8 Live and 3.5 Transcribe

A look at how developers can build with our latest audio models, Gemini 3.8 Live, 3.8 Live Extended Thinking, and 3.5 Transcribe.

Read source
marktechpost.com /2 days ago

A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech Model Hold Up Against Whisper Base? Word Error Rate, Speed, Stre...

Explore a comprehensive coding guide benchmarking Cactus Compute's 16.9 MB speech model against Whisper base. Learn about word error rates, CPU speed, streaming latency, and speech...

Read source
pandaily.com /1 month ago

DeepSeek App Gray-Tests Native AI Voice Chat With Four TTS Voices

DeepSeek is gray-testing in-app AI voice chat: a speaker control in the top-right corner and four selectable TTS voices — Beike, Bailang, Haixing and Anchao — as a product feature...

Read source
patentlyo.com /3 weeks ago

This Is Not a Feature Vector: Zentian v. Apple

Federal Circuit affirms cancellation of Zentian's speech-recognition patent, rejecting a Magritte analogy that codewords aren't feature vectors. Continue reading this post on Paten...

Read source
writeoutloud.net /3 weeks ago

Voice

there is a voice...

Read source
marktechpost.com /1 month ago

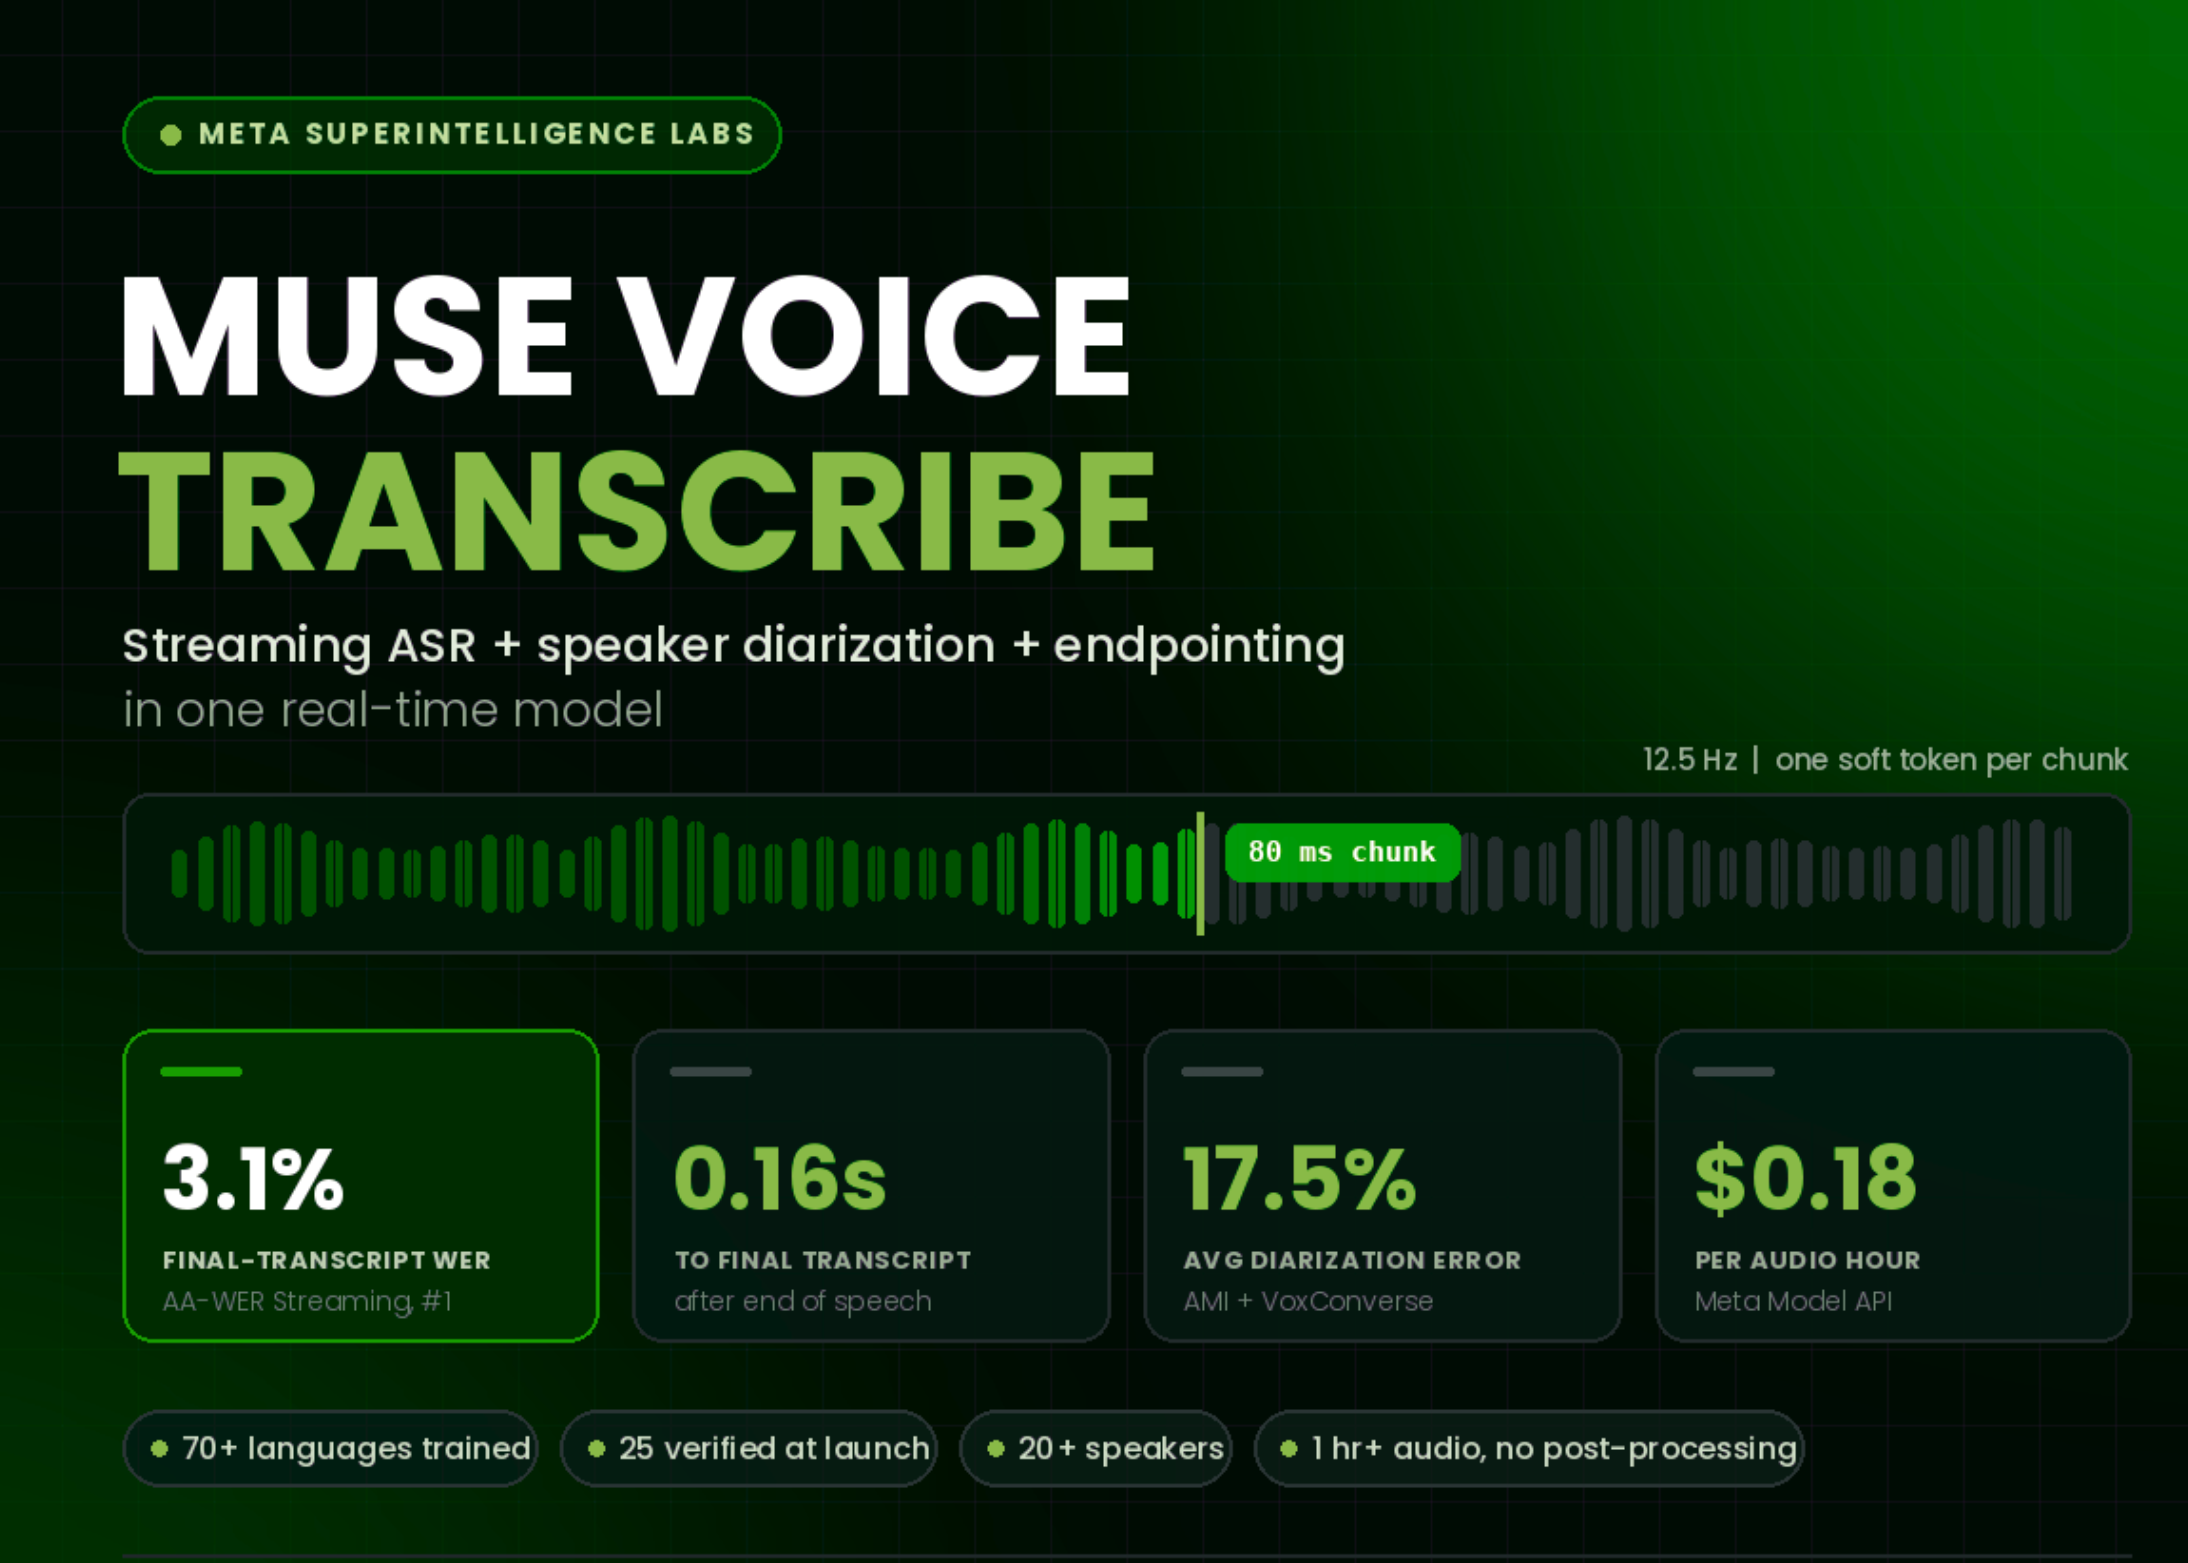
Meta Superintelligence Labs Releases Muse Voice Transcribe: One Real-Time Model for Streaming ASR, Diarization, and Endp...

Most production voice stacks are three systems stitched together. One model transcribes, a second separates speakers, and a detector decides when the user stopped talking. Each han...

Read source
aws.amazon.com /2 days ago

Stream low-latency speech from AI agents using Kokoro TTS on Amazon SageMaker AI

Voice agents often wait for an agent's full response before starting speech synthesis, adding latency users feel directly. This post shows how to stream each sentence to a Kokoro-8...

Read source
techmeme.com /1 month ago

Meta launches Muse Voice Transcribe, MSL's first real-time audio perception model, with streaming automatic speech recog...

Meta AI Research: Meta launches Muse Voice Transcribe, MSL's first real-time audio perception model, with streaming automatic speech recognition, trained with 70+ languages  —  Exp...

Read source
medium.com /1 month ago

Beyond Python: One Open-Source C++ Audio Engine for TTS, ASR, Voice Cloning & 10+ Tasks

One engine, cross-platform, 10+ tasks: audio.cpp unifies TTS, ASR, voice cloning, music generation, diarization, source separation, and…Continue reading on Medium В»

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Content-Based Speech

feeds.dzone.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

bioengineer.org

Recent coverage from public sources
Public source

cryptobriefing.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

medium.com

Recent coverage from public sources
Public source