What Is Comparison Testing in Software Testing?
Comparison testing measures your product against a competitor, a benchmark, or a visual baseline. Learn what it means, how to run one, and what to automate.
Search fresh public links, source activity, and ready-to-use post angles for Benchmarking.
Fresh curated links around Benchmarking are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Comparison testing measures your product against a competitor, a benchmark, or a visual baseline. Learn what it means, how to run one, and what to automate.
LLM benchmarks score general model capability, evals score your application. See what each can gate, where benchmarks break, and how to build an eval suite.
With the recent release of Java/OpenJDK 27 I began some fresh benchmarks in not having looked at the OpenJDK Java performance in a few years. Carried away, I ended up re-testing al...
Public benchmarks are essential in machine learning. They let us compare models, reproduce experiments, and quickly evaluate new…Continue reading on Medium »
Immediately following the OpenJDK 8 through OpenJDK 27 benchmarks I expanded the scope of testing to look at how recent OpenJDK releases have been comparing to alternative JVMs lik...
Originally appeared on The Rails Tech Debt Blog.Last month the Rails Foundation published something the Ruby on Rails community had not seen before: a leaderboard of coding agents...
I have a confession, and I suspect I'm not alone in it: I've built RAG infrastructure multiple times, and until last week I had never benchmarked any of it. Unit tests, sure. Inte...
What gets measured gets improved. Here are five key people metrics.
One RTX 5090, 128 GB of RAM, and four open models from 125B to 748B parameters. Over the past weeks I got each of them running on the same workstation, on three different runtimes....
With the Btrfs pull request for Linux 7.3 having delivered more performance optimizations with some ~3x and ~5x gains mentioned in specific areas, I was eager to test out the new B...
Fast startup is a small but important part of a pleasant Neovim experience. This benchmark examines how SnaxVim compares with several popular Neovim distros1 using multiple measure...
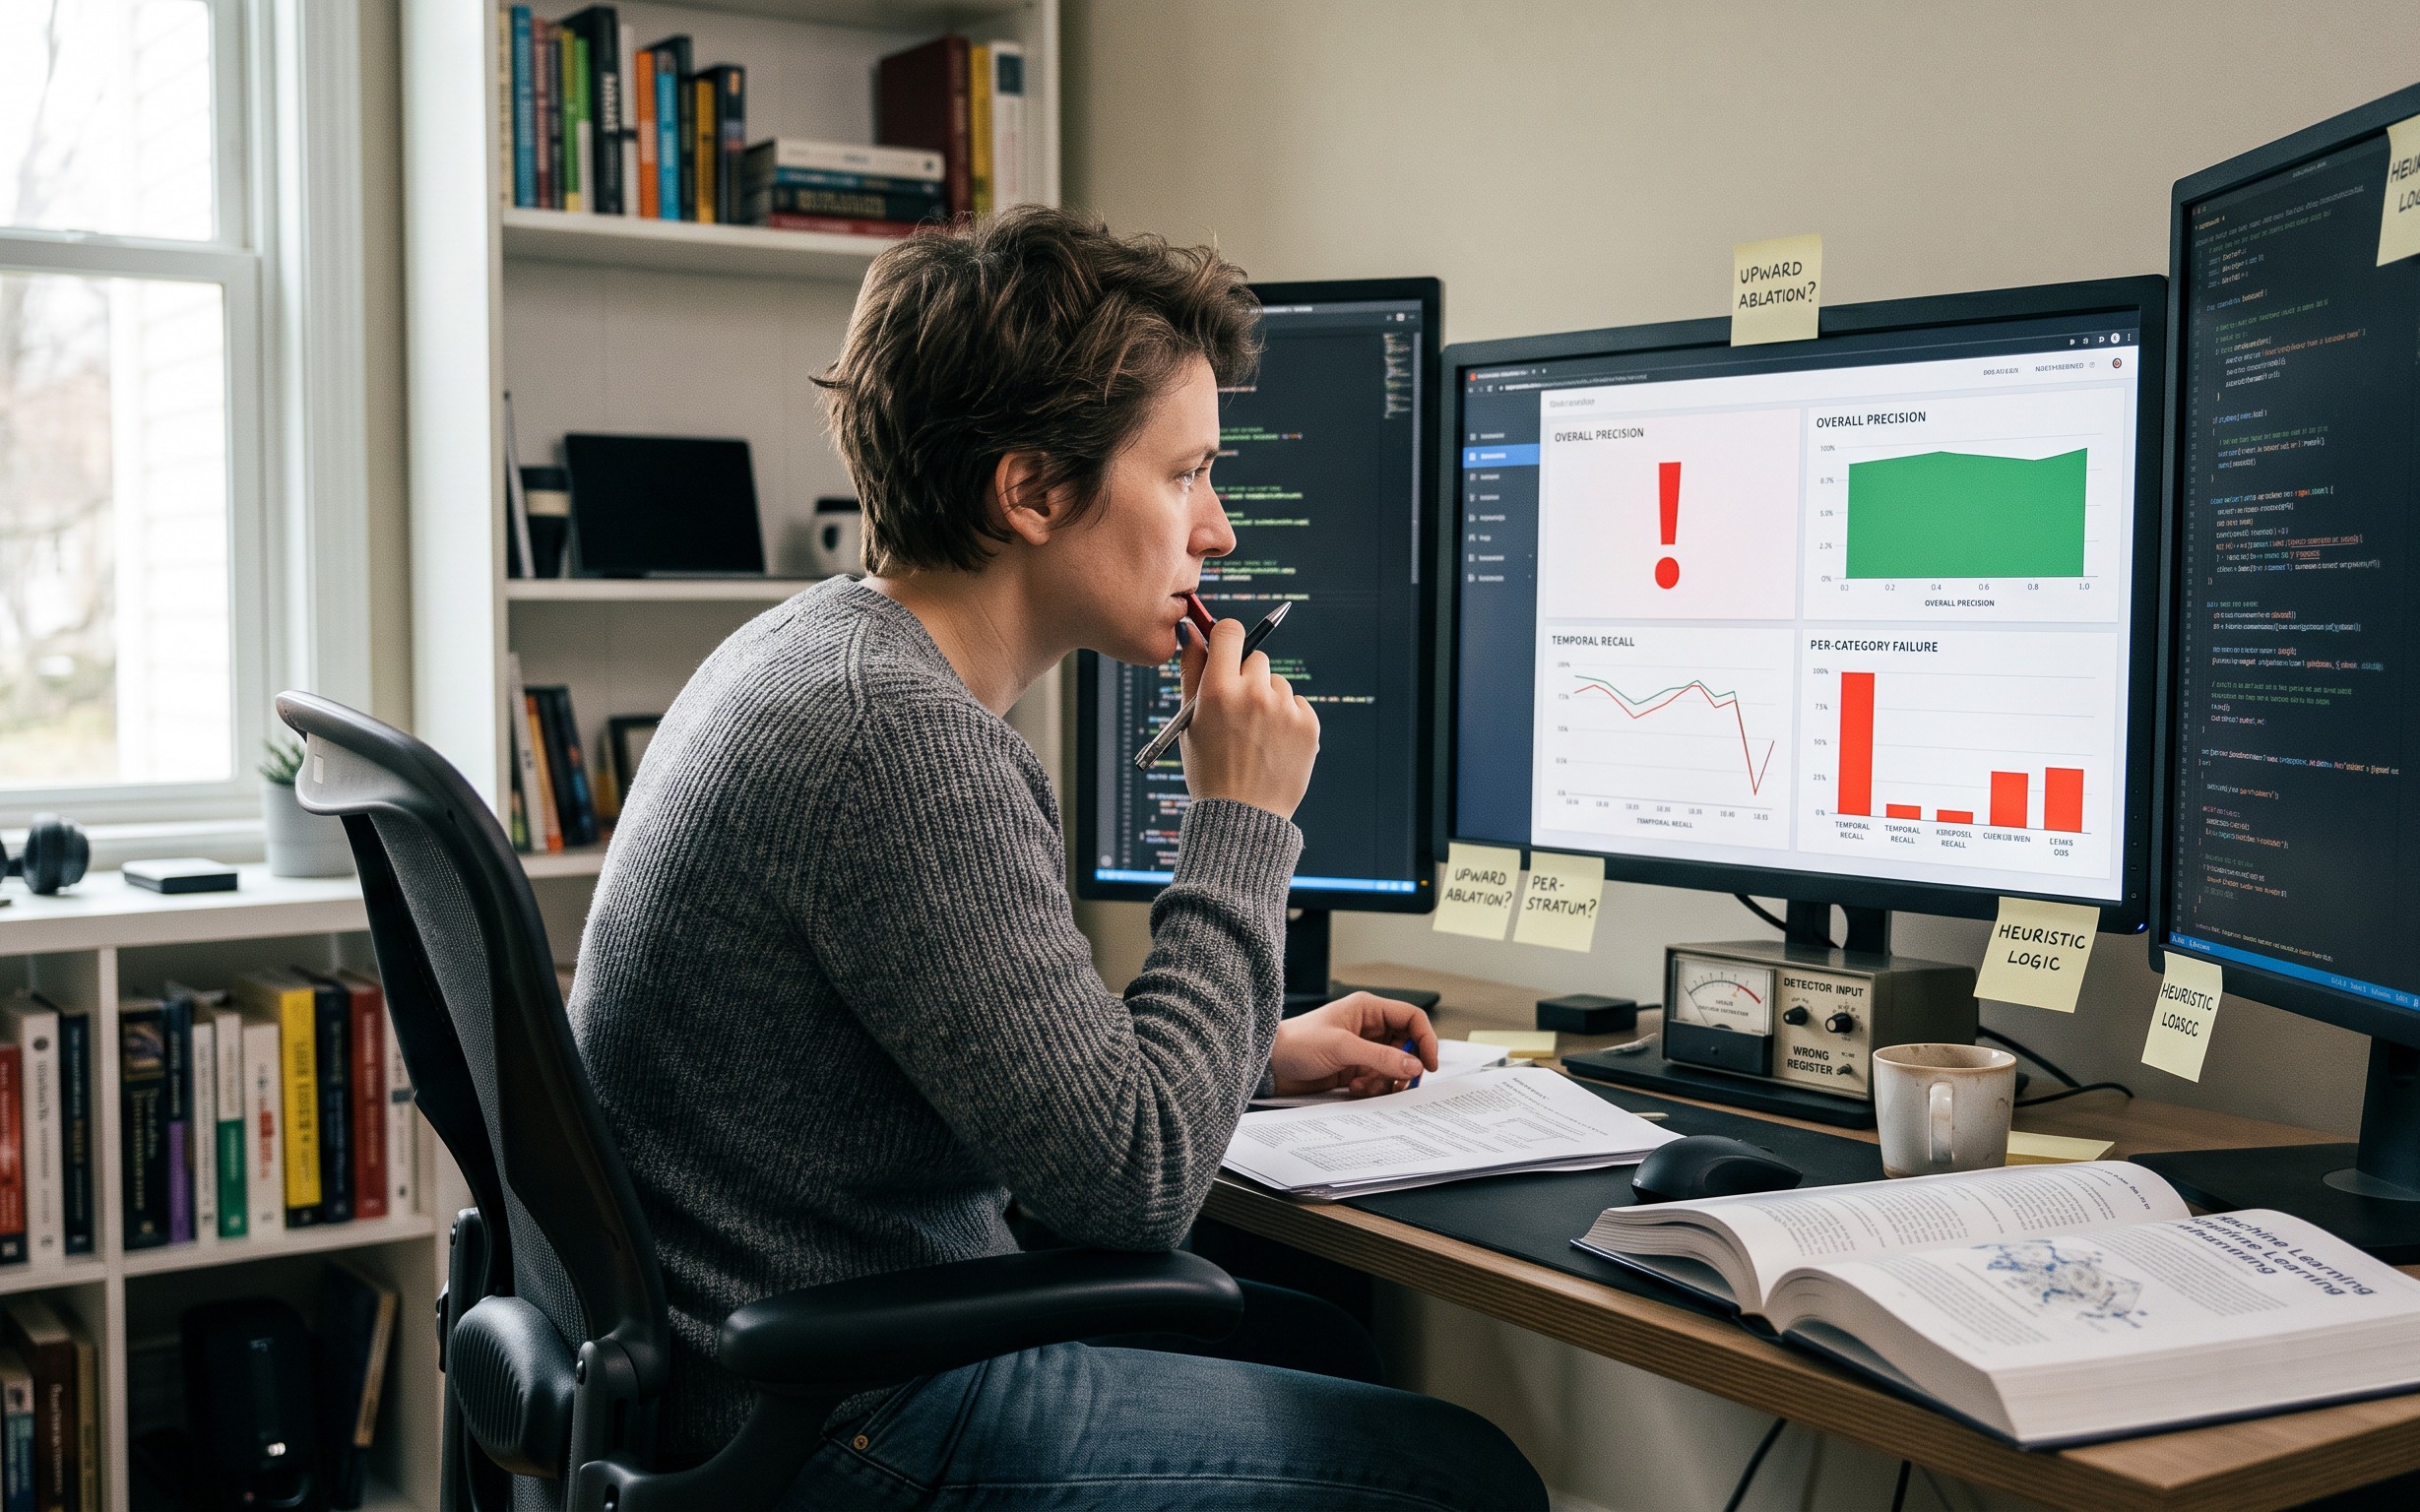
A detector I built was scoring 0.067 recall on temporal errors, meaning it caught about one in fifteen of the wrong dates it was supposed to find. Wrong dates are supposed to be th...
Evaluates AI agents based on their ability to learn complex operational tasks as demonstrated by knowledge workers
Moving Large Language Models (LLMs) from experimental prototypes into enterprise production exposes a critical truth: your infrastructure dictates both your performance ceilings an...
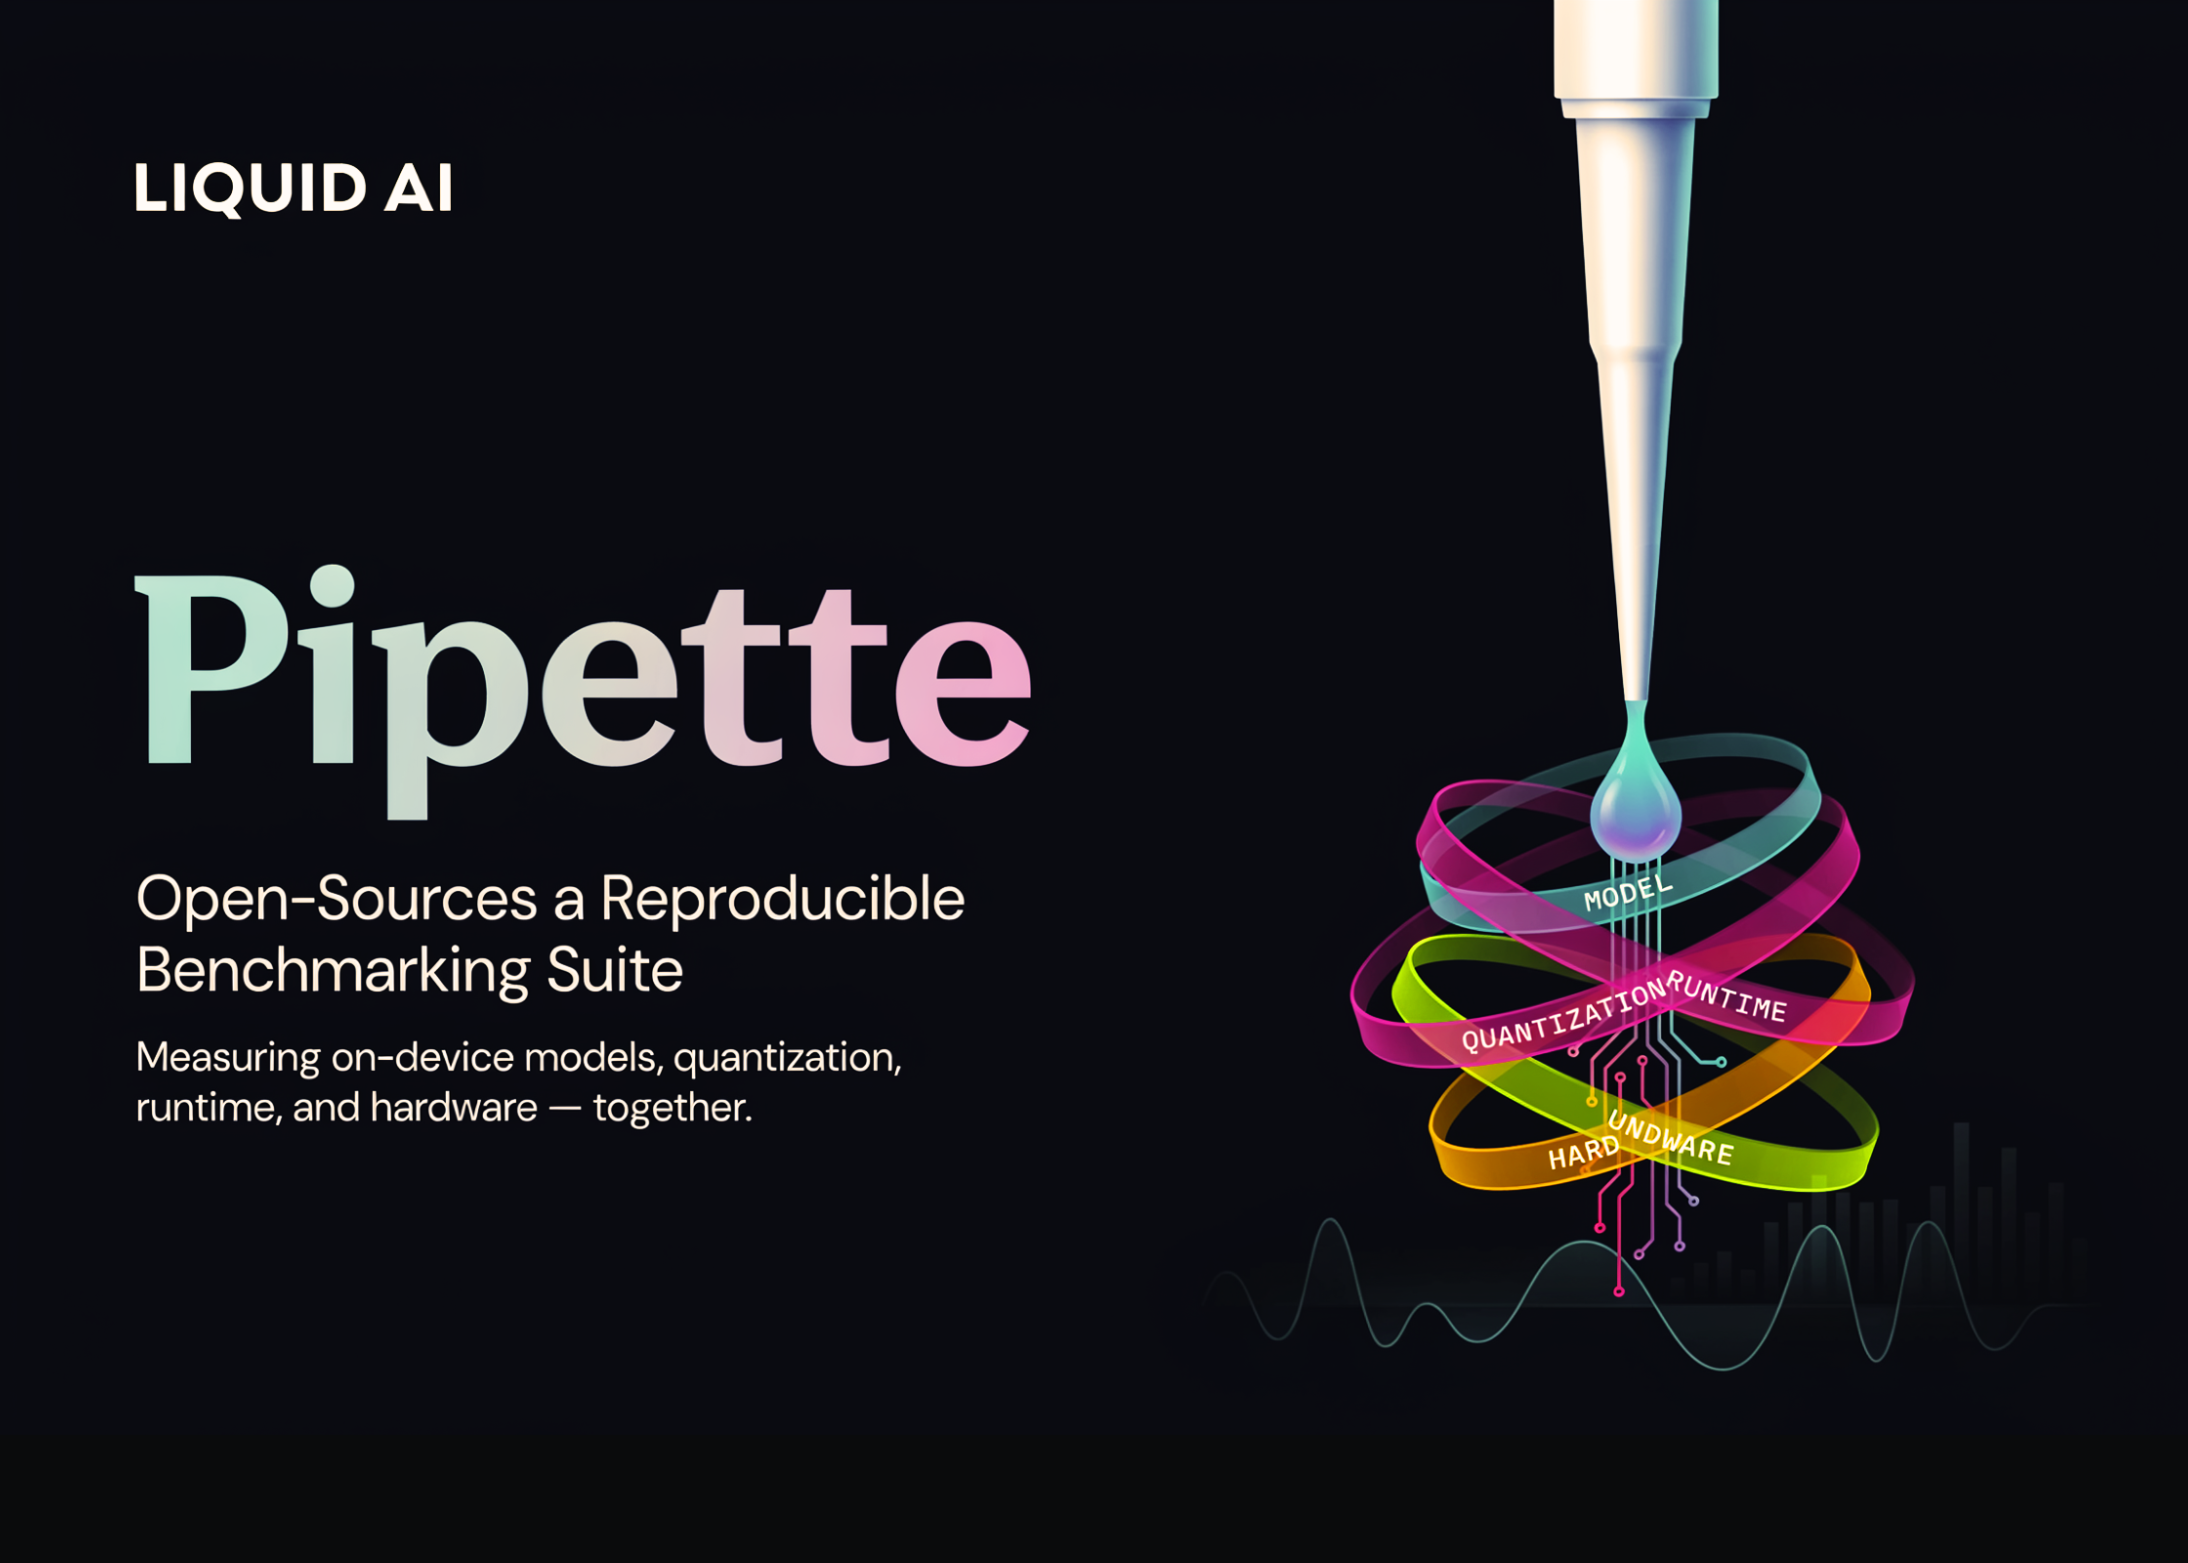
Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI released Pipette....
Benchmark two 30B Mixture-of-Experts models, Qwen3-Coder-30B and NVIDIA Nemotron-3-Nano-30B, across G5, G6, G6e, and G7 GPU instances on Amazon SageMaker AI. Compare throughput, la...
L&D teams quote industry completion rates and engagement averages they cannot verify, while sitting on far better data of their own. Running a small internal study is less work...
Exa 3.0 is a search API upgrade from Exa. It adds a larger embedding model, Exa Lite at $4 per 1,000 requests, and Dynamic Highlights, and leads 8 benchmarks Exa ran itself. The po...
Before you panic over that benchmark score, there’s something you should probably know!
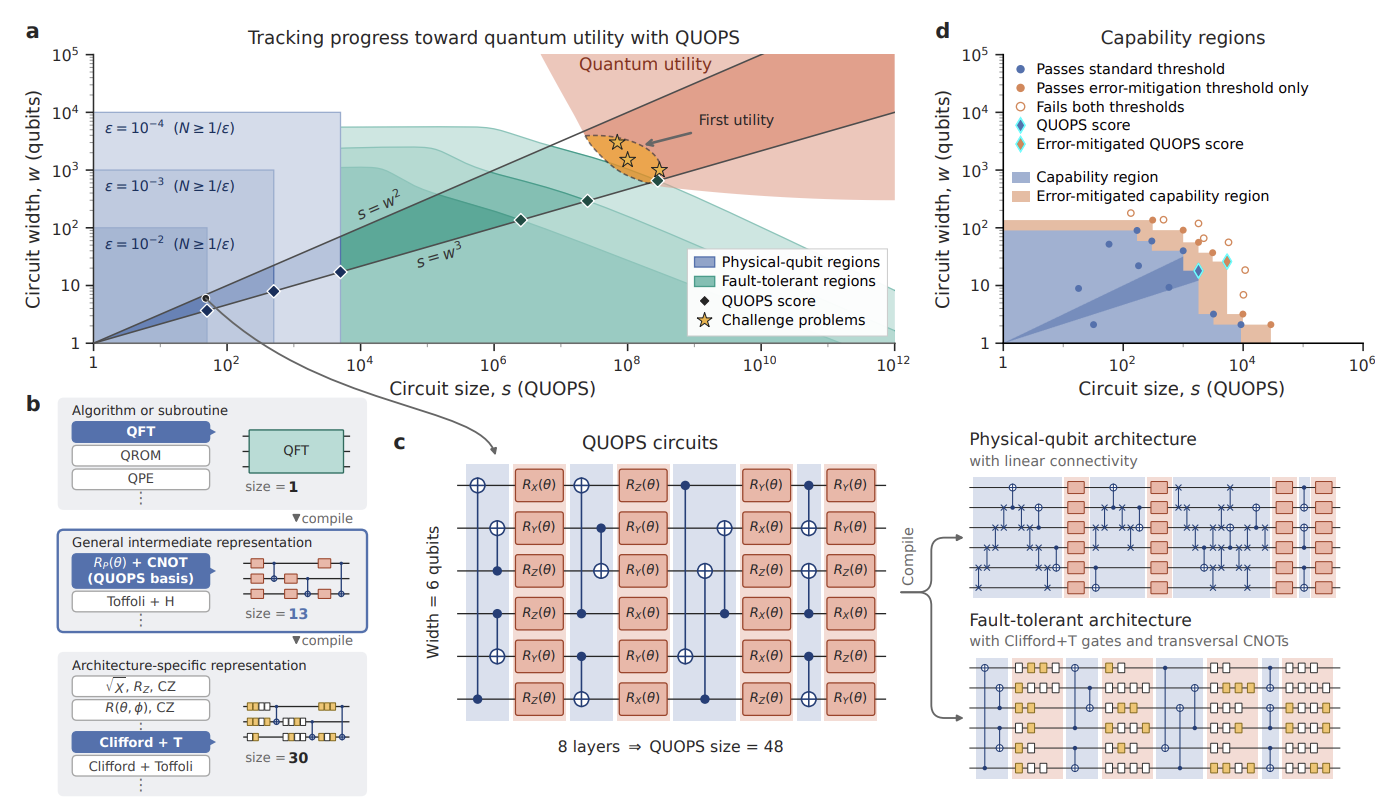
Insider Brief A new benchmark could give researchers and buyers a more practical way to compare quantum computers by measuring how much computation they can complete successfully a...
Amplified Group, the team development specialist, today announces the launch of the GTM Team Index, a new benchmark designed specifically... The post New GTM Team Index Helps Tech...
Salary benchmarking is only as good as the choices behind it. Here are the six setup decisions that shape every pay decision, and how benchmarks connect to your salary structure.
В мае я подал OenoBench, винный бенчмарк для языковых моделей, на NeurIPS. В дискуссии с ревьюерами всплыл вопрос, на который ни у меня, ни у них не было опоры: какой результат на...
With the recently reviewed Star Labs StarFighter Ultra Linux laptop its BIOS allows for configurable memory speeds unlike many other laptop vendor BIOS implementations these days....
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.