Meta、初のリアルタイム音声認識モデル「Muse Voice Transcribe」 20人超の話者識別と多言語混在に対応
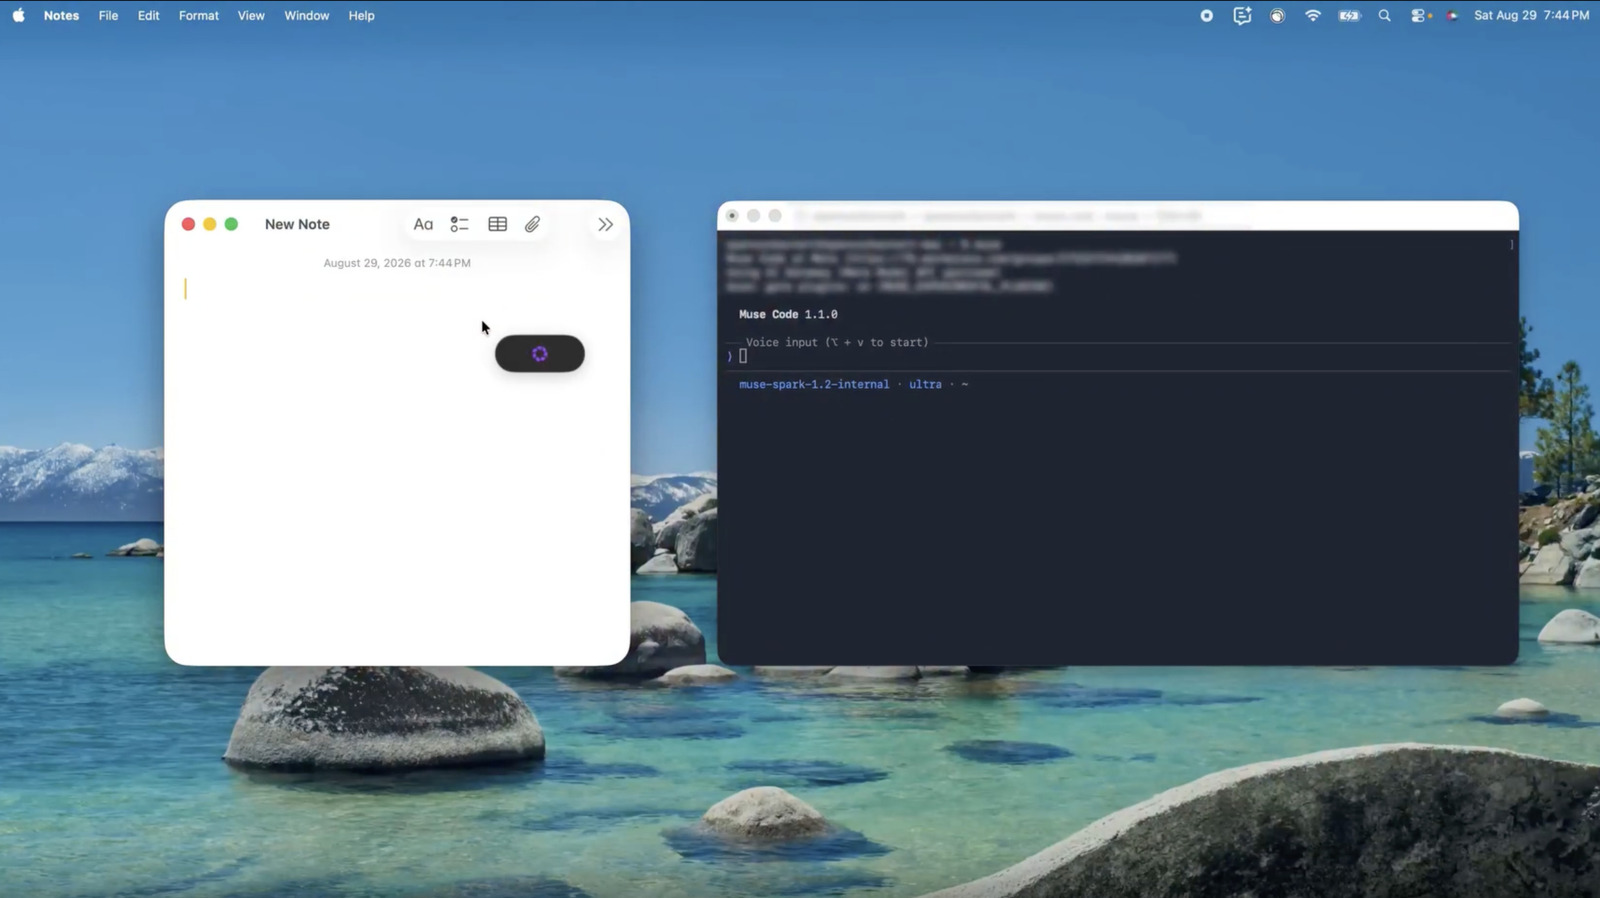
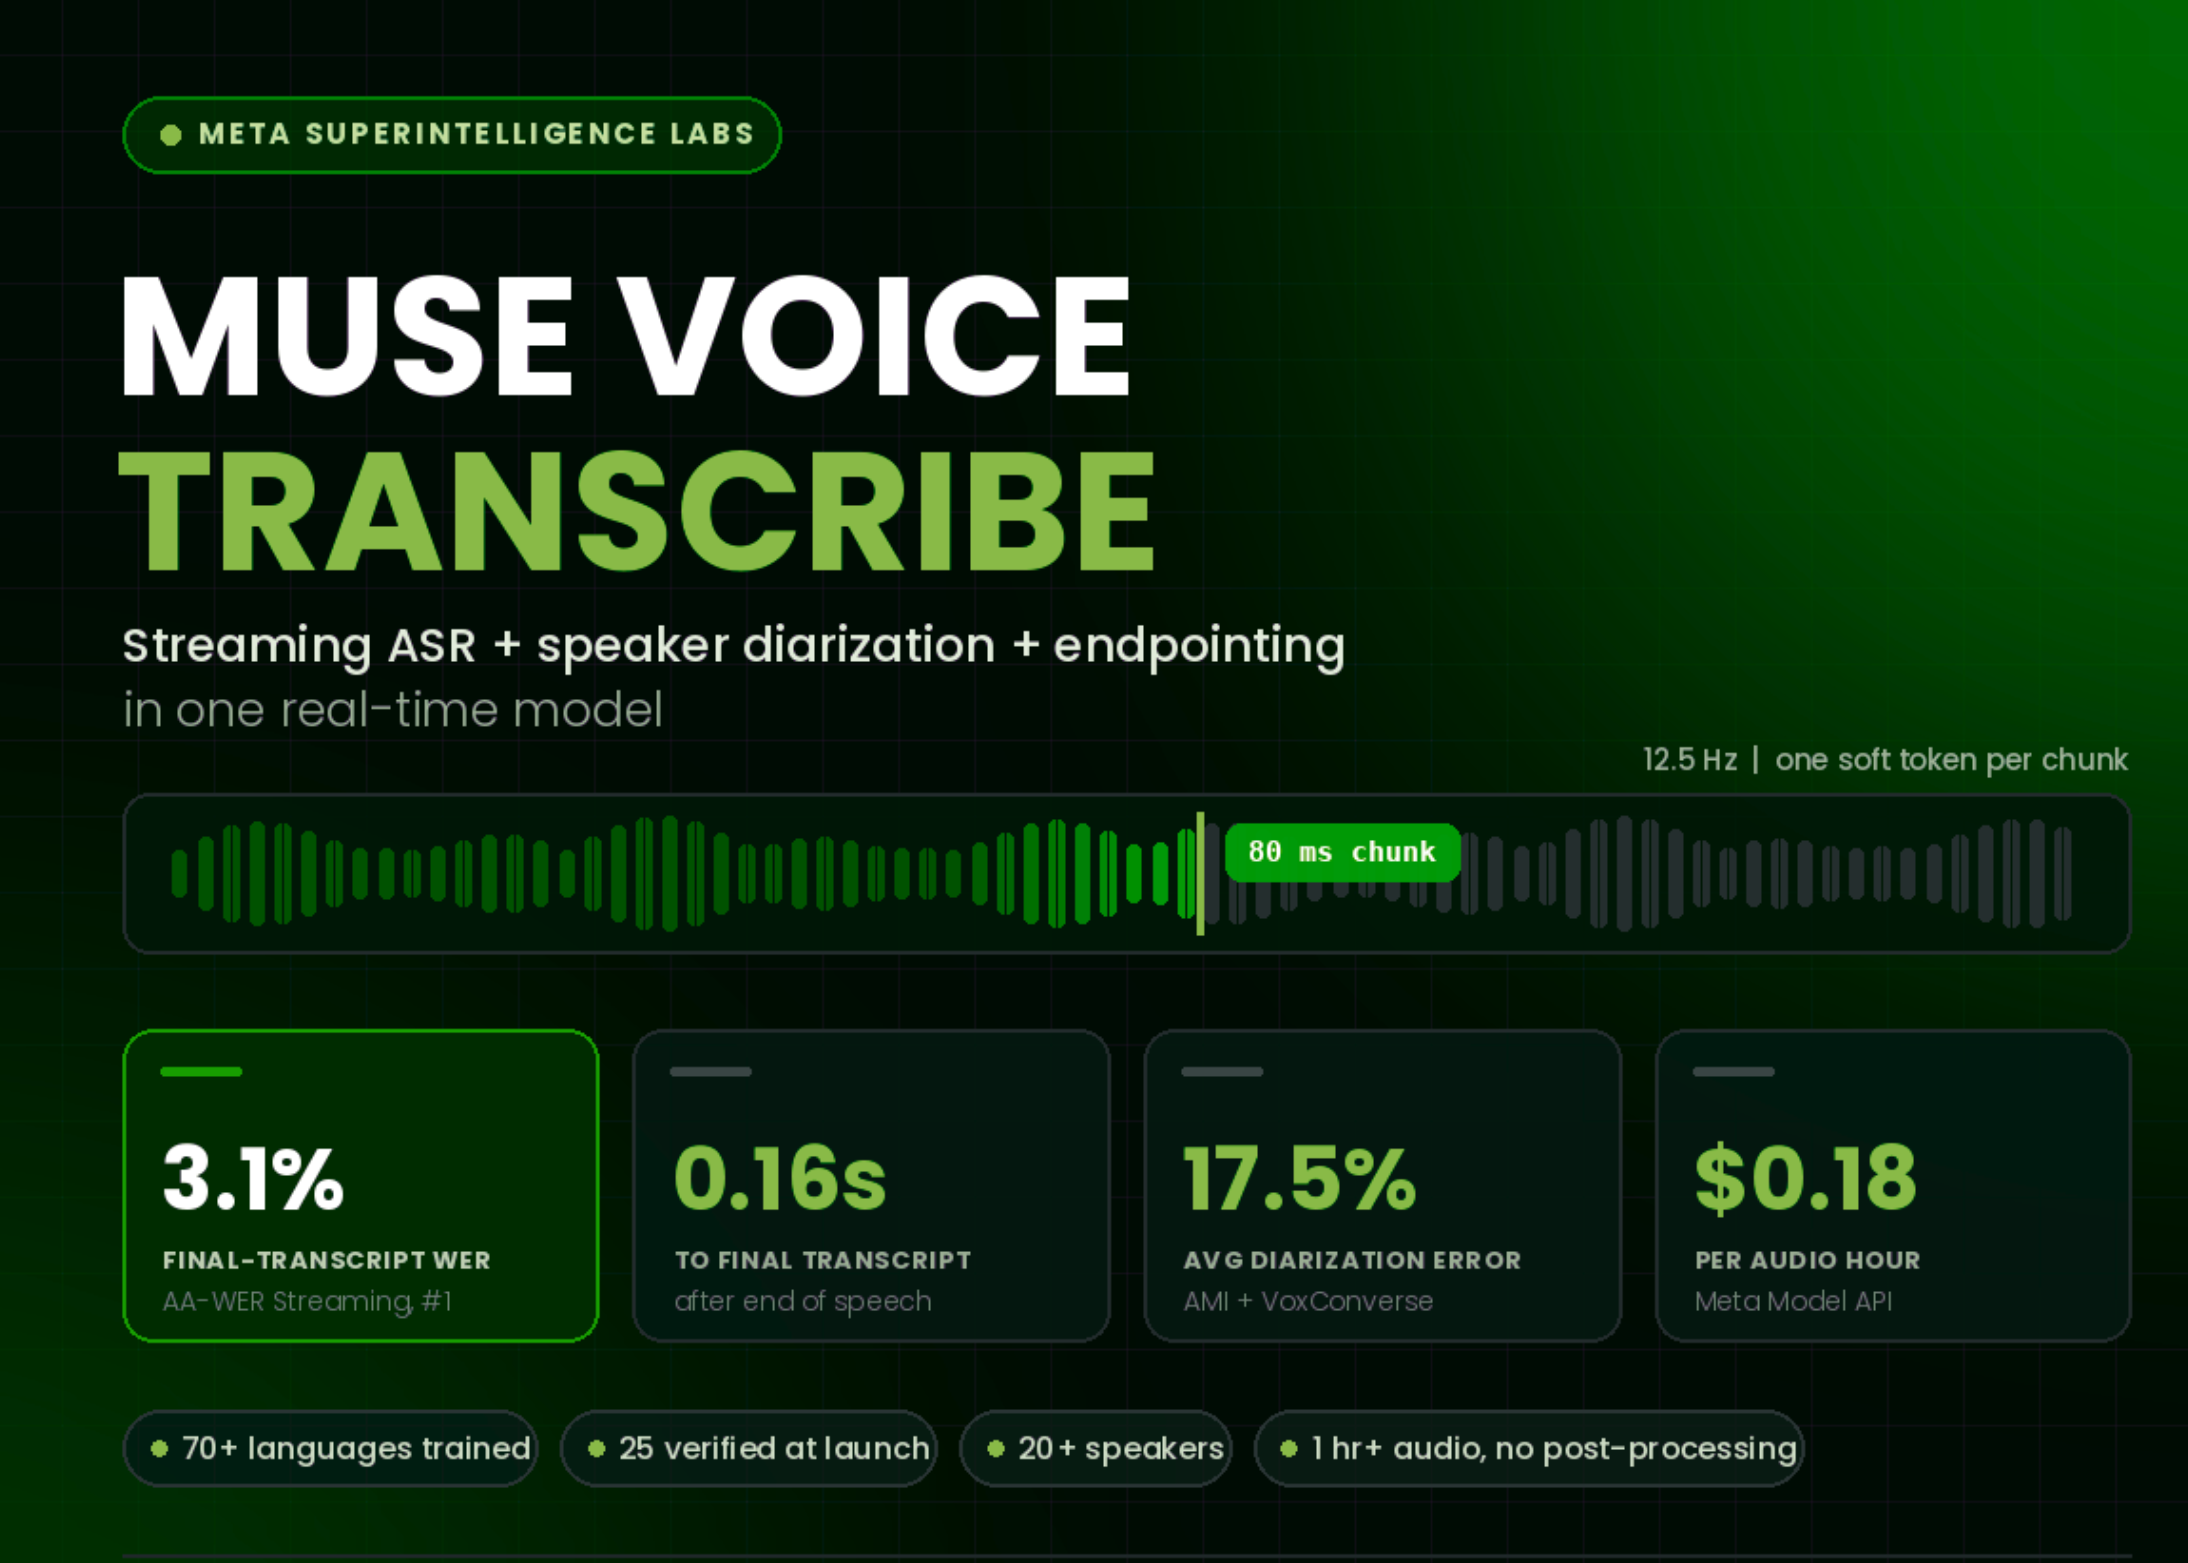
Metaは、リアルタイム音声認識モデル「Muse Voice Transcribe」を発表した。単一モデルで音声認識、話者分離、発話終了検知を処理し、20人以上の話者識別や日本語を含む多言語に対応する。「Met...
Search fresh public links, source activity, and ready-to-use post angles for Audio Language Model.
Fresh curated links around Audio Language Model are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Metaは、リアルタイム音声認識モデル「Muse Voice Transcribe」を発表した。単一モデルで音声認識、話者分離、発話終了検知を処理し、20人以上の話者識別や日本語を含む多言語に対応する。「Met...
Large Language Models (LLMs) have transformed the way applications process and generate natural language. They are widely used in chatbots, search systems, coding assistants, docum...
A new multimodal deep learning framework fuses Log-Mel spectrograms and BERT embeddings through self-attention to automatically score spoken English fluency with 97.53% accuracy.
Large Language Models can take several seconds, or sometimes much longer, to produce a complete response. In a traditional blocking application, the caller waits until the entire r...
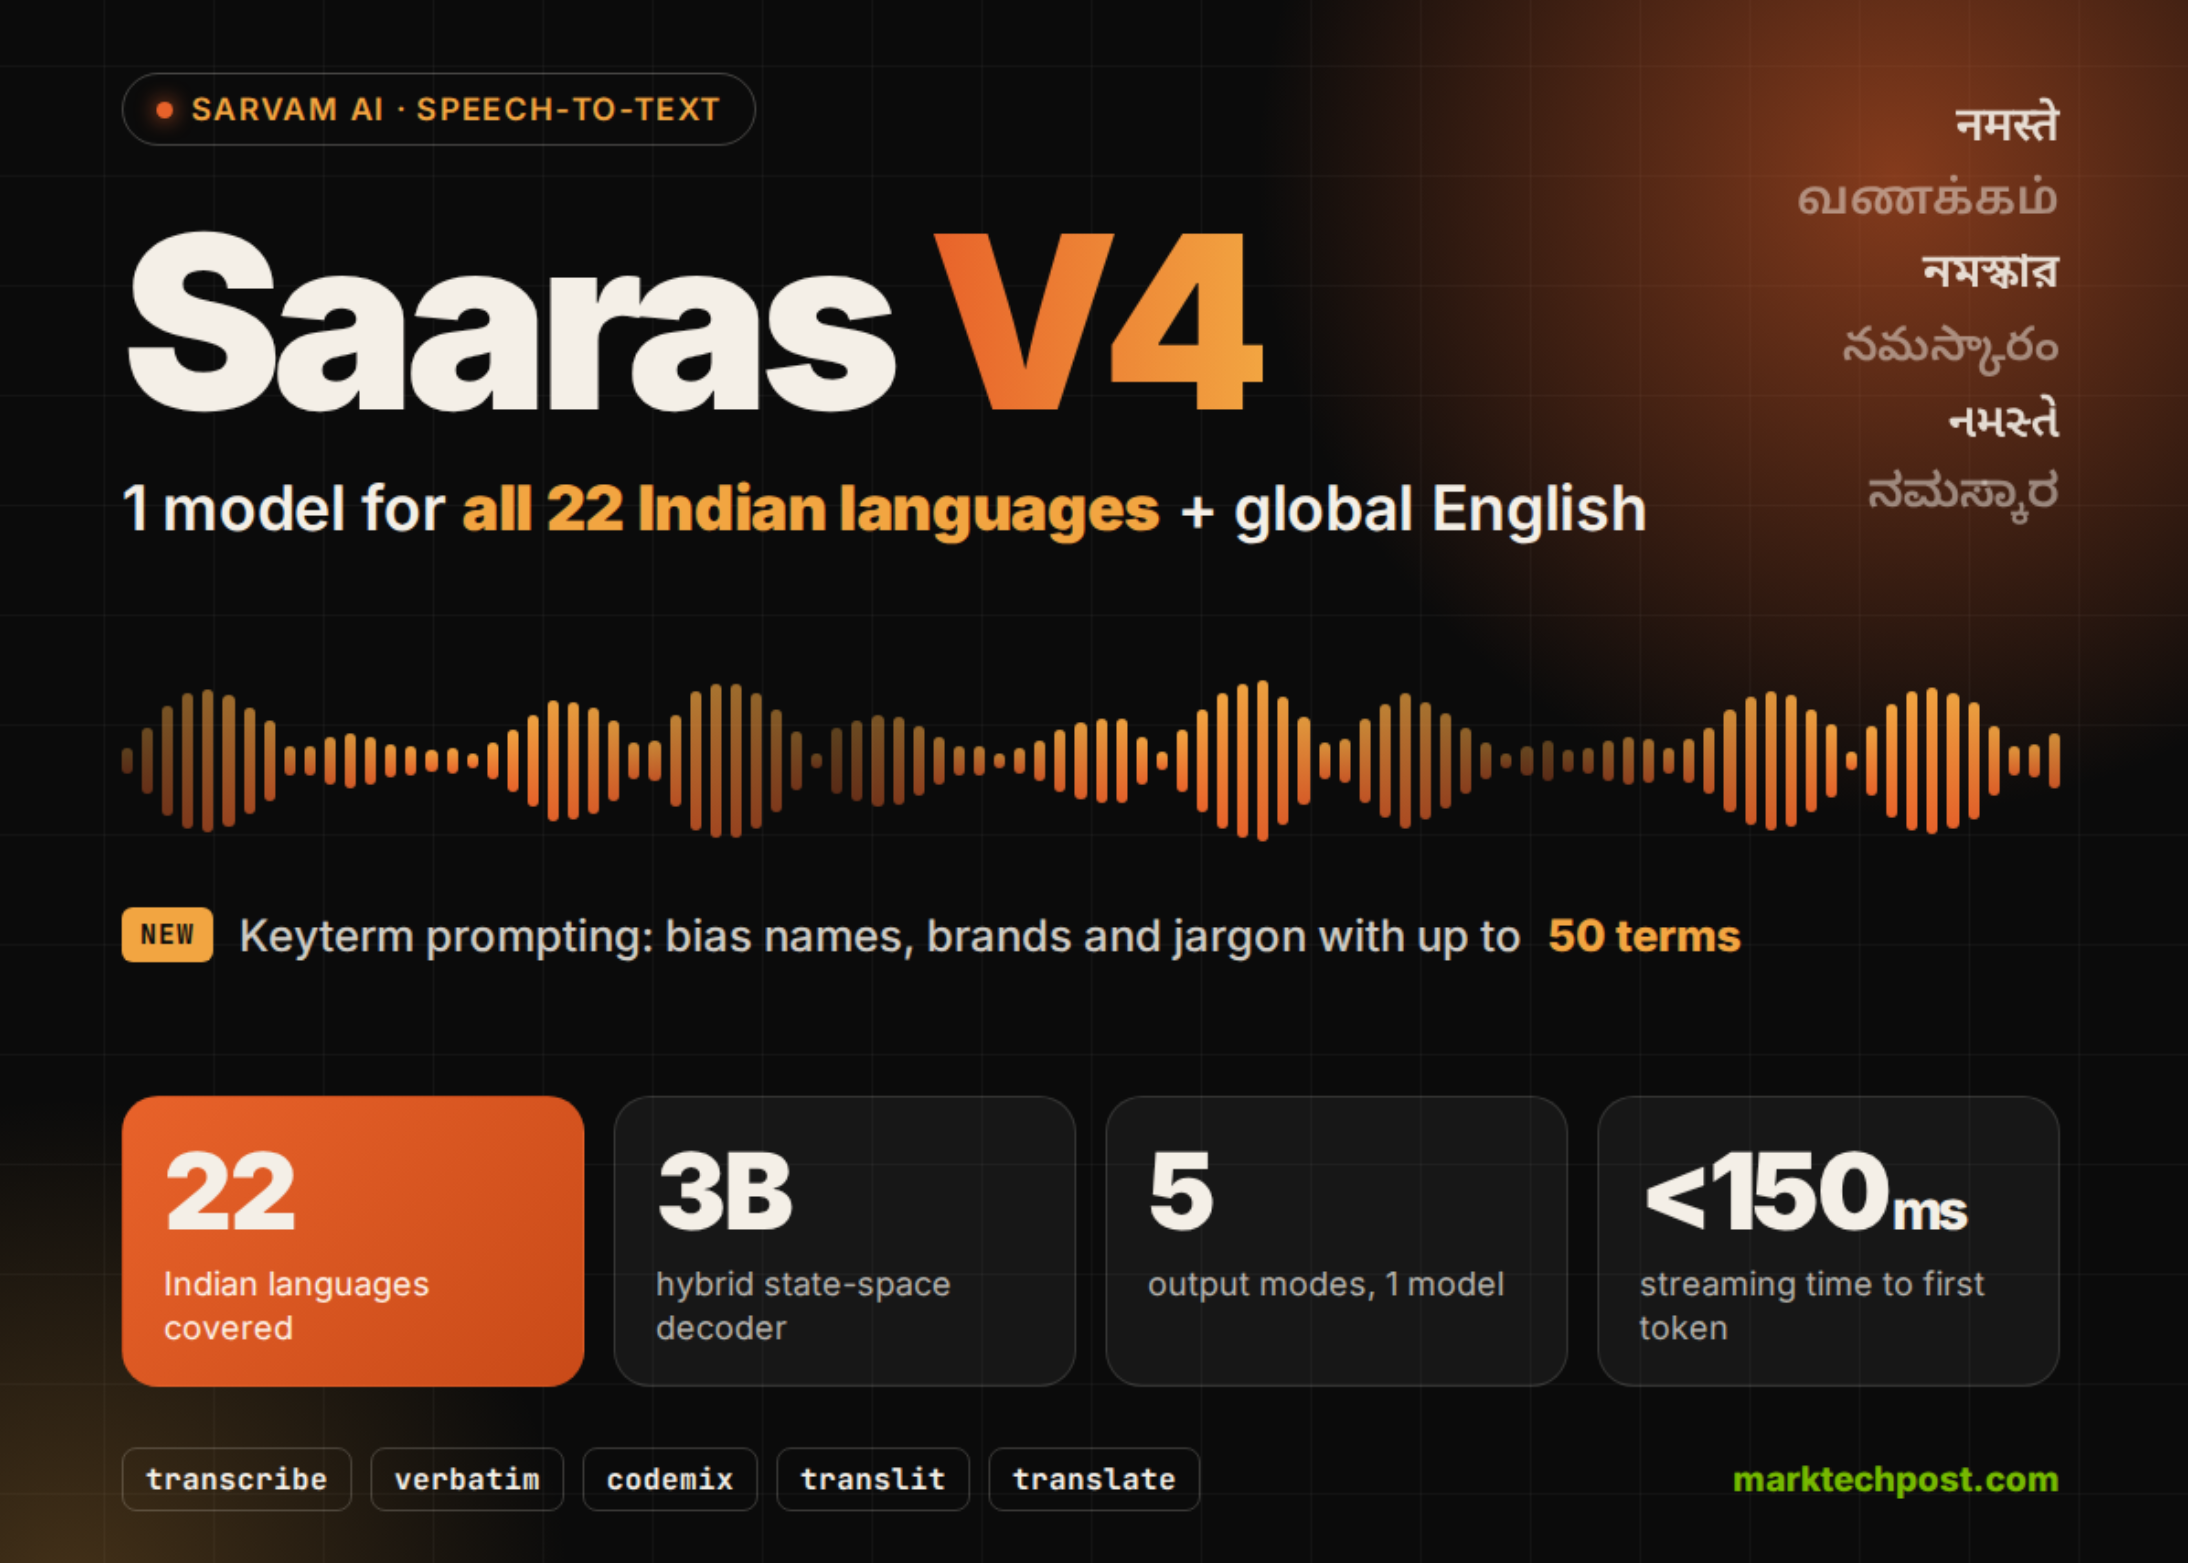
Sarvam AI's Saaras V4 is a speech-to-text model covering all 22 Indian languages plus global English. It pairs an audio encoder with a 3B hybrid state-space decoder. It adds keyter...
Gradium has open-sourced Phonon, a family of on-device text-to-speech models. The English Phonon 31m ships under Apache 2.0, fits in 64.5 MB, and starts speaking in about 7 ms on a...
Fish Audio released Drama 3, a 35B mixture-of-experts text-to-speech model with about 3B active parameters. It takes plain-language direction, covers 83 languages and ships open we...
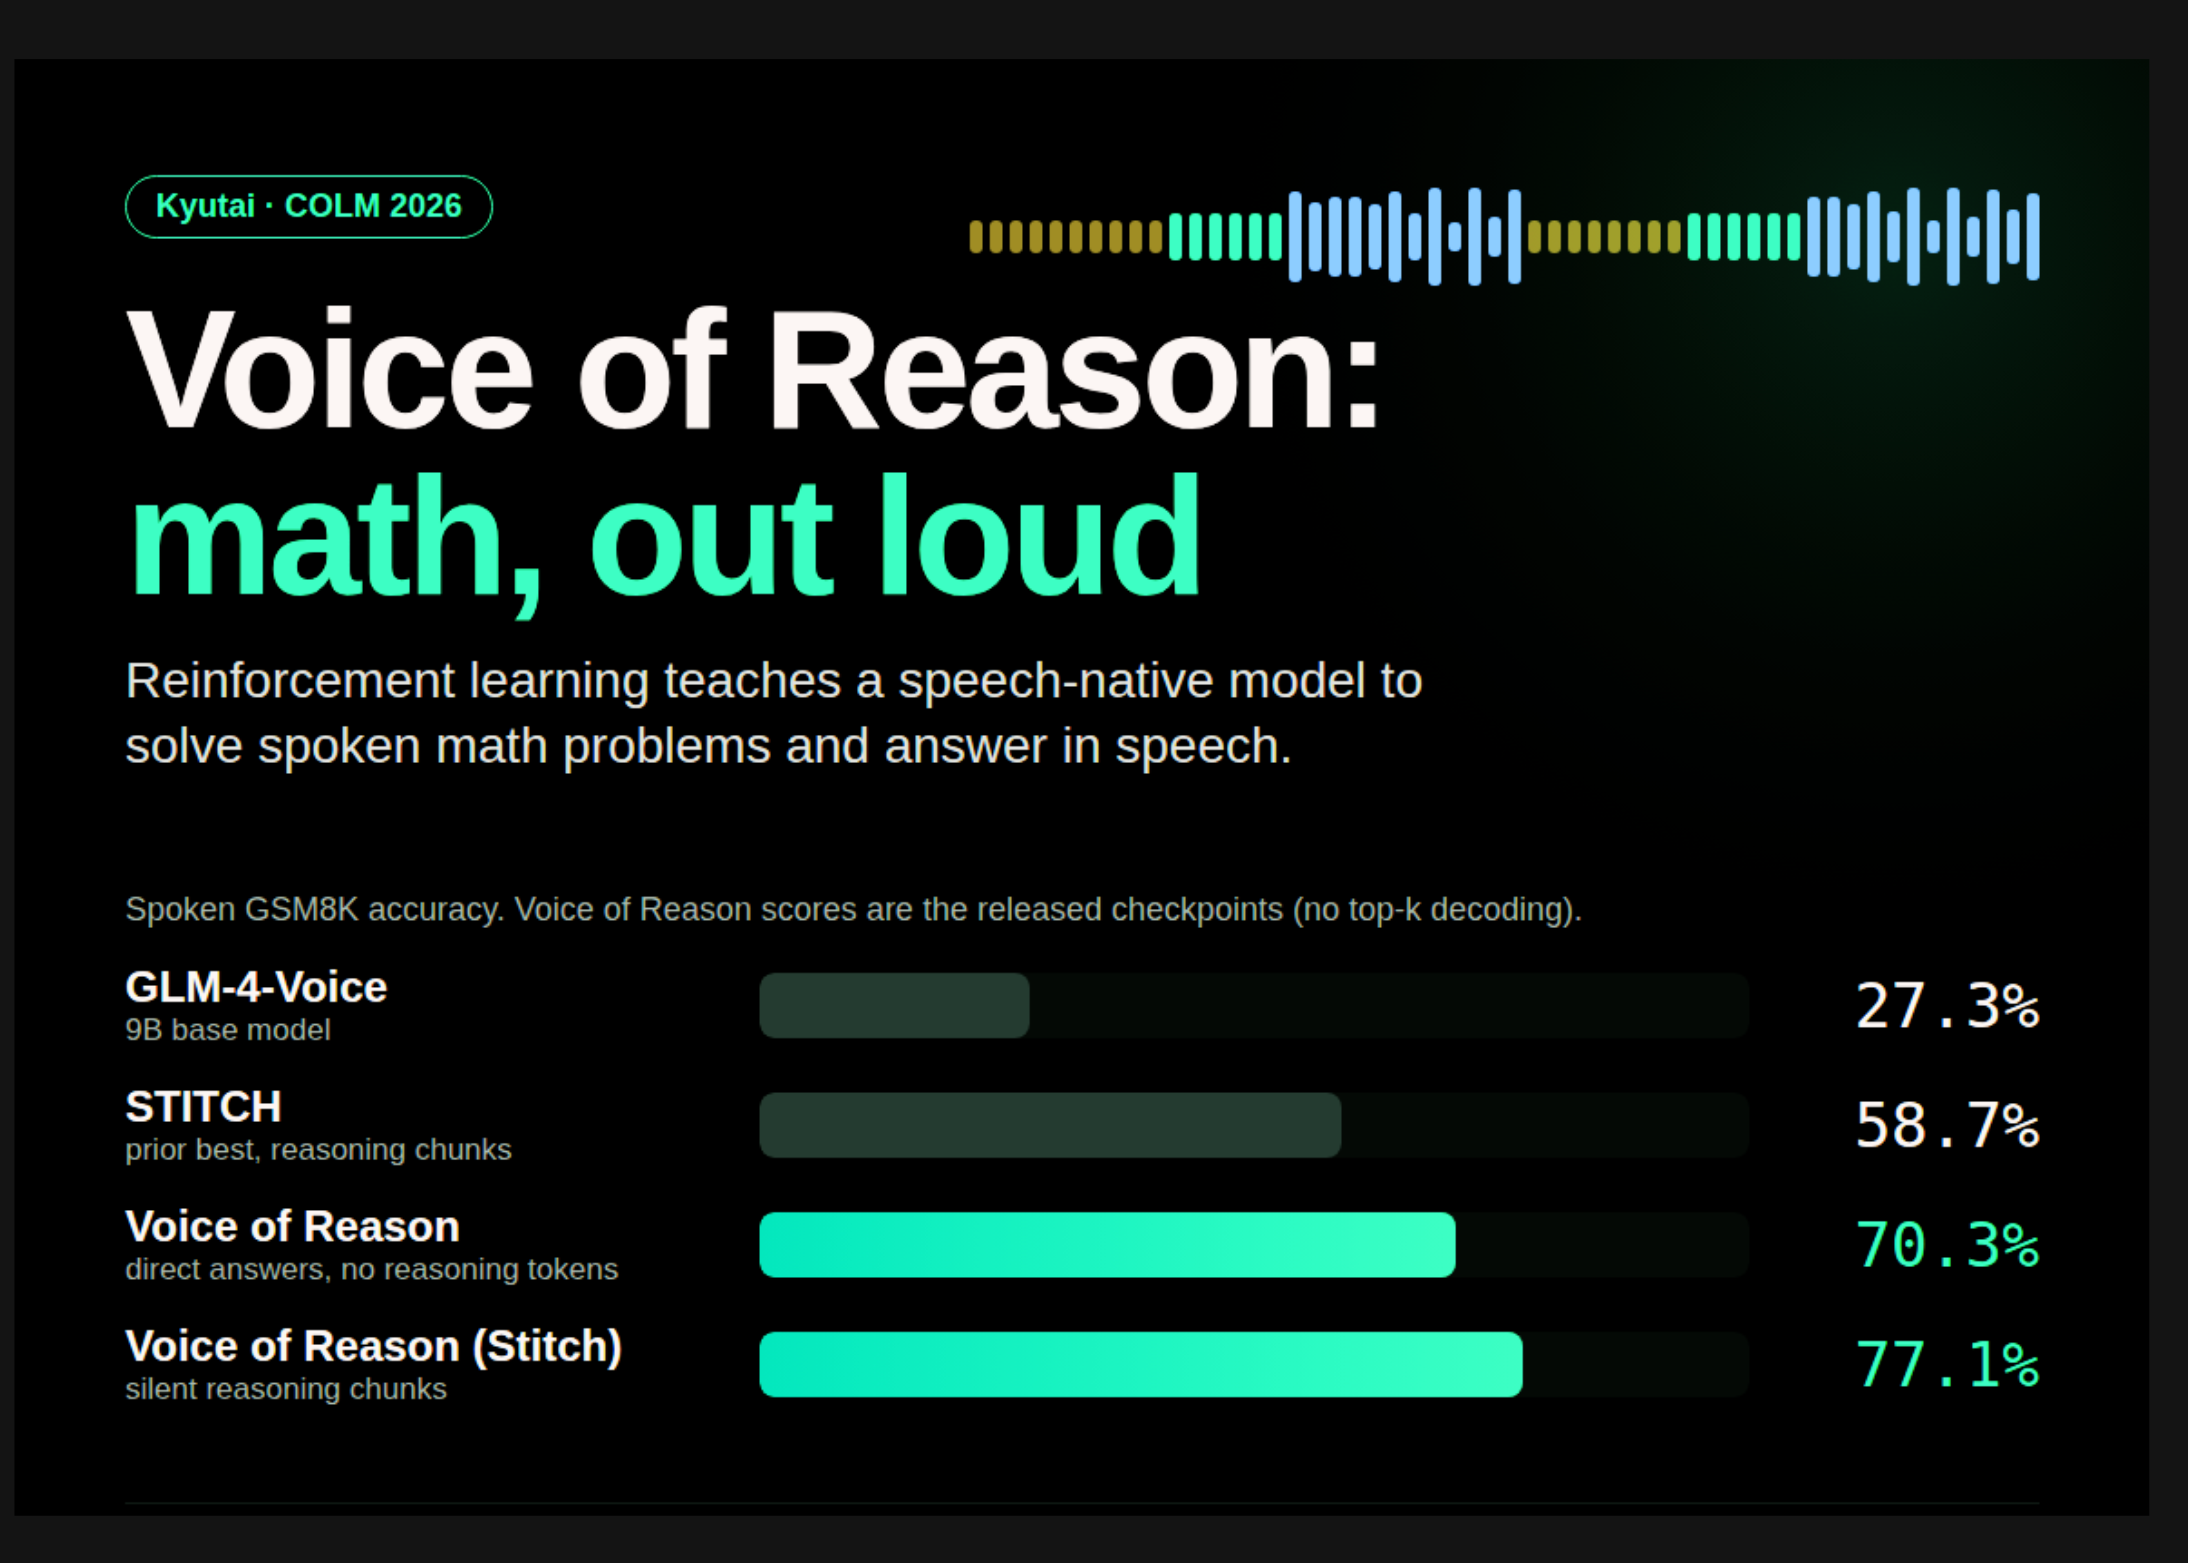
Kyutai has released Voice of Reason, 2 open-weight speech-to-speech models built on GLM-4-Voice-9B. Supervised fine-tuning and reinforcement learning lift spoken GSM8K accuracy fro...
Ollama pulls model weights, keeps an HTTP server on port 11434, and hands any client an OpenAI-shaped endpoint pointed at your own machine. Learn how to manage, configure, and opti...
LM Studio has added Z.ai’s new GLM-5.3-Flash model to Bionic, its AI agent platform, bringing multimodal input, a 1 million-token context window, and significantly lower pricing th...
The latest release from Meta Superintelligence Lab is a powerful transcription model.
При обработке больших аудио сначала важно определить, на каком языке говорит человек, и только затем направить запись в подходящую систему распознавания речи. Это становится особен...
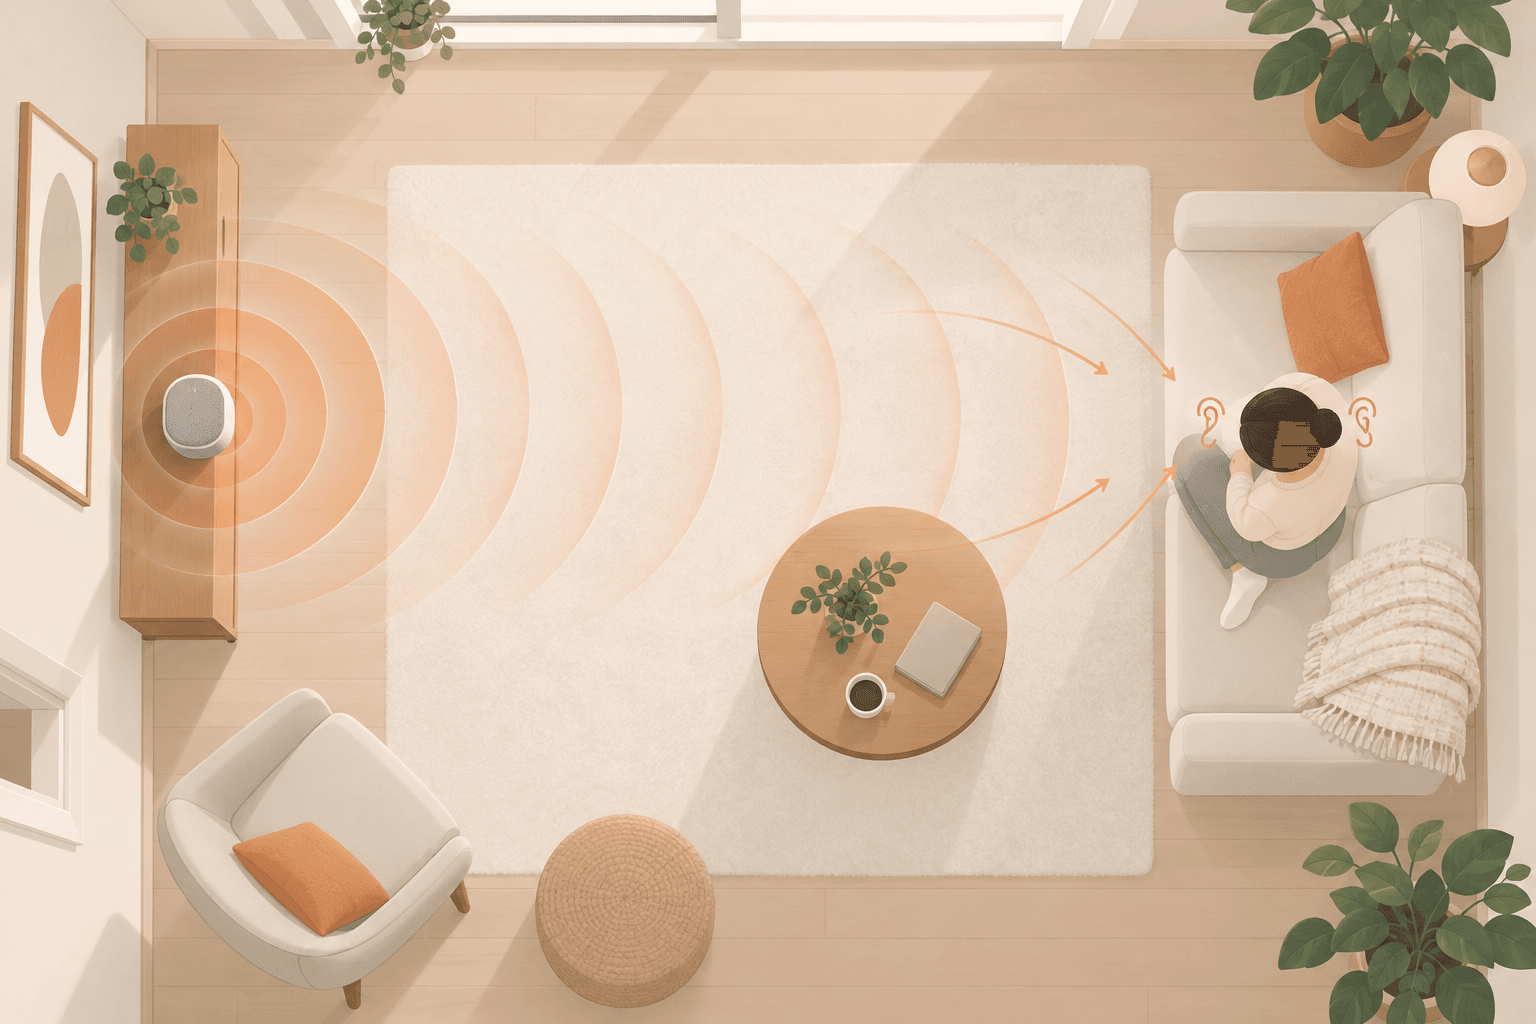
Built on MiDashengLM-7B with a new Spatial-Dasheng encoder, the Apache 2.0 model pairs general audio understanding with sound direction, distance and movement.
Ming-3.0-tts ships under MIT in two sizes, with voice cloning, text-based voice design, 14 paralinguistic tags, seven languages plus Sichuanese and Cantonese, and multi-speaker pod...
Large Language Models (LLMs) are commonly accessed through cloud APIs provided by services such as OpenAI, Anthropic, or Google Gemini. However, there are many situations where dev...
Meta AI Research: Meta launches Muse Voice Transcribe, MSL's first real-time audio perception model, with streaming automatic speech recognition, trained with 70+ languages — Exp...
Most production voice stacks are three systems stitched together. One model transcribes, a second separates speakers, and a detector decides when the user stopped talking. Each han...
Ant Group and inclusionAI open-sourced Ling-3.0-flash-VL, a 124B MoE multimodal model with 5.5B active parameters. BF16 and FP8 weights arrived September 9 with a vision feedback l...
Bilibili's Index LLM team released Index-Translate under Apache-2.0: 2B, 9B and 35B-A3B preview text models for 150 languages, plus dubbing, syllable-control and long-document vari...
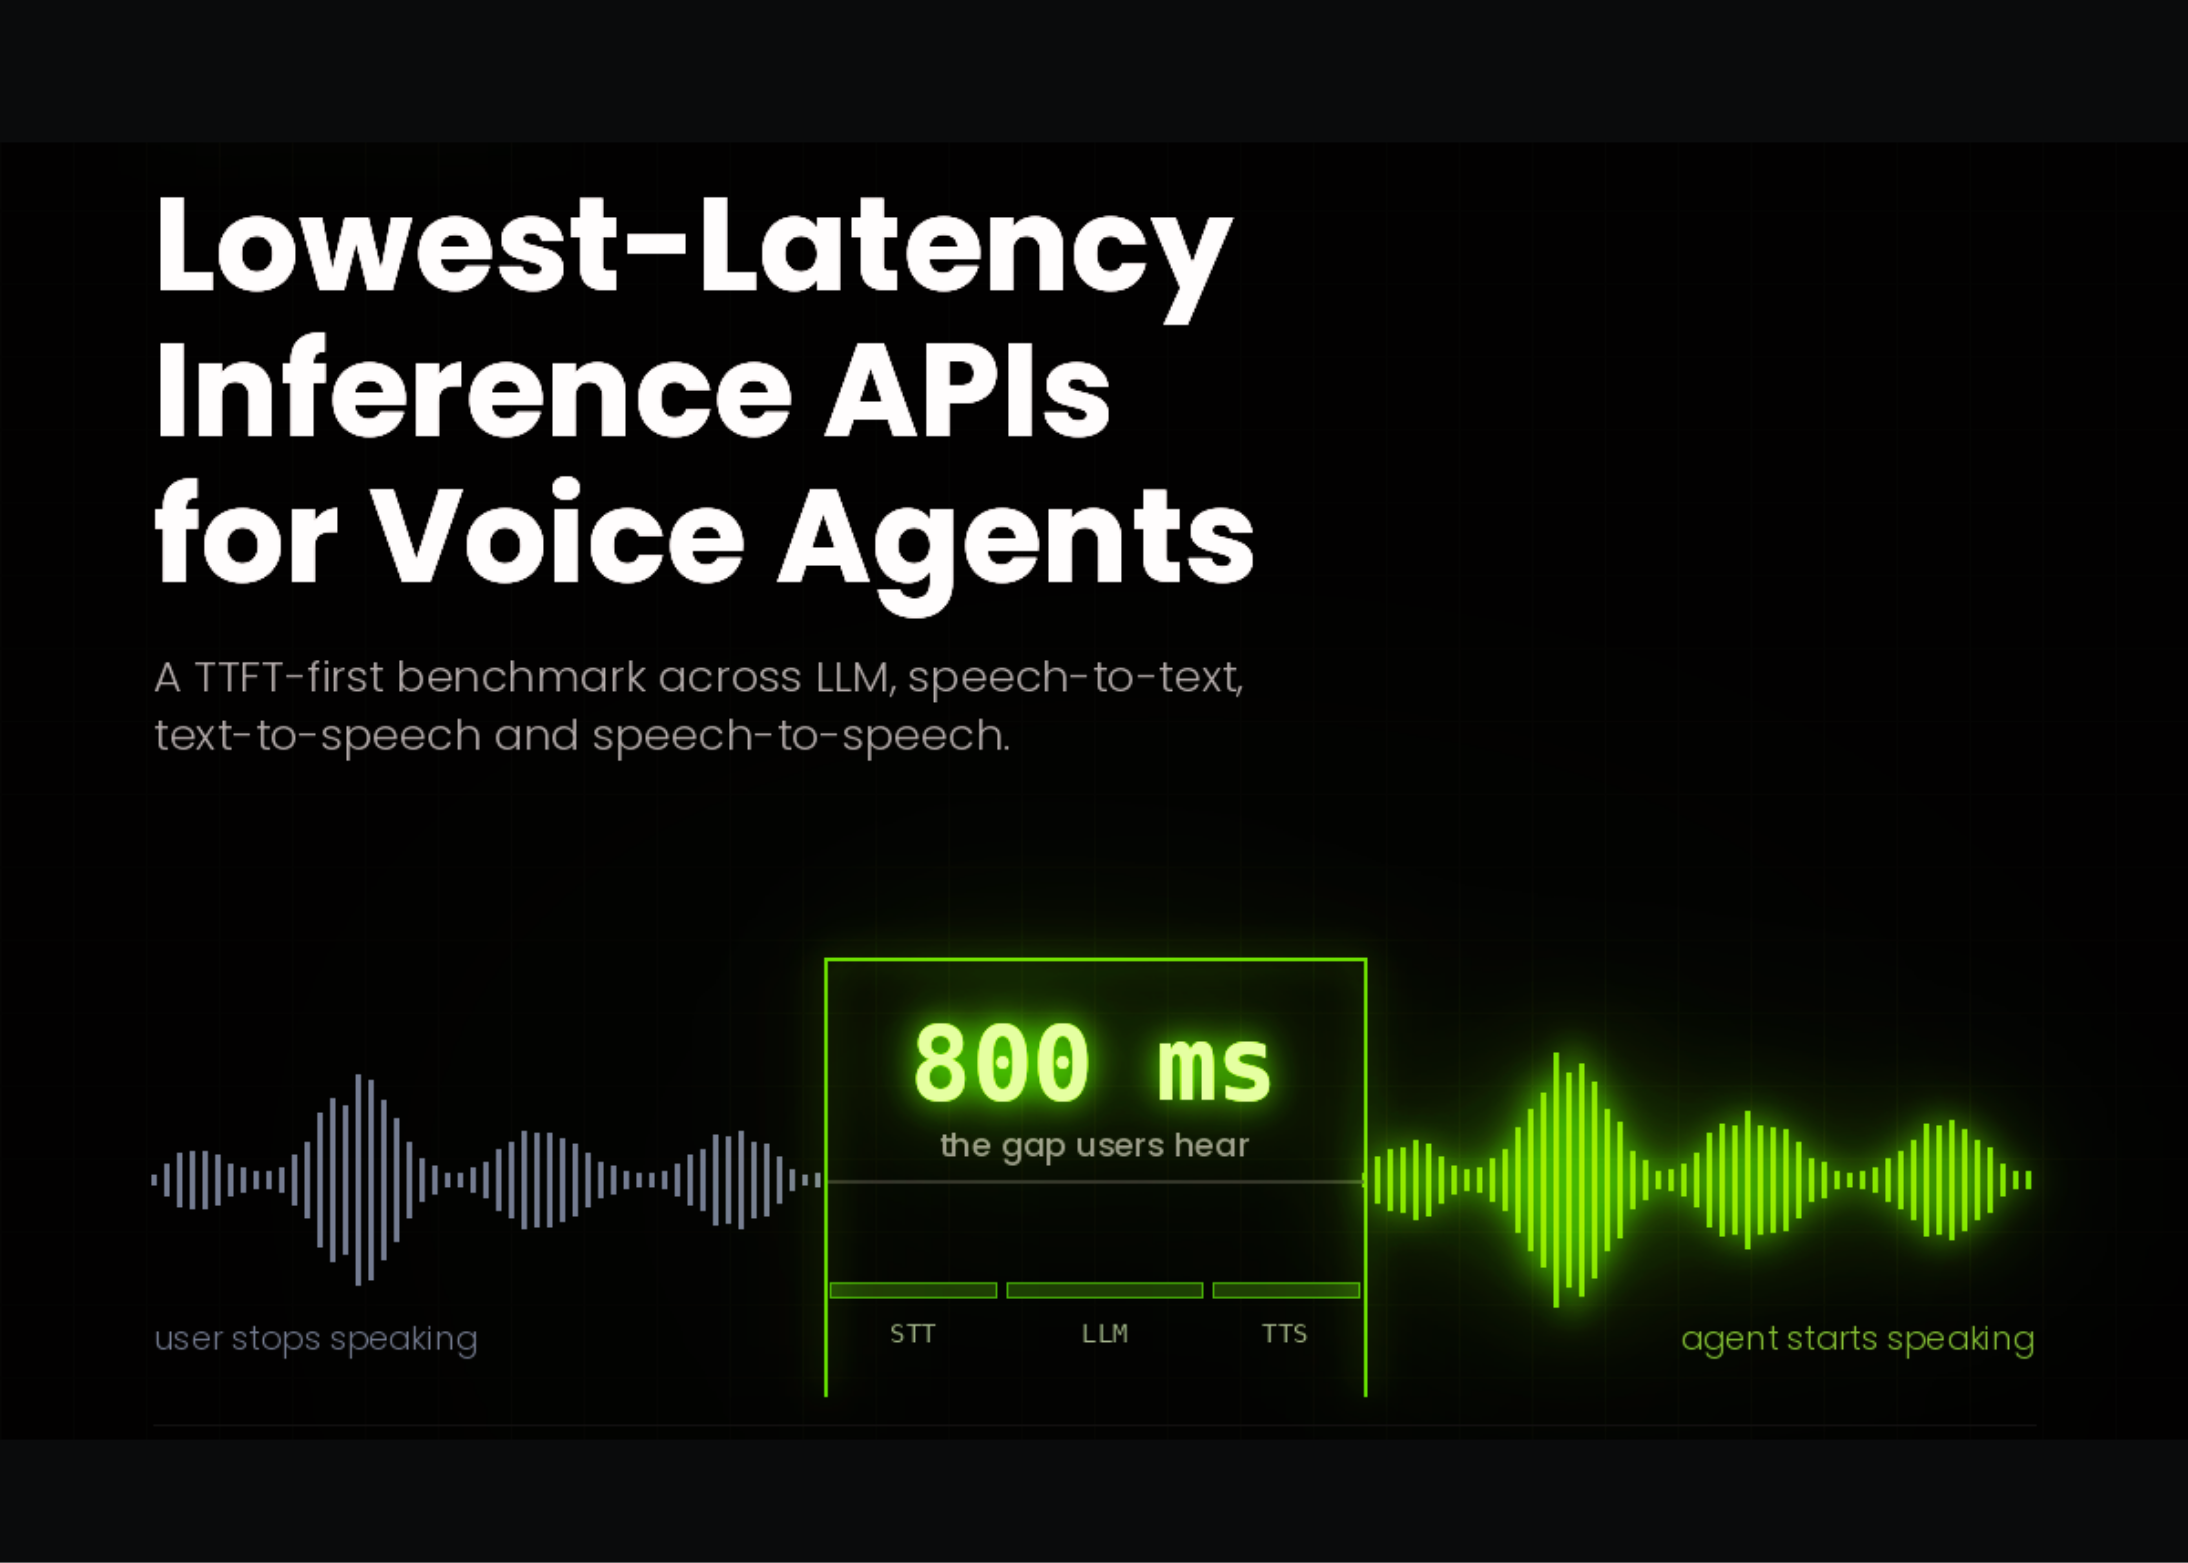
Voice agents fail on latency long before they fail on intelligence. Time to first token is the metric most teams use to choose an inference API, and it is the right starting point...
Alibaba's Qwen team launched Qwen3.8-Omni-Flash, a native text/image/audio/video model with 1M context, ~26% average gains vs Omni-Plus, open Qwen-Live Harness, and steep API audio...
The basics of how LLMs work, from tokens and Transformers to prompting and RAG.Continue reading on Medium »
AI applications do not always need the same language model for every request. A simple factual question may only require a small, fast model, while a request involving multiple con...
Z.ai: Z.ai releases GLM-5.3-Flash, the first natively multimodal GLM-5 series model, with 320B parameters, and says it served the model as Ox Alpha on Chinese chips — We introduc...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.