Latest updates for Apache Parquet

Fresh curated links around Apache Parquet are collected here so marketers can spot useful updates and turn timely ideas into posts faster.

Recent items include:

  • Columnar Formats for AI Telemetry: Parquet vs Vortex With DuckDB
  • AWS Aurora PostgreSQL adds direct queries for Iceberg and Parquet data lakes
  • Apache Iceberg: Индиана Джонс и Каталог судьбы в Lakehouse

Post angles to try

Share the most useful takeaway for your audience.
Turn one article into a quick practical checklist.
Ask your audience how this shift affects their work.
Turn angles into scheduled posts

Fresh articles and ideas

Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.

dzone.com /1 week ago

Columnar Formats for AI Telemetry: Parquet vs Vortex With DuckDB

An AI inference service makes a model available to an application through an API. When you ask an inference API a question, the application sends your prompt to the service. The se...

Read source
sourcetrail.com /2 weeks ago

AWS Aurora PostgreSQL adds direct queries for Iceberg and Parquet data lakes

AWS Aurora PostgreSQL now queries Iceberg and Parquet data in S3 without ETL, using DuckDB and familiar SQL. See versions, setup, limits, and costs. The post AWS Aurora PostgreSQL...

Read source
habr.com /1 month ago

Apache Iceberg: Индиана Джонс и Каталог судьбы в Lakehouse

В феврале этого года проект с красивым именем Polaris незаметно стал полноценным проектом фонда Apache. Новость прошла как-то мимо, ну стал и стал, мало ли. Между тем это одна из т...

Read source
snowflake.com /1 month ago

Snowflakeを使用したApache Icebergへのデータのストリーミング

Snowpipe Streamingを使用して、SnowflakeマネージドのApache Icebergテーブルにデータを簡単にストリーミングする方法をご紹介します。

Read source
towardsdatascience.com /3 weeks ago

I Compacted 1,000 Apache Iceberg Files Into 6. Here’s What Happened to Query Performance.

Benchmarking the impact of fewer, larger files across three SQL workloads The post I Compacted 1,000 Apache Iceberg Files Into 6. Here’s What Happened to Query Performance. appeare...

Read source
databricks.com /1 month ago

Open Table Formats Explained: Iceberg vs. Delta vs. Hudi

Open table formats are metadata layers that sit on top of data files in object storage, adding ACID transactions...

Read source
aws.amazon.com /1 month ago

Query Amazon S3 Tables from Amazon EMR Trino using the Iceberg REST endpoint

Learn how to query Amazon S3 Tables from Trino on Amazon EMR using the Apache Iceberg REST catalog endpoint. This post shows how to deploy the integration with AWS CloudFormation,...

Read source
dev.to /3 weeks ago

Archivos PDF, ZIP y binarios viajando en Kafka con nombre intacto.

Archivos PDF, ZIP y binarios viajando en Kafka con nombre intacto. Día 07 de la serie técnica WKafka Open Source. No aprovisiones un bucket en la nube cuando lo único que nece...

Read source
aws.amazon.com /1 month ago

Build a dynamic streaming data lake with Apache Iceberg and Apache Flink

Learn how to build a dynamic streaming data lake on Amazon Managed Service for Apache Flink that adapts to new event types and schema changes without stopping the pipeline, using A...

Read source
dev.to /1 month ago

Building a Modern Data Lakehouse on AWS: S3, Iceberg, Glue, Athena, and Lake Formation

The data lakehouse has become the default architecture for analytics on AWS in 2026. It combines the best of both worlds: the low-cost, schema-flexible storage of a data lake (S3)...

Read source
aws.amazon.com /2 weeks ago

Cost-effective ETL with DuckDB and Amazon S3 Tables on AWS Glue

Learn how to pair DuckDB with AWS Glue 6.0 to run SQL-centric ETL on a single worker, reading Parquet from Amazon S3 and writing Apache Iceberg tables to Amazon S3 Tables. This pos...

Read source
kdnuggets.com /4 weeks ago

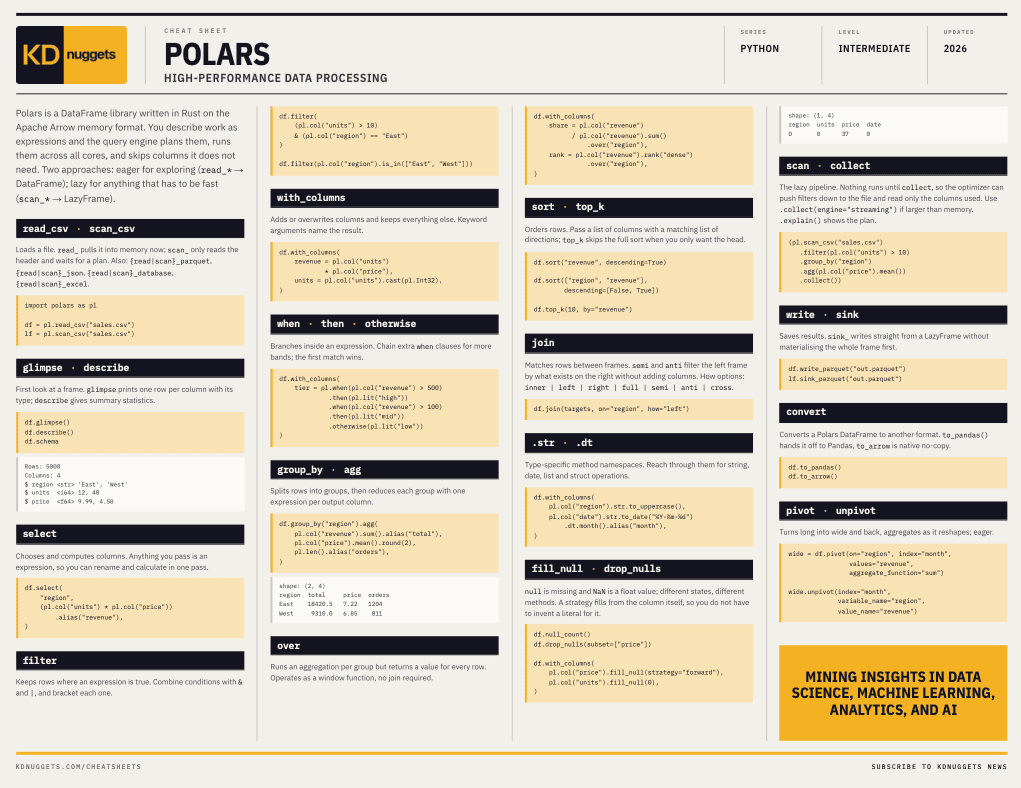
High-Performance Data Processing with Polars: A KDnuggets Cheat Sheet

Polars is a DataFrame library written in Rust on the Apache Arrow memory format, and the speed comes less from the language than from the model. The model? Describe your work as ex...

Read source
aws.amazon.com /1 month ago

Build with geospatial and variant types in Iceberg v3 on AWS Glue 6.0

AWS Glue 6.0 with Apache Spark 4.1 adds support for Apache Iceberg v3: native geospatial types, nanosecond-precision timestamps, the VARIANT type, and DEFAULT column values. This p...

Read source
snowflake.com /1 month ago

Streaming Data into Apache Iceberg with Snowflake

Discover how to easily stream data into Snowflake-managed Apache Iceberg tables using Snowpipe Streaming.

Read source
aws.amazon.com /1 month ago

Build a real-time event pipeline with Spark Real-Time Mode on AWS Glue 6.0

With AWS Glue 6.0, you can build real-time, near-real-time, and batch data pipelines on a single platform. Using a financial market-risk example, learn how to flag high-risk trades...

Read source
habr.com /3 weeks ago

Lakekeeper и Apache Polaris: сравниваем REST-каталоги для Iceberg

Спор о формате таблиц для lakehouse, похоже, закончился, Iceberg сегодня поддерживают Trino, Spark, ClickHouse, Snowflake и дальше по списку, так что следующим приходится выбирать...

Read source
dzone.com /12 hours ago

Delta Lake UniForm to Snowflake: Cross-Platform Table Access Without a Second Copy

Making a Databricks-owned Delta table queryable from Snowflake without copying it is one of those things where every individual piece — Delta Lake UniForm, Unity Catalog, private c...

Read source
dzone.com /3 weeks ago

Why Databricks and Snowflake Speak the Kafka Protocol: Ingestion vs Architecture

Kafka-compatible ingestion is showing up everywhere now, including in analytics platforms that have nothing to do with running Kafka. Databricks added Kafka-compatible APIs to its...

Read source
aws.amazon.com /3 weeks ago

Getting started with Apache Iceberg write support in Amazon Redshift – Part 3

Amazon Redshift now supports evolving Apache Iceberg table schemas and partition layouts through ALTER statements, with no data rewrites or pipeline rebuilds. In this final post of...

Read source
dev.to /3 weeks ago

Feeding the OLAP beast: ClickHouse massive bulk ingestion steps.

Feeding the OLAP beast: ClickHouse massive bulk ingestion steps. ClickHouse is a columnar beast, but treating it like MySQL by inserting row-by-row will bring your cluster to its...

Read source
dev.to /3 weeks ago

PDF, ZIP and binary files streaming over Kafka with names intact.

PDF, ZIP and binary files streaming over Kafka with names intact. Day 07 of the WKafka Open-Source Engineering Series. Don't provision a cloud bucket when all you need is send...

Read source
databricks.com /2 weeks ago

Load terabytes of data in minutes into Lakebase Postgres

Operational databases like Postgres are built to reliably execute highly concurrent...

Read source
dzone.com /1 month ago

dbt Meets Apache Flink: One Workflow for Data Engineers

Data engineers managing batch SQL pipelines on Snowflake, BigQuery, and increasingly Databricks, and streaming pipelines on Apache Flink face a familiar problem: two toolchains, tw...

Read source
talkpython.fm /1 month ago

Talk Python to Me: #562: DuckLake: The Lakehouse That's Just SQL and Parquet

How many files does your query read before it reads any data? On some data lakes, you go through JSON and metadata files first, just to learn which Parquet files matter. DuckLake a...

Read source

Turn fresh research into a full content calendar

Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.

Sources covering Apache Parquet

feeds.dzone.com

Recent coverage from public sources
Public source

aws.amazon.com

Recent coverage from public sources
Public source

dev.to

Recent coverage from public sources
Public source

habr.com

Recent coverage from public sources
Public source

planetpython.org

Recent coverage from public sources
Public source

towardsdatascience.com

Recent coverage from public sources
Public source