Kafka With Spring Boot: Introduction
Kafka is a distributed event streaming platform that enables real-time data ingestion, storage, and processing of continuous event streams. To do that, Kafka has a complex internal...
Search fresh public links, source activity, and ready-to-use post angles for Apache Kafka.
Fresh curated links around Apache Kafka are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Kafka is a distributed event streaming platform that enables real-time data ingestion, storage, and processing of continuous event streams. To do that, Kafka has a complex internal...
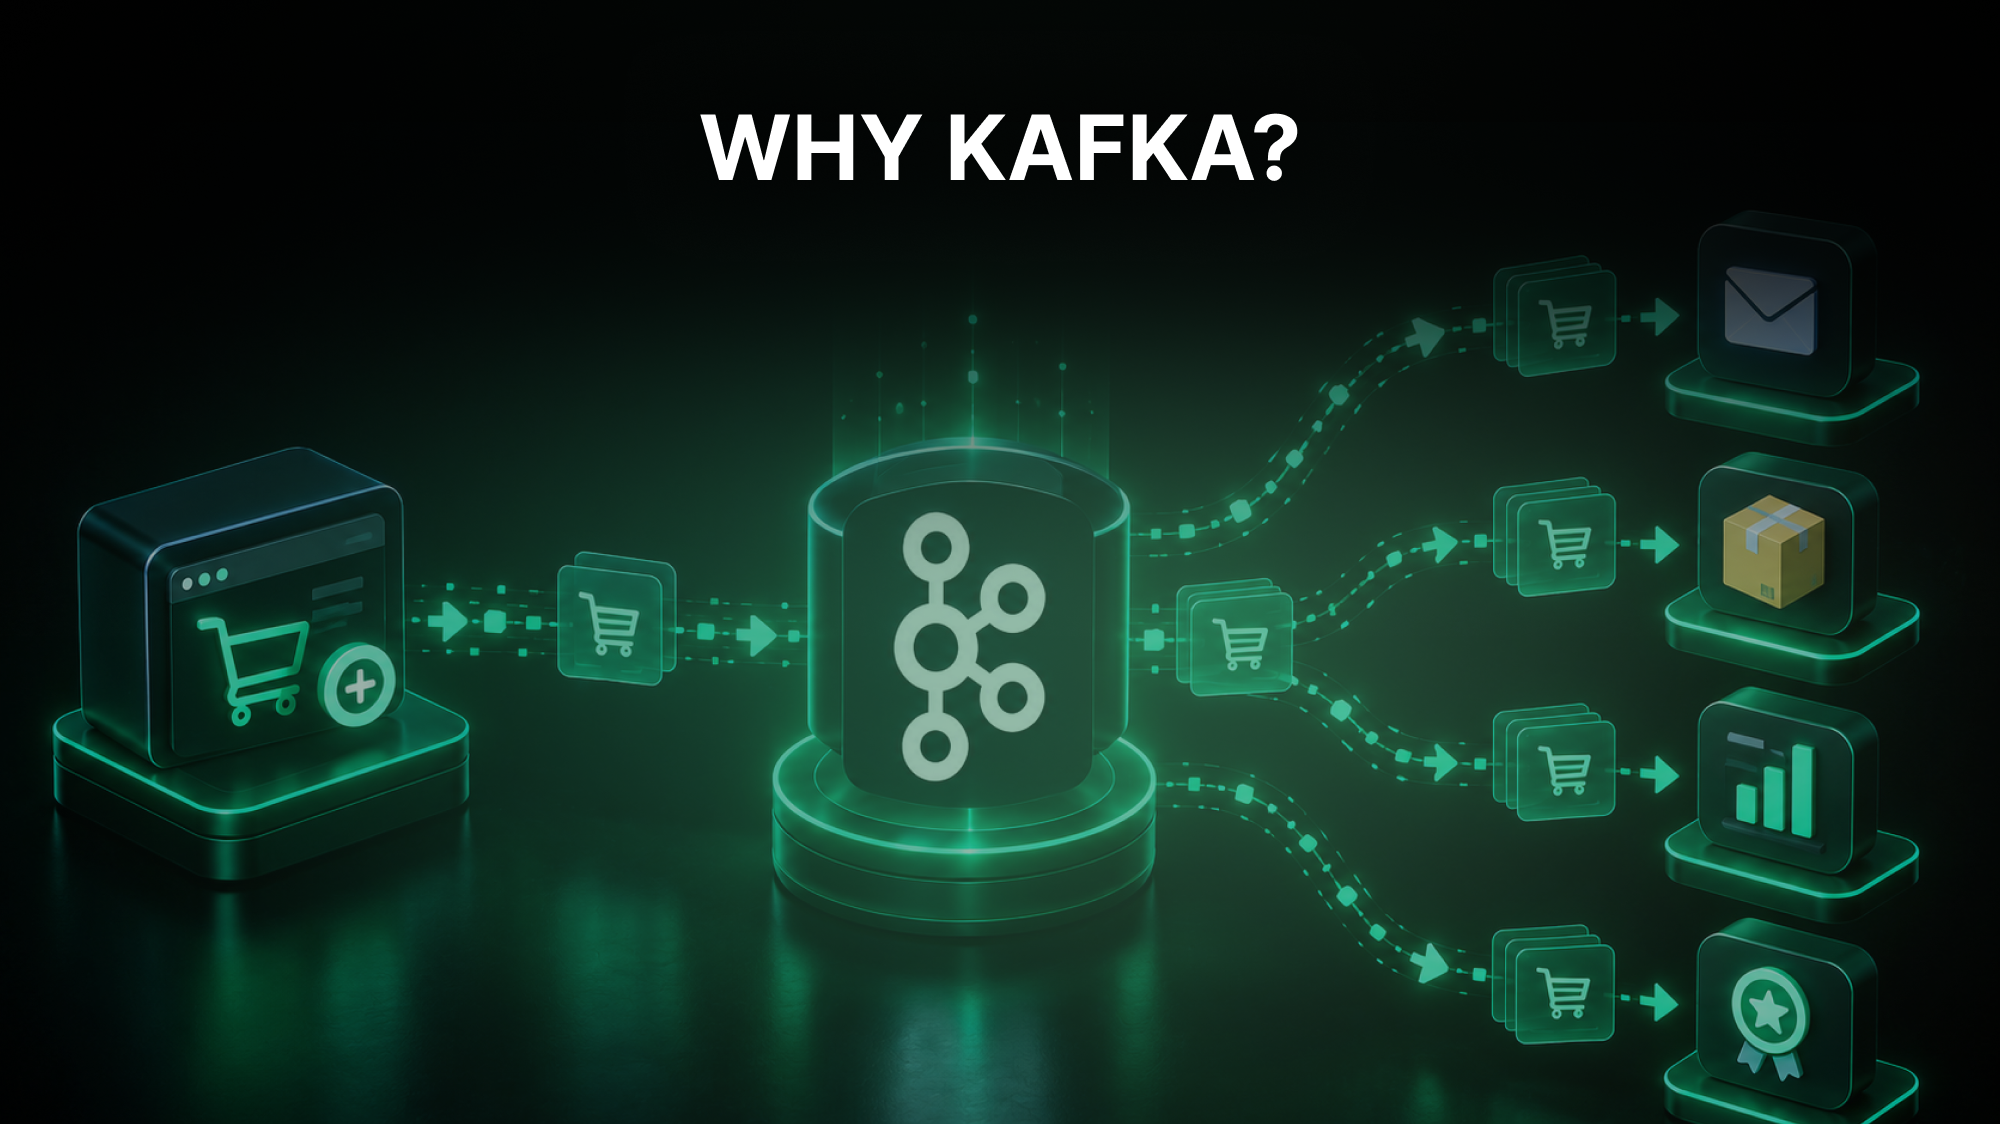
Learn how Kafka works and why every backend uses it: producers, consumers, topics, partitions and offsets explained with a checkout example.
Kafka-compatible ingestion is showing up everywhere now, including in analytics platforms that have nothing to do with running Kafka. Databricks added Kafka-compatible APIs to its...
Dashboards are everywhere. Business and IT teams use them to track metrics, visualize trends, and make decisions. But when working with real-time data from Apache Kafka, it’s not o...
Archivos PDF, ZIP y binarios viajando en Kafka con nombre intacto. Día 07 de la serie técnica WKafka Open Source. No aprovisiones un bucket en la nube cuando lo único que nece...
PDF, ZIP and binary files streaming over Kafka with names intact. Day 07 of the WKafka Open-Source Engineering Series. Don't provision a cloud bucket when all you need is send...
The KIP-848 consumer protocol in Apache Kafka 4.0 redesigns consumer group rebalancing to eliminate stop-the-world pauses. This post explains how the consumer protocol works on Ama...
Привет, Хабр! Меня зовут Максим Шуматбаев, я инженер технической поддержки в Arenadata. Это вторая часть разбора, что на самом деле происходит при работе клиентских приложений с Ka...
Enterprise AI is moving beyond isolated prompt-response calls and toward systems that observe events, preserve state, invoke tools, and publish decisions back into operational work...
Если вы хоть раз эксплуатировали Kafka, то знаете, сколько нервных клеток способен съесть её кластер. Поднять Kafka для PoC несложно, а вот дальше начинается планирование ёмкости,...
Comments
MSK Replicator now supports OAuth 2.0 (SASL/OAUTHBEARER) authentication to external Apache Kafka clusters. This post walks through the three supported grant types, how to configure...
Change data capture (CDC) pipelines look straightforward on paper: capture database changes, publish them to Kafka, and update downstream systems. The difficulty starts when events...
Привет, бойцы, вы готовы победить перенос данных? Есть задача: перенести данные из PostgreSQL в Kafka. Первая мысль: написать небольшой сервис.Он будет выполнять SELECT, превращать...
Every SaaS company has the same uncomfortable question after a major incident: who noticed first, the monitoring or the customers? For a long time our honest answer was “it depends...
As consumer groups on Amazon MSK scale to thousands of members, the metadata record Kafka writes during rebalances can exceed the 1 MB limit and stall the group. Learn how to estim...
Компактация лога в Kafka может привести к ситуации, когда разные реплики одного топика начинают хранить разную версию данных — и расхождение сохраняется даже после восстановления б...
Running Apache Flink on a mainframe sounds odd at first. A modern stream processing engine on a platform most people call legacy? But take a closer look. It is not only possible. I...
Data engineers managing batch SQL pipelines on Snowflake, BigQuery, and increasingly Databricks, and streaming pipelines on Apache Flink face a familiar problem: two toolchains, tw...
Today, stream processing platforms facilitate the real-time analysis of data flowing continuously from Internet of Things (IOT) devices, financial transactions, web applications an...
How many partitions does your Amazon MSK topic need? Choosing the right partition count affects throughput, scalability, and operational complexity. This post provides practical gu...
Привет, Хабр! Меня зовут Виктор Овчинников, я руковожу продуктовым направлением «Интеграционная платформа» в «Диасофт». Той самой Digital Q.Integration, которую вы имеете полное пр...
A Kafka recovery often looks successful before it actually is. The replay job exits. Consumer lag drops. Error rate returns to normal. The dashboard is green enough for everyone to...
Learn how to build a dynamic streaming data lake on Amazon Managed Service for Apache Flink that adapts to new event types and schema changes without stopping the pipeline, using A...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.