What Are AI Evals? How They Work and How to Run One
AI evals score AI outputs against a fixed dataset instead of asserting pass or fail. Learn the four parts of an eval, the main types, and how to gate a release.
Search fresh public links, source activity, and ready-to-use post angles for Ai Evaluation.
Fresh curated links around AI Evaluation are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
AI evals score AI outputs against a fixed dataset instead of asserting pass or fail. Learn the four parts of an eval, the main types, and how to gate a release.
The 11 best AI evaluation tools for production in 2026, ranked by seven criteria checked in vendor docs: online scoring, CI gates, alerts and self-hosting.
An eval is a systematic measurement of an AI system’s behavior. Not a test that passes or fails, a measurement that returns a number with…Continue reading on Data Science Collectiv...
G-Eval scores LLM output with model-written evaluation steps and a probability-weighted score. See how it works, a recount of its SummEval data, and its limits.
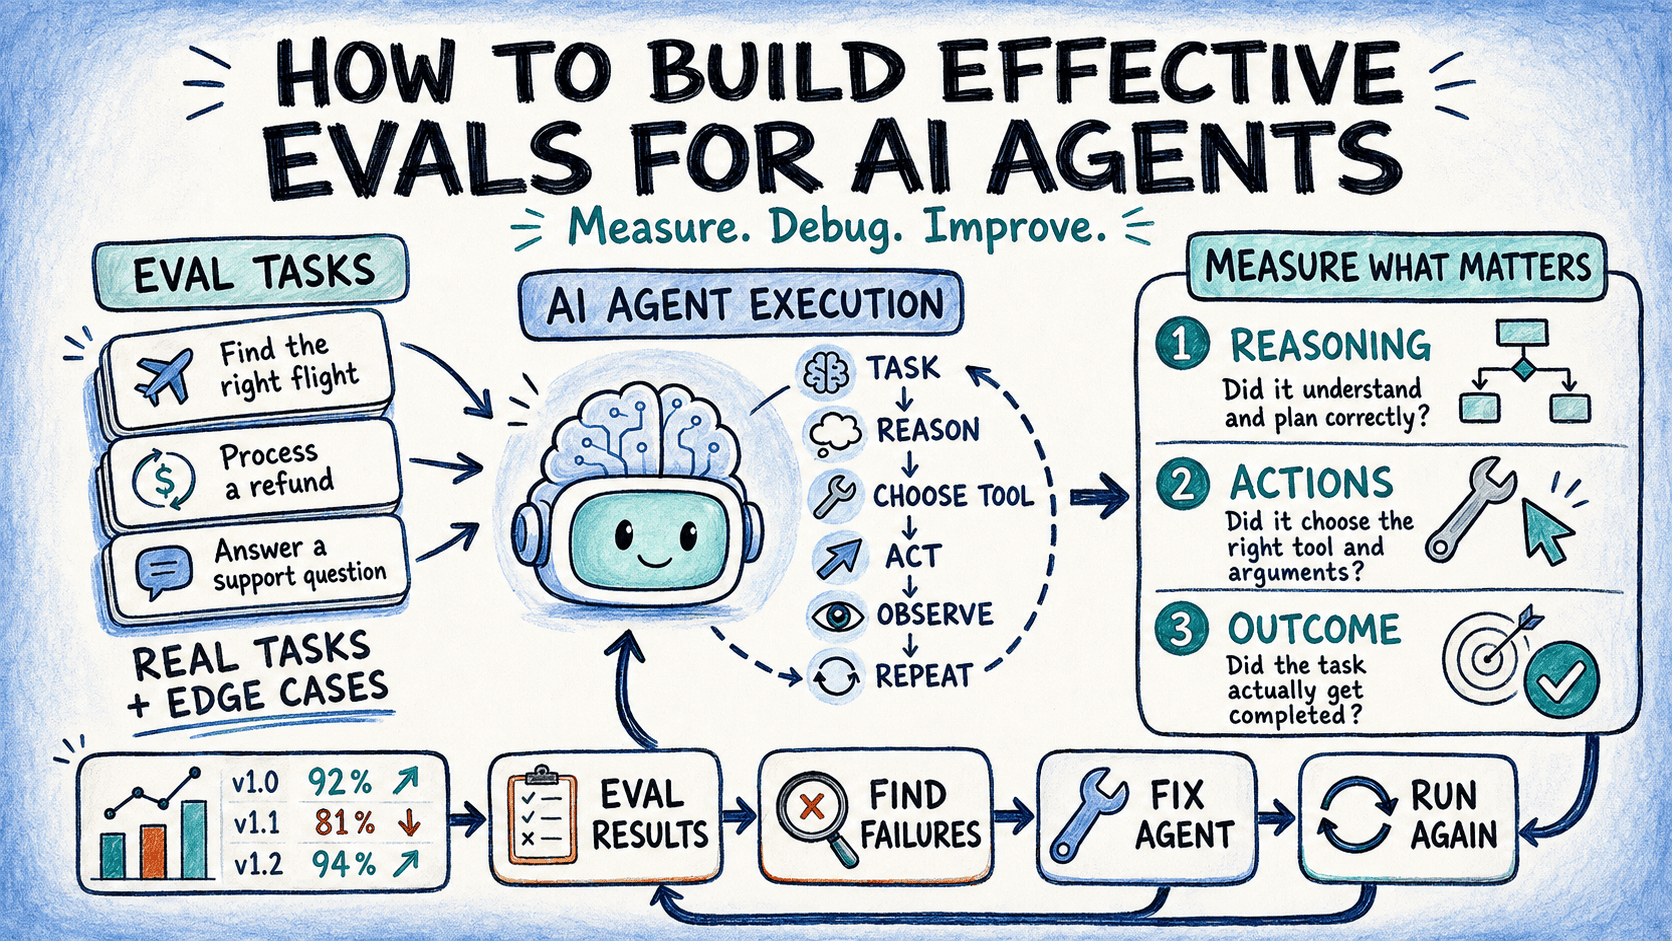
Learn how to build effective evals for AI agents, from designing clear tasks and choosing the right graders to building reliable eval harnesses and tracking changes over time.
The Real Question Is Not: Which Grader Is Smartest? When teams begin building AI evaluations, it is tempting to reach for an LLM-as-a-judge because it can read almost anything and...
Rushabh Mehta of Meta on agent evals: idempotency keys, checkpointing, memory TTLs, the three grader types, and why GAIA 2 shows temporal awareness still fails.
Agent-as-a-judge uses an AI agent with tools to grade another agent's work. Compare it with LLM judges and see a recount of the DevAI judges' error direction.
<figure data-wp-context="{&quot;imageId&quot;:&quot;6aa4e93495aaa&quot;}" data-wp-interactive="core/image" data-wp-key="6aa4e93495aaa&qu...
AI時代の評価、「この点数を信じてください」から「物差しを変えても結論は変わらないか」へ--GD数理研、「評価OS」をGitHubで公開
Sauce AI vs KaneAI: how each writes tests from natural language, heals them, exports code and is priced, plus how to try KaneAI on a flow from Sauce AI.
With AI now a taught subject in UAE schools and national assessment bodies tendering for automated scoring, the question for heads is no longer whether to look at AI marking but ho...
AI agent evaluation metrics with a formula for each: task completion, tool accuracy, trajectory, cost and pass^k, trace fields needed and when each misleads.
TestMu AI is the fastest multi-modal testing platform available, driven by KaneAI, the world's first GenAI-Native Testing Agent.
LLM benchmarks score general model capability, evals score your application. See what each can gate, where benchmarks break, and how to build an eval suite.
Vapi, Retell or Bland AI? Compare pricing models, agent builders, LLM choice, telephony, HIPAA and built-in testing, plus how to test your voice agent first.
Agent-native is a claim, not a feature. Seven checks you can run during a trial to test whether a vendor's tool works with no human at the screen.
<figure data-wp-context="{&quot;imageId&quot;:&quot;6ab0cc8b307c7&quot;}" data-wp-interactive="core/image" data-wp-key="6ab0cc8b307c7&qu...
Agentic AI architecture splits planner, generator, and evaluator roles. Why a generator cannot grade its own output, and how to wire an independent evaluator.
OpenAI GDPval tests AI on 1,320 real work tasks from 44 occupations. See what the 220 open tasks hold, how experts grade them, and why GDPval-AA scores differ.
AI (Artificial Intelligence) နည်းပညာက အá€á€¯á€¡á€á€»á€á€”်မှာ နေရာá€á€á€¯á€„်းမှာ ရှá€á€”ေပါပြီዠဒါပေမဲá...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.