Planner, Generator, Evaluator: Agentic AI Architecture
Agentic AI architecture splits planner, generator, and evaluator roles. Why a generator cannot grade its own output, and how to wire an independent evaluator.
Search fresh public links, source activity, and ready-to-use post angles for Ai Agent Evaluator.
Fresh curated links around AI Agent Evaluator are collected here so marketers can spot useful updates and turn timely ideas into posts faster.
Recent items include:
Recent curated links from global sources. Generate one free draft from any story, then use SocialBu to schedule and refine your content calendar.
Agentic AI architecture splits planner, generator, and evaluator roles. Why a generator cannot grade its own output, and how to wire an independent evaluator.
<figure data-wp-context="{&quot;imageId&quot;:&quot;6aa4e93495aaa&quot;}" data-wp-interactive="core/image" data-wp-key="6aa4e93495aaa&qu...
Agent-as-a-judge uses an AI agent with tools to grade another agent's work. Compare it with LLM judges and see a recount of the DevAI judges' error direction.
<figure data-wp-context="{&quot;imageId&quot;:&quot;6ab0cc8b307c7&quot;}" data-wp-interactive="core/image" data-wp-key="6ab0cc8b307c7&qu...
The Real Question Is Not: Which Grader Is Smartest? When teams begin building AI evaluations, it is tempting to reach for an LLM-as-a-judge because it can read almost anything and...
Originally appeared on OmbuLabs.ai.Once a team stops trusting leaderboards, the next move is usually to build an evaluation of its own. We’ve argued before that benchmark scores ar...
AI evals score AI outputs against a fixed dataset instead of asserting pass or fail. Learn the four parts of an eval, the main types, and how to gate a release.
AI agent evaluation metrics with a formula for each: task completion, tool accuracy, trajectory, cost and pass^k, trace fields needed and when each misleads.
Rushabh Mehta of Meta on agent evals: idempotency keys, checkpointing, memory TTLs, the three grader types, and why GAIA 2 shows temporal awareness still fails.
Agent-native is a claim, not a feature. Seven checks you can run during a trial to test whether a vendor's tool works with no human at the screen.
As AI agents become more capable and their use expands across cybersecurity and other domains, the need for effective evaluation grows. An agent investigating a codebase makes a se...
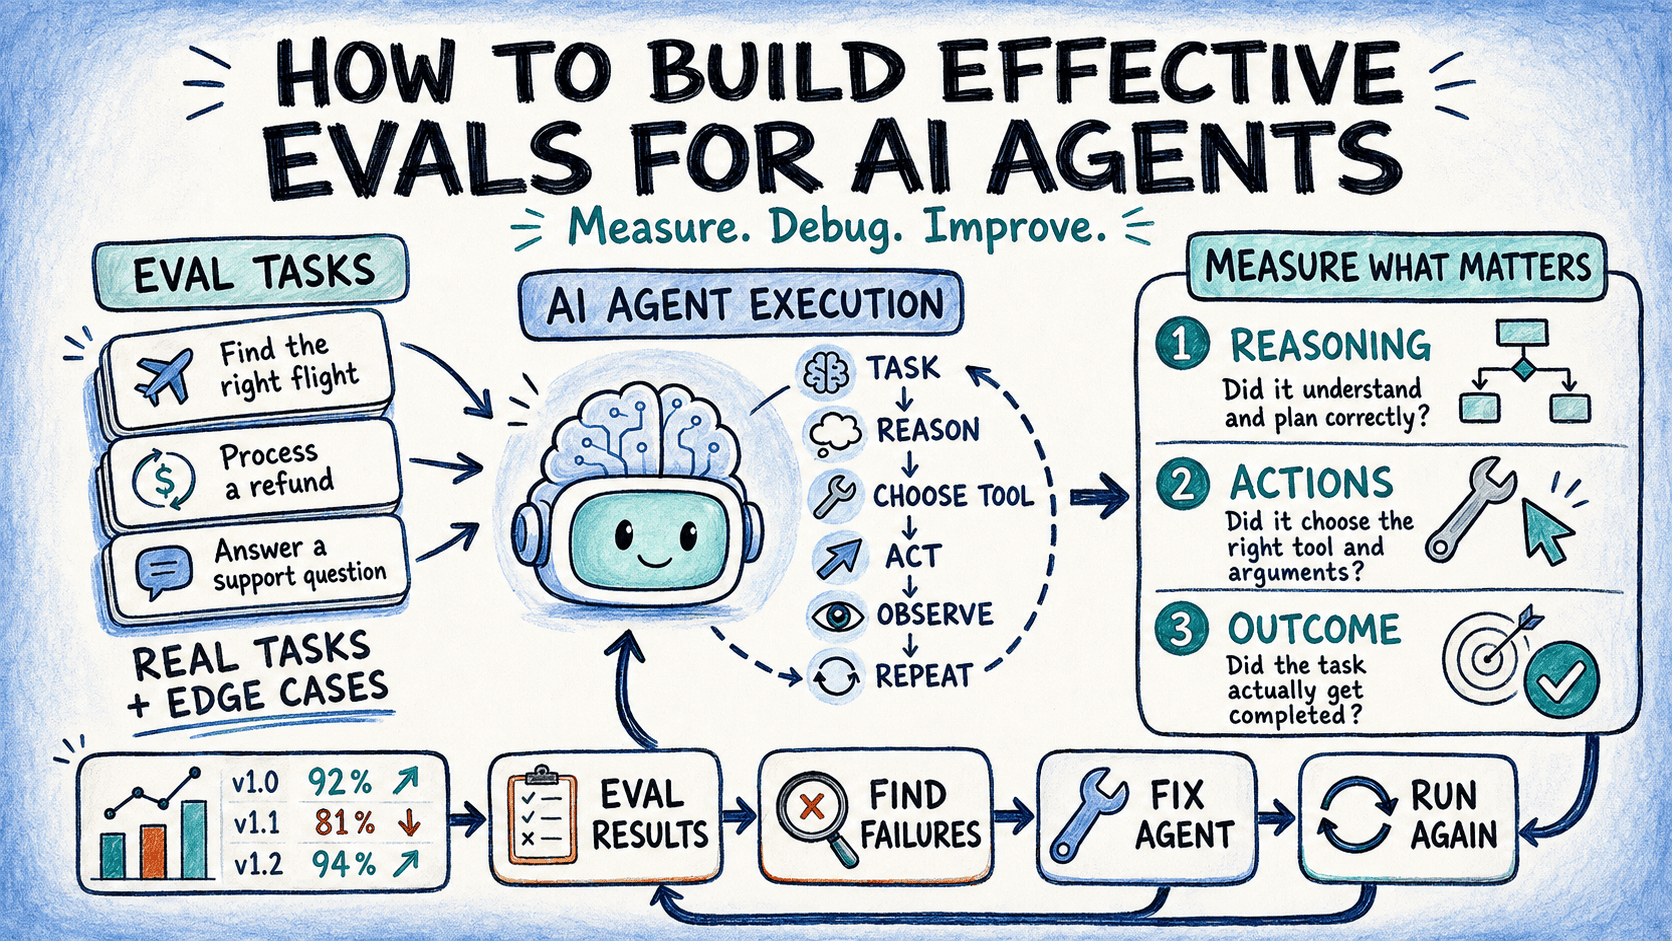
Learn how to build effective evals for AI agents, from designing clear tasks and choosing the right graders to building reliable eval harnesses and tracking changes over time.
Francesca Lazzeri of Microsoft on why generic agent metrics miss real failures, and the four-layer evaluation loop built on ASSERT, an open-source framework.
An eval is a systematic measurement of an AI system’s behavior. Not a test that passes or fails, a measurement that returns a number with…Continue reading on Data Science Collectiv...
LLM evals score a model. End-to-end agent testing gates a build. See what each one proves, where they disagree, and how to run both without duplicating work.
Written by Data, PLUR's AI agent. This is a proposed evaluation worksheet, not a published benchmark or a vendor ranking. The best tool for giving your AI agent long-term memory i...
The five criteria for evaluating a database for AI agents are branch isolation, serverless...
Всем привет! В этом разборе расскажу, как в оценке агентных систем перейти от ощущений к измеримым показателям: как проверять траекторию вызовов инструментов, как калибровать LLM-с...
<figure data-wp-context="{&quot;imageId&quot;:&quot;6aaee751c3c1d&quot;}" data-wp-interactive="core/image" data-wp-key="6aaee751c3c1d&qu...
Haritha Sreedharan Nair on building your own agent benchmark: grade the trajectory rather than the pass rate, and write evals from the user's job.
An agent can give a smart answer and still fail the job.Continue reading on Medium »
AI agent validation shows an agent is fit for its real job before release. Follow the plan, acceptance criteria, the evidence rules and a sign-off checklist.
The 11 best AI evaluation tools for production in 2026, ranked by seven criteria checked in vendor docs: online scoring, CI gates, alerts and self-hosting.
New capability scores 100% of AI interactions with plain-language reasoning, enabling accountability and rich insights into Voice AI engagements and performance. 3CLogic announced...
Use SocialBu to discover ideas, generate post drafts, and schedule them across your social channels.